Getting Started With Regression Analysis Project Ideas
Most people approach regression projects by grabbing a dataset and running a model, then feeling satisfied when the output produces numbers. The result is usually something that looks fine until someone asks a question about what actually changed in the model's behavior. That is where the useful work begins. The ideas below are the kind of projects that teach you how to think about regression properly, not just how to call a function. I worked on a project involving vibration sensor data from industrial motors. The raw approach of feeding all sensor readings into a standard OLS regression produced coefficients that looked reasonable at first glance. The residuals showed clear autocorrelation though, which invalidated every confidence interval in the output. I switched to a Generalized Least Squares approach with a first-order autoregressive error structure, which corrected the standard errors and made the predictions actually useful for scheduling maintenance. The R-squared dropped slightly, but the model became trustworthy. A common beginner approach is to drop neighborhood, square footage, and year built into a regression and call it done. The coefficients will come out, but they will be misleading if the relationship between square footage and price changes depending on which neighborhood you are in. Adding interaction terms between location and size is a more realistic model, even if it makes the interpretation slightly harder to explain to stakeholders. I learned this the hard way on a residential property dataset where the baseline model overestimated prices in high-demand areas by roughly 15 percent because it could not capture the non-linear premium associated with larger homes in those zones.
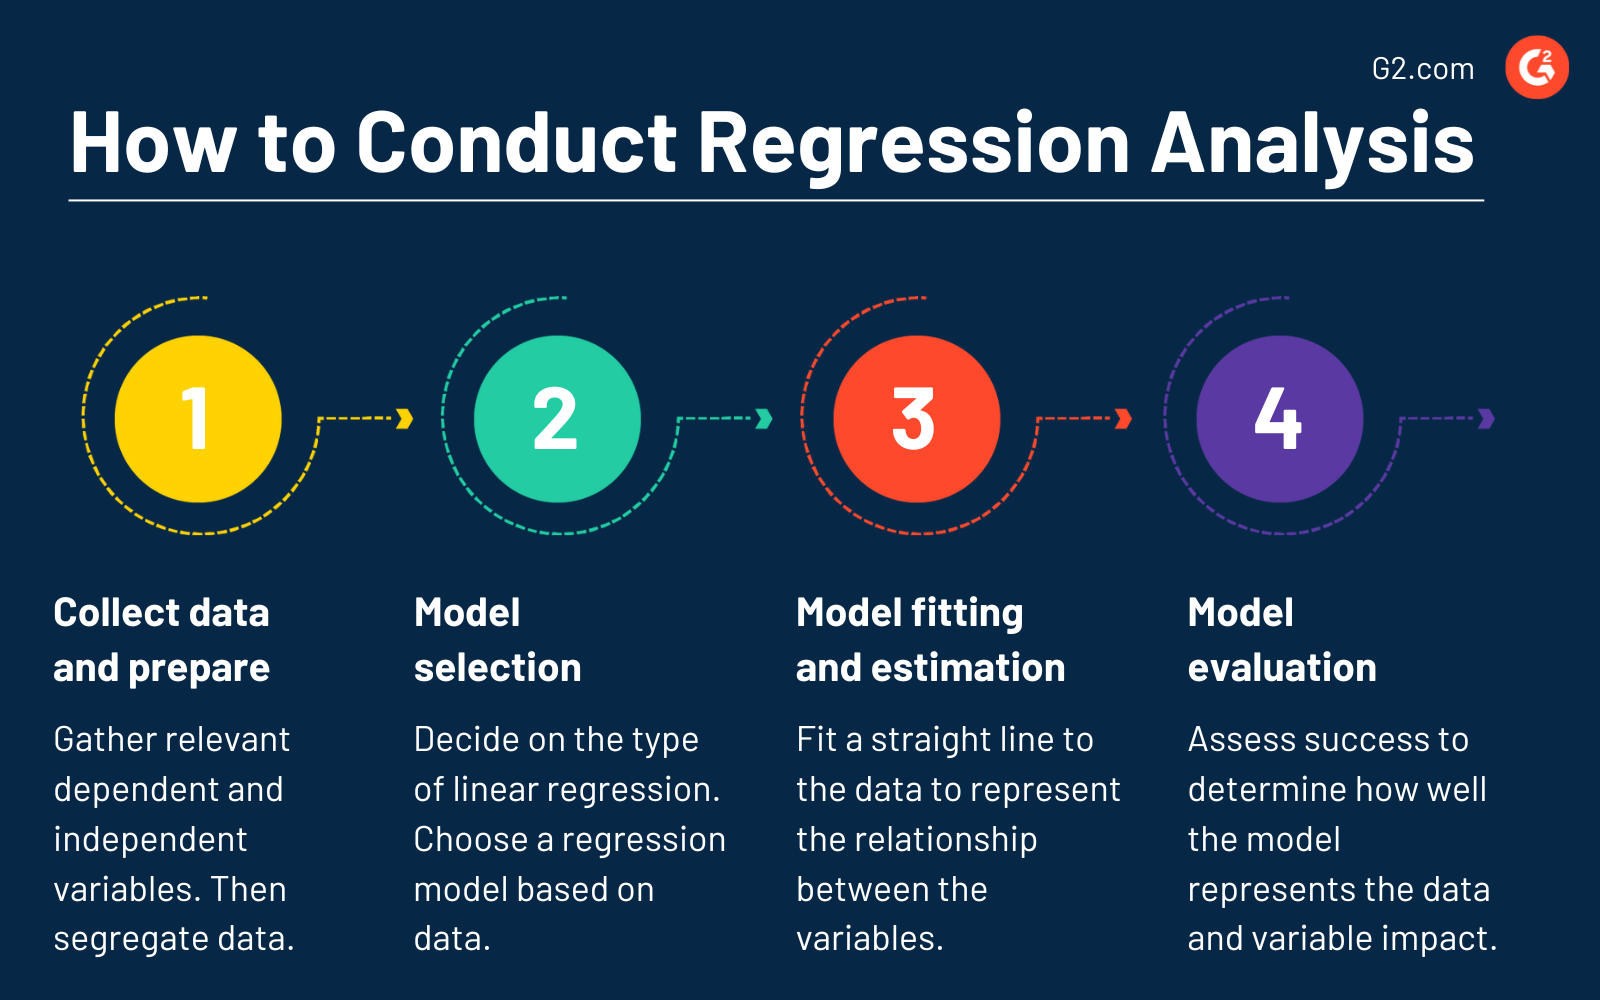
Logistic regression is the standard starting point here, and for good reason. But treating all patient factors as equally important leads to overfitting, especially when you have hundreds of diagnostic codes against a relatively small number of readmission events. Regularization through LASSO or Ridge penalties helps manage the feature space. You can also incorporate clinical domain knowledge by pre-selecting variables based on established medical guidelines before running the model. This is not cheating, it is simply acknowledging that pure data-driven selection can introduce noise when the outcome is imbalanced. Churn models benefit from time-aware validation. Standard train-test splitting works fine until the test set accidentally contains future data that the model could never have known about during training. A time-based split where the training window ends before the test window starts is more realistic. The difference between a properly validated churn model and a naive one is often the gap between a useful business tool and a dashboard that looks impressive but fails under scrutiny. The actual workflow for these projects is straightforward once you stop treating it like a code exercise. Load the data first and spend time understanding what each variable represents in the real world before fitting anything. A column labeled revenue might actually be a lagging indicator rather than a driver, and mixing those up silently corrupts your interpretation. Check for missing data patterns. Missing completely at random is rare in practice, and imputing everything with the mean will distort your coefficient estimates.
Variable selection matters more than model selection in most real-world regression work. Adding polynomial terms, log transformations, or interaction effects based on domain understanding typically improves performance more than switching from OLS to a more complex estimator. I once spent a full day tuning a gradient boosting regressor only to realize that the simpler linear model with the right interaction terms was performing comparably and was far easier to explain to the people who would actually use the results.
Get the Full Details

Common Pitfalls And Where Regression Fails Completely
Regression assumes a linear relationship between features and the target, or at least that your transformations have made the relationship approximately linear. If the underlying connection is genuinely non-linear and you cannot find a transformation that fixes it, regression is the wrong tool. Decision trees or non-parametric methods are better suited for those cases, even though they sacrifice interpretability. Another scenario where regression breaks down is when predictors are nearly perfectly correlated. Collinearity does not bias the coefficients, but it inflates their variance to the point where the estimates become unstable. Small changes in the data can flip coefficient signs, which makes any business decision based on those coefficients unreliable. Variance inflation factors above ten are a red flag. Dropping redundant features or using dimensionality reduction techniques before fitting the model is the standard fix. Outliers deserve careful handling rather than automatic removal. A single influential point can pull the regression line dramatically, and removing it without justification is dishonest. However, keeping an outlier that is clearly a data entry error is equally bad practice. I usually flag potential outliers, examine the original data source, and make a documented decision rather than blindly deleting anything more than two standard deviations from the mean.
Where To Find Data For These Projects
Kaggle hosts numerous regression-focused datasets, though the quality varies significantly. The UCI Machine Learning Repository is more curated. Government open data portals contain messy but realistic datasets that reflect actual working conditions. A dataset that is too clean teaches you nothing about the debugging process that dominates real projects.
Summary Of What Actually Helps
The best Regression Analysis Project Ideas share a common trait: they force you to deal with messy data, interpret coefficients in context, and validate the model against assumptions rather than just accuracy metrics. Accuracy alone tells you very little about whether a regression model is useful or merely overfit. Focus on residual diagnostics, cross-validation strategy, and whether the model makes sense to someone who did not build it. That is what separates a project that looks good on paper from one that survives contact with actual data.