How to Build a Risk Assessment Code Matrix That Actually Works
A Risk Assessment Code Matrix is a grid that maps likelihood against severity to produce a single numerical risk score. It sounds simple because it is simple. The problem isn't the concept, it's the implementation. Most people build these and then ignore them the moment a deadline hits. I'm going to walk you through building one that doesn't collapse under real-world use. We'll cover the mechanics, the pitfalls I've seen burn teams, and a specific edge case that took me three weeks to fix.
How the Risk Assessment Code Matrix Actually Works
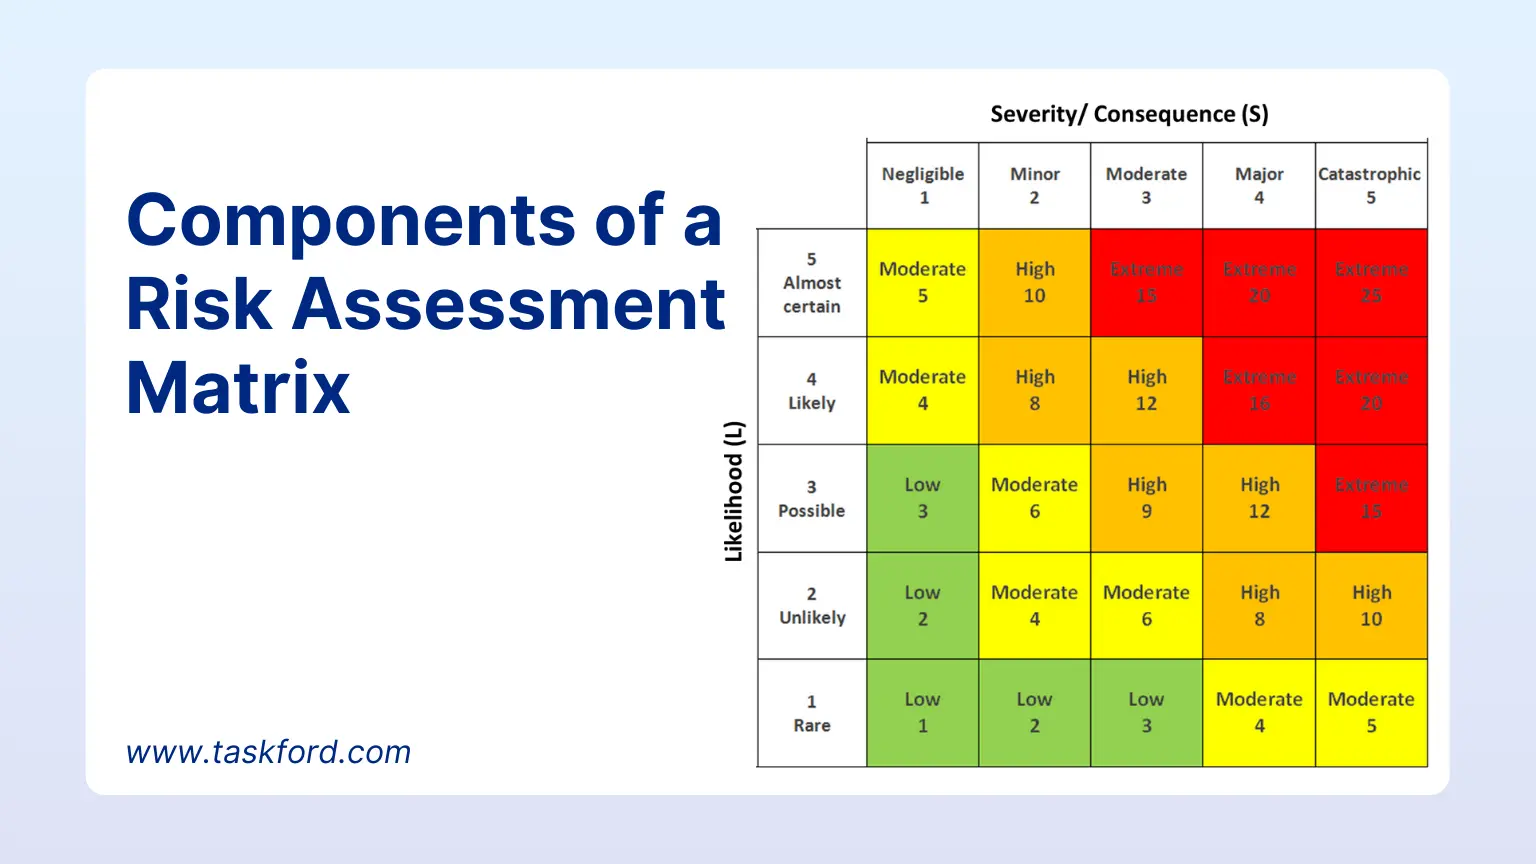
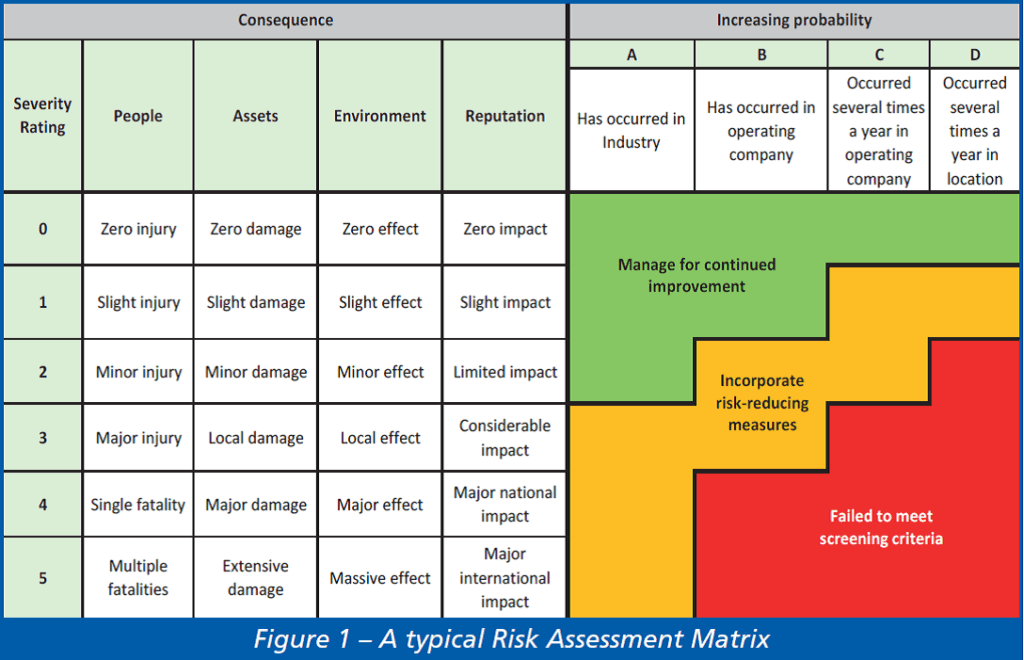
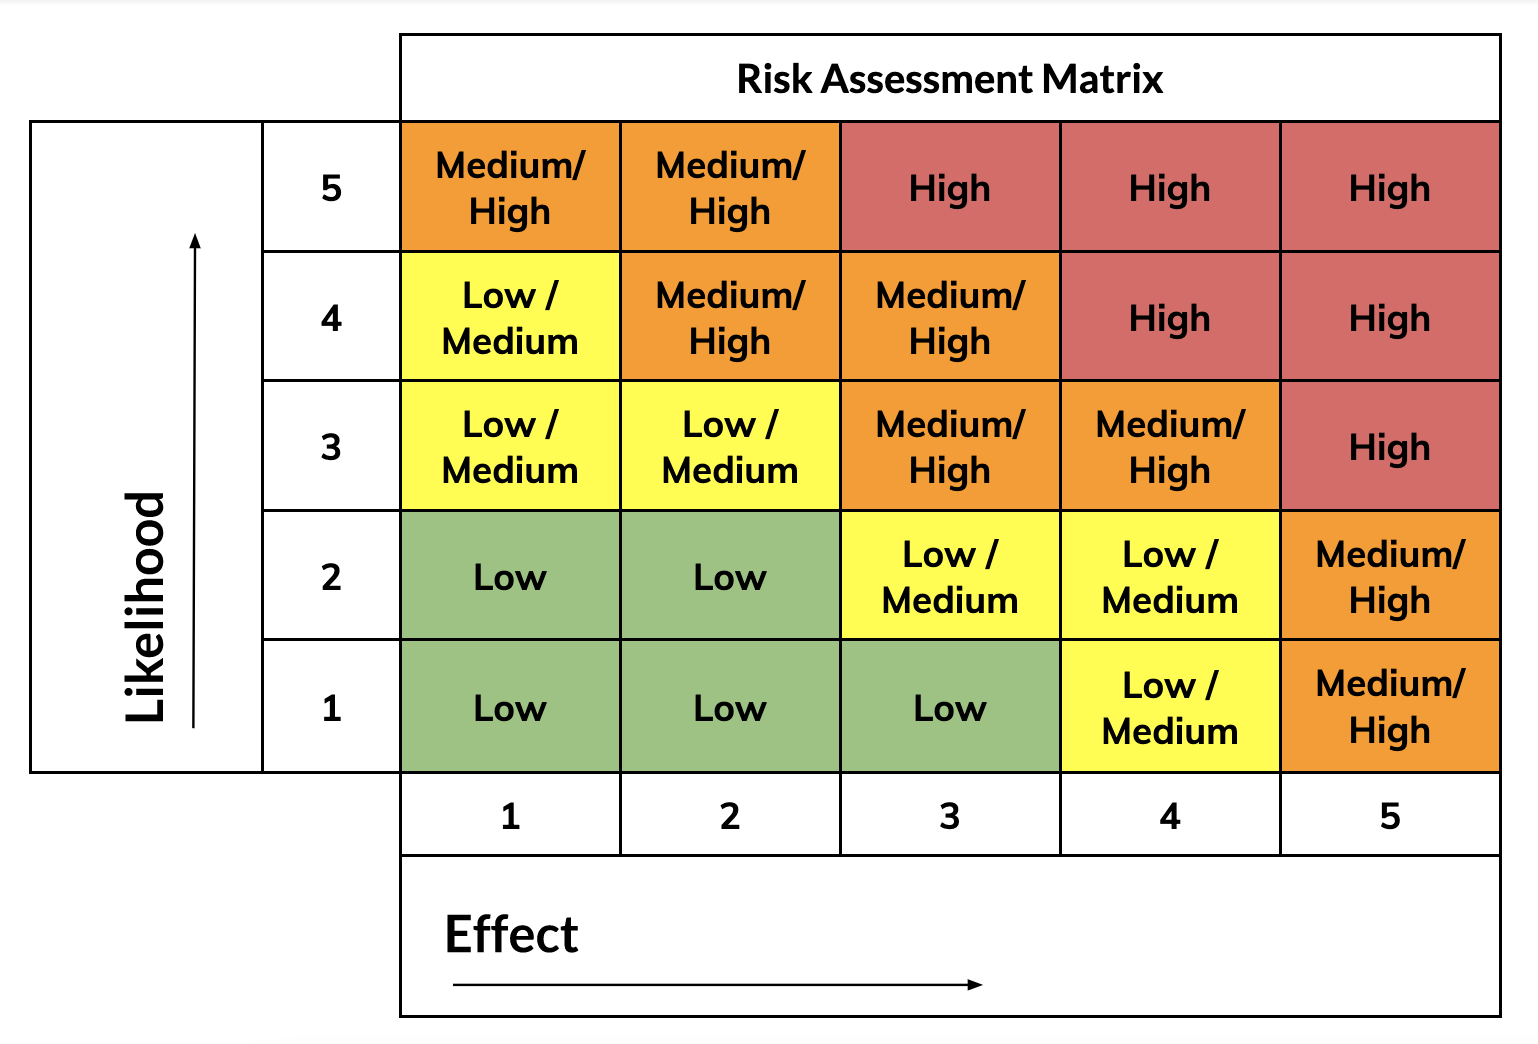
Start with two axes. On the X-axis, you place likelihood ratings. On the Y-axis, severity or impact ratings. The simplest version uses a 1-5 scale for both. Multiply them together and you get a risk score ranging from 1 to 25. Scores in the higher range trigger action. Lower scores get logged and monitored. That's the textbook version. Here's what nobody tells you: the scale choice matters more than the multiplication formula. A 1-5 scale gives you only 25 possible outcomes. In practice, that means your high-risk bucket ends up swallowing half your threats. You lose discrimination. I switched one of my projects to a 1-10 scale for likelihood and a 1-5 for severity, which gives 50 unique scores. Suddenly you can actually tell the difference between a problem that needs immediate attention and one that needs a watch list. Severity isn't just about financial loss. In operational risk, you need to layer it: safety impact, regulatory impact, reputational impact, financial impact. Assign weights to each dimension based on what your organization actually cares about. A healthcare company weights safety and regulatory heavily. A SaaS startup might weight reputational and financial over safety. Don't use a generic matrix and pretend it applies to your context. It won't.
Building It Step by Step
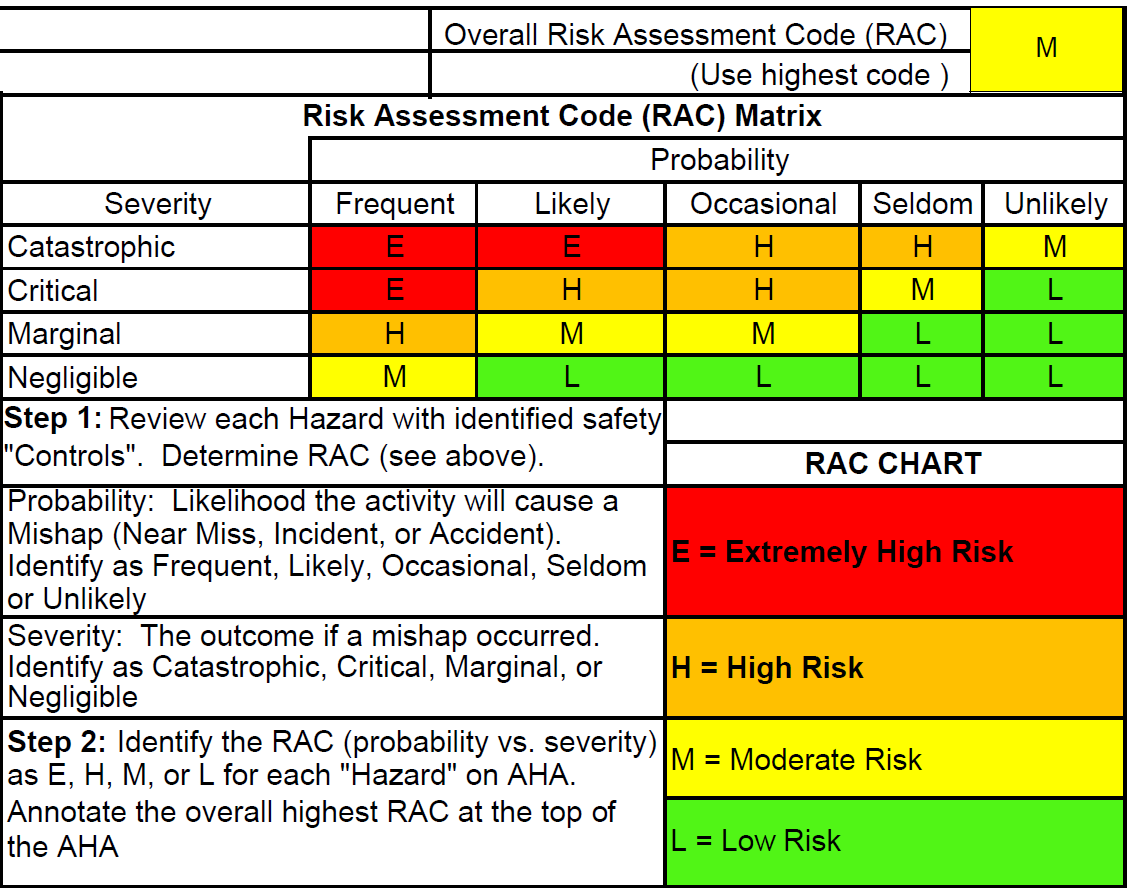
Pick your scales first. Decide whether 1-5 or 1-10 makes sense for likelihood. Keep severity at 1-5 unless you have a genuinely complex impact model. Write down what each number means in plain language so anyone on the team can fill it out without calling you at 11pm. Here's an example of bad calibration: Likelihood "5" is defined as "almost certain to occur within 12 months." But the team fills it out and rates everything as a 4 or 5. The matrix becomes noise. Fix this by anchoring each rating to concrete evidence: past incident data, industry benchmarks, or expert panels. If you don't have historical data, run a Delphi exercise with three subject matter experts and average their ratings. Next, define your risk thresholds. I usually see three bands: low risk (green), medium risk (amber), high risk (red). But don't just split the score range evenly. A score of 8 might be high risk in one domain and acceptable in another. Set thresholds per risk category, not globally. This is where most implementations fail. They create one matrix and apply it everywhere, then wonder why their compliance team is drowning in false positives.
Get the Full Details

Create the actual grid. Use a spreadsheet for the first draft. Map every identified risk to its likelihood and severity score. Calculate the product. Flag anything above your threshold. Generate a report that shows which risks sit in which band and what the top ten are by score.
The Edge Case That Broke My First Implementation
I was working on a supply chain risk project for a mid-size manufacturer. We had a risk around single-source suppliers in a politically unstable region. The likelihood was rated a 3 and severity a 5, giving a score of 15. Medium risk. According to the matrix, it needed monitoring, not immediate action. Three months later, a port strike hit that region. We had no alternative supplier lined up because we hadn't treated the risk as critical. The matrix had failed us. The workaround was straightforward but counter-intuitive. I added a multiplier for concentration risk. Any risk involving a single-source dependency got its severity score automatically bumped by one level. The same risk became severity 6, score 18, and moved into the high-risk band. That triggered the action we should have taken from the start. You can add similar modifiers for dependencies, regulatory exposure, or cascading failure potential. Just document every modifier so auditors and future reviewers understand why the score changed.
Common Pitfalls and How to Avoid Them
Here's what I've learned after building and maintaining these systems across five organizations: Pitfall one: treating the matrix as a one-time exercise. Risk matrices decay. New threats emerge, old threats evolve, organizational priorities shift. Review and recalibrate at least quarterly. Budget two hours per quarter for this. If you skip it for a year, the matrix becomes decoration. Pitfall two: letting subjective judgment go unchallenged. One person's "high likelihood" is another person's "remote possibility." Standardize your definitions, yes, but also require that any risk rated above your threshold be reviewed by at least two people. A second set of eyes catches inflated scores caused by recency bias or fear-mongering.

Pitfall three: confusing the matrix output with the risk decision. The score is a prioritization tool, not a decision engine. A score of 20 doesn't mean you must spend a million dollars mitigating it. It means you need to discuss it at the next risk committee meeting. The actual response depends on cost-benefit analysis, not just the number. I've seen teams stop thinking when they see a high score. That's dangerous. Pitfall four: using too many categories. A 10x10 matrix looks thorough. It creates 100 cells. Nobody can navigate that. Stick to 5x5 or 5x10 max. If you need more granularity, add a scoring modifier like I described above rather than expanding the grid itself.
When a Risk Assessment Code Matrix Isn't the Right Tool
This method works well for qualitative risk assessment where hard data is scarce. It breaks down when you have strong quantitative data available. If you can model loss distributions, run Monte Carlo simulations, or calculate expected monetary value, do that instead. A matrix oversimplifies those scenarios. Use it as a screening tool, not a final analysis. I also recommend against using a standard Risk Assessment Code Matrix for cybersecurity risk. The threat landscape moves too fast and the dependencies are too complex. Consider Fault Tree Analysis or Attack Tree modeling for technical risk, and reserve the matrix for operational and strategic risk categories.
What You Need to Get Started
You need a risk register with identified threats, calibrated likelihood and severity scales, threshold definitions, and a decision to actually use the output. That's it. The spreadsheet template I use has the grid, the calculation formulas, and a separate tab for tracking mitigation actions tied to each risk. I can share a basic version if anyone wants it, but the real value is in the calibration work, not the template itself. Build it. Use it. Review it quarterly. Add modifiers for your specific context. Don't let it become another document that collects dust.