The Unsexy Reality of Building a Risk Management Plan
A risk management plan is not a document you write once and file away. It is a living tracking system that gets ignored by everyone except the person who built it, which is usually the same person the company will blame when things go wrong. I spent about four years building these for mid-market software companies before realizing the industry had almost nothing useful to show people. Most Risk Management Plan Example you find online is either a compliance checkbox exercise or a consultant's PowerPoint dressed up as a framework. Neither helps you actually run a project without losing sleep at 2 AM.
What actually goes into a functional plan
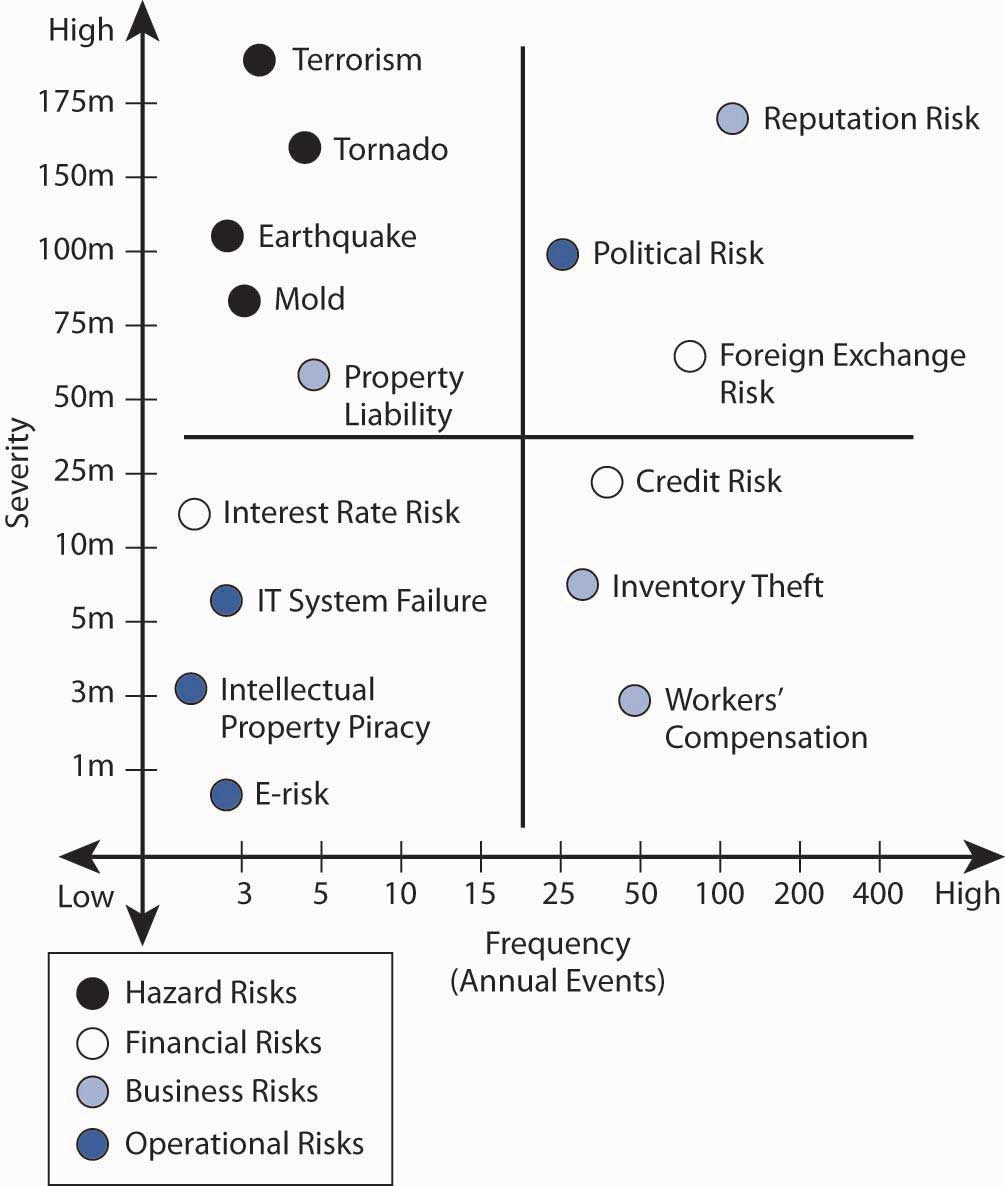
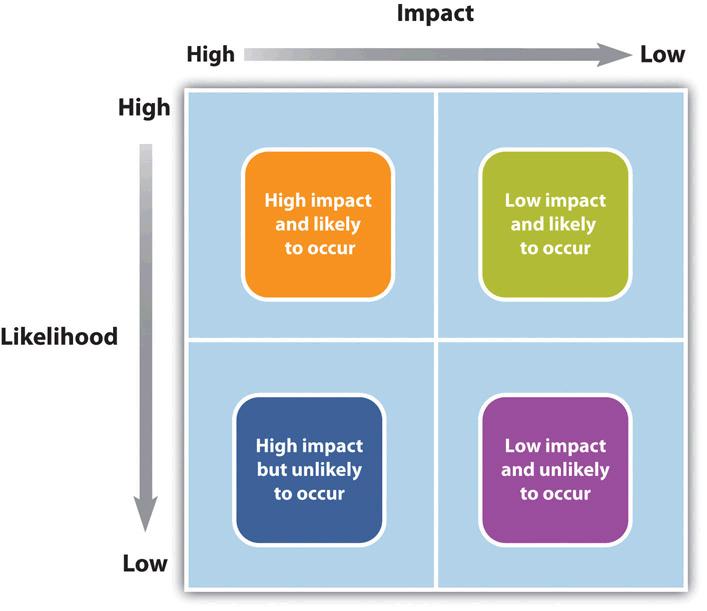
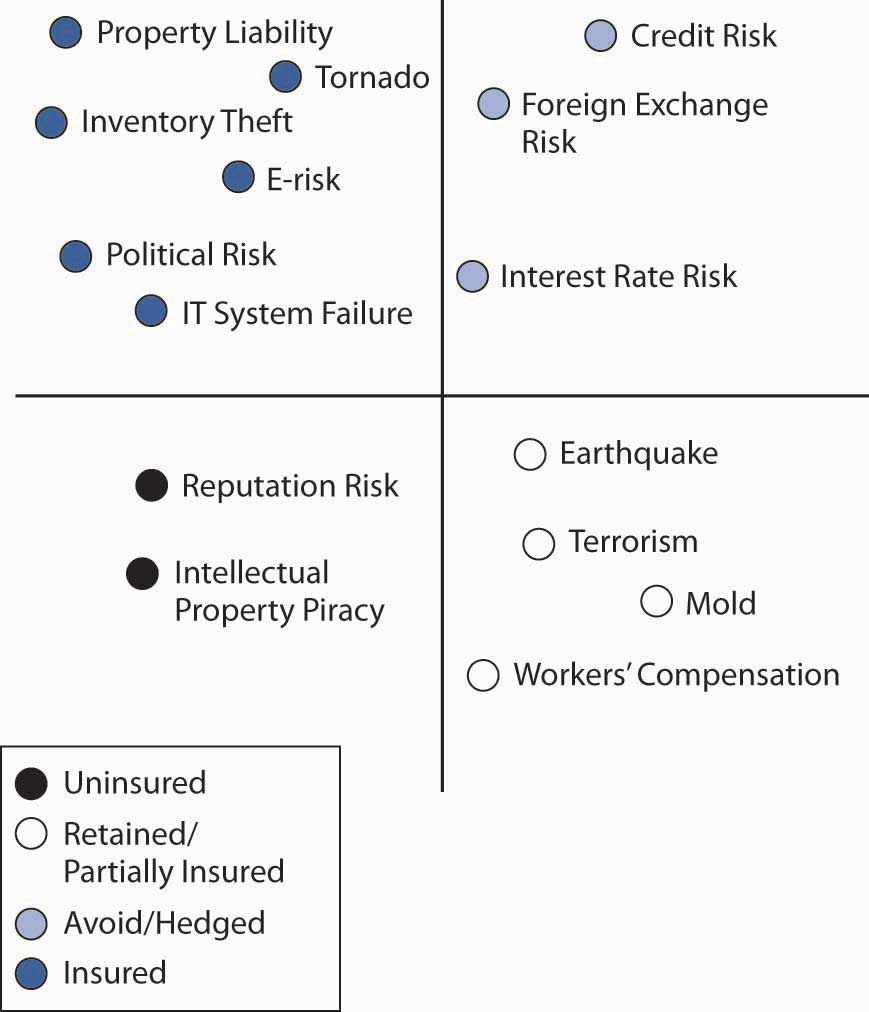
Start with a risk register. This is just a spreadsheet or database with columns for: identified risk, probability, impact, risk score, owner, mitigation strategy, trigger conditions, and status. The risk score is your first multiplier. Probability (1-5) times Impact (1-5) gives you a number from 1 to 25. Everything above 12 requires an active mitigation strategy and regular review. Everything below 5 gets logged but doesn't demand attention unless the conditions change. Probability and impact scales need to be defined in plain language so different team members don't interpret them differently. "High impact" means something different to a developer than it does to a finance person. Write down what each number actually represents in dollar terms or timeline terms. After the register comes the mitigation strategies. These fall into four buckets: avoid, mitigate, transfer, or accept. Avoid means changing the plan so the risk doesn't exist anymore. Mitigate means reducing either the probability or the impact. Transfer means insurance or outsourcing. Accept means you acknowledge it and move on. Most plans I see dump everything into "mitigate" because that sounds proactive. It isn't always the right call.
Then there is the monitoring cadence. You need scheduled reviews—at minimum monthly for active high-risk items. Trigger conditions matter here. Define what events should cause an immediate review rather than waiting for the next scheduled check-in. Supply chain disruption, key personnel leaving, scope changes over 20%, budget variance above 15 percent. These are your tripwires.
Get the Full Details
A concrete Risk Management Plan Example you can adapt
Here is a simplified version of a risk register I've used across multiple projects. This is not a full plan but the core structure: Risk ID: R-001 | Description: Key dependency on single external API provider | Probability: 3 | Impact: 4 | Score: 12 | Owner: Lead Engineer | Mitigation: Build abstraction layer with fallback provider; negotiate SLA with penalty clauses | Trigger: API deprecation notice or 99% uptime drop below 99.5% | Status: Active Risk ID: R-002 | Description: Third-party vendor misses delivery milestone | Probability: 4 | Impact: 3 | Score: 12 | Owner: Project Manager | Mitigation: Phased payment tied to milestone completion; weekly status calls starting 60 days before deadline | Trigger: Missed internal check-in or delay notification | Status: Active
Risk ID: R-003 | Description: Regulatory compliance change in target market | Probability: 2 | Impact: 5 | Score: 10 | Owner: Legal/Compliance Lead | Mitigation: Accept with monitoring; subscribe to regulatory alerts for both EU and US markets | Trigger: Formal regulatory announcement or compliance audit notice | Status: Monitored The full plan would then document the governance structure—who owns what, escalation paths, reporting formats, and the review schedule. That governance section is where most plans die. They list ten stakeholders who all think someone else is responsible for updating the register.
What nobody tells you about risk registers
The biggest mistake I see is treating the risk register as a static artifact. It decays within weeks if nobody maintains it. I learned this the hard way on a healthcare compliance project where we had a solid register at kickoff and it became completely irrelevant three months later because the team stopped updating it during sprint planning. The risks changed but the document didn't know about it. Another counter-intuitive point: you should deliberately leave some risks unmaintained. When you try to track everything with equal rigor, nothing gets tracked properly. Pick your top five to ten risks and give them real ownership with real review cycles. The rest get quarterly status checks at most. This is not negligence. It is resource allocation. Also, your impact scores should reflect the organization's actual risk tolerance, not theoretical worst cases. If your company can absorb a two-week delay without funding panic, then a two-week delay is low impact regardless of what the textbook says. I once worked with a team that scored every schedule risk as "critical" because they were following a generic methodology. We ended up with seventeen critical risks and zero ability to prioritize. That is worse than having three critical risks and a clear plan for each.
The workaround I ended up relying on
During a cloud migration project, our original risk register missed a category entirely: data reconciliation risk. We had planned for downtime, vendor issues, and staffing gaps. We did not plan for the possibility that the migrated data would contain silent corruptions—incomplete records that passed validation checks but were actually wrong. This was not in any standard risk framework I had seen. The workaround was adding a "risk category gap analysis" step before finalizing the register. For each major work stream, we asked: what could go wrong that is not already covered by existing risks? We ran this as a structured session with people who actually do the work, not the people who manage the paperwork. That session surfaced the data corruption risk, and we built a validation testing protocol around it before migration began. This turned out to be the most valuable hour of risk planning we did. The migration itself had complications but we caught the data integrity issues in testing because we had specifically planned for silent failures rather than just visible ones.
Where this approach breaks down
The primary limitation is that risk management plans assume a level of organizational stability that rarely exists. If your project has frequent leadership changes, shifting priorities, or unclear decision-making authority, the plan becomes a waste of time. You cannot maintain a risk register when the person who owns it gets reassigned every six weeks. Another honest bottleneck: these plans create a false sense of security. Stakeholders see a comprehensive document and assume the project is well-managed. It is not. The plan captures known risks and plausible unknowns. It does not capture black swan events or competent incompetence. A detailed risk register will not save you from a project manager who consistently understates timelines or an engineer who hides technical debt. If your organization treats a Risk Management Plan Example as a compliance requirement rather than a decision-making tool, the investment yields diminishing returns quickly. I have seen companies spend weeks perfecting their risk frameworks and then ignore them completely during execution because nobody in leadership cared about the output. The plan existed on paper and in nothing else.
In those situations, a lighter approach works better. A simple living document updated during regular standups or sprint reviews, with only the current top five risks discussed explicitly, tends to produce more honest risk awareness than a formalized register that gets buried in a shared drive. The structure matters less than the habit of discussing what could go wrong on a regular basis.
Practical implementation steps
Week one: identify your risk owners and collect initial risks through structured interviews with people who know the work. Do not rely on workshops with large groups. Individual conversations surface different concerns. Week two: score the risks, assign mitigations, and define trigger conditions. Run the gap analysis I described above. This usually takes two to three hours per major project area. Week three: socialize the plan with stakeholders and adjust based on their input. This is where you learn what the organization actually tolerates versus what it claims to prioritize.
Thereafter: schedule the review cadence, assign ownership, and integrate risk discussion into existing meetings rather than creating new ones. Adding a dedicated risk meeting is the fastest way to ensure the risk process fails. People will treat it as administrative overhead and stop engaging with it within a month. The register itself should live somewhere the team actually works—connected to your project management tool, your documentation platform, or your issue tracker. A standalone document that requires manual updates gets abandoned. An integrated system where risks appear alongside tasks and sprints stays visible. I have found that the most effective risk management plans are the ones nobody notices after the first month. They work because the risks are handled through normal project operations rather than requiring special attention. When a risk register demands constant manual updates and explicit review meetings, it is probably trying too hard. When it quietly lives inside your existing workflow and surfaces only when something actually goes wrong, that is when it is doing its job.