Getting Risk Management Policies Right Without the Corporate Fluff
I spent three years watching companies treat risk management policies like a compliance checkbox. Most of them never actually do anything useful because the documents sit on a shared drive, outdated since 2019. The ones that work follow a different pattern entirely. I learned this after a project at a mid-size fintech where a single undocumented workaround for payment reconciliation cost us a regulatory fine, and the policy document couldn't even locate the right person to blame. The reality is that good risk management policies exist in two layers. The written layer is the formal document. The operational layer is what actually happens when someone bypasses a control because the control is impractical. You need both. If you only have the written layer, you have a paper shield that looks convincing until something goes wrong.
Risk Management Policies Examples That Actually Work in Practice
Let me walk through a few specific examples. Not the textbook versions. The versions you see when someone has actually lived with the consequences of getting them wrong. Take third-party vendor risk assessment. The basic policy says all vendors must be reviewed before contract signing. This is correct but useless if your procurement team isn't told to stop and wait for the review. I saw this fail at a SaaS company where engineers would provision test accounts for vendors without going through the security team. The policy existed, but the actual workflow had no enforcement point. The fix was adding a procurement system checkpoint that physically prevented purchase orders from being created without a completed vendor risk form. It took two weeks to implement and eliminated the workaround completely. Another example is change management for production systems. A common policy states that all production changes require approval from a technical lead. The problem I encountered was that teams started routing changes through fake approval chains. Someone would document a change request, a lead would approve it within minutes without reviewing anything, and then the change would break something. The policy was technically followed but operationally hollow. What we ended up doing was introducing a minimum review window. Changes had to sit for at least four business hours before approval could be given, and we tracked the average review time. If a lead was approving everything in under ten minutes, that triggered an audit flag. Approval quality went up noticeably after that change, not because we added more bureaucracy, but because we made rubber-stamping harder to do.
Access provisioning policies are another area where most examples fail. The standard wording is something like employees should have access only to what they need. That's fine as a principle. The practical failure is that people get promoted, transferred, or their role changes and nobody revokes the old access. I worked with a company where a former database administrator still had production write access six months after moving to a marketing role. The policy required quarterly access reviews, but the reviews were just checkboxes that managers signed without actually verifying each permission. We replaced the quarterly review with an automated script that compared current access against role templates and flagged anything that didn't match. False positives took about two days to resolve, but the coverage was far better than what manual reviews ever produced. Data classification policies look simple on paper but are notoriously hard to enforce. The typical example is classifying data as public, internal, confidential, and restricted. The difficulty is knowing what data you actually have and where it lives. A healthcare client of mine had a policy document that was thorough on paper but they had no inventory of where patient data was stored across legacy systems. The policy said restricted data must be encrypted at rest and in transit, but half the systems didn't support encryption. They spent about eight months building a data discovery and inventory process before the policy became actionable. The policy was correct. They just needed infrastructure to back it up.
Get the Full Details
The Counter-Intuitive Stuff Nobody Tells You About Early On
One thing that surprised me early in my career is that having fewer, simpler controls often produces better risk outcomes than having many complex ones. A single well-understood approval gate beats five overlapping controls that everyone ignores because they cancel each other out. I once reviewed a company's information security policy and counted forty-three separate controls in the access management section. Half of them were contradictory. Three of them required approval from the same person. None of them were consistently enforced. We reduced the policy to eleven controls and the enforcement rate went from about thirty percent to over eighty percent within a quarter. Less is genuinely more here. Another counter-intuitive point is that risk management policies should deliberately include escape hatch procedures. If your policy says there is no exception process, people will create shadow processes. I recommended building formal exception handling into every major policy. The exception should require documented business justification, named approver authority, expiration dates, and mandatory review. This makes exceptions visible instead of hidden. Hidden exceptions become your biggest risk because nobody knows they exist until something breaks. The biggest pitfall I see is treating policy as a static deliverable. Policies decay. Technology changes, regulations shift, teams reorganize. A policy written two years ago is probably already outdated in significant ways. The companies that handle this well treat policy maintenance as an ongoing operational task, not an annual exercise. They assign ownership, set review calendars tied to regulatory deadlines, and track policy version history. I track this with a simple spreadsheet that maps each policy to an owner, a last review date, a next review due date, and any active exceptions. It takes about fifteen minutes a week to update and catches drift before it becomes a problem.
Here is a blunt assessment of what doesn't work. Automated risk scoring tools that claim to evaluate your entire risk posture from questionnaires are mostly noise. They give a single score that sounds scientific but is built on assumptions you didn't validate. I used one for a compliance audit and the tool gave our security program an A rating while we were simultaneously struggling with unpatched critical vulnerabilities. The questionnaire was too abstract to catch implementation gaps. These tools have a place for initial screening, but they should never replace actual technical verification of your controls. Similarly, insurance-based risk transfer should not be confused with risk management. Buying cyber liability insurance is a financial decision. It does not reduce the probability of a breach. I have seen companies reduce their security spending because they thought the insurance policy covered everything. It didn't. The policy had exclusions for unpatched systems, and we had a known unpatched vulnerability at the time of the incident. The claim was denied. Insurance is a secondary measure. It covers financial impact. It doesn't prevent the impact from happening. If you are building your first risk management framework from scratch, start with the three areas that cause the most real damage. Access control, change management, and incident response. Get those documented, assigned, and tested before you worry about business continuity planning or third-party risk maturity models. The later areas matter, but the early ones are where most incidents actually originate. I usually recommend spending about three months getting the foundational policies right before expanding into the broader framework. Most people rush through this and end up with a lot of policy documentation that doesn't cover what they actually care about when something goes wrong.
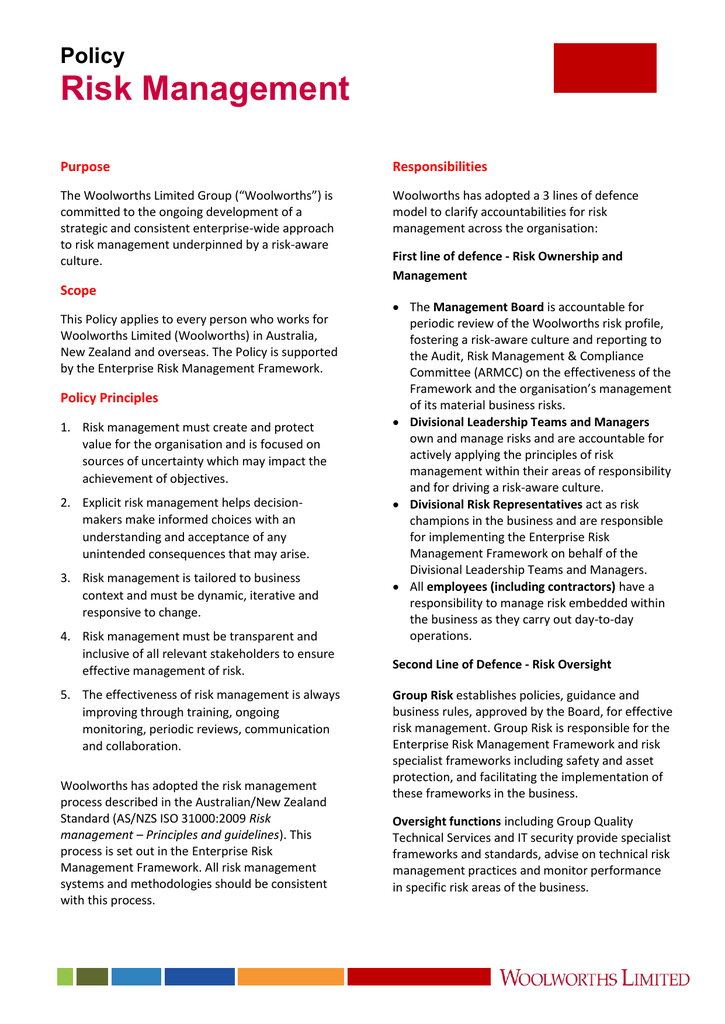
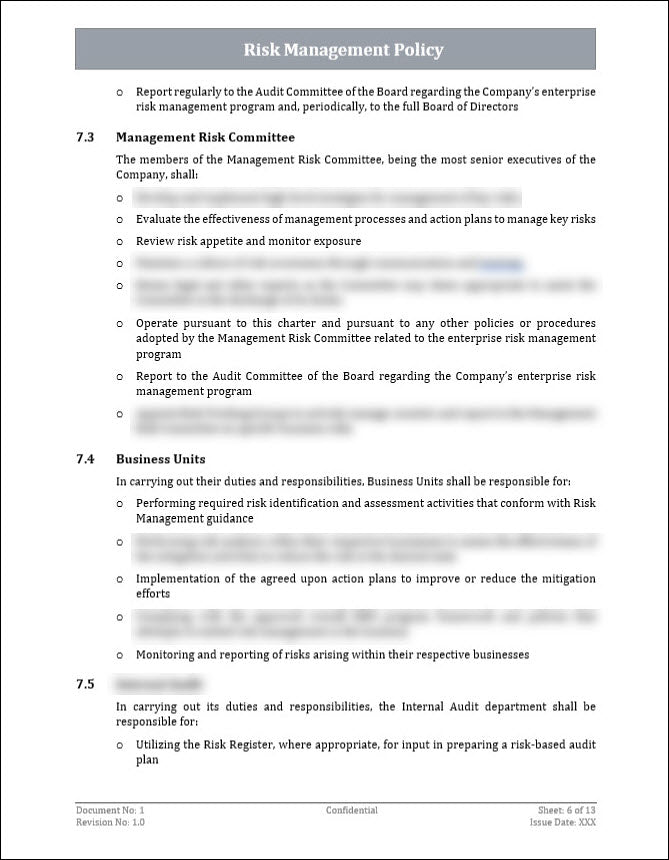
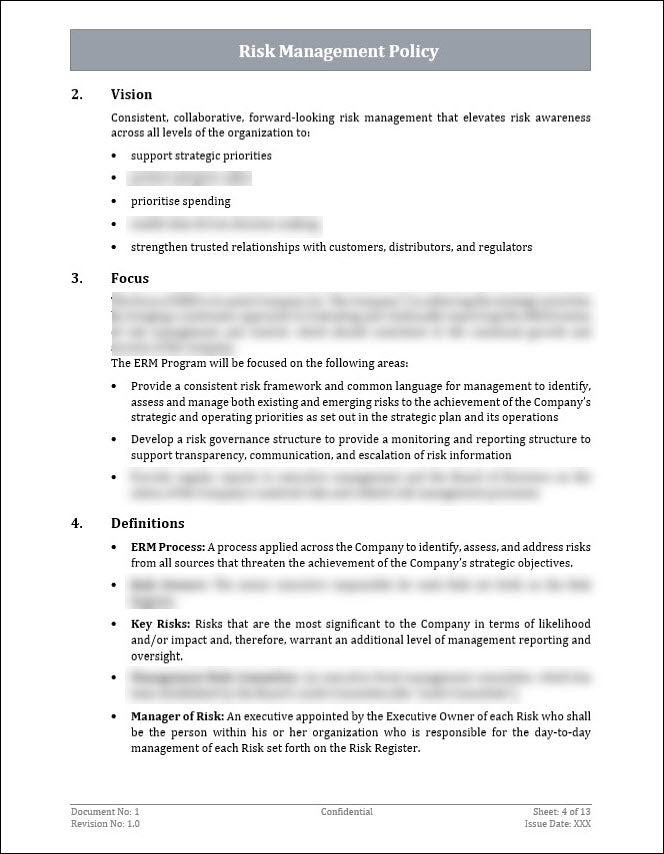
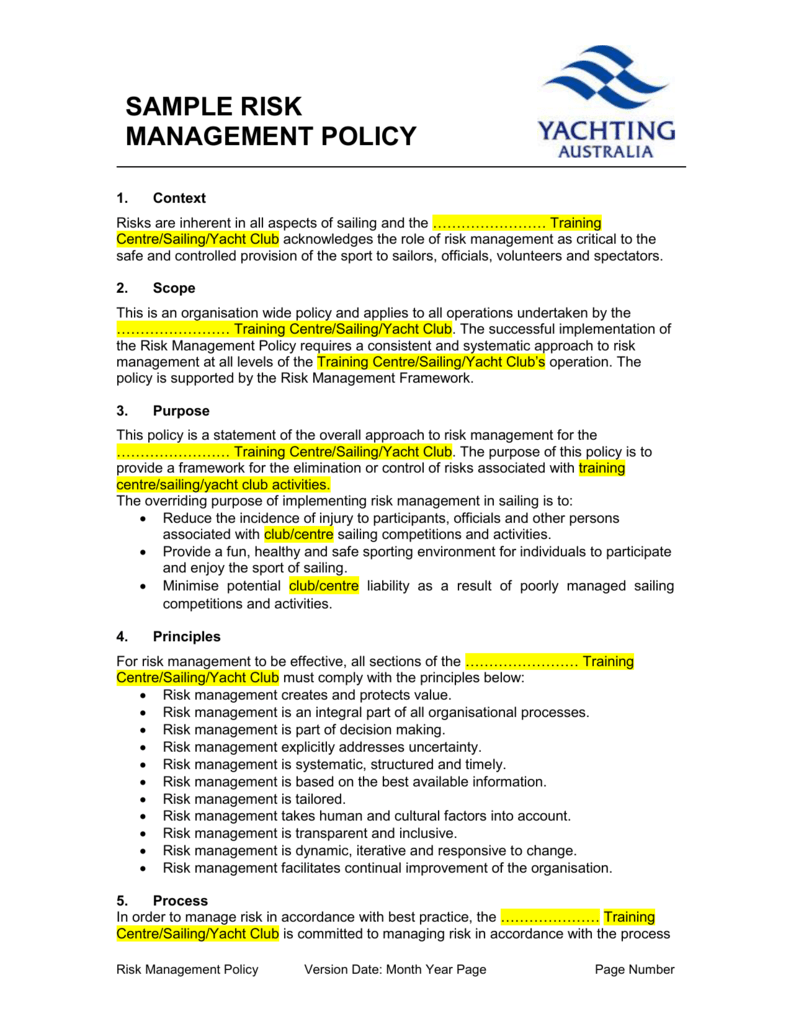
The downloadable template I keep refers to is a simplified version of a policy governance document. It includes sections for policy purpose, scope, roles and responsibilities, control requirements, exception handling, review cycle, and version history. It is not a complete framework by itself, but it gives you a structure to build on rather than starting from a blank page. You can use it as a starting point and adapt it to your specific environment. The structure matters more than the exact wording. Your legal and compliance teams will want to review it anyway before it goes live. One final note that applies more broadly than just this topic. Risk management policies are only as good as the organization's willingness to enforce them. A well-written policy that nobody follows is worse than no policy at all because it creates a false sense of security. People read it, assume they are protected, and then make decisions based on that assumption. If you cannot enforce a policy, do not write it. Write something you can actually uphold and review it regularly to make sure you can. That is the practical truth behind every example that works.