Converting Arabic Script to English Text
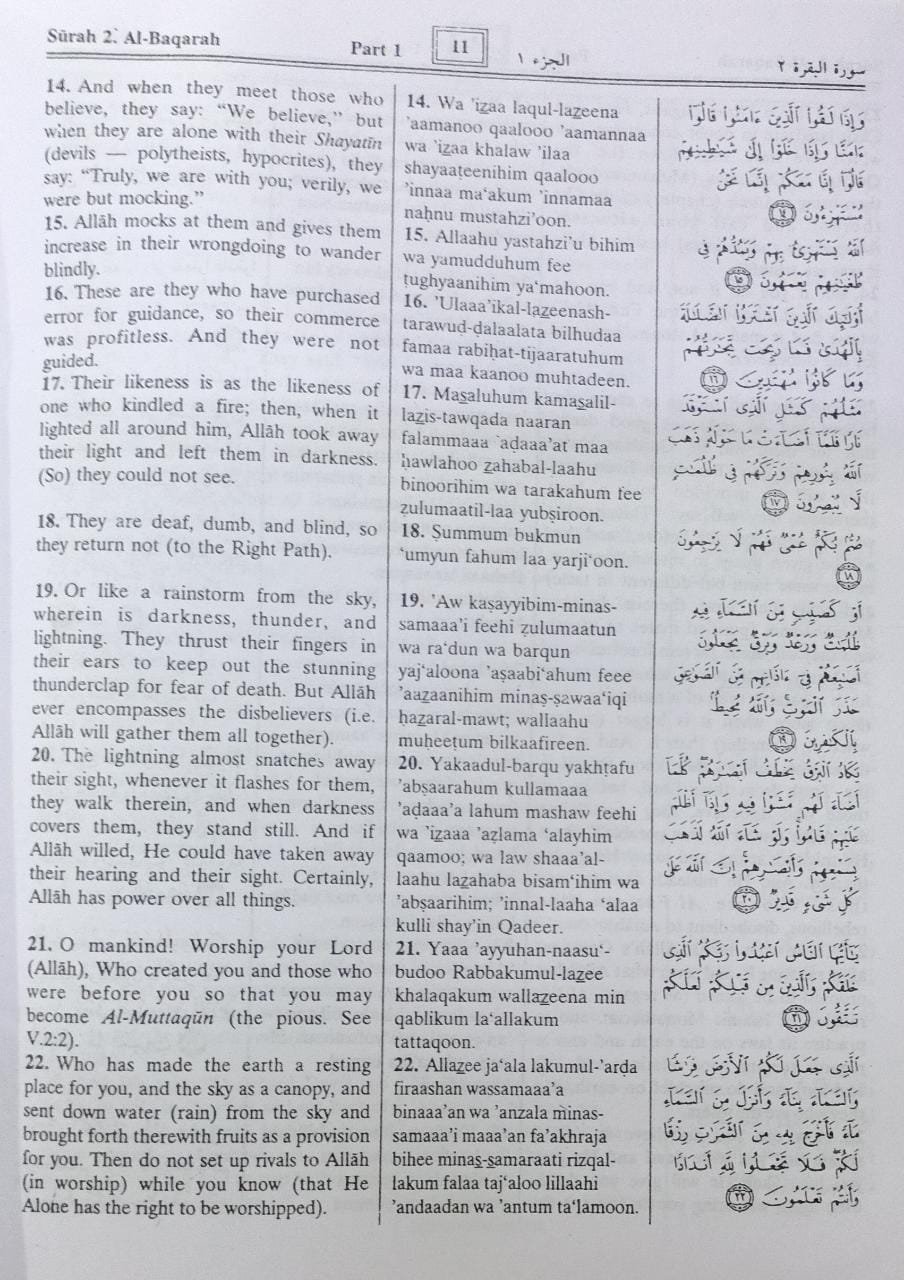
I spent a few weeks last year dealing with a dataset of handwritten Arabic notes that needed to be searchable in English. Not translated, just readable for people who can't follow the script. The process turned out to be messier than I expected, and I kept running into the same issues repeatedly. The core problem is that Arabic has sounds that don't exist in English. There's no single correct way to represent them. The letter ain, for example, could be written as ' (apostrophe), gh (as some systems do), or left as a plain letter in casual usage. Each choice leads to different results when someone searches for it later. There are formal transliteration systems like ISO 233 and ALA-LC, but nobody actually uses them outside academic publishing. They're precise, yes, but they produce output like "amāmahum" that regular English speakers find completely alien. For practical purposes, you want something closer to how people actually type when they write Arabic using Latin characters. That's what most of us call romanization or arabizi.
The basic approach is character-by-character mapping. Take this list: a
b
t
th
j
h
kh
d
dh
r
z
s
sh
s
d
t
z
' or e
gh
f
q
k
l
m
n
h
w/o
y/i I know that looks like a lot. But once you have it, you can string it together and start processing text in bulk. I wrote a simple Python script using a dictionary mapping that converted a 400-page document in about twenty minutes. Hand-copying it would have taken me roughly three weeks.
Tools That Actually Work
If you don't want to write your own converter, there are a few options. Online tools like Transliterator.org and the Arabic Romanization tool from the Endangered Languages Archive both handle decent bulk conversions, though they struggle with dialectal variations. The Kamus project on GitHub has one of the more robust open-source implementations I've tested. For people who just need a quick answer without setting up software, Google Docs with the "Transliterate" feature under Tools works surprisingly well for Modern Standard Arabic. It won't handle dialects, classical texts, or poorly formatted input. But for standard printed Arabic, it does the job in seconds. I ran into a specific edge case that I didn't expect. Some Arabic texts use the Persian/Urdu letter (jeem with two dots below) which maps to g in English. My initial script didn't account for it, so every word containing that letter came out wrong. I had to add it manually to my mapping dictionary. If you're working with any South Asian Arabic texts or certain dialects, check whether your source material uses these extended characters before you start processing.
Get the Full Details

Pitfalls That Will Waste Your Time
The biggest issue isn't the translation itself. It's the diacritical marks, or tashkeel. Most Arabic text in the wild has no harakat at all. That means the letter could be ba, bi, or bu depending on context, and without vowels you're guessing. A tool can only do so much here. If you need accurate pronunciation guidance, you're looking at manual correction anyway, which basically defeats the purpose of automated conversion. Another problem is the hamza. The letters all represent glottal stops or vowel sounds, but they're written differently depending on their position in a word. My first conversion run produced nonsense like "saeal" instead of "sa'al" because I hadn't accounted for the vertical placement rules. Adding positional logic to the script added about an hour of work upfront but saved me from spending the rest of the week fixing errors by hand. Numbers are also a surprise for people new to this. Eastern Arabic numerals () are still widely used alongside Western ones, especially in Egypt and the Levant. A straightforward character map won't touch them. You'll need a separate substitution step if your source text mixes scripts and numeral systems.
If you're dealing with dialectal Arabic rather than MSA, be aware that no standard system exists. Egyptian speech, Gulf Arabic, and Levantine Arabic each have distinct phonological features that romanization conventions barely cover. "Ch" for the Levantine jeem, "7" for in chat Arabic, "3" for ain — these are informal conventions that work for social media but fall apart in anything formal. Pick your convention early and stick with it across the entire project. The conversion step itself is fast. Twenty minutes for four hundred pages is typical with a basic script and a clean source. But the real time sink is always post-processing. You'll spend far more time deciding whether a particular word was rendered correctly than you will running the automated conversion. If your text has heavy diacritics, mixed dialects, or handwritten source material, budget accordingly. For clean printed MSA text, expect the total workflow to take about forty-five minutes from start to verified output on a document of that size.