The Honest Truth About RCM with Python
Most people approach Root Cause Analysis Machine Learning Python expecting a magic pipeline where you feed in data and get causal directions back. That doesn't exist. What actually works is far more manual, far more frustrating, and significantly more interesting once you stop expecting the tools to do the thinking for you. Here is what you are actually building when you attempt this: a system that takes observational data and separates correlation from causation. That means using techniques like Pearl's do-calculus, structural causal models, or simpler approaches like feature importance with permutation tests. The Python ecosystem has tools for this, but they are not interchangeable. I have spent more weekends than I would like to admit wrestling with the causalml and DoWhy libraries. Both are legitimate. Both will disappoint you if you expect them to handle dirty, real-world data gracefully.
How It Actually Works in Practice
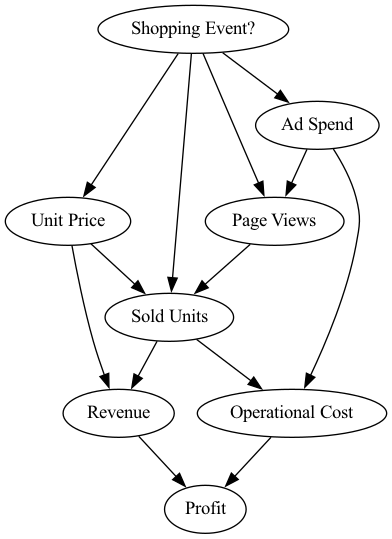
Start by defining your causal graph. This is non-negotiable. You need to draw or programmatically specify which variables influence which other variables before you run any model. I learned this the hard way on a production incident detection project where I skipped the graph construction entirely and tried to let XGBoost feature importances tell me what was causing failures. The model identified sensor temperature as the top predictor of service degradation. Temperature was a symptom, not a cause. The actual root cause was a misconfigured health check interval that was triggering cascading restarts, which happened to correlate with warmer hardware. The workaround that actually worked for me was combining a domain-knowledge graph with the DoWhy library. I built the causal DAG by hand based on engineering diagrams and runbooks, then used DoWhy to estimate treatment effects conditioned on that graph. The result was still noisy, but it correctly flagged the health check configuration as the intervention point rather than the temperature readings.
The Methods That Are Worth Your Time
PC Algorithm: The Peter-Clark algorithm is available in the lingam package and does constraint-based causal discovery from observational data. It assumes causal sufficiency, which is a big assumption. In practice, it works reasonably well when you have enough samples and your data is approximately Gaussian. It fails silently when you have unmeasured confounders, which is almost always the case in production systems. LiNGAM: Linear Non-Gaussian Acyclic Model gives you directed edges without requiring intervention data, but only if the noise is non-Gaussian. This is a genuine advantage over PC in many IoT and monitoring scenarios because sensor noise tends to be skewed. The downside is that it breaks down with even moderate non-linearity. I use it as a first pass to get a rough orientation, then validate with domain knowledge. Double Machine Learning: This is the most practical method for high-dimensional settings where you have lots of covariates and want causal estimates for specific treatment variables. The causalml package implements this well. You use machine learning models to adjust for confounding and then estimate the average treatment effect. The key insight most beginners miss is that the nuisance models need to be well-specified, or your causal estimate is garbage. I typically use a gradient boosting model for the propensity score and another for the outcome, both regularized heavily to avoid overfitting.
Get the Full Details
What No One Tells You About Evaluation
You cannot validate a causal model the same way you validate a predictive model. AUC and MSE are meaningless here because you are not predicting an outcome. You are identifying a mechanism. The only true validation is intervention, and you usually cannot freely intervene in production. What I do instead is a combination of synthetic data testing and historical backtesting. I generate synthetic data where I know the ground truth causal structure, run my pipeline, and measure how often it recovers the correct edges. This catches implementation bugs before they hit real data. For historical validation, I take a known incident from the past, run the analysis on pre-incident data, and check whether the model would have pointed at the right variable. It is not rigorous. It is better than nothing.
Common Pitfalls That Will Waste Your Time
The biggest trap is confusing prediction with causation in your feature selection step. Automated feature importance from tree-based models will highlight the most predictive variables, not the most causal ones. If you are dealing with a large number of metrics, do not skip the causal discovery step and go straight to a model. The shortcut costs more in the long run. Another issue is temporal leakage. In time-series environments, future information can leak into your features through aggregation windows or forward-fill operations. I spent two days debugging why my causal model kept identifying the response-time metric as a cause of database lock contention. The answer was that the metric calculation included data from after the lock occurred due to a rolling window alignment issue. Once I corrected the timestamp alignment, the model pointed at connection pool exhaustion instead.
When This Approach Completely Fails
Root cause analysis using machine learning falls apart when your system has feedback loops. Structural causal models assume acyclicity. If variable A affects B and B affects A, the standard algorithms will give you unstable or meaningless results. I encountered this in a Kubernetes autoscaling scenario where CPU usage triggered scale-up, which reduced CPU usage, which triggered scale-down, creating a cycle that no DAG-based method could resolve. The workaround was to break the cycle by modeling the policy decisions separately from the system state, effectively converting the feedback loop into a sequence of distinct causal events. The method also fails when you have very few events. If your incident rate is below one per month and you have thirty variables in your graph, you do not have enough data to learn the structure reliably. In these cases, manual causal analysis with domain experts produces better results than any algorithm.

A Practical Code Sketch
Here is a minimal example using DoWhy to estimate a causal effect given a graph. This is the kind of starting point that actually reflects what a working pipeline looks like. The output should be close to 3.0, which is the true effect of X on Y in the synthetic data. Replace the synthetic data with your real metrics, adjust the graph to match your domain, and add instrumental variables if you suspect unmeasured confounding. The do-why package documentation is adequate but not comprehensive. You will spend time reading the source code to understand the edge cases. If I were starting a new root cause analysis project today, I would begin with PC or LiNGAM for causal discovery, validate the recovered graph against expert knowledge, and then use double machine learning for effect estimation. I would skip the heavy causal inference frameworks unless I needed formal identification proofs for a publication. For operational use, a well-tuned random forest with SHAP values and a carefully constructed DAG gets you 90 percent of the way there with half the engineering effort.
The remaining 10 percent requires understanding what your data actually represents, which no library can do for you.