When your floating point math stops matching reality
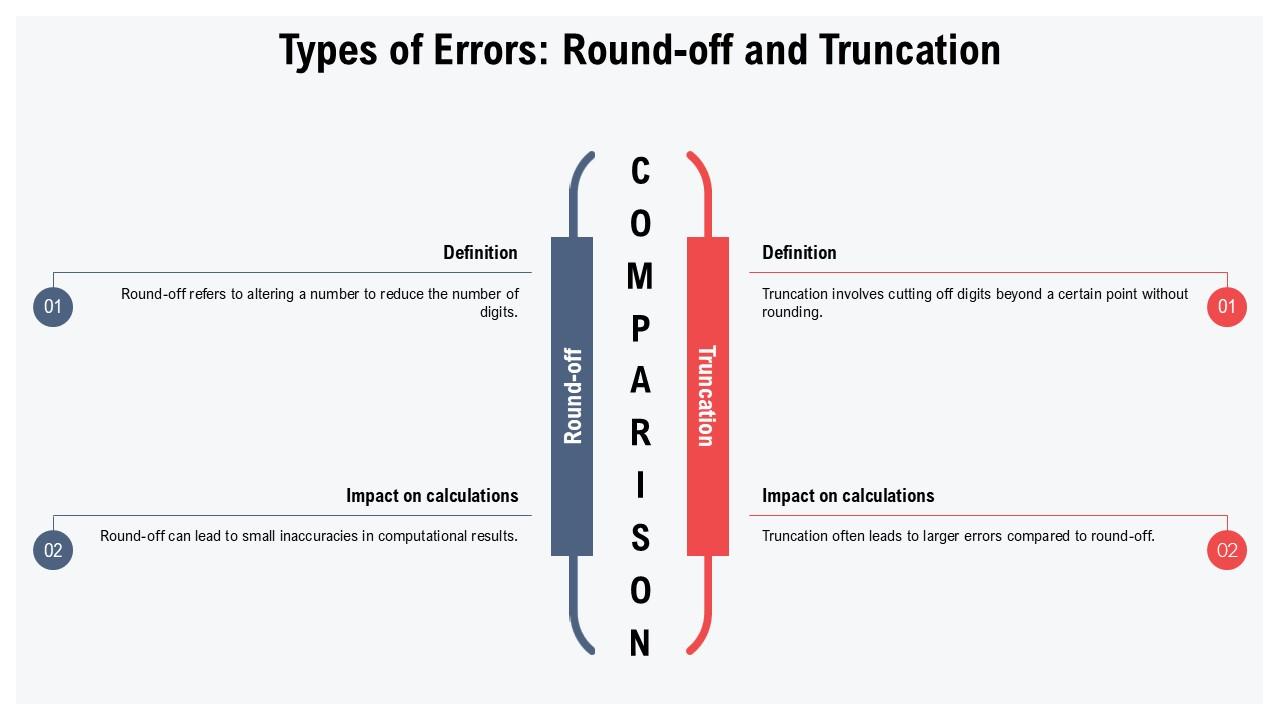
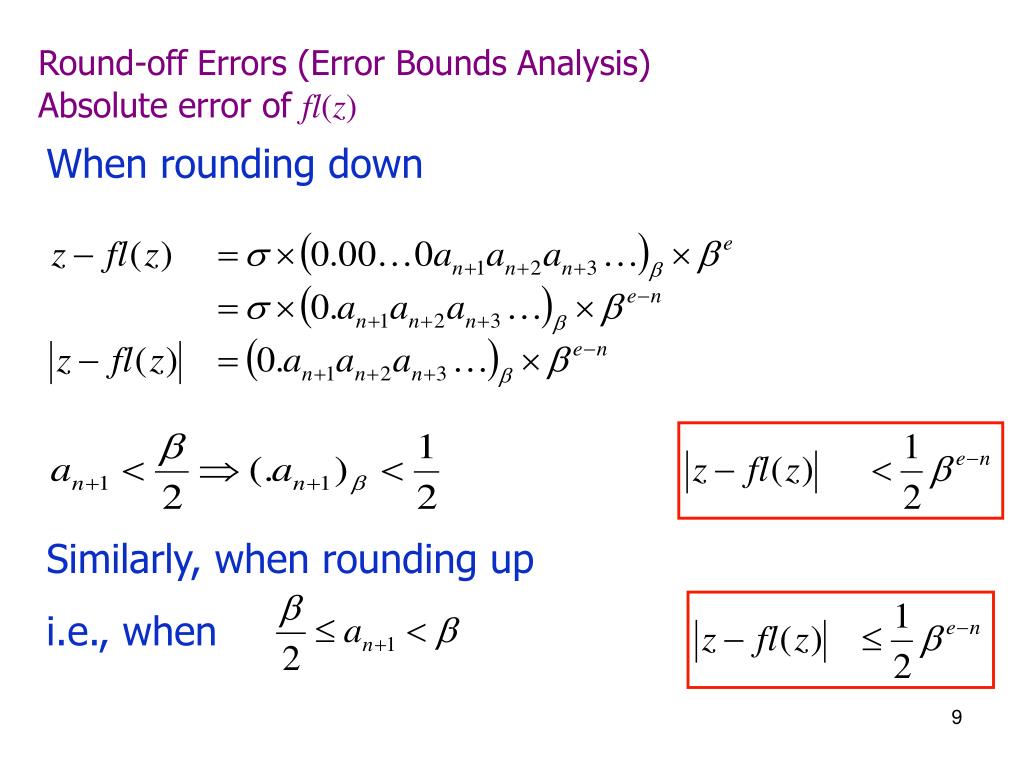
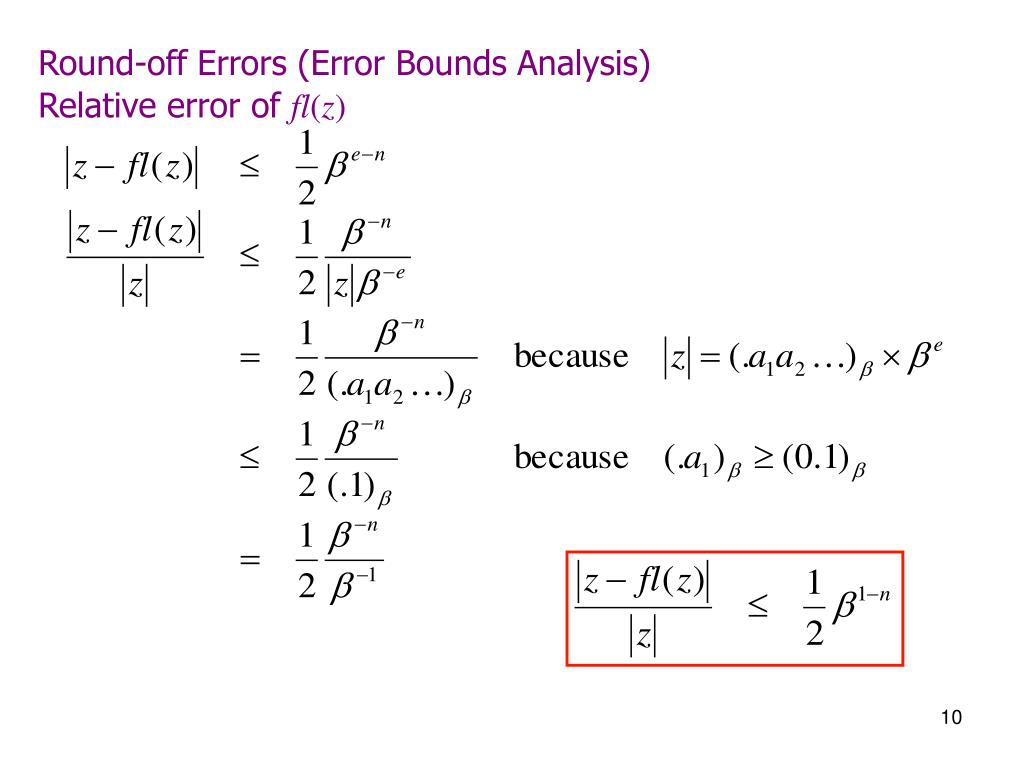
I've spent years working with numerical computation, and the two most common precision killers people run into are round-off error and overflow error. They're different problems, they look different, and they require different fixes. Most people treat them like the same thing until their pipeline blows up. Round-off error happens because computers can't represent every real number exactly. That's it, fundamentally. A double-precision float gives you about 15-17 significant decimal digits. Anything beyond that gets truncated or rounded depending on your system's rounding mode. This is deterministic but cumulative. In a long loop doing additions, each step introduces a tiny error that compounds. I once had a financial calculation that drifted by about 0.03 over 50,000 iterations. Totally within expected behavior for IEEE 754, completely unacceptable for the actual business logic. The fix was using a decimal type or running the accumulation in a higher-precision workspace. I switched to fixed-point arithmetic scaled by 10,000 internally. Took about an hour to refactor, saved me from having debugging sessions that lasted weeks. Overflow is more dramatic. It happens when a calculation produces a result that exceeds the maximum value your data type can hold. For a 32-bit float, that's roughly 3.4 times ten to the 38th power. Multiply two large numbers, feed a numerical method too far, or forget to check bounds in a recursive routine and boom, you get infinity or a negative number where a positive one should be. Underflow is the cousin — results so close to zero they get rounded to zero entirely, which silently destroys accuracy in normalization routines.
Here's something beginners almost never expect: round-off error can actually cause what looks like overflow in iterative methods. When subtracting two nearly equal large numbers during a step, the catastrophic cancellation produces garbage, and that garbage can then explode in the next iteration. The root cause wasn't overflow at all. It was precision loss from subtraction. I've seen entire research pipelines fail because someone didn't recognize that pattern and kept throwing bigger data types at it instead of reformulating the algorithm. The overflow path is more straightforward to diagnose but less forgiving to fix. You can guard it with checks, yes. Compare against your type's max before executing an operation. But that adds branching and slows things down. A cleaner approach for scientific code is to work in log space when dealing with products and quotients of very large or very small numbers. Log turns multiplication into addition, and addition rarely overflows in the same way. My experience has been that this approach works well for probability calculations and likelihood functions, but it falls apart fast when you need differences, because log(a - b) isn't a stable operation either. There's no universal solution here. For round-off, the go-to mitigation is Kahan summation or similar compensated summation techniques. Instead of a plain accumulator, you track a running correction term that captures the low-order bits that get lost at each step. It adds a few operations per loop iteration but keeps the error bounded relative to the machine epsilon rather than growing with the square root of the iteration count. I use this anywhere I'm summing more than a thousand floating point values where the magnitudes vary significantly.
Another practical consideration: the hardware matters. On x86, intermediate calculations sometimes happen in 80-bit extended precision even when your variables are declared as doubles. This means the same code can produce slightly different results across compilers or optimization levels. That's not a bug in your code, it's the hardware doing what it was designed to do. If reproducibility matters, you need flags like -ffloat-store or equivalent compiler directives to pin everything to the declared precision. Without them, you're not guaranteed bitwise identical output across builds, which breaks test suites and makes debugging numerical issues feel like chasing ghosts. Overflow detection libraries exist for most languages. In C and C++, checking for infinity with isnan or checking against numeric limits from
Get the Full Details