Computing Descriptive Statistics Without Overthinking It
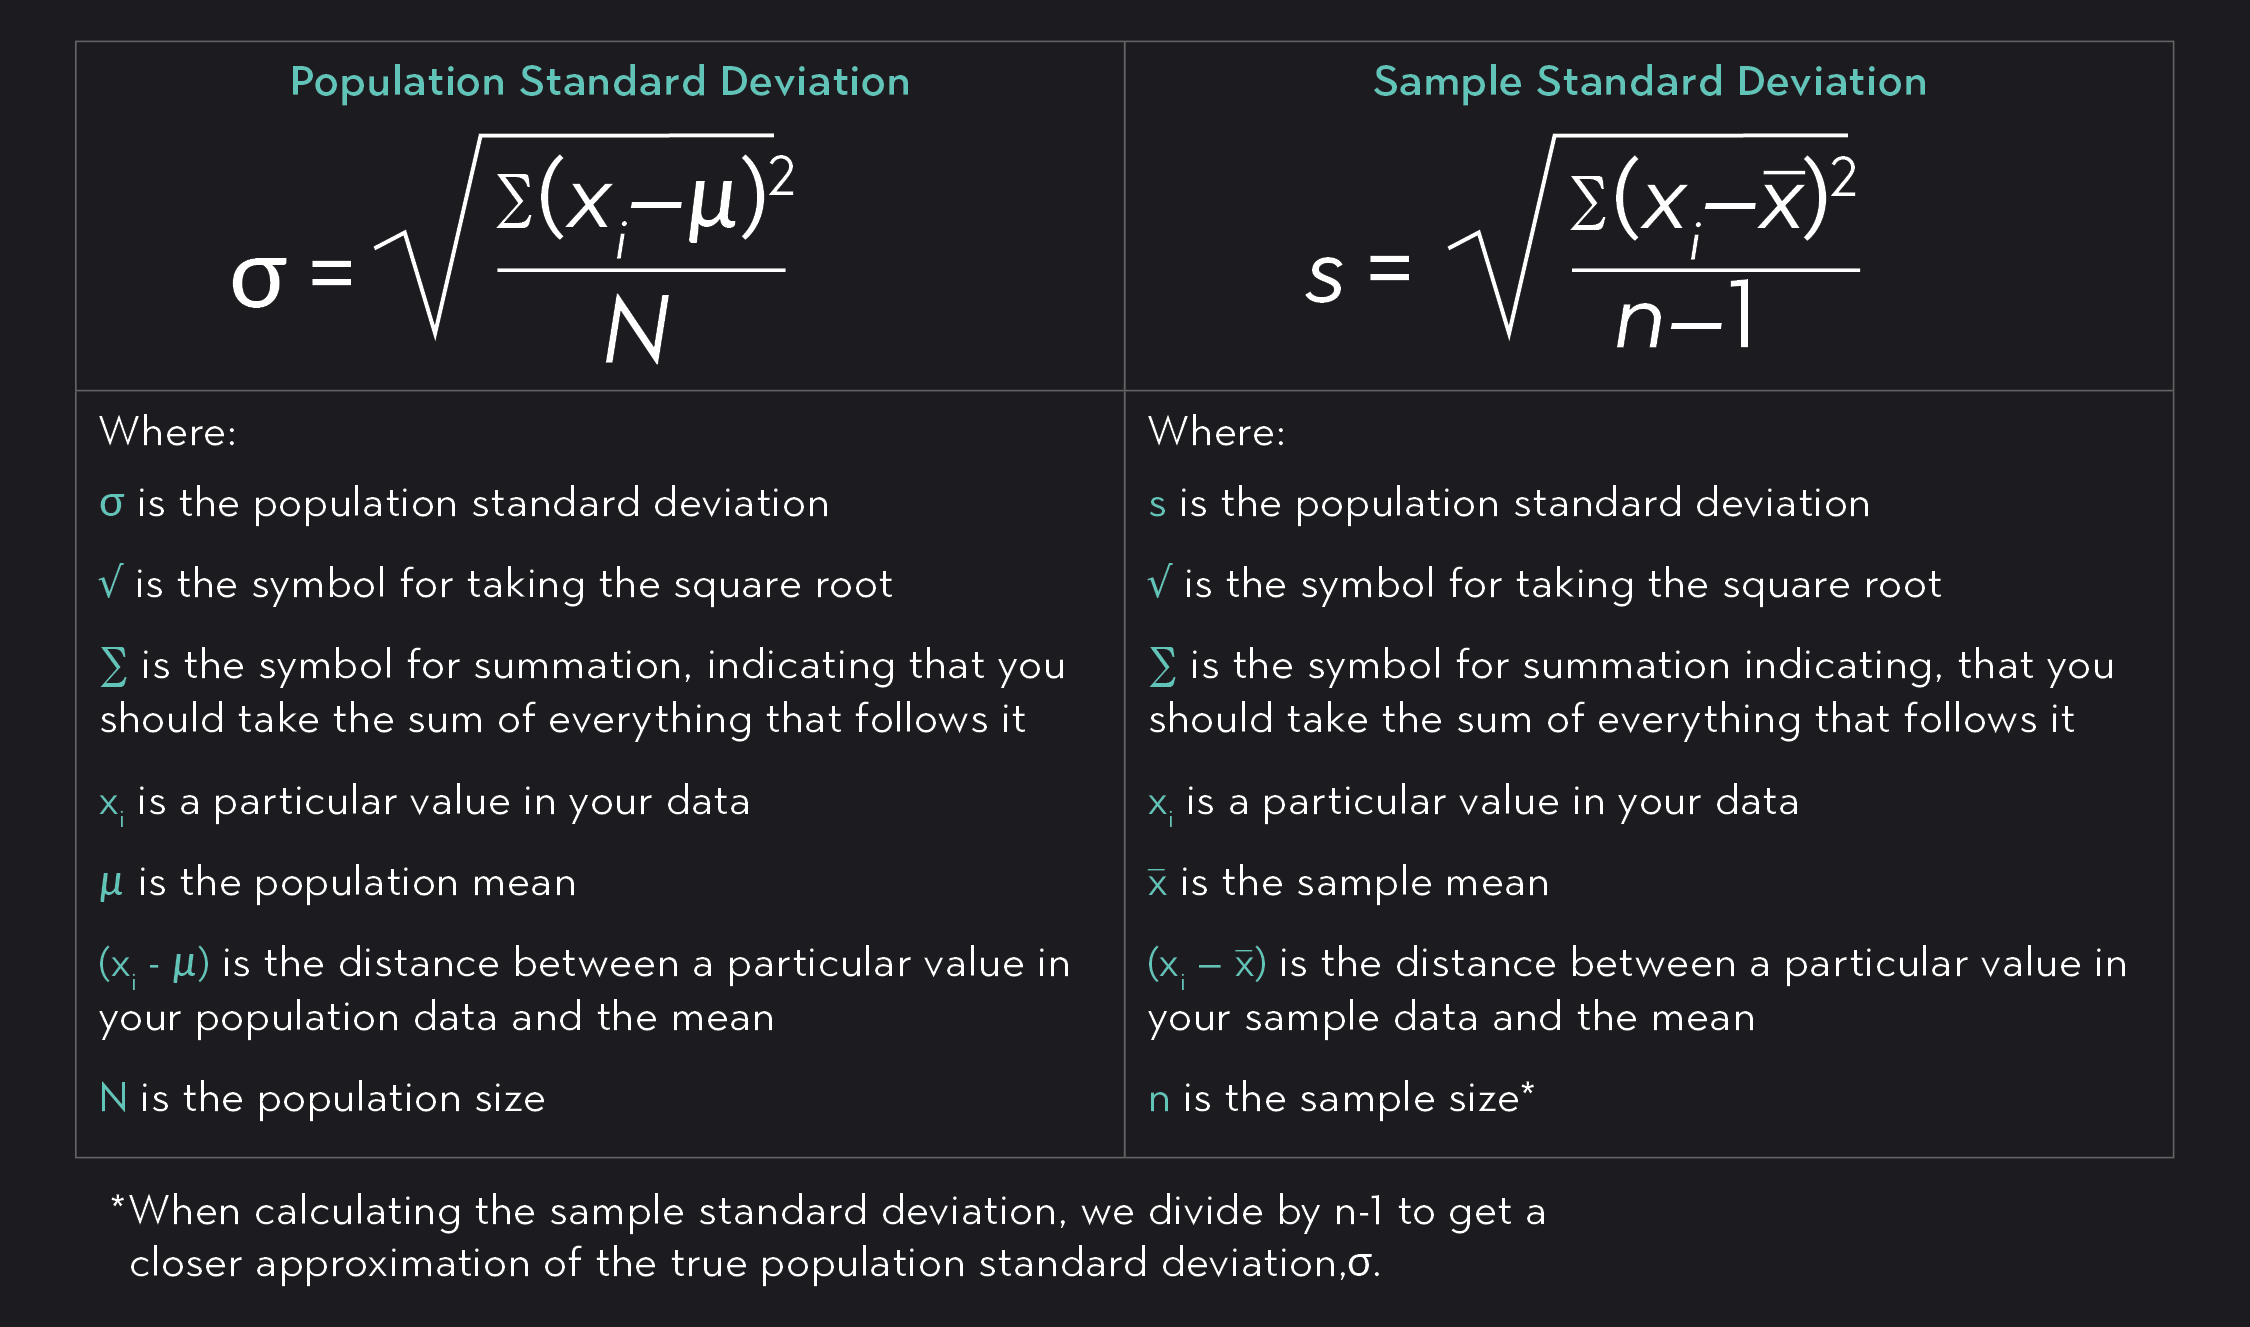
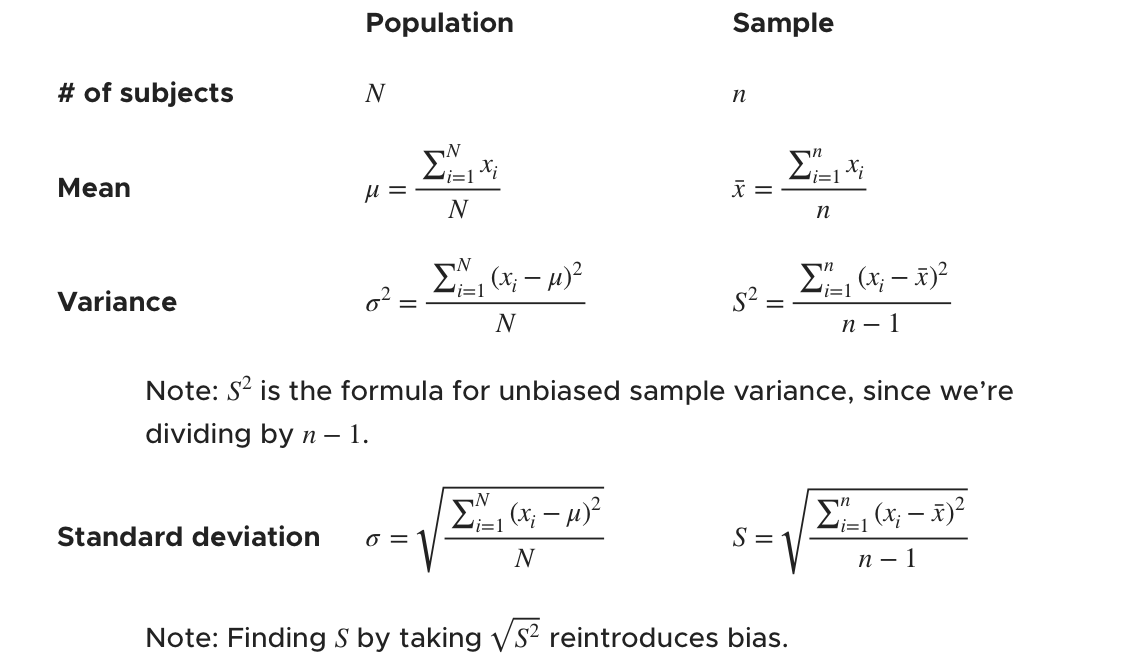
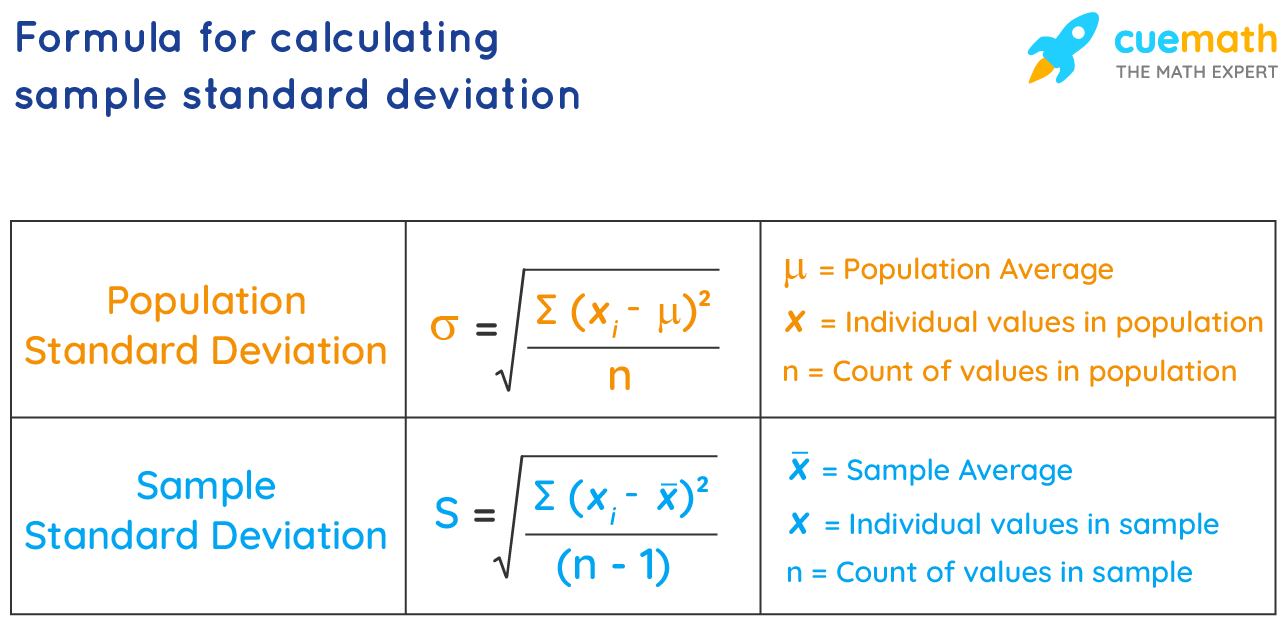
I used to get tripped up on sample standard deviation in the field because I would calculate it the same way I would for a population dataset, and that cost me time and accuracy on projects with small sample sizes. The difference is the divisor. Population standard deviation divides by N, while sample standard deviation divides by N minus one. That single adjustment is called Bessel's correction and it compensates for the fact that a sample tends to underestimate the true spread of the larger population. The sample mean is just the sum of all observations divided by the number of observations. It is straightforward, but people rush through it and make arithmetic mistakes when the dataset is long. I keep a running tally in a spreadsheet with a simple SUM formula and divide by COUNT. No complex macros needed. The sample standard deviation measures dispersion around that mean. You subtract the mean from each data point, square the result, sum those squared deviations, divide by N minus one, and take the square root. That gives you a value in the same units as your original data, which makes it easier to interpret than variance.
Here is a practical example from a quality control report I worked on last year. We had a batch of 12 resistance measurements from a production line, and the values ranged from 4.82 ohms to 5.17 ohms. The sample mean came out to 4.99 ohms, and the sample standard deviation was approximately 0.118 ohms. If I had used the population formula by mistake, the standard deviation would have been about 0.113 ohms. The difference looked small until we were setting tolerance bands and trying to meet Six Sigma thresholds, where that 0.005 gap mattered for our process capability index.
How To Calculate It Step By Step
Start by writing down every data point in a single column. Keep raw data separate from calculated results so you can always go back and verify. Then compute the mean by adding all values and dividing by the count. Next, create a second column for the deviations. Each entry is the original value minus the sample mean. These deviations should sum to approximately zero, and if they do not, you have a rounding issue or a calculation error somewhere. Square each deviation and put those results in a third column. Sum them. This is your sum of squares, sometimes written as SS. Divide SS by N minus one to get the sample variance. Take the square root of the variance and you have your sample standard deviation.
Get the Full Details

In Excel, the formula =STDEV.S(range) does all of this in one step. In Python, use numpy.std(data, ddof=1) or pandas.Series.std(ddof=1). The ddof parameter is degrees of freedom, and setting it to 1 applies the N minus one correction. If you leave it at the default of 0, you are computing population standard deviation instead, which is a common mistake.
Edge Cases That Will Slow You Down
Working with small samples is where things get messy. With fewer than five observations, the sample standard deviation becomes extremely unstable. A single outlier can swing the result by twenty percent or more. I ran into this on a materials testing project where we only had three samples due to expensive specimen preparation. The standard deviation was wildly sensitive to which outlier was included, so I switched to using the interquartile range as a supplementary measure and reported both statistics in my notes. That gave stakeholders a clearer picture without pretending the data supported more precision than it actually did. Another issue comes up with grouped or rounded data. When values are rounded to one decimal place, the standard deviation will be slightly underestimated because the rounding compresses the apparent spread. In most cases the bias is minor, but if your rounding interval is large relative to the true variability, the distortion becomes noticeable. Duplicates also deserve attention. If your dataset contains many repeated values, the standard deviation will be low, and that is correct. But sometimes people assume a low standard deviation means the measurement tool is imprecise, when in fact the phenomenon itself might genuinely have very little variation. Context matters more than the number.
Common Pitfalls
The most frequent error I see is confusing sample and population formulas. Software defaults vary by tool. Excel's STDEV.P uses the population formula, while STDEV.S uses the sample formula. SPSS defaults to sample standard deviation for most procedures. R's sd() function uses the sample formula by default. Always check what your tool is actually doing before trusting the output. A second pitfall is applying these calculations to data that is not approximately symmetric or normally distributed. The mean and standard deviation are most informative for bell-shaped distributions. For heavily skewed data, the median and interquartile range are more reliable summaries. I learned this the hard way when analyzing income data for a community survey. The mean was pulled far above the median by a handful of high earners, and the standard deviation was huge and nearly meaningless for describing the typical respondent. People also forget to check for missing values. If your dataset has gaps and your software does not handle them explicitly, you might end up with an incorrect count and a biased mean. Set your tool to skip NA values rather than returning an error, but verify the effective sample size afterward.

When These Metrics Fail Completely
Sample mean and sample standard deviation break down with categorical data. They are meaningless for nominal variables like brand names or color categories. Do not try to compute them for text data. They also perform poorly with ordinal scales that have very few distinct levels, such as a five-point Likert scale with most responses clustered at two values. In those cases, frequency tables and mode are more appropriate. Bimodal or multimodal distributions are another problem. A single mean and standard deviation will obscure the fact that your data comes from two or more distinct groups. I encountered this in a manufacturing dataset where parts came from two different machines with different calibration settings. The combined mean and standard deviation suggested acceptable variation, but each machine individually was well within tolerance. Splitting the data by source revealed the issue immediately.
Practical Workflow I Recommend
Import your data into a clean spreadsheet or script. Remove any entries that are clearly errors, like negative weights or impossible temperatures, but document every deletion with a reason. Compute the sample mean and sample standard deviation together with the median and quartiles so you can compare them side by side. Plot a histogram or box plot. If the distribution looks roughly symmetric and unimodal, the mean and standard deviation are reasonable summaries. If it looks skewed or multimodal, rely more on the median and interquartile range and note the asymmetry in your report. For small samples under ten observations, consider reporting the range alongside the standard deviation. The range gives a quick sense of spread that does not depend heavily on distributional assumptions, and it is easier for non-technical readers to grasp than a variance-based metric. These statistics are workhorse tools, not magic solutions. They give you a quick snapshot of central tendency and spread, but they do not replace checking your data visually and understanding what generated it. Do the math, check the shape, and report what the numbers actually support.