Why Everyone Messes Up the Sample Standard Deviation Symbol
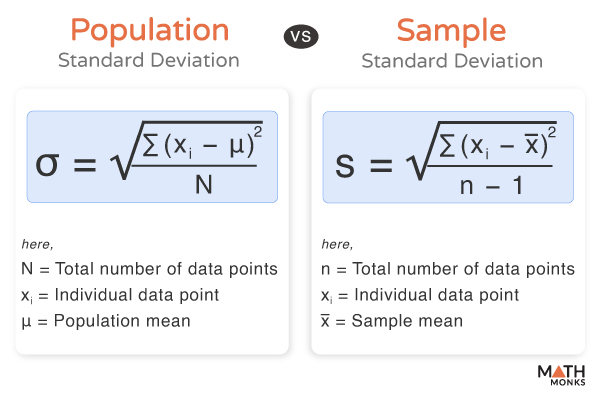
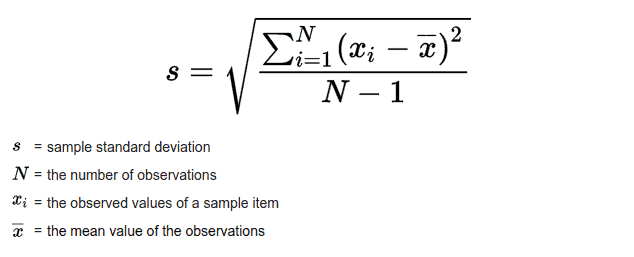
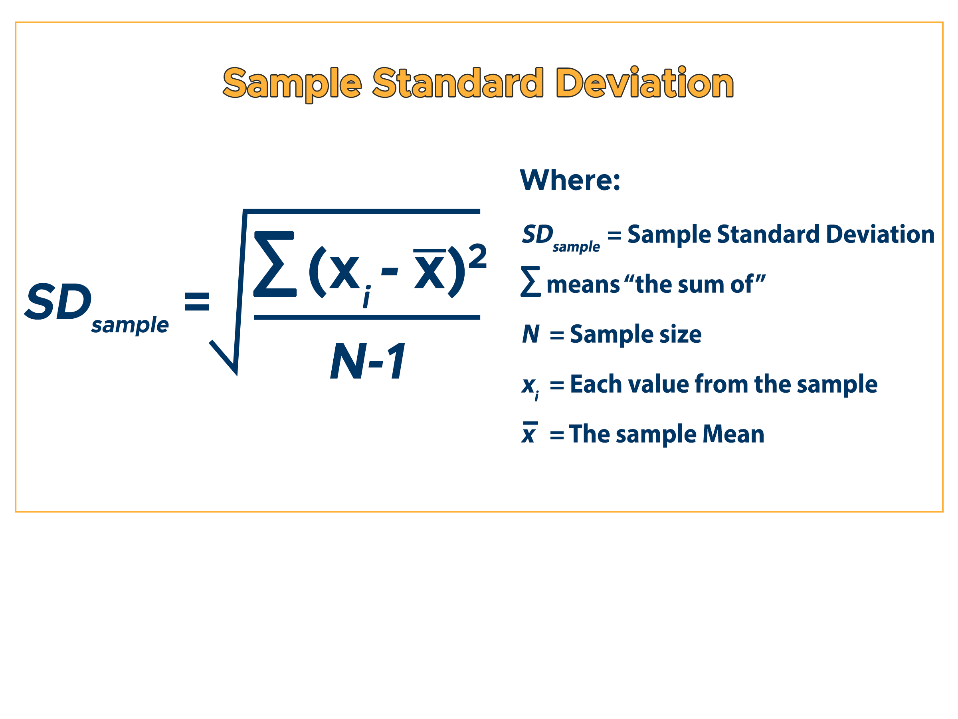
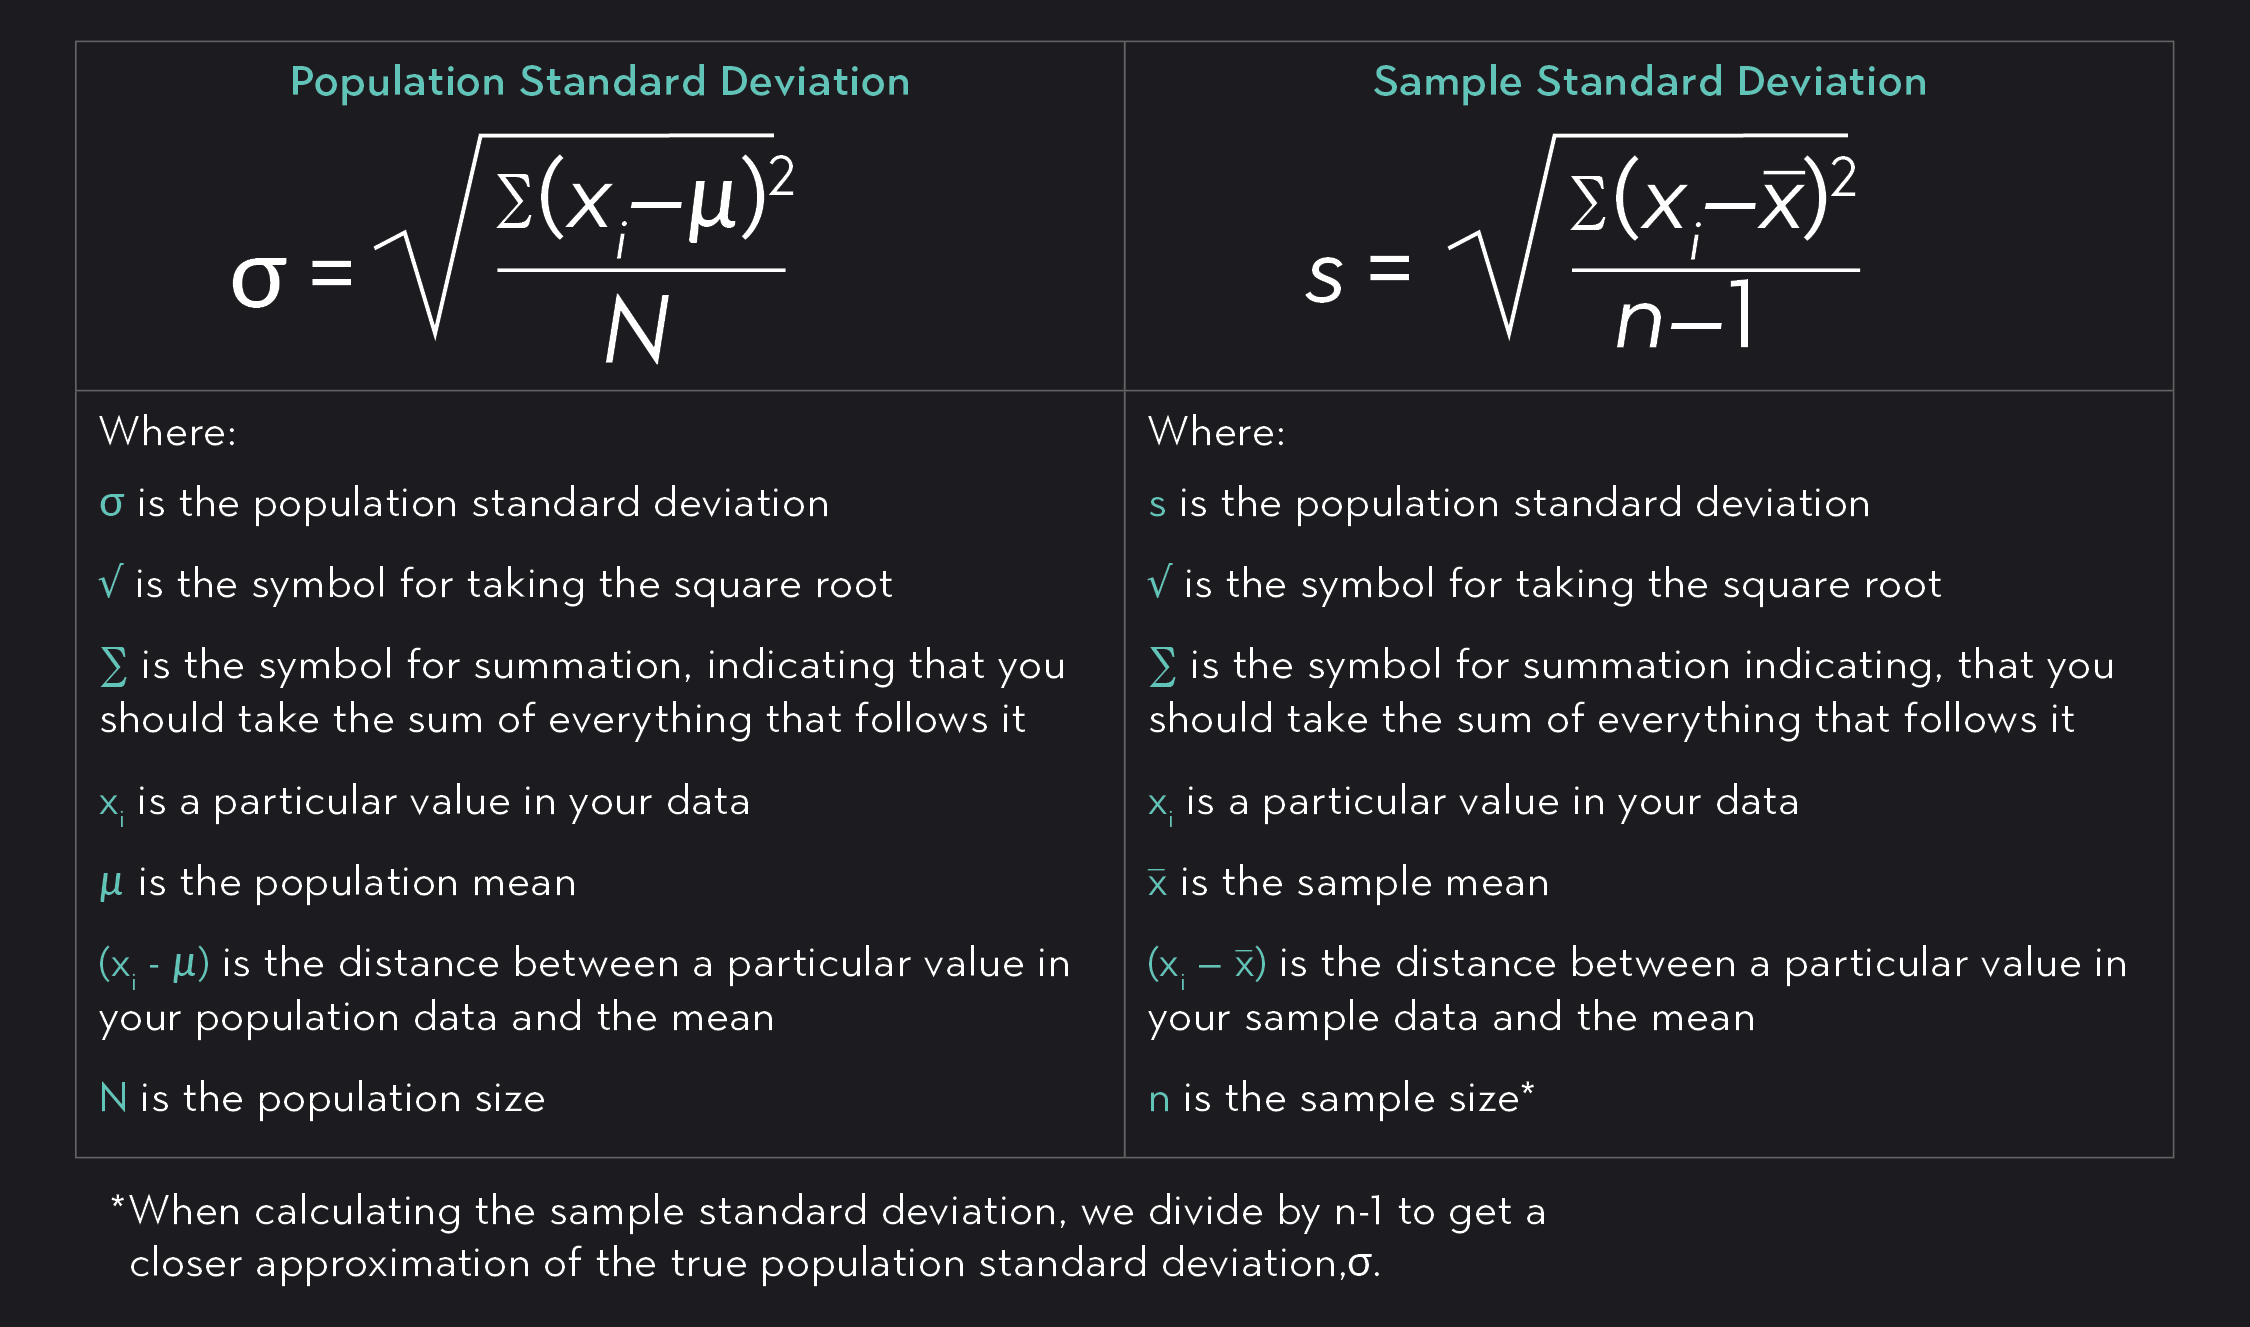
The symbol you need for sample standard deviation is s. Not . That's the population standard deviation symbol, and it doesn't apply when you're working with a subset of data. I see this mistake constantly in student labs and in workplace spreadsheets where someone copies the population formula without adjusting the denominator. The full expression looks like this:
Sample Standard Deviation Symbol Formula
s = [(x - x)² / (n - 1)] The x is the sample mean, means sum, and that n minus 1 in the denominator is what separates it from the population version. People forget why it's there. It's called Bessel's correction. Without it, your estimate systematically underestimates the true population standard deviation when you're working with a sample rather than the entire population. Using n instead of n-1 is one of the most common errors I've had to fix in other people's work. Here's where it gets messy in practice. I was analyzing sensor readouts from a batch of thermal imaging cameras last year, and the dataset had only twelve readings per unit. When I ran the calculation with n instead of n-1, the standard deviation came out roughly eight percent too low. That difference mattered because our tolerance threshold was tight. The corrected value pushed some units just barely over spec that would have looked fine otherwise. It's the kind of thing that doesn't show up on a quiz but costs you a rework cycle in the field.
The square root sign covers the entire fraction. Sometimes people write it as s with a superscript 2 for variance first, then take the square root. Both approaches give the same result, but keeping everything under one radical reduces transcription errors when you're doing this by hand or writing out a proof.
Get the Full Details
When the Symbol Doesn't Behave the Way You Expect
If your sample size is below five, the s statistic becomes extremely unstable. Small samples with Bessel's correction produce wildly varying results from one sampling event to the next. I learned this the hard way when we were trying to establish baseline readings for a new manufacturing process with only four test pieces. The standard deviation estimates varied by nearly three hundred percent across replicate measurements. At that scale, the symbol s is basically telling you nothing reliable about the population. We switched to bootstrapping confidence intervals instead, which gave us something actually usable rather than pretending the point estimate meant much. Another edge case involves datasets with zero variance. If every single observation is identical, s equals zero and the formula works fine. But if your software or calculator returns an error or NaN when computing it, check whether you accidentally have missing values getting filtered out before the denominator calculation runs. Some statistical packages drop incomplete cases silently, which changes n mid-calculation and breaks the whole thing. I spent two hours chasing a bug in a Python pipeline once only to discover that one column had hidden nulls that were reducing my sample size without me noticing. When reporting the symbol in academic or technical writing, always define it on first use. Just writing s means nothing to someone who hasn't seen your methodology section. State clearly that s represents the sample standard deviation calculated with n-1 degrees of freedom. Don't assume readers know which version you're using because plenty of introductory textbooks and online resources use n in the denominator without warning.
Practical Calculation Notes
Most people never touch the raw formula anymore. Excel uses STDEV.S, R uses sd(), and Python's numpy has np.std() with the ddof parameter set to 1 for sample standard deviation. Each of these tools defaults differently, which is another trap. Excel's older STDEV function is the sample version while STDEVP is population. R and Python default to population standard deviation unless you specify otherwise. If you're comparing results across platforms, verify which denominator each one is using. The symbol s assumes your data is approximately normally distributed for confidence interval work downstream. With heavily skewed distributions or outliers, the sample standard deviation still computes correctly, but any inference you build on top of it may be misleading. I've seen this cause problems in quality control environments where operators trust the number without checking the shape of the underlying distribution first. One more thing nobody warns you about: when you combine independent samples, you can't just average their s values. The combined sample standard deviation requires pooling the sum of squares properly. Taking the mean of two standard deviations gives you something that isn't the standard deviation of the combined group. This matters whenever you're merging datasets from different sources or time periods and then need a single summary statistic.
The symbol itself is straightforward. It's the surrounding assumptions and the edge cases that cause real trouble in practice.