So You Got the FASTQ Files and Now You Need to Make Sense of Them
You downloaded the data. It's sitting on your hard drive as a bunch of .fastq files. The sequencer threw out gigabytes of noise and you're supposed to extract something meaningful from it. This guide walks you through what actually happens after the run finishes, what tools are worth your time, and where everything breaks. The gap between "I can run bwa mem" and "I can actually interpret these results without fabricating conclusions" is enormous. Most free tutorials skip the part where things go wrong. A proper Sequencing Data Analysis Course forces you to sit with failed alignments, weird coverage drops, and variant callers that disagree with each other. That's where the real learning happens. Here's what most courses don't tell you upfront. Don't touch the aligner yet. First, check your FASTQ files with FastQC. I remember running a whole RNA-seq pipeline once on a dataset that turned out to have 40% adapter contamination because the library prep tech skipped the cleanup step. Alignment rates were abysmal, and I spent six hours wondering if I had the wrong reference genome before I actually looked at the per-base sequence content plot. Trimmomatic or fastp will fix this in about three minutes. Always run the quality check first. It saves you from chasing ghosts.
Look at two things specifically: per-base quality scores across all cycles, and the adapter content summary. If cycle 1 quality drops below Q20 across the board, your sequencer had an issue. If adapter contamination is above 5%, trim before aligning. This usually cuts downstream errors by half. Skipping this step because it feels like busywork is the single most common mistake I see.
Alignment: Picking the Right Tool for the Job
For DNA sequencing, BWA-MEM is still the workhorse. It handles reads up to 2 megabases with long-read mode and takes roughly 30 minutes on a standard 30x human genome on a 16-core machine. For RNA-seq, STAR is the standard choice despite being memory-hungry. It needs about 32GB RAM just for the index, but it aligns splice junctions correctly where most other tools fail. Here's the thing nobody explains well: mapping quality matters more than you think. A read with MAPQ=0 should never be used for variant calling, regardless of how well it aligns. I worked on a project where we were studying structural variants in a non-model organism with a poorly annotated genome. The aligner was placing reads in repetitive regions and giving them high mapping qualities because the reference was incomplete. We caught it only because the coverage profile showed massive spikes in known repeat elements. The workaround was to filter out any region with coverage exceeding three standard deviations from the genome-wide median before calling variants. That removed probably 15% of false positives.
Get the Full Details

Variant Calling and Why It Is Not Straightforward
GATK's HaplotypeCaller is the default for germline variants. It does local reassembly around potential variant sites, which is computationally expensive but significantly more accurate than plain pileup methods. For somatic variants, Mutect2 is the tool. But here's what beginners consistently miss: variant quality score recalibration (VQSR) requires a large training set. If you're working with fewer than 30 samples, VQSR will give you garbage. Use hard filtering instead. The recommended filters are simpler and actually effective at small cohort sizes. A common pitfall is assuming that a Variant Quality Score Threshold of 30 is a universal rule. It isn't. For low-coverage whole exome sequencing, you might need to lower it to 20. For high-coverage whole genome, you can raise it to 50. The right threshold depends entirely on your coverage depth, the variant type, and your false positive tolerance. Run GATK's VariantEval after calling to see how your filtering choices affect sensitivity and specificity on your actual data.
Quality Control Metrics That Actually Matter
Beyond the basic FastQC output, you need to look at insertion size distributions from paired-end alignments, duplicate rates, and coverage uniformity. Mark duplicates with Picard or sambamba before variant calling. If your duplicate rate is above 25%, something went wrong during library preparation and you should flag it in your methods section. At above 40%, reconsider whether the sample is usable at all. Coverage uniformity is another silent killer. The 1000 Genomes Project paper showed that even with targeted capture, coverage can vary by a factor of ten across the target region. A gene might have an average coverage of 80x but contain exons with zero coverage. Always check your depth distribution with QualiMap or mosdepth rather than relying on a single mean value. This usually takes about two minutes to run and prevents entirely wrong biological conclusions.
RNA-Seq Specific Concerns
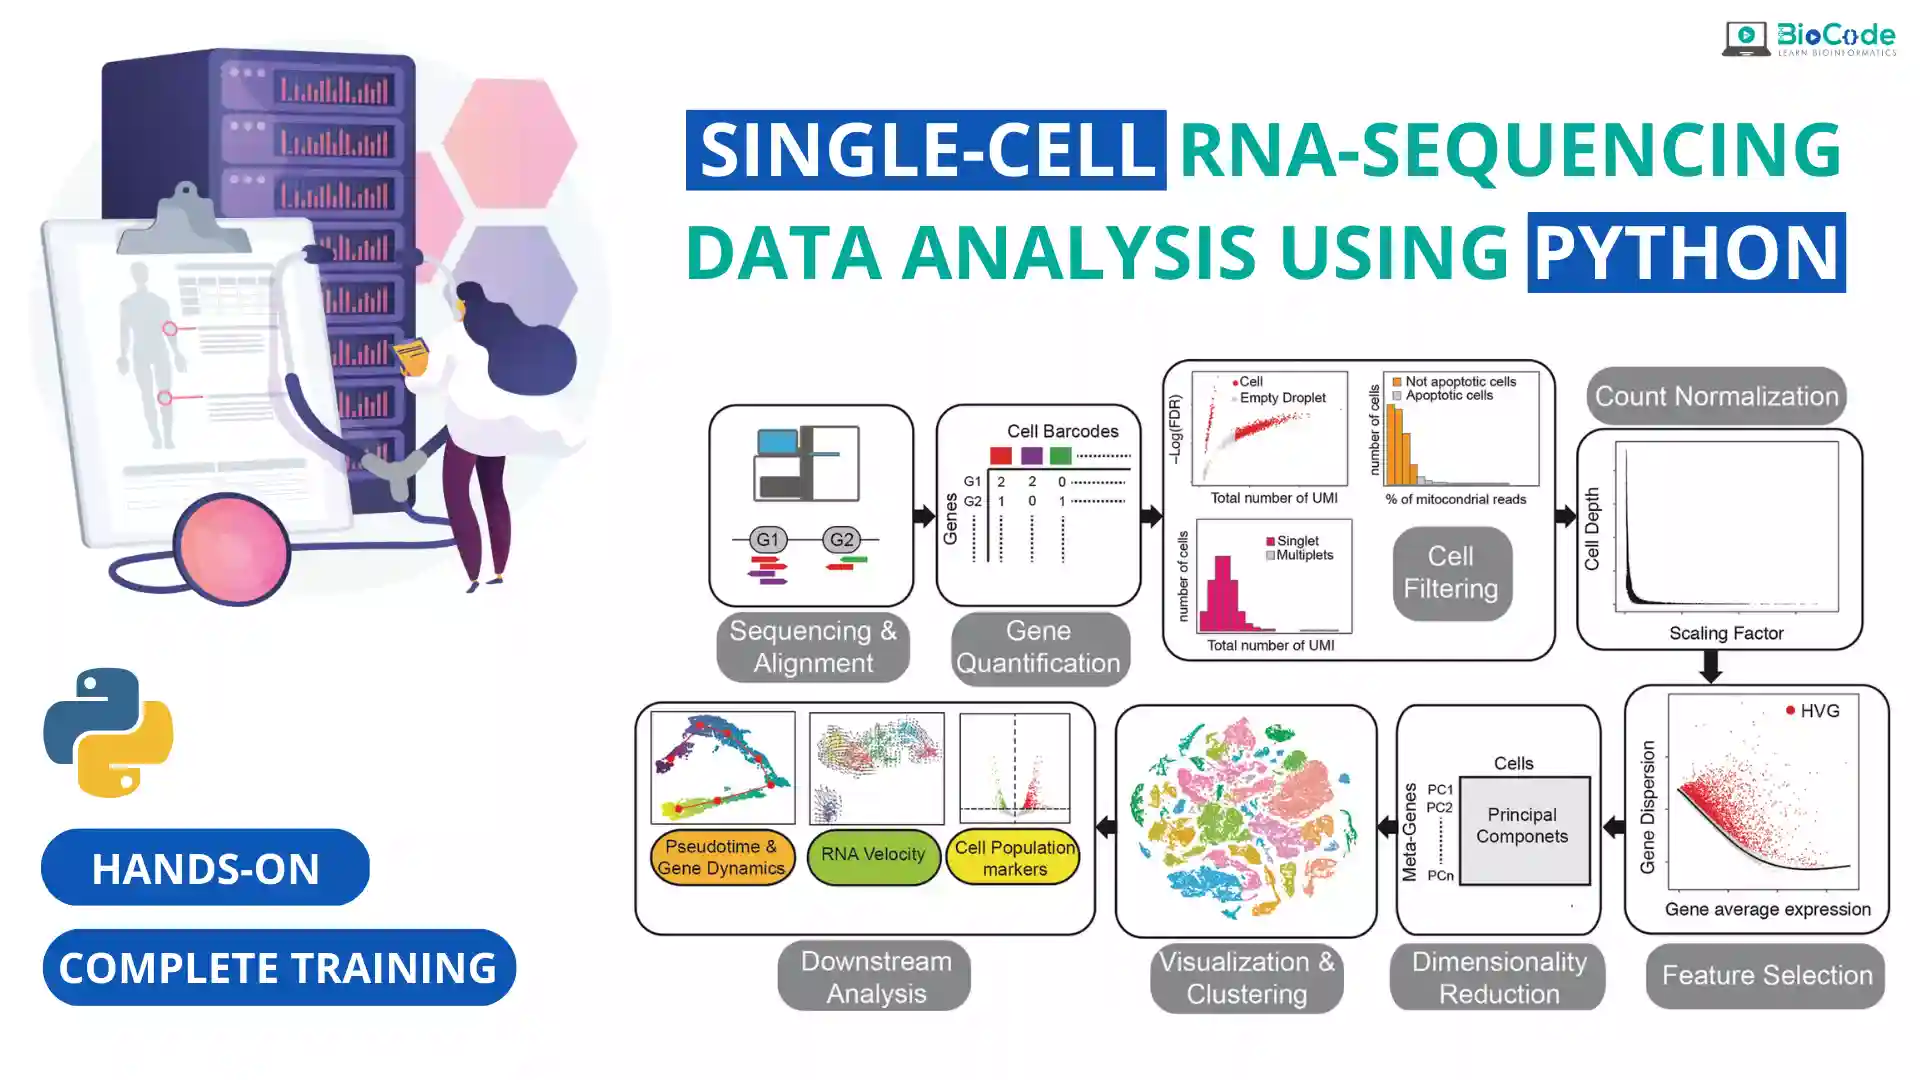
RNA-seq analysis has its own landmines. Strand specificity matters. If your library prep was stranded, you need to tell the quantification tool which strand the reads come from. Getting this wrong inflates gene counts by 30 to 50 percent for overlapping genes on opposite strands. The DESeq2 workflow assumes you've already done proper QC with tools like RSeQC, which checks read distribution across gene bodies. A 3-prime bias in your data means your RNA was degraded before sequencing, and differential expression results from that dataset are unreliable. Transcript-level quantification with Salmon or Kallisto is dramatically faster than alignment-based approaches. They're quasi-mapping based and run a full transcriptome in under 10 minutes on a laptop. The trade-off is that they depend on an accurate transcriptome annotation. If your organism's GTF file is incomplete or outdated, you'll get biased abundance estimates. Always verify your annotation against the latest Ensembl or GENCODE release.
Where Everything Falls Apart
No pipeline handles everything well. Here's what breaks in practice: metagenomic samples with unknown organisms will produce mostly unaligned reads no matter what you do. Low-input single-cell data has extreme amplification bias that no amount of bioinformatics can fully correct. Variant calling in regions with high GC content remains unreliable across all major callers. Structural variant detection is still an open research problem, not a solved workflow. If your project involves any of these scenarios, you're doing applied research, not following a tutorial. Also, reference genome choice is more consequential than most people realize. Using GRCh37 instead of GRCh38 for human data means you're missing about 200 megabases of sequence and working with outdated coordinate systems. LiftOver exists but introduces its own errors at the breakpoints. Start with the latest reference whenever possible.
Building a Reproducible Workflow
Use Snakemake or Nextflow to chain your steps together. Hardcoding individual bash commands for each sample will not scale past ten samples and will make debugging a nightmare. Containerize your tools with Singularity or Docker so that environment differences don't silently change your results between runs. Pin your software versions. A GATK update between two pipeline runs can shift your variant calls enough to change your conclusions. Document your parameters. Write them down, don't just assume you'll remember them. I once reproduced an analysis from six months prior and spent two days figuring out that I had accidentally used a different reference genome build because I hadn't written it down anywhere. Ten seconds of documentation would have saved me nearly a full day.
What a Real Course Should Cover
If you're looking into a Sequencing Data Analysis Course, make sure it covers hands-on pipeline building, not just clicking through a web interface. Galaxy and CLC Workbench are fine for quick analyses, but they hide the decisions that matter. You need to understand what happens at each step, which parameters you can safely change, and how to diagnose when results look wrong. The best courses include exercises with deliberately broken data so you learn to spot issues rather than blindly trusting output files. Practical experience with real datasets beats theoretical knowledge every time. Start with publicly available data from SRA or ENA, work through a complete pipeline from FASTQ to final results, and then apply it to your own samples. The learning curve is steep but manageable if you move step by step and keep good notes along the way.