
Working with Snowflake Stored Procedures
SQL is the only scripting language you get inside Snowflake for stored procedures. JavaScript is supported as well, but SQL stored procedures are where most of the actual work happens. They run as native database routines, execute under the same privilege model as regular SQL, and compile into the plan cache just like ad-hoc queries. I spent about three weeks debugging a procedure that would consistently fail on a specific row, returning a generic "statement has more execution stages than maximum allowed" error. The root cause was a lateral flatten inside a loop that expanded a single row into roughly 40,000 sub-rows before any aggregation. I solved it by materializing the flatted result into a temporary table first, then processing from there. The procedure went from crashing in under a minute to finishing in about eight. Just something to keep in mind when you are working with semi-structured data.
Snowflake Stored Procedure Language Sql
The CREATE PROCEDURE syntax in SQL mode follows this general shape: CREATE OR REPLACE PROCEDURE schema.procedure_name (param1 VARCHAR, param2 INTEGER) RETURNS VARIANT NOT NULL EXECUTE AS CALLER LANGUAGE SQL AS $$ SELECT ... $$; You declare parameters with their types, set the return type explicitly, and choose between EXECUTE AS OWNER and EXECUTE AS CALLER. That choice matters more than people realize. OWNER runs the procedure with the privileges of the defining role, which is typically what you want for internal procedures that touch restricted tables. CALLER runs with the caller's privileges, which can be useful but also opens up access control issues if your roles are not tightly managed. I default to OWNER on anything that touches production data.
One thing that trips people up is that SQL stored procedures do not return result sets the way you might expect from other databases. If you want to return a table, you declare the return type as TABLE and use a RETURN TABLE(...) construct. If you declare VARIANT or STRING, you can return scalar values or JSON. For most ETL-style procedures, you are writing side effects, not returning values. The procedure body executes statements sequentially, and the return type is essentially cosmetic unless you are building something that pipes directly into a query. Transaction control is another area worth paying attention to. Snowflake procedures commit automatically after each statement by default, which means you cannot rely on implicit transaction boundaries the way you can in PostgreSQL or SQL Server. If you need atomicity, you have to use BEGIN ... END blocks, but even then, rollback behavior is limited. Snowflake does support SAVEPOINT, but not all operations are savepointable. I learned this the hard way when a partial load procedure left my warehouse in a dirty state because one DML statement failed and the others had already committed. Now I check row counts and use explicit transaction wrappers wherever the operation involves multiple stages. Here is a practical example. A lot of my work involves batch processing records from a staging area and loading them into a target table. This is a representative pattern:
Get the Full Details
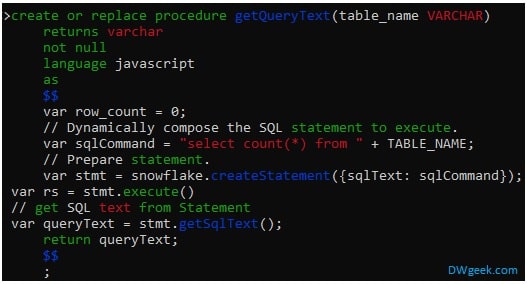
CREATE OR REPLACE PROCEDURE load_customer_batch(batch_id NUMBER) RETURNS NUMBER NOT NULL LANGUAGE SQL EXECUTE AS OWNER AS DECLARE result_rows NUMBER DEFAULT 0; BEGIN INSERT INTO target.customers SELECT * FROM staging.customers WHERE batch_id = :batch_id AND processed_flag = FALSE; result_rows := ROW_COUNT(); UPDATE staging.customers SET processed_flag = TRUE WHERE batch_id = :batch_id; RETURN result_rows; END; $$; This looks straightforward, but there are a couple of things worth noting. The ROW_COUNT() function returns the number of rows affected by the immediately preceding statement, not the total for the procedure. That means if you have multiple inserts, you need to capture the count after each one. Also, the UPDATE that sets the processed flag will fail silently if there are no matching rows, and ROW_COUNT() will return zero. You should add a guard clause or a check on TARGET_LINES if you want to raise an error on unexpected input. Performance characteristics differ significantly between SQL and JavaScript procedures. SQL procedures compile to native execution plans and benefit from the same optimization pipeline as regular queries. JavaScript procedures run in a different interpreter layer, which introduces overhead and limits your access to Snowflake's query optimizer. If a procedure can be written in pure SQL, write it in pure SQL. The only reason to reach for JavaScript is when you need complex string manipulation, dynamic SQL construction, or integration with external libraries that SQL does not support. Even then, the performance penalty is real. A procedure that processes a million rows in about 30 seconds as SQL can take three to five minutes as JavaScript, depending on the complexity.
Debugging is another practical concern. Snowflake provides the RESULT_SCAN function, which lets you query the results of the last executed statement as a table. It works inside procedures too. I use this constantly. When a procedure fails unexpectedly, I insert a logging table call before the failing statement, capture the output with RESULT_SCAN, and query the log afterward. It is not glamorous, but it saves you from spinning up a whole debugging framework. Snowflake also supports system functions like GET_DDL and INFORMATION_SCHEMA.ROUTINES for inspecting your procedures, which is useful when you are working across multiple schemas and lose track of which version is deployed where. The main limitation that bites people repeatedly is the lack of true error handling. There is no TRY/CATCH block in SQL procedures. If a statement fails, the procedure terminates and any subsequent statements are skipped. With EXECUTE AS OWNER, the failure propagates to the caller, who sees the error message. You can work around this by wrapping risky operations in conditional logic, checking return values, and logging failures explicitly. It adds boilerplate, but it is necessary if you are building production-grade procedures. Another issue is the parameter limit. Snowflake supports up to 100 parameters per procedure, which sounds generous until you are writing procedures that accept a long list of filter conditions or configuration flags. I have seen procedures hit this ceiling and then require refactoring into a JSON configuration object or a wrapper procedure that passes parameters through a temporary table. It is a structural workaround, but it works.
For deployment, I recommend using a simple migration pattern rather than ad-hoc CREATE OR REPLACE calls. Store your procedures in version-controlled SQL files, run them through a script that checks whether the procedure exists and compares hashes, and only apply changes when necessary. This avoids the churn of recompiling procedures on every deployment and gives you a clear audit trail. Snowflake's QUERY_HISTORY and EVENT_HISTORY tables can help you track when procedures were last executed and whether they are being used at all, which is useful for cleanup. If you are starting fresh and need a reference implementation, the official Snowflake documentation covers the full syntax and gives working examples for both SQL and JavaScript procedures. The documentation is updated regularly, so it is worth checking for any changes to the transaction or error handling model since the platform has evolved. There is no separate download or installer for stored procedure support. It ships with the Snowflake service, and you just need a role with CREATE PROCEDURE privilege on the relevant schema. Most organizations grant this to a dedicated DBA or platform role rather than individual developers. The bottom line is that SQL stored procedures in Snowflake are functional but constrained compared to what you get in traditional RDBMS platforms. They excel at pipeline-style batch processing and encapsulating repeated logic, but they lack advanced procedural features like exception handling, cursor support, and fine-grained transaction control. If your workload requires complex branching, conditional logic across many stages, or deep error recovery, you might be better off moving that logic to an external orchestrator and keeping the procedure thin. Use it for what it is good at: executing a sequence of SQL statements with clear inputs and outputs, under controlled privileges, at scale.


