Software Composition Analysis isn't a magic bullet, but it will save you from shipping something that turns into a headline.
I'm not going to pretend this is a new problem. We've been dealing with open source dependency risk for well over a decade now. What changed is the tooling finally caught up to the scale of the problem, and the bar for doing this right is much higher than just running a single command and hoping for the best. Most teams get SCA wrong in the first three months because they skip the boring parts—the inventory, the normalization, the continuous scanning—and then wonder why their security team isn't happy with the results. Here's how the process actually works, from start to finish, without the marketing gloss.
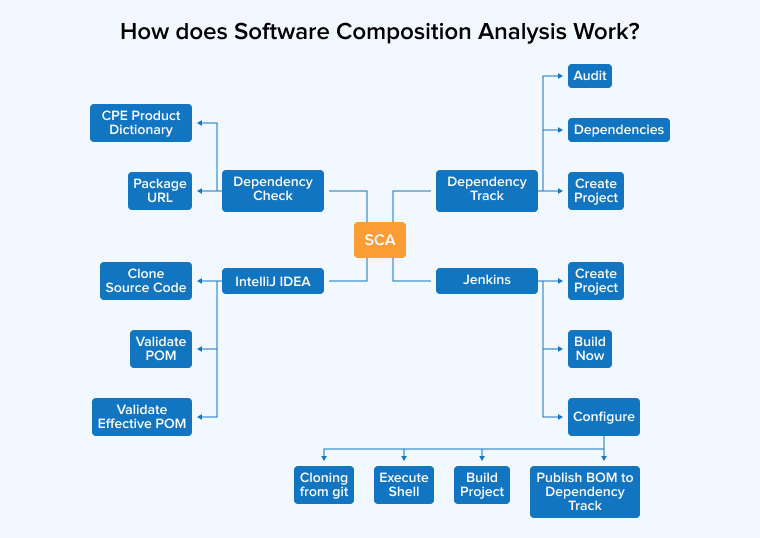
How Software Composition Analysis actually works
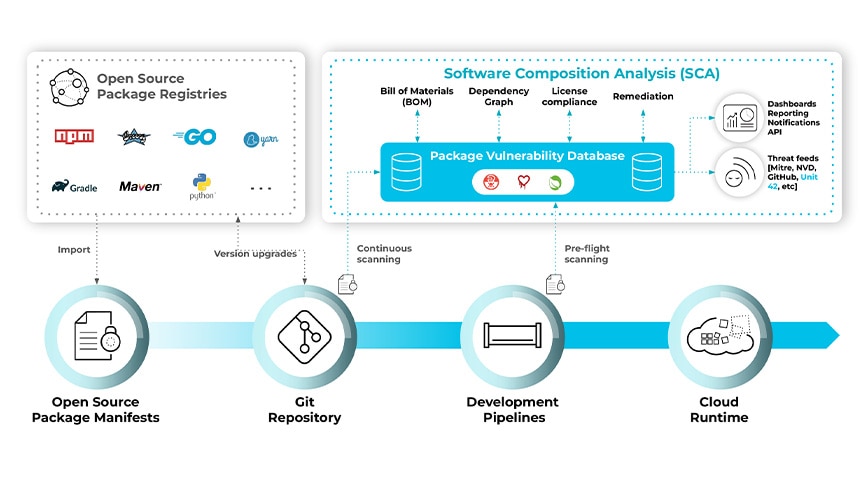
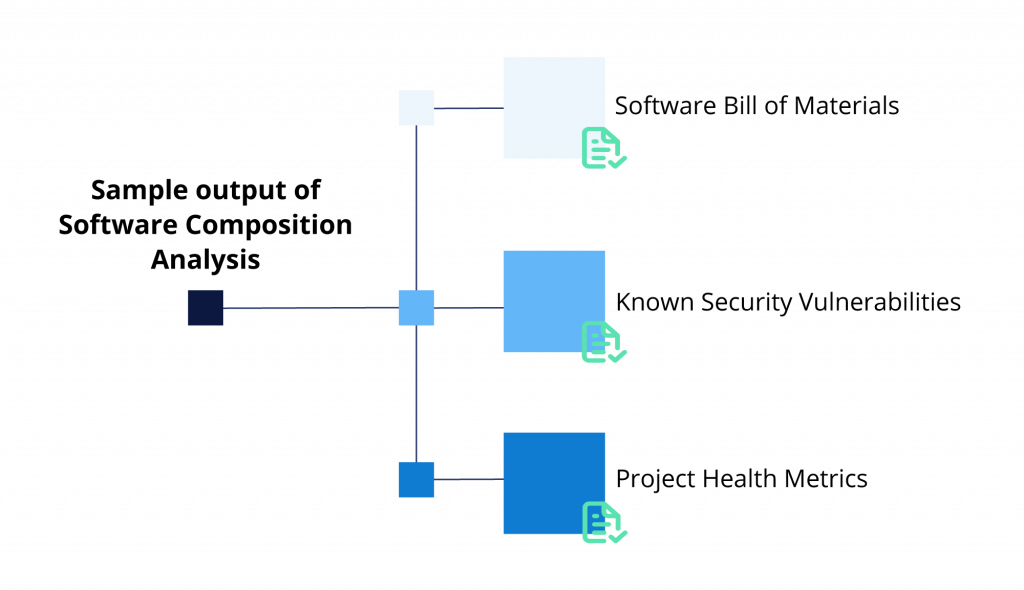
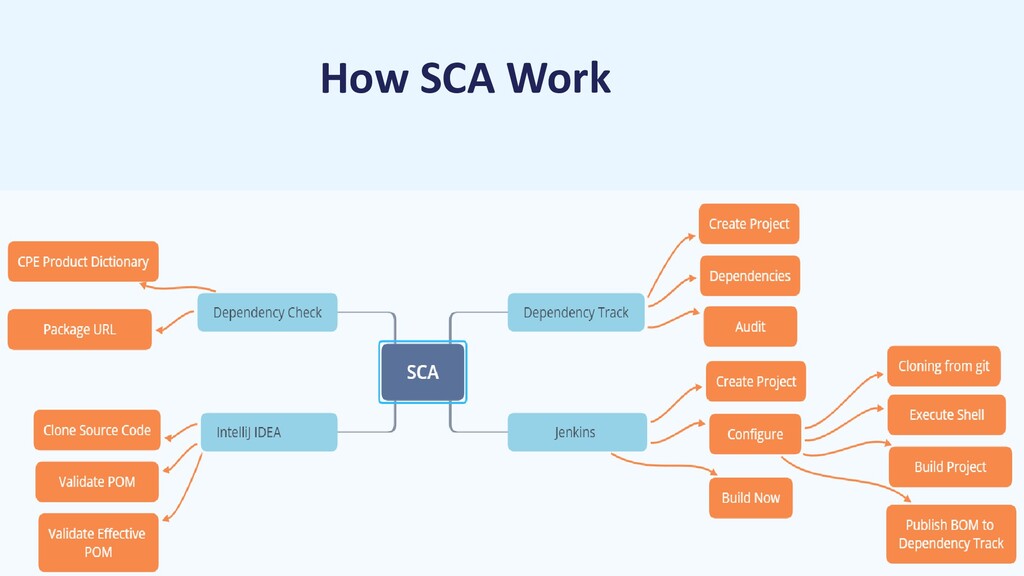
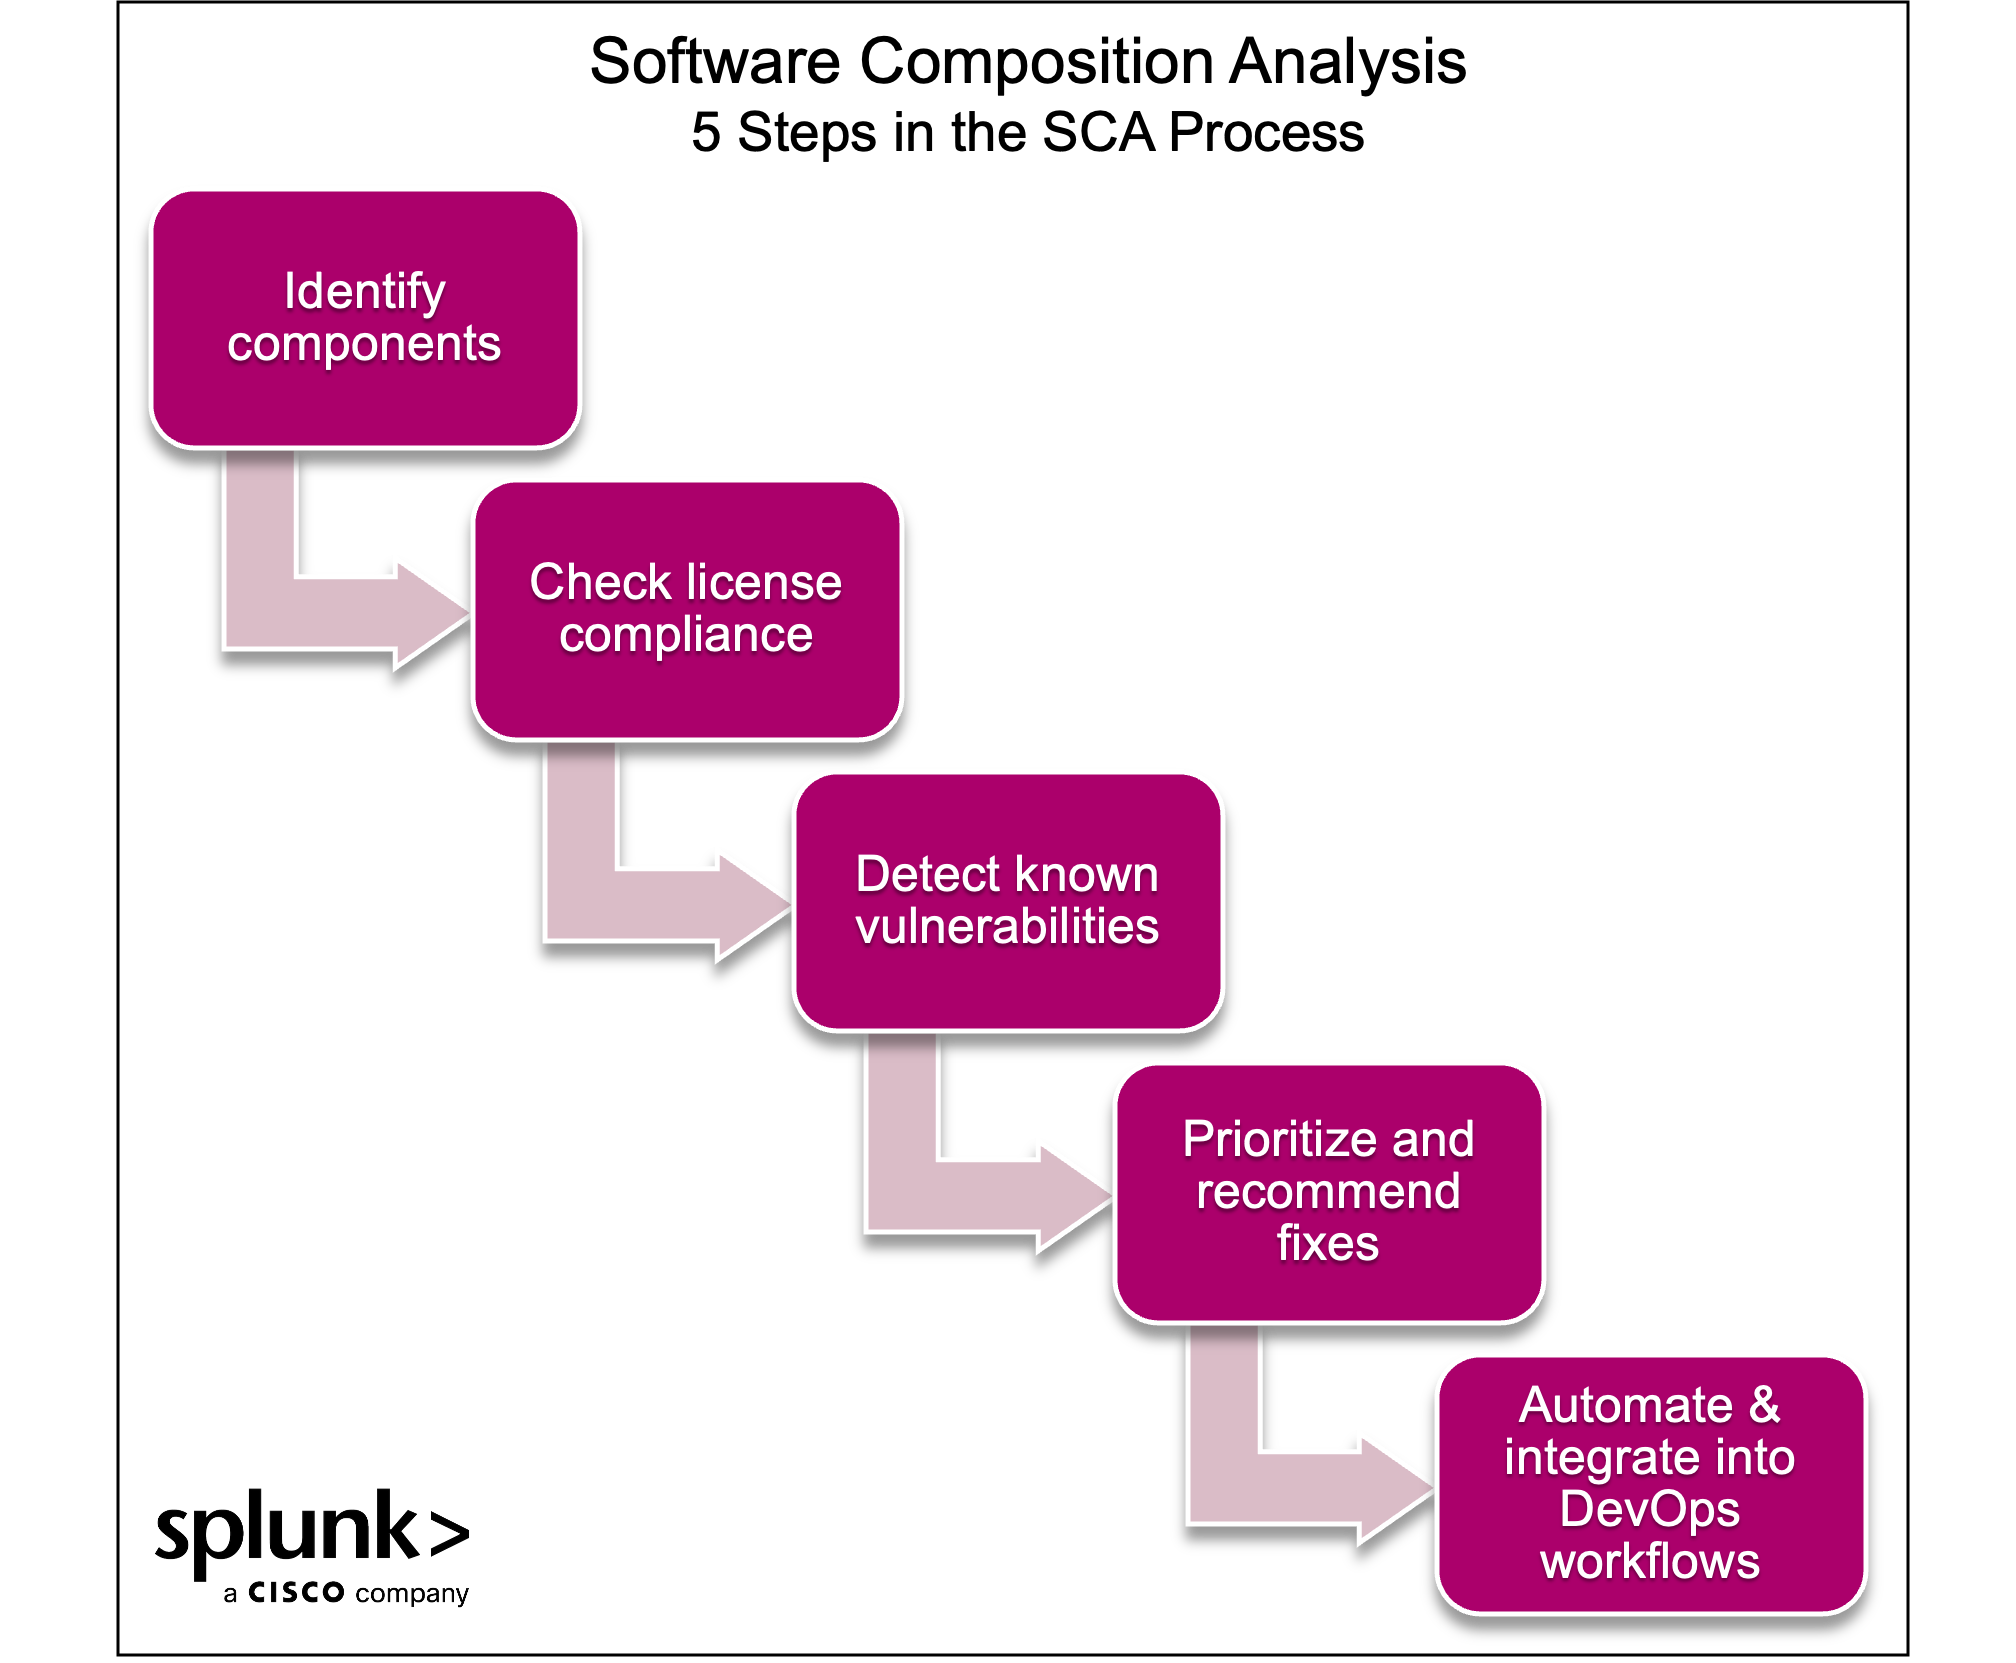
The basic flow is straightforward, even if the execution is messy. You take your codebase and all its dependencies, generate a Software Composition Analysis inventory of everything in it, cross-reference that inventory against vulnerability databases, and then triage the findings based on your actual deployment context. The inventory part is where most people trip up because they think "inventory" means "look at the package.json file." That's only the surface layer. A proper SCA scan looks at lock files, transitive dependencies, container images, runtime processes, and sometimes even the compiled binaries themselves. It extracts package names, version strings, hashes, licenses, and any other metadata it can find. This output is usually called a Software Bill of Materials or SBOM. You can export it in SPDX or CycloneDX format. These are structured data formats that downstream tools consume, and they're essential if you want to integrate SCA into a CI/CD pipeline instead of running manual checks. The vulnerability matching is where the actual work happens. The tool takes each component from your SBOM and queries vulnerability databases like the National Vulnerability Database, GitHub Advisory Database, OSV, and various vendor-specific advisories. It matches on component name and version range. If your project depends on log4j 2.14.1 and there's a CVE for log4j versions below 2.15.0, you get a hit. Simple in theory. Not simple in practice, as you'll see in a moment.
After matching, the tool assigns a severity score, typically using CVSS or a similar scoring system. Then it produces a report with actionable findings. Some tools also provide fix recommendations—upgrade this package, apply this patch, switch to an alternative library. That last part is important because raw vulnerability counts without remediation guidance are just noise.
Get the Full Details
Running a Software Composition Analysis scan from scratch
I'll walk you through setting this up using open source tooling. You can absolutely pay for commercial platforms like Snyk or Black Duck if that's your budget, but the underlying mechanics are the same. I prefer starting with open source tooling because it forces you to understand what's happening instead of treating the tool as a black box. First, install Syft and Grype. Syft generates the SBOM. Grype scans it for vulnerabilities. Both are from Anchore and they work well together. On macOS you'd run something like brew install syft grype. On Linux, grab the binaries from their GitHub releases page. Generate your SBOM:
syft . --output spdx-json > sbom.json This scans your current directory, including all declared and transitive dependencies, and outputs a full SBOM. If you're scanning a Docker image instead, use syft docker:myimage:latest. If you're scanning a running container, use the filesystem walker with syft dir:/path/to/filesystem. Then scan the SBOM:
grype sbom:sbom.json --output json > results.json The results file will contain every vulnerability match, severity, package details, and any available fix information. You can pipe this to jq or another tool to filter by severity, package name, or exploit availability. The key is not to look at the raw JSON directly—you need to build a filtering layer around it because the default output is enormous and mostly useless without context. For a CI/CD integration, I typically extract the high and critical findings, cross-reference them against our allowlist, and fail the pipeline only if there are unapproved findings in the high/critical range. Everything else goes into a tracking dashboard. That's the approach that scales. Failing every pipeline run on a medium-severity finding for a library you never import is a fast track to losing engineering credibility for the security team.
What nobody tells you about SCA that becomes obvious after six months of this
The first counter-intuitive thing: lock files don't replace dependency scanning. A lock file tells you exactly which versions are locked, yes, but it doesn't tell you about vulnerabilities in those versions. You still need a vulnerability database lookup. Some teams confuse having a lock file with having solved the dependency problem. You haven't. The lock file is just one input into the SCA process. The second thing: the biggest vulnerability in your supply chain is often the one you didn't know you had. This isn't dramatic. It's structural. Your package.json might declare ten direct dependencies, but the resolved dependency tree contains maybe two hundred packages. Every single one of those two hundred is a potential attack surface. SCA tools that only check your top-level dependencies will miss roughly 95 percent of the actual risk. This is why transitive dependency scanning is non-negotiable. Here's a specific edge case I ran into that took me about three days to resolve properly. I was scanning a Python service that pulled in a seemingly harmless utility package called structlog. The SCA tool flagged a vulnerability in a transitive dependency of structlog—a package called python-json-logger at version 2.0.4, which had a CVE related to improper input handling. The advisory said the vulnerability was in versions below 2.0.5 and was rated high severity. Easy to fix, right? Just bump the version.
Except this service didn't actually use python-json-logger for logging. It used it as a transitive dependency for a completely different feature that happened to be disabled in our configuration. The vulnerable code path was in the JSON serialization logic, but our deployment only used the plain text logging path. The SCA tool had no way to know this because it works at the package level, not the code path level. The workaround was tedious but necessary. I wrote a small script that parsed our actual runtime configuration, mapped it to the dependency tree, and flagged any findings where the vulnerable functionality was unreachable given our configuration. I then added this as a post-processing step in our CI pipeline. It cut our false positive rate by about 60 percent. It wasn't elegant, but it was honest about what the tool can and can't do. I also learned that some SCA tools have dramatically different accuracy depending on whether you give them a container image versus a source code directory. Container images include the full filesystem, which means the scanner can detect installed system packages, runtime libraries, and bundled assets that source-only scanning misses entirely. I switched our primary scan target from source directories to container images after comparing results side by side. The image-based scan found approximately three times more vulnerabilities than the source scan, and I can confirm those were real vulnerabilities because we patched them.
Where SCA breaks down and what you should do instead
Let me be blunt about the limitations because the vendors won't be. SCA cannot detect vulnerabilities in your own custom code. It scans dependencies. If you wrote a buffer overflow in your C++ extension module, SCA will not find it. You need a static analysis tool for that, and even then, SAST tools have their own failure modes. SCA and SAST are different tools solving different problems. Don't expect one to cover the other. SCA struggles with proprietary or internal packages. If your organization maintains internal npm packages or private PyPI repositories, many open source SCA tools will either miss them entirely or fail to look up vulnerabilities because the packages don't exist in public advisory databases. You need a commercial SCA platform with private package support or you need to set up a local vulnerability mirror. This is a real gap that affects a lot of enterprise organizations.
False positives are a chronic issue. A typical scan of a medium-sized Java application might surface two to four thousand vulnerabilities. Maybe fifteen to thirty of them are relevant to your actual runtime. The rest are either in unused code paths, in test dependencies, in libraries that don't apply to your environment, or in packages with mitigating controls you've already implemented. The ratio improves if you scan container images at runtime instead of building times, because runtime scanning sees only what's actually deployed. But even runtime scanning will produce noise. License compliance is another area where SCA falls short of what teams expect. Yes, the tool will flag GPL or AGPL licensed dependencies. But license risk is not the same as a vulnerability. A GPL violation is a legal risk, not a security risk, and the mitigation strategy is completely different. Some teams conflate the two and treat a license finding with the same urgency as a critical RCE. It's important to separate these concerns in your triage workflow because they require different resolution paths and different stakeholders. One practical recommendation that hasn't failed me yet: build and maintain a vulnerability allowlist with justification fields. When you legitimately decide to accept a risk—because the vulnerable code path isn't used, because a compensating control exists, because the fix would introduce instability—document it in the allowlist with a reason and an expiration date. Review the allowlist quarterly. This turns your SCA noise into a manageable signal and gives your security team auditable evidence that findings were reviewed rather than ignored.
The tooling for Software Composition Analysis has matured significantly over the past few years. The open source options are good enough for most teams to start with. The hard part isn't running the scan. It's building the operational discipline around triage, allowlisting, continuous monitoring, and accepting that you will never eliminate all dependency risk. You manage it. That's the realistic outcome.