Understanding Statistical Reporting Output from SPSS
Writing a proper results section for a research paper after running SPSS can be frustrating if you've never done it before. The software generates a massive amount of output, but it doesn't come formatted for academic publication. You need to know how to extract the right numbers and present them correctly. Most graduate students struggle with this transition from raw output to manuscript-ready tables. I remember when I was trying to report factorial ANOVA results for my dissertation. The standard deviations came out with too many decimal places, and I couldn't figure out why the effect sizes weren't matching what I calculated by hand. It turned out I was looking at Type III sums of squares instead of Type I, which made a real difference with my unbalanced design. That took me about three hours to figure out on a Sunday evening.
Spss Report Writing Sample
Here's what a proper results paragraph should look like after running your analysis: F(2, 147) = 4.32, p = .016, ² = .055. The post hoc comparisons using Tukey's HSD test revealed that Group A (M = 23.4, SD = 4.2) scored significantly higher than Group C (M = 19.8, SD = 5.1, p = .008). There was no significant difference between Group A and Group B (p = .234). Notice a few things here. The degrees of freedom are reported first, then the F-value with two decimal places, the exact p-value to three decimals, and the effect size. Don't round p-values to .05 or .01 unless your journal specifically allows it. Always report exact values when they fall below .001, and use the non-italic F and p symbols.
Setting Up Your Output Correctly
Before you even run your analysis, you should adjust your SPSS output settings. Go to Edit > Options > Output and change the number format. Most journals want two decimal places for means and standard deviations, three for p-values and test statistics. If you leave the default settings, you'll get something like M = 23.43215678, which is useless for publication. Also check your missing values handling. The Exclude cases listwise option in your analysis dialog will drop any case with missing data on any variable in your model. This can dramatically reduce your sample size. If you have missing data patterns, consider using Exclude cases pairwise instead, though this means different analyses might use slightly different N values.
Get the Full Details
Common Table Formats You'll Need
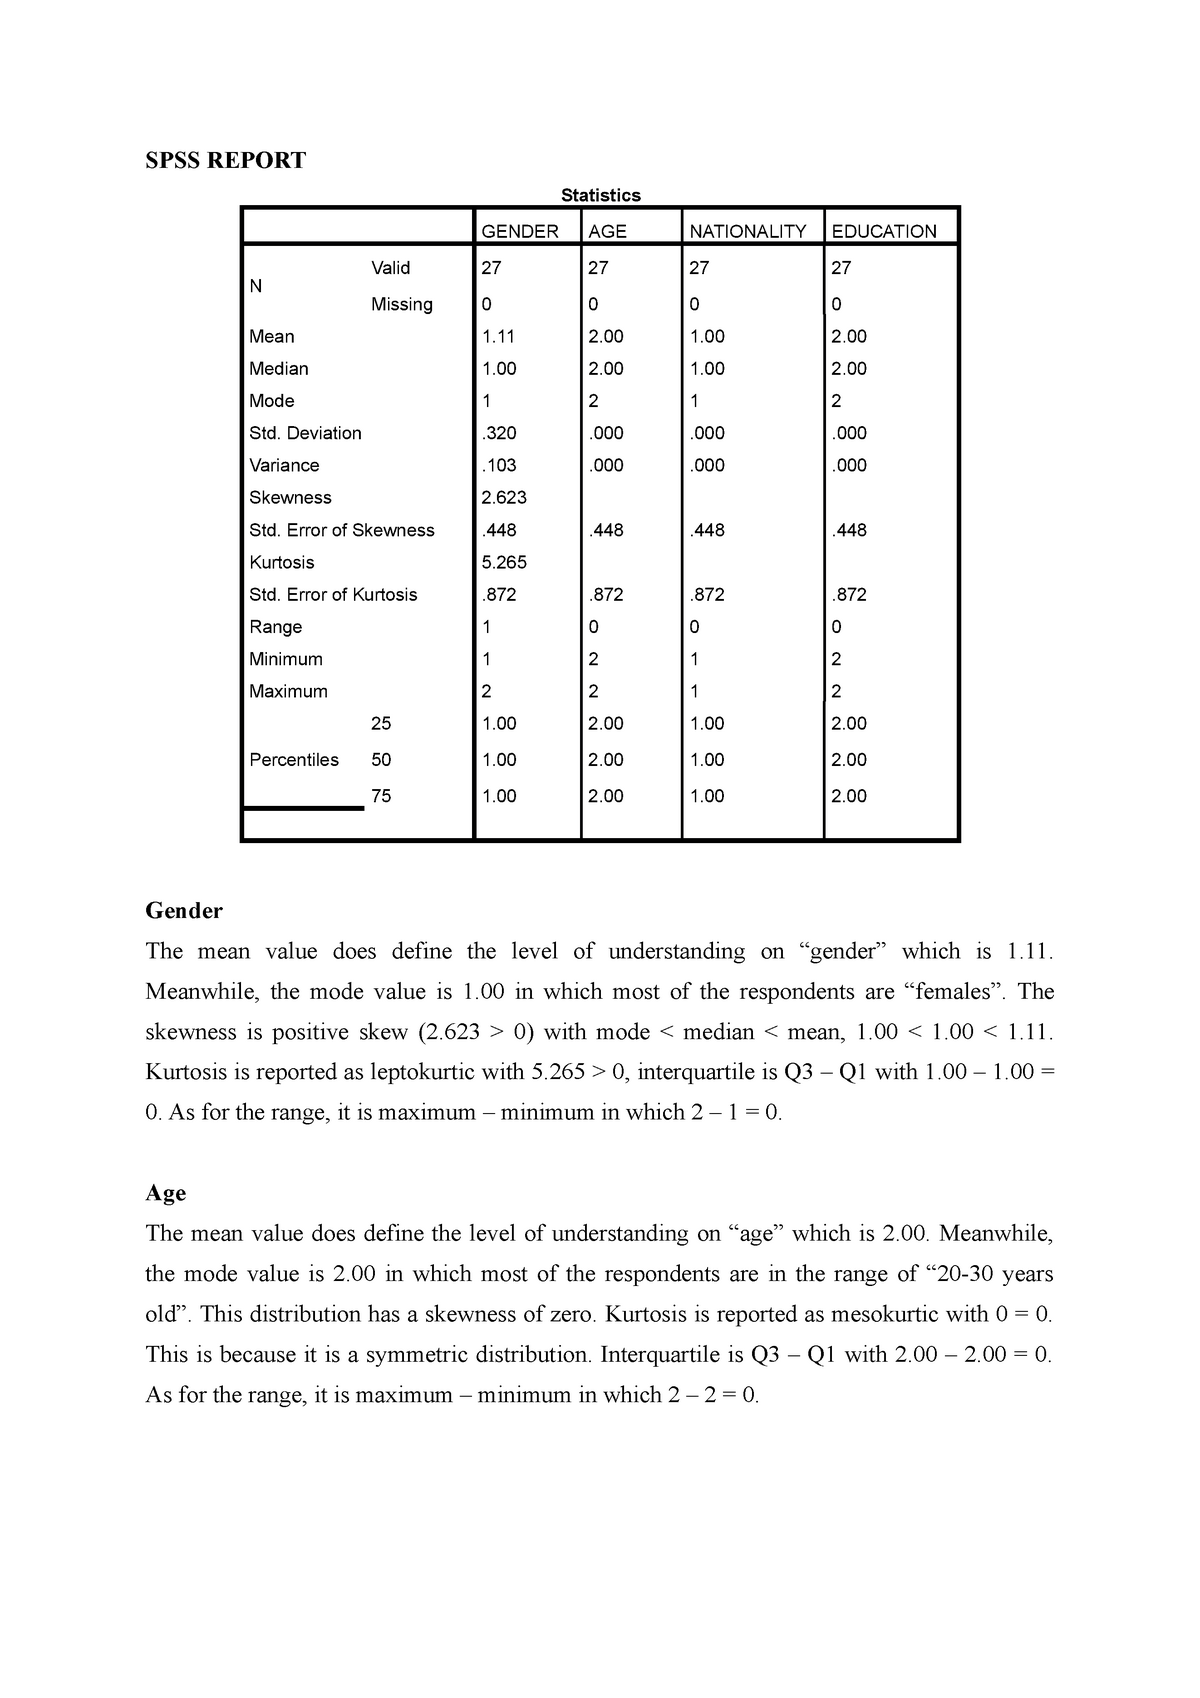
Demographic tables typically go in a separate table at the beginning of your results. Include N, mean, and standard deviation for continuous variables, and frequencies and percentages for categorical ones. Make sure your percentages sum to 100% within each category, but only report one decimal place for percentages unless your cell counts are small. For bivariate relationships, correlation matrices should use asterisks for significance levels. Report the exact coefficient to two decimals, then add one or two asterisks based on your alpha level. Most journals use * for p < .05 and for p
.01. Don't bother reporting the N for each correlation unless there are missing values, because in that case the N might vary across cells. Regression tables are trickier. Include the unstandardized coefficient B, its standard error, the standardized coefficient beta, and the t-value with its p-value. Put the confidence interval for B in the final column if your target journal accepts it. Some people also like to include the variance inflation factor in a footnote when multicollinearity is a concern, but that clutters the table.
What SPSS Gets Wrong That You Need to Fix
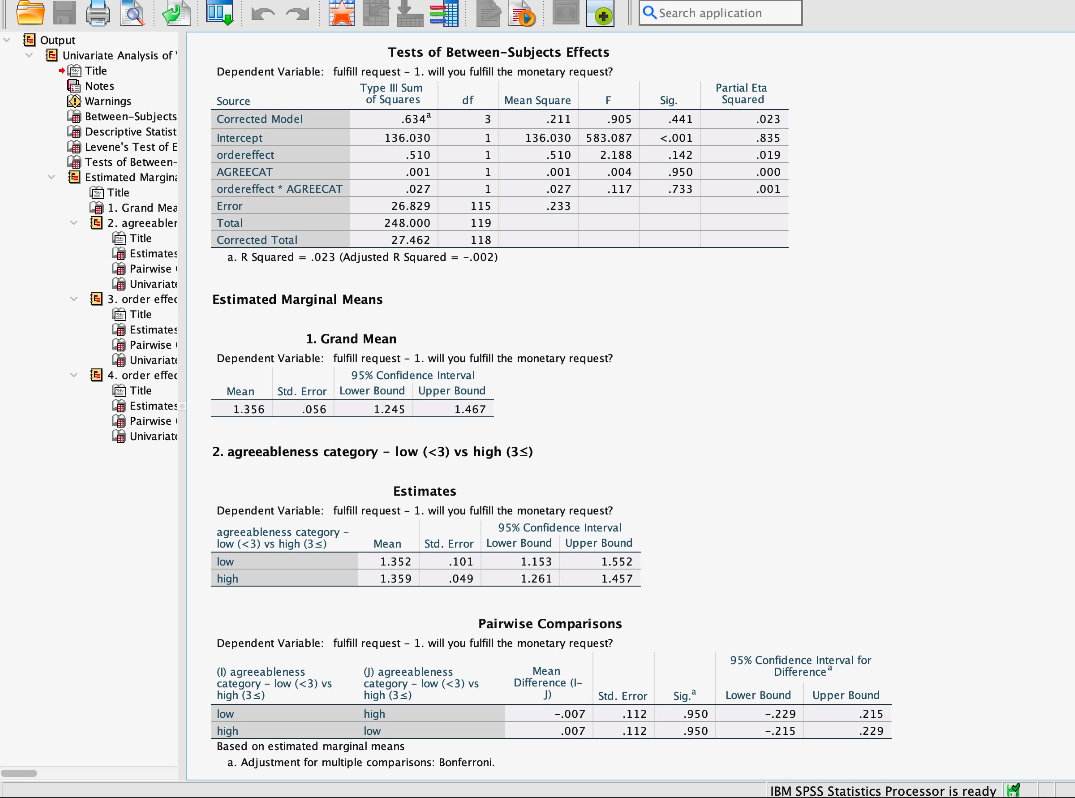
The software will sometimes give you wrong effect size estimates if you don't specify the right options. For ANOVA, SPSS gives you partial eta squared by default, but many journals prefer eta squared or omega squared. The conversion is simple: omega squared equals partial eta squared divided by 1 minus partial eta squared plus partial eta squared divided by the degrees of freedom for the effect. Another issue is how SPSS handles multiple comparisons. When you run post hoc tests, the software adjusts the p-values automatically, but it uses different methods depending on which test you select. Bonferroni is conservative and works well when you have few comparisons. Tukey's HSD controls family-wise error rate better for all pairwise comparisons. Sheffé is the most conservative option and is only really necessary for complex contrasts. I once spent two weeks trying to figure out why my logistic regression odds ratios didn't match what I calculated manually. The problem was that SPSS was using a different coding scheme for my categorical predictor than I expected. The reference category matters a lot, and if you code it wrong, every odds ratio gets flipped. Check the zero-one point of your dummy variables, and verify that the reference category matches what you expect in the output.
Writing the Results Text
Don't repeat every number from your table in the text. Pick the key findings and describe them, then refer readers to the table for the complete statistics. If a result is not significant, mention it briefly but don't dwell on it. Reviewers and readers want to see that you know how to interpret your output, not that you can transcribe numbers from one format to another. Report confidence intervals whenever possible. They tell readers more about the precision of your estimates than p-values alone. A 95% confidence interval that just barely excludes zero conveys different information than one that spans a wide range of plausible values, even if both are statistically significant. If you're reporting a significant interaction effect, describe the simple main effects rather than just stating that an interaction exists. Run post hoc tests at each level of the moderating variable, and report those results with their own statistics. This usually takes about 20 minutes of additional SPSS work but makes your paper much more interpretable.
When SPSS Isn't the Best Tool
SPSS is fine for standard analyses, but it struggles with complex multilevel models, structural equation modeling, and advanced missing data techniques. If your research design requires these methods, consider using R, Mplus, or Stata instead. SPSS has added some of these capabilities through syntax extensions, but the functionality is usually inferior to dedicated software. Also be aware that SPSS syntax can create hidden problems. If you save your syntax and reuse it later, the output file might accumulate old results that confuse you or co-authors. Always start with a fresh output window when you begin a new analysis session, and label your syntax clearly so you know exactly what each block produces. The software also generates unnecessary output by default. Turning off chart output and saving only the tables you need can reduce your output file size from several hundred megabytes to a few gigabytes, depending on how many analyses you run. Check the Display box in each analysis dialog to control what gets printed.