
Why Most People Skip Real SQL Practice
The problem isn't that there's no SQL material online. There's way too much of it. The problem is that most practice sets teach you syntax in isolation and then leave you completely stuck when you're asked to write something that actually resembles work. I've watched junior developers who could recite every JOIN type in their sleep freeze when a real query needed a window function combined with a CTE and a filter on aggregated results. I spent a couple years running interview prep sessions at a mid-size analytics team. My job was basically to take people who understood SELECT statements and get them to something closer to production-ready. I learned pretty quickly that the gap between "I know SQL" and "I can write SQL that doesn't tank the database" is enormous, and the kind of structured practice you need to bridge it is harder to find than you'd think.
Sql Practice Questions With Solutions That Actually Help
The best practice sets do one thing most free resources don't: they present a realistic scenario with a messy data model, then walk you through the solution while explaining why each piece exists. Not just the answer, but the reasoning that led to it. Here's how to get the most out of that kind of material. Start by understanding your data model before you touch a single SELECT. I see people jump straight to queries all the time, which is backwards. In my experience, spending ten minutes mapping out the relationships between tables — foreign keys, nullable columns, indexing strategy — cuts your debugging time down significantly. It usually takes me about five minutes to sketch out the schema mentally and another five to write the first draft. A lot of those first drafts are wrong, but the wrong ones are instructive. Work through problems in order of complexity. Don't start with window functions or recursive CTEs. Start with GROUP BY and HAVING, move into subqueries, then join multiple tables, and only then tackle the harder stuff. The progression matters because each layer builds on the last. If you try to write a query with three nested CTEs before you're comfortable with a simple self-join, you'll get lost in the nesting and never figure out where the bug is.
Here are a few questions I keep coming back to because they cover the kind of scenarios that show up in real work and in interviews alike.
Get the Full Details

Fundamental Questions
Question 1: Write a query to find the second highest salary from an Employee table. Solution approach: There are at least three ways to do this, and the "right" one depends on what you're optimizing for. The simplest for beginners uses a subquery:
SELECT MAX(salary) FROM Employee WHERE salary < (SELECT MAX(salary) FROM Employee); This works fine on small datasets. On larger tables, it scans the table twice, which adds up. A cleaner approach uses ORDER BY with LIMIT and OFFSET: SELECT salary FROM Employee ORDER BY salary DESC LIMIT 1 OFFSET 1;
Even better for production use, especially if you need the Nth highest where N changes, is a dense_rank window function. It handles ties correctly, which the two methods above don't always do. If two people share the top salary, the subquery method gives you that same salary again as the "second highest," which is wrong if you mean the second distinct value. Question 2: Find all employees who earn more than their department's average salary. Solution:
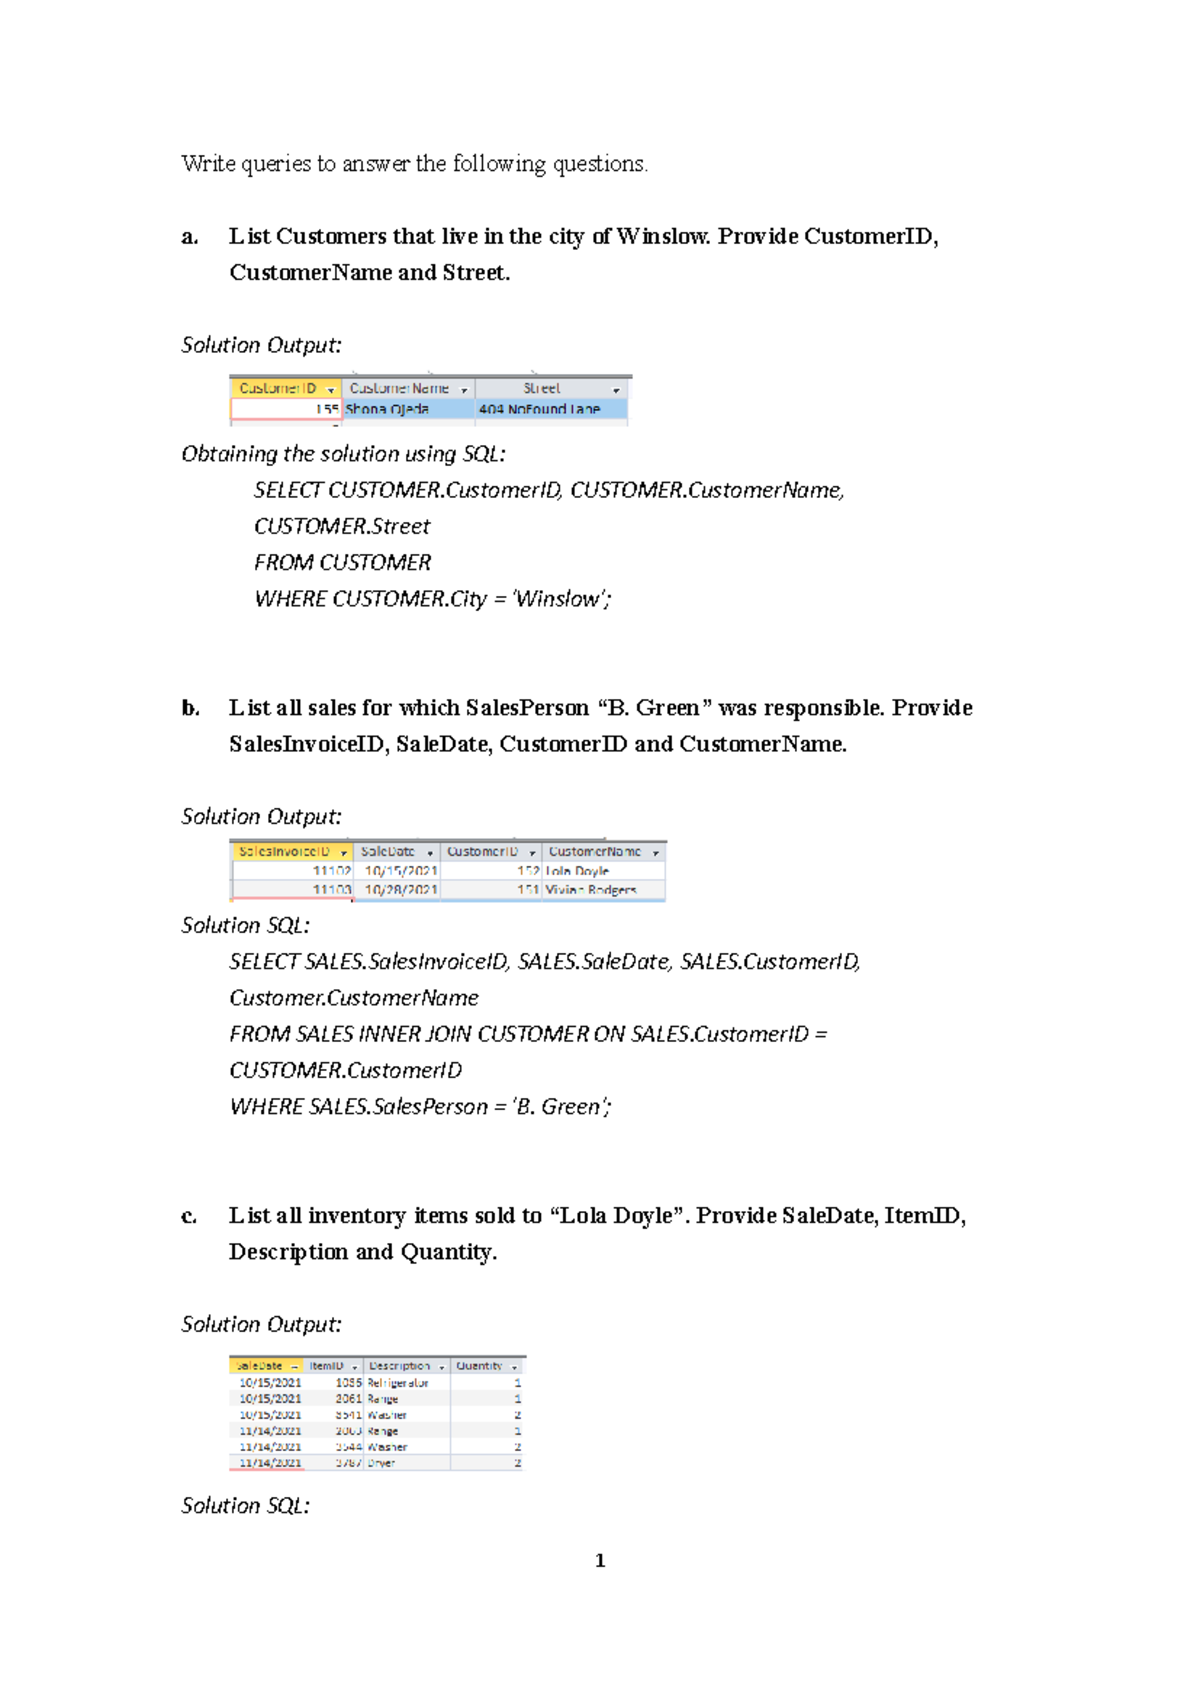
This requires a correlated subquery or a CTE. Here's the CTE version, which is easier to read and often faster because the database can cache the subquery result: WITH dept_avg AS (SELECT department_id, AVG(salary) AS avg_salary FROM Employee GROUP BY department_id)
SELECT e.name, e.salary, d.department_id FROM Employee e
JOIN dept_avg d ON e.department_id = d.department_id
WHERE e.salary > d.avg_salary; The correlated subquery version does the same thing but recalculates the average for each row. On a table with thousands of employees across a dozen departments, that's a lot of unnecessary recomputation. I learned this the hard way once when I shipped a report query that joined back to itself on every row of a 500K-row table. It ran for forty-three minutes. Rewriting it with a CTE dropped it to under two minutes.
Moderate Difficulty Questions
Question 3: Delete duplicate rows from a table without using a temporary table. Solution: This is one of those questions that sounds simple until you actually try to write it. The approach depends on your database. In PostgreSQL and SQL Server, you can use ROW_NUMBER():
WITH cte AS (SELECT *, ROW_NUMBER() OVER (PARTITION BY column1, column2 ORDER BY id) AS rn FROM table_name)
DELETE FROM cte WHERE rn > 1; In MySQL, you'd use a self-join instead: DELETE t1 FROM table_name t1 JOIN table_name t2 ON t1.column1 = t2.column1 AND t1.id > t2.id;
The edge case I ran into here was when the table had no primary key or unique identifier. ROW_NUMBER() needs an ORDER BY clause, and without any stable ordering, the results are non-deterministic. You end up deleting arbitrary rows, which is bad. My workaround was to add a synthetic unique column first using a row numbering function, then run the deduplication, then drop the temporary column. It's an extra step but it prevents data loss. Question 4: Find the cumulative sum of a column grouped by another column. Solution:
This calls for a window function with an accumulating frame: SELECT date, department, revenue, SUM(revenue) OVER (PARTITION BY department ORDER BY date) AS cumulative_revenue FROM sales; The PARTITION BY creates separate running totals for each department. Without it, you'd get one massive cumulative sum across everything, which is rarely what you want. The ORDER BY inside the OVER clause determines the sequence. If you omit it, most databases will give you an error or return the total in an undefined order depending on the engine.
Advanced Questions
Question 5: Write a query to find consecutive login streaks for users. Solution: This is a gaps-and-islands problem, which trips up a lot of people. The trick is to subtract a row number from the dates. When dates are consecutive, that difference stays constant within a streak.

WITH ranked AS (SELECT user_id, login_date, ROW_NUMBER() OVER (PARTITION BY user_id ORDER BY login_date) AS rn FROM logins),
groups AS (SELECT user_id, login_date, DATE_SUB(login_date, INTERVAL rn DAY) AS grp FROM ranked)
SELECT user_id, MIN(login_date) AS streak_start, MAX(login_date) AS streak_end, COUNT(*) AS streak_length FROM groups GROUP BY user_id, grp HAVING COUNT(*) >= 3; I worked on a project where we needed this exact logic to detect subscription fraud. Someone would log in daily for a week, then suddenly stop and reappear under a different account. The consecutive login pattern was a reliable signal. The tricky part wasn't the query itself — it was making it performant. The ranked CTE alone was scanning millions of rows. Adding an index on (user_id, login_date) reduced the runtime from several minutes to under ten seconds. Without the index, the window function had to do a full table sort for every user. That's a detail most practice sets won't tell you about. Question 6: Pivot rows into columns dynamically.
Solution: Dynamically pivoting in SQL is database-specific and not always straightforward. Here's how it works in SQL Server using dynamic SQL: DECLARE @cols NVARCHAR(MAX), @query NVARCHAR(MAX);
SELECT @cols = STRING_AGG(QUOTENAME(category), ',') FROM (SELECT DISTINCT category FROM sales) t;
SET @query = 'SELECT product, ' + @cols + ' FROM sales PIVOT (SUM(amount) FOR category IN (' + @cols + ')) p';
EXEC sp_executesql @query;
In PostgreSQL, you'd use FILTER clauses or conditional aggregation instead. Each approach has trade-offs. Dynamic SQL is flexible but harder to maintain and opens you up to injection risks if you're not careful with sanitization. Static pivot queries are safer and easier to debug but break the moment a new category appears in your data. I usually recommend static aggregation for production code and dynamic pivots only for reporting tools where the column set changes infrequently.

Common Mistakes to Avoid
One thing I notice constantly is people confusing WHERE and HAVING. WHERE filters rows before aggregation. HAVING filters groups after aggregation. Put a condition like "salary > 50000" in a HAVING clause and the database will throw an error because salary isn't part of any aggregate function and isn't in the GROUP BY. These aren't edge cases — they're the most common syntax errors I see in code reviews. Another frequent issue is assuming NULL behaves like zero or an empty string. It doesn't. NULL means unknown, and any comparison with NULL returns NULL, which evaluates to false in a WHERE clause. If you want to include NULLs in a count, you need COALESCE or ISNULL to replace them first. If you're joining on a column that contains NULLs, remember that NULL = NULL is always false. You'll get unexpected missing rows in your results and no error message to warn you about it. Index usage is another area where practice questions rarely help but real work absolutely demands attention. A query that looks correct can still be catastrophically slow if the database engine decides to do a sequential scan instead of an index seek. Running EXPLAIN ANALYZE on your queries — even simple ones — teaches you more about performance than any tutorial. It shows you exactly what's happening at the execution level: which indexes are being used, how many rows are being scanned, where the sort operations are happening. I check EXPLAIN output before I ship anything that touches more than a few thousand rows.
If you're looking for places to practice, a few reliable sources include LeetCode's SQL section, HackerRank's SQL track, and StrataScratch, which pulls real interview questions from companies. Mode Analytics also has a solid SQL tutorial with interactive exercises that feel closer to actual work than most gamified platforms. For deeper study, the PostgreSQL documentation and execution plan guides from each major database vendor are worth more than half the courses I've seen. The bottom line is that SQL practice only works if the problems approximate real conditions. Syntax drills build muscle memory but they don't teach you to think about query plans, data distribution, or how your query will behave when the dataset grows tenfold. The questions I listed above are useful because they force you to deal with those issues directly — duplicate handling, consecutive date logic, dynamic column generation, performance-aware writing. Work through them slowly, read the solutions carefully, and then modify them to break them. Change the data types, add constraints, introduce skewed distributions. See what happens when your assumptions no longer hold. That's where the actual learning is.
