How Stack Based Programming Language Actually Works
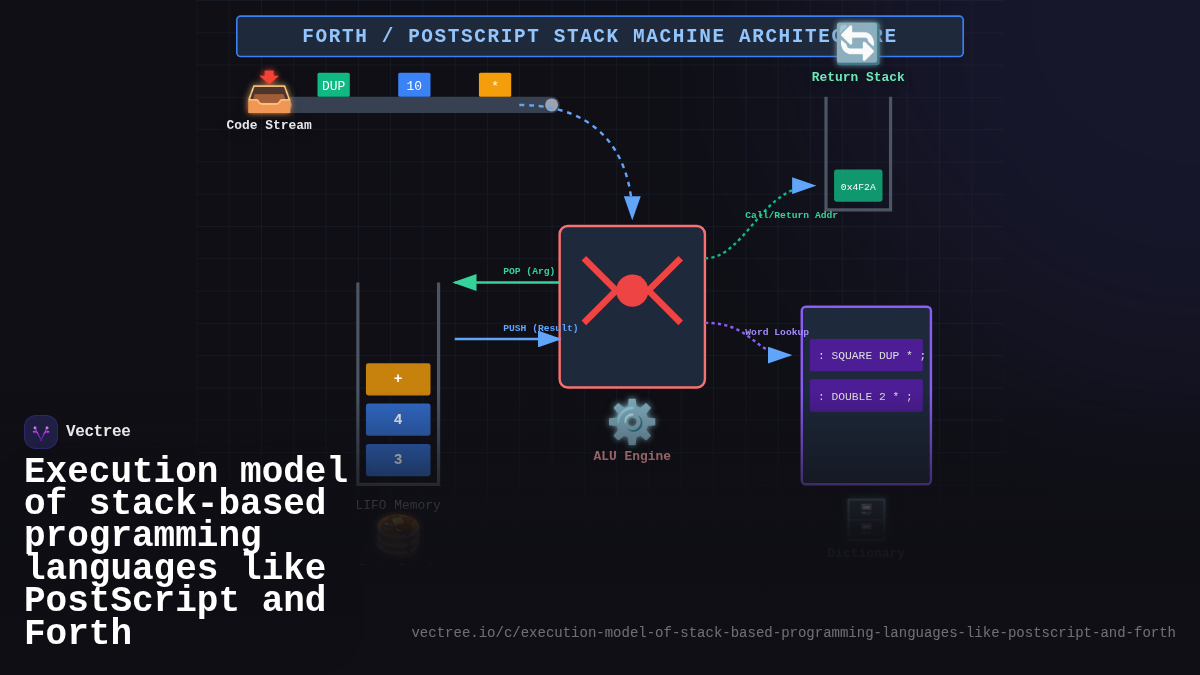
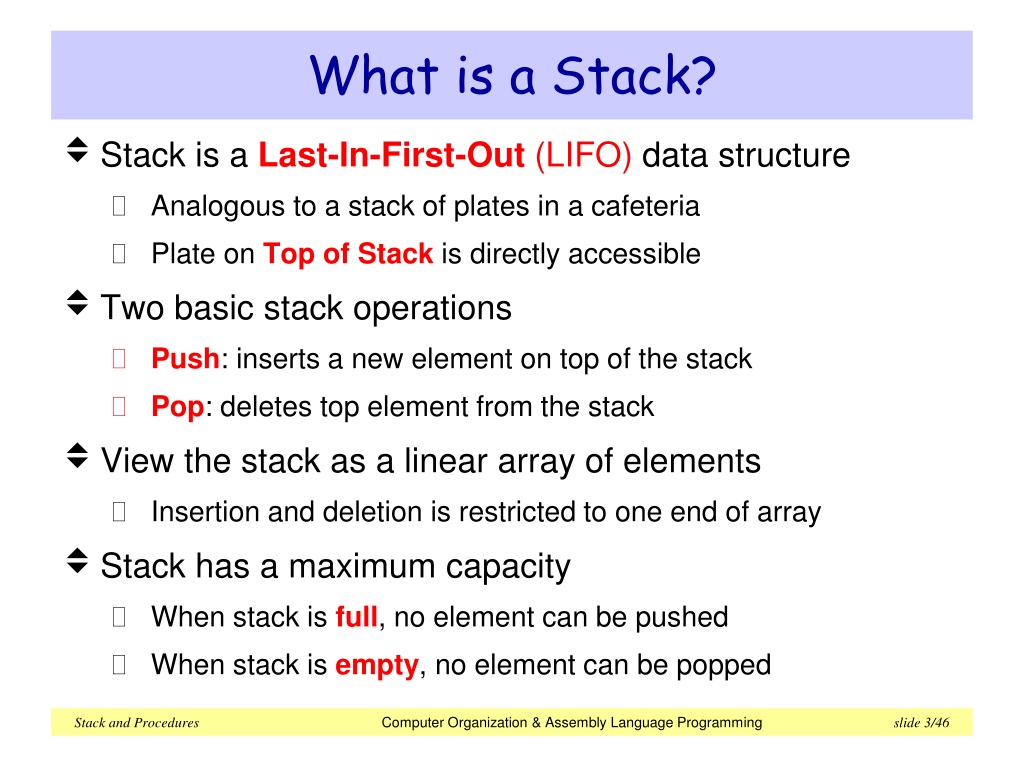
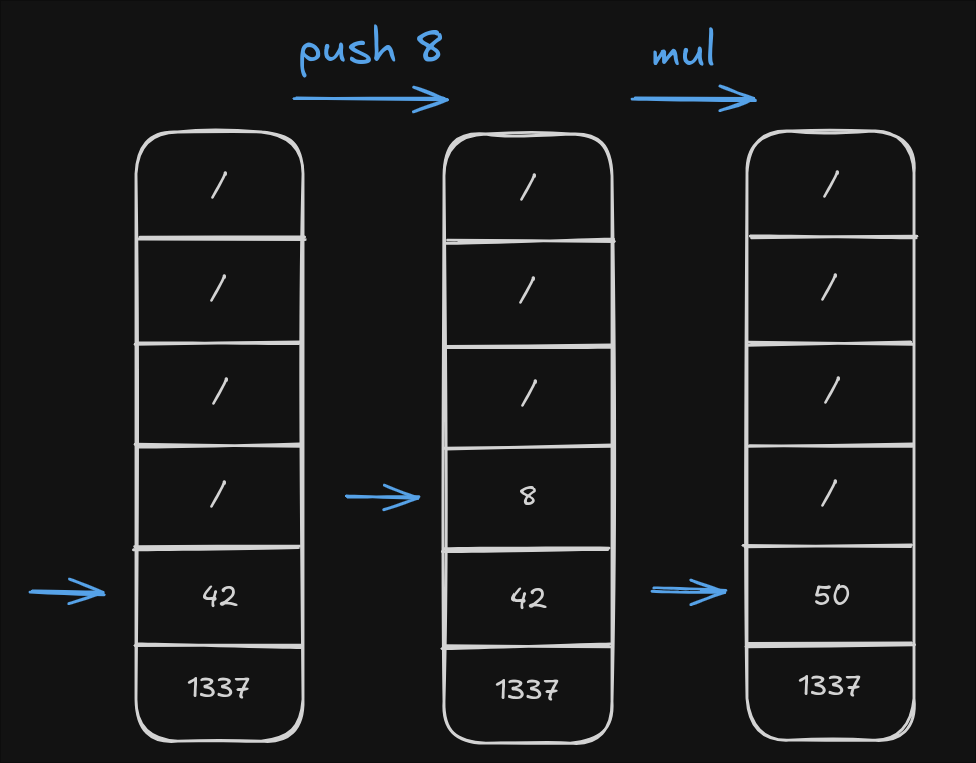
A stack based programming language is simpler than most people expect once they stop trying to map it onto traditional imperative programming. You have a stack. Operations push values onto it. Other operations pop values off it. That is the entire model. Everything else is built on top of that. I first encountered this through PostScript in the early 2000s when I was debugging a printer driver that generated page descriptions. The code looked like complete gibberish at first glance. Something like 3 4 add dup 2 mul. But once you read it right to left instead of left to right, it makes perfect sense. Push 3, push 4, add them, duplicate the result, multiply by 2. You get 14. The compiler or interpreter doesn't care about variable names or parentheses. It just executes instructions in order against the stack.
What Is Stack Based Programming Language
The term covers any language where the stack is the primary mechanism for passing data between operations. Forth is probably the most well known. Factor and Joy are more modern examples. Even your calculator might be stack based if it uses Reverse Polish Notation. The key characteristic is that functions receive their arguments from the stack rather than through named parameters. Most traditional languages use something called an operand stack combined with an environment or frame stack. Stack based languages collapse those into a single structure. This is both the elegance and the frustration. You are always working with the same mechanism. Here is a practical example. Say you want to compute the area of a triangle. In a C-style language you might write area = 0.5 * base * height. In a stack based language it would look more like 0.5 swap * rot * or some variation depending on the language. The values end up on the stack, operations rearrange and consume them, and you pull the result off at the end. No assignment statements. No intermediate variables. Just stack manipulation.
I spent about three weeks converting a batch processing script from Python to Factor for a client who needed more deterministic memory behavior. Factor uses a stack plus a heap, and it handles large data transforms without the garbage collection pauses that Python throws in your face during batch runs. The conversion took longer than expected because my brain kept wanting to reach for variables. I had to rewrite my thinking process, not just translate syntax.
Get the Full Details
The Mechanics You Need to Know
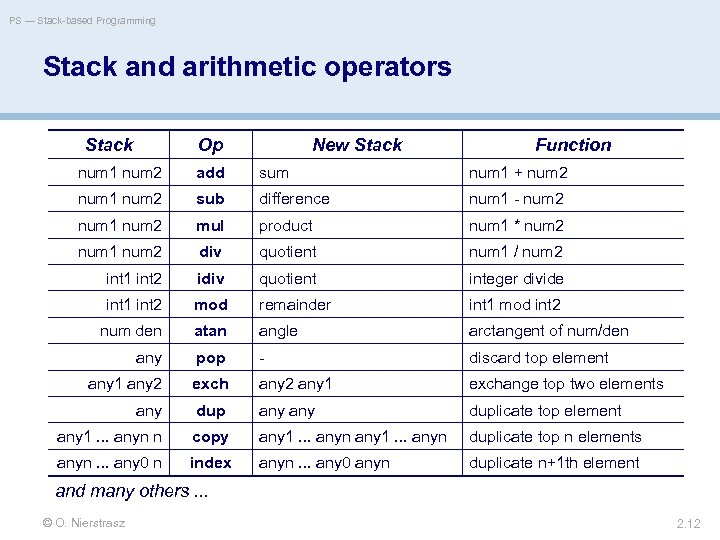
Understanding the core stack operations is essential before you write anything meaningful. Push places a value on top. Pop removes the top value and discards it. Dup copies the top value. Swap exchanges the top two values. Over copies the second value to the top. These five operations alone can construct just about anything. Deeper stack manipulation gets tricky quickly. Rot moves the third item to the top, shifting the top two down. Drop removes the top item without using it. Pick accesses an arbitrary depth without disrupting the rest of the stack. Each language implements these slightly differently. Factor calls them quoters or combinator words. Forth has rot and -rot. PostScript uses roll and croll. The real challenge is composing these into useful abstractions. When I built a simple JSON parser in Factor, I ended up writing a custom combinator that handled the stack rearrangement for nested objects. Without it, every nested level required manual swap and dup sequences that made the code nearly unreadable. The combinator reduced about forty lines of stack gymnastics down to six lines of readable code.
Where It Falls Apart
Stack based languages are not a universal solution. They struggle with certain patterns that imperative languages handle naturally. Recursive algorithms that depend on maintaining multiple frames of local state become painful. You have to explicitly manage the stack yourself, which means writing your own stack management code instead of relying on the language runtime. Debugging is harder. When a stack based program crashes, you often get a stack trace that shows you exactly what was on the stack at the time of failure, but reading that trace requires fluency in the stack manipulation vocabulary. A typical crash in Forth might show you a stack state like ( 42 -- ) meaning it expected two values and got one. figure out which operation caused the mismatch takes experience. Memory management is another issue. While stack based languages like Factor avoid the garbage collection pauses that plague Python or Java, they do not eliminate memory concerns entirely. Deeply nested computations can still cause stack overflow if you do not restructure your code to use heaps or explicit data structures. I ran into this with a image processing pipeline that needed to maintain large intermediate matrices. The stack grew to several hundred megabytes before I rewrote the core loop to use persistent arrays instead.
Performance varies significantly by language. PostScript interpreters are generally slow because they are designed for readability by machines that render pages, not for computational throughput. Forth can be extremely fast if compiled properly, sometimes approaching C speeds on simple numeric operations. Factor sits somewhere in between with a JIT compiler that handles common patterns well but struggles with deeply recursive code.
Getting Started Practically
If you want to try this, Factor is probably the most approachable starting point. It has a graphical development environment, decent documentation, and a package manager called the Bundle Database. You can download it from factorcode.org. The free version includes everything you need for learning. There is no paid tier blocking core functionality. Forth is another option but the ecosystem is fragmented. You will pick up different dialects depending on which implementation you use. gforth runs on Linux and macOS and handles most standard Forth well, but it lacks some of the modern extensions that commercial implementations provide. If you go this route, stick to ANSI Forth features and avoid dialect-specific extensions until you are comfortable. PostScript is more of a legacy choice now. It is still relevant for printer drivers and PDF generation, but learning it purely as a programming exercise offers diminishing returns. The syntax is intentionally verbose and the error messages are unhelpful. I only recommend it if your actual goal is working with print systems or PDF internals.
My recommendation is to start with Factor and work through the tutorial that ships with it. The first ten exercises cover push, pop, dup, swap, rot, and basic function composition. By the time you finish exercise ten, you should be able to write a simple stack based program that reads input, processes it, and outputs results without referencing any variables. That baseline is important because everything after it builds on the same stack-first mindset. There is a learning curve but it is a narrow one. Most people who commit to it can write functional stack based code within two to three weeks of regular practice. The barrier is not the syntax. It is unlearning the habit of reaching for named variables on every problem.