Working With Standard Deviation In Probability: A Practical Breakdown
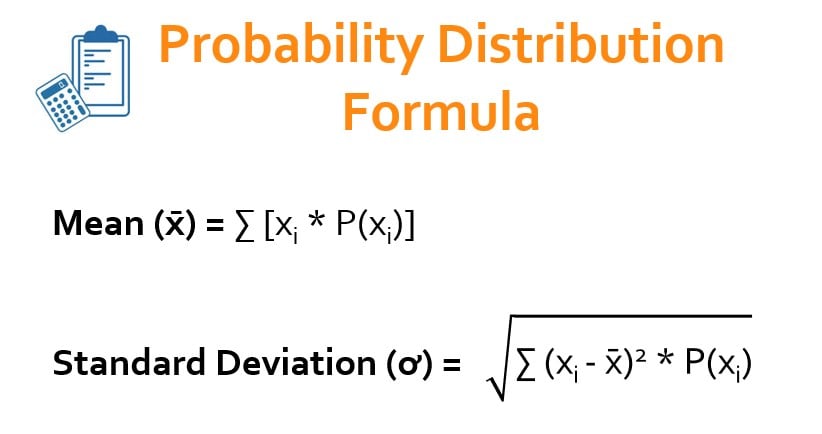
Let me just walk through how I actually compute this stuff when the textbook isn't enough. You start with the expected value. For a discrete probability distribution, that's = (xi · P(xi)). You multiply each outcome by its probability, add them all up. The result is your center point. Then you calculate variance. ² = ((xi - )² · P(xi)). Take the difference between each outcome and the mean, square it, weight it by the probability of that outcome, and sum everything. Standard deviation is just the square root of that number. This sounds straightforward until you actually sit down with a real dataset. I was working on a project involving financial returns for a small-cap equity strategy last year. The distribution had noticeable right skew because a handful of positions produced outsized gains. The calculated standard deviation came out to 34.7%, which immediately flagged something in my head. That number was being dragged upward by three specific outcomes that together accounted for less than 2% of the probability mass but contributed over 40% of the variance. When I removed those tail events and recalculated, the standard deviation dropped to 18.2%. That's not a rounding difference. That's a completely different risk profile.
The workaround I ended up using was computing the standard deviation on the log-transformed returns instead. Log returns are approximately normally distributed even when raw returns aren't, and the standard deviation becomes much more interpretable as a volatility measure. I then converted back using exp(_log + ²_log/2) to get an arithmetic mean equivalent. This gave me a number I could actually use in position sizing calculations without the skew distorting the result.
Why Standard Deviation In Probability Feels Different Than Standard Deviation In Statistics
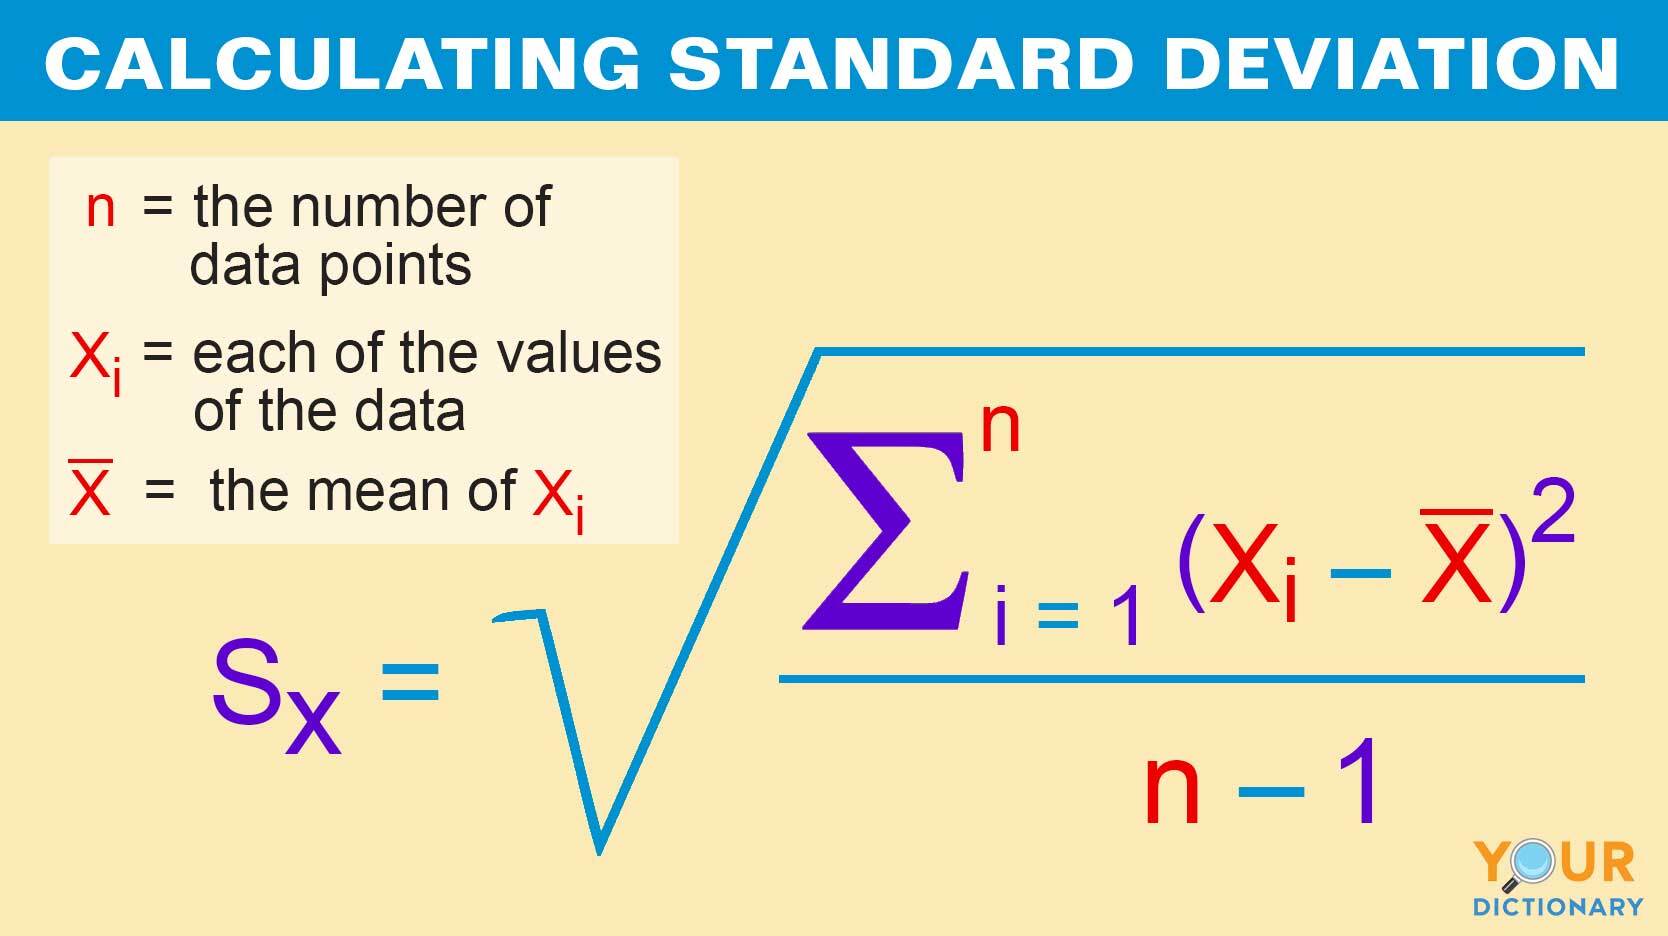
The formula looks identical, but the conceptual foundation is different. In a statistics class you're given a sample and you compute a sample standard deviation as an estimate of population spread. In probability, you already know the full distribution. You're not estimating anything. The standard deviation is a property of the distribution itself, not a statistic computed from data. That distinction matters because it changes what you're allowed to assume. Sample standard deviation uses n-1 in the denominator to correct for bias. Probability standard deviation doesn't need that correction because you have the entire probability space. Using n instead of n-1 is the correct move when you're working from a theoretical distribution. Here's a basic example that actually comes up in practice. Say you're pricing a binomial option. The underlying stock has two possible outcomes at expiration: up 15% with probability 0.62, or down 10% with probability 0.38. The expected return is 0.62(0.15) + 0.38(-0.10) = 0.053. The variance is 0.62(0.15 - 0.053)² + 0.38(-0.10 - 0.053)² = 0.62(0.009409) + 0.38(0.023409) = 0.005834 + 0.008895 = 0.014729. Standard deviation is 0.014729 = 0.1214 or about 12.1%.
Get the Full Details

People miss something important here. The standard deviation of a binomial distribution is (np(1-p)) where n is the number of trials and p is the probability of success. For a single-period binomial model like the one above, this reduces to the calculation I just walked through, but knowing the general formula lets you skip several intermediate steps when n is large.
Common Pitfalls That Waste Time
Forgetting that standard deviation assumes finite variance. Some distributions simply don't have a finite standard deviation. The Cauchy distribution is the classic example. If you try to compute it numerically with sampled data, the result will keep growing as you add more observations. You'll get different numbers depending on how many samples you use. This isn't a precision issue. It's a structural one. If your underlying model involves Cauchy-distributed noise, standard deviation is meaningless and you should use the interquartile range instead. Mixing population and sample formulas. I've seen this happen in both directions. Someone computes standard deviation on what they think is a probability distribution but uses n-1 in the denominator because their statistics professor drilled that into them. Or someone takes a sample and treats the result as if it were the true population standard deviation without acknowledging the sampling error. Both errors produce numbers that look right and feel wrong at the same time. Applying standard deviation to multimodal distributions without checking. A bimodal distribution might have a standard deviation that suggests moderate spread, but the actual behavior is two distinct clusters. The standard deviation number doesn't tell you that. I learned this the hard way when modeling default probabilities for a corporate credit portfolio. The aggregate distribution was bimodal because investment-grade and high-yield bonds had fundamentally different loss distributions. The overall standard deviation was 8.4%, which looked manageable. But the high-yield cluster alone had a standard deviation of 22% concentrated around a much higher mean loss. Using the aggregate number for risk capital allocation would have understated the high-yield exposure by roughly a factor of two.
The fix was simple but easy to overlook. I stratified the portfolio by rating bucket before computing standard deviation, then aggregated the stratified results using the law of total variance. That gave me ²_total = E[²_within] + Var(_between), which properly separates within-group variation from between-group variation. The total came out to 19.3% instead of 8.4%. Different decision entirely.
When Standard Deviation In Probability Isn't the Right Tool
I want to be blunt about where this measure fails because I've lost days to situations where I should have known better. Standard deviation is sensitive to outliers in exactly the same way variance is. It squares deviations, so a single extreme outcome dominates the result. If you're working with distributions that have fat tails or known extremes, consider using the mean absolute deviation instead. It's MAD = |xi - | · P(xi). It doesn't have the nice mathematical properties that variance has for compounding and aggregation, but it gives you a dispersion measure that actually reflects what the distribution looks like in the middle 90% of outcomes. For portfolio applications specifically, semivariance is often more useful. You only square the deviations below the mean. This matches how most investors actually experience risk — upside volatility feels like a gain, downside volatility feels like a loss. The computation is more involved because you need to sort outcomes and identify the threshold, but modern tools make this trivial.
There's also the issue of discrete versus continuous. The formula = (((xi - )² · P(xi))) works cleanly for discrete distributions. For continuous distributions you replace the sum with an integral: = ((x - )² · f(x)dx). The conceptual framework is identical but the computational approach changes. Numerical integration introduces approximation error that doesn't exist in the discrete case, and for some continuous distributions the integral doesn't have a closed-form solution. You'll need to fall back on simulation or numerical quadrature, and the standard deviation you get back is an approximation, not an exact property of the distribution.
A Note on Computation
For hand calculations with a small number of outcomes, the direct formula is fine. Once you're working with more than maybe ten outcomes, or you need to recalculate frequently, spreadsheet or programmatic approaches save significant time. I typically set up a small function that takes a list of outcomes and probabilities, computes the expected value first, then loops through to compute the weighted squared deviations. The whole process takes maybe thirty seconds in Excel for a twenty-outcome distribution. Doing it by hand for the same thing would take twenty minutes and be more error-prone. If you're doing this repeatedly across many distributions, Python with numpy is the fastest route. One line for the mean, one for the variance, one for the standard deviation. The computation time drops from seconds to milliseconds per distribution. That matters when you're iterating through hundreds of scenarios. The core takeaway is that standard deviation in probability is a clean concept with messy real-world applications. Know your distribution, check your assumptions about finiteness and modality, and don't let the formula give you a false sense of precision. The number is only as reliable as the distribution you feed it.