
Where Most People Drop the Ball on Their Stats Workflow
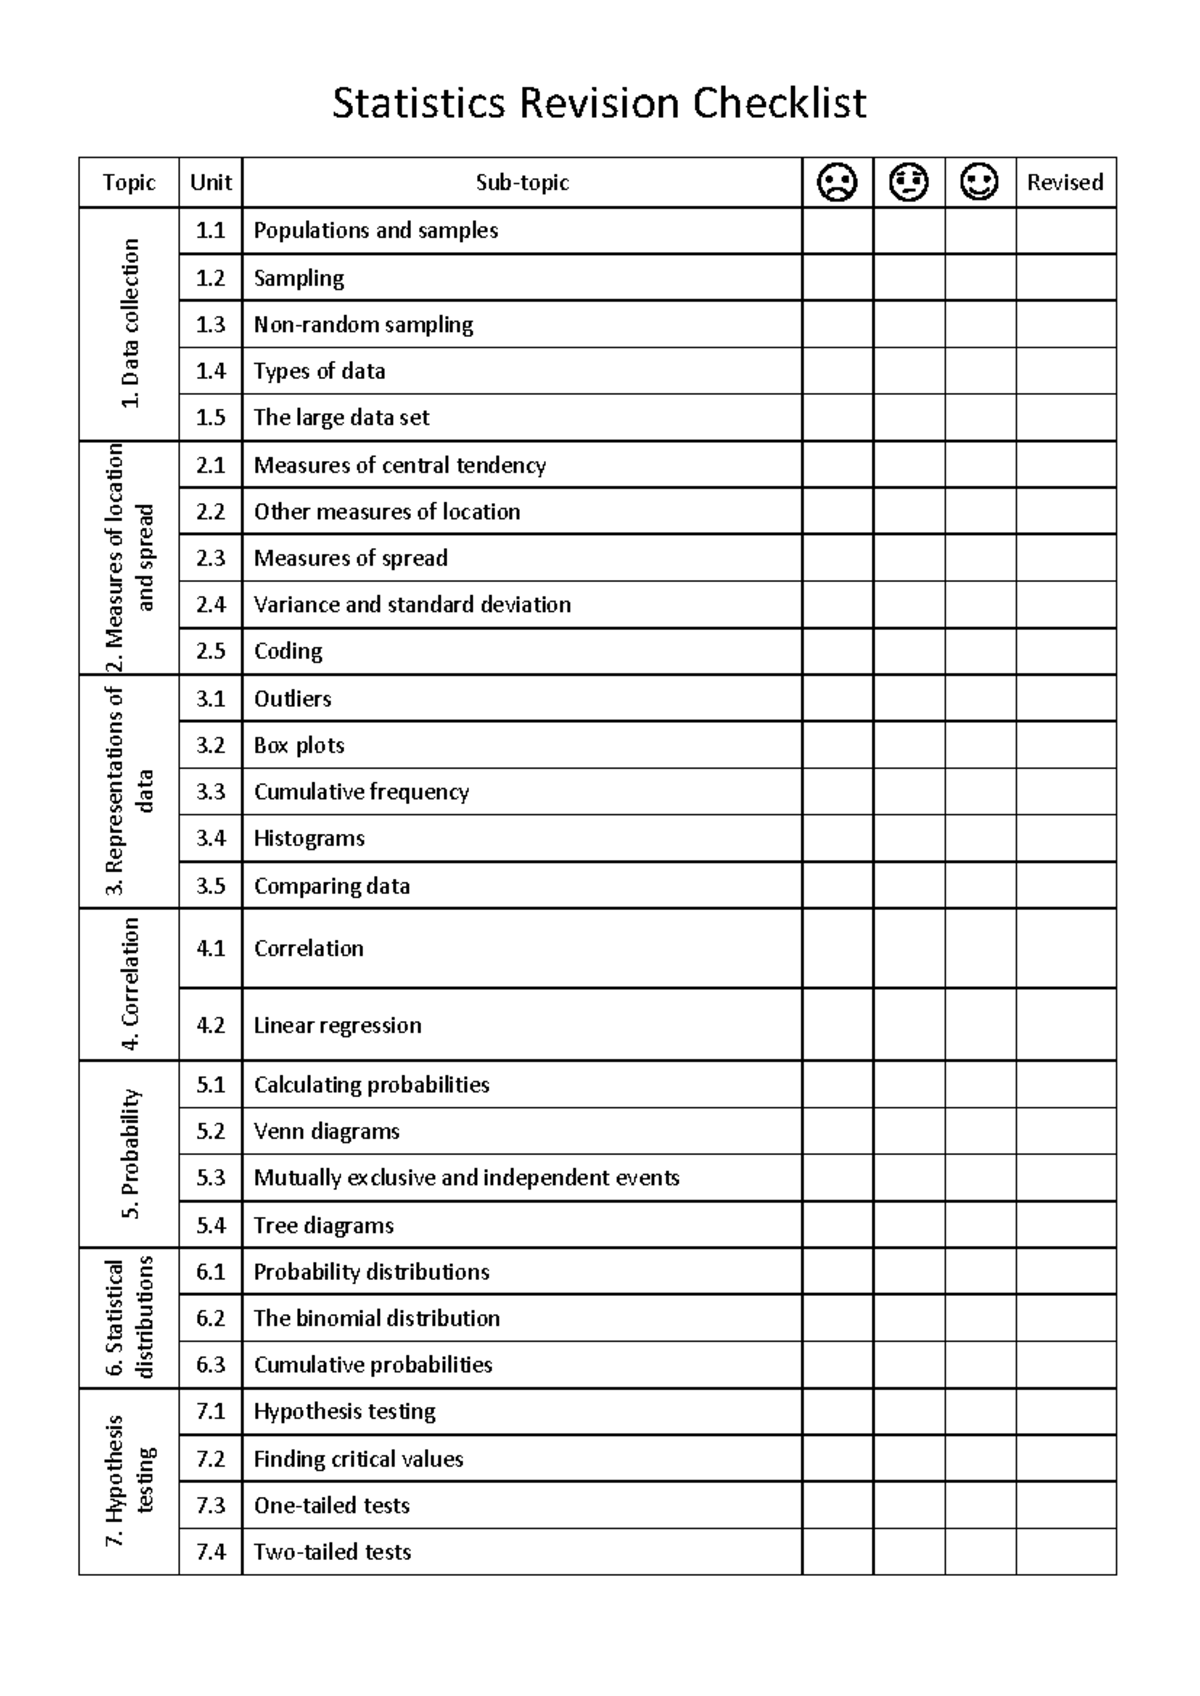
Running a proper statistical analysis is a multi-step pipeline and every single step has a place where you can lose hours of work. I built out a Statistics Checklist that I reference before and during every project, mostly because I keep repeating the same mistakes anyway. Here is what lives on my screen while I work. It is not a comprehensive academic framework. It is a set of checkpoints I hit before I touch a dataset, right after cleaning, and before I ship any numbers to anyone else. Phase one — before you open anything. Define the question you are actually answering. Not the question you think you should be answering. The one your stakeholders would use to decide whether the project was a success or a waste of budget. Write it down in one sentence. This sounds basic and I skip it until something breaks.
Phase two — data audit. Check the sampling frame. Identify which units are missing, which variables have structural zeros, and whether your N is large enough for the test you plan to run. For a two-sample t-test with equal variance you need roughly 30 per group to get stable power. For logistic regression the rule of thumb is ten events per predictor variable. If you are doing survival analysis with time-to-event data you need to watch the event rate, not just the total sample size. Phase three — cleaning and validation. Look at distributions before you summarize them. Mean and standard deviation will lie to you on skewed data. Run a quick normality check if you are planning parametric tests. Not because you need perfection but because a heavy skew with n=40 will inflate your Type I error in a way you will not notice until someone asks you about it. Phase four — analysis execution. Document your code with enough comments that you can explain it to someone who only speaks R or Python. Version-control everything. Save intermediate outputs so you can rerun a failed step without redoing the entire pipeline.
Phase five — interpretation and reporting. Report effect sizes alongside p-values. A statistically significant result with a Cohen d of 0.1 is not meaningful in most applied settings. I use Cohen benchmarks as a starting point, not a law. Context matters more than any table in the back of a textbook.
Get the Full Details
What Nobody Tells You About This Process
There are a few things that make this checklist painful in practice. I will give you the ones that cost me the most time. The first is missing data patterns. People assume missing completely at random and move on. It is almost never the case. In a clinical trial I ran a while back I had eighteen percent missingness on a primary outcome. A quick Little's MCAR test came back significant, which told me the data were not missing at random. I could not just drop those cases without biasing the result. I switched to multiple imputation with chained equations and added the outcome variable to the imputation model itself. That detail alone changed the direction of my conclusion. Had I just used listwise deletion I would have reported a statistically significant treatment effect that disappeared once the imputation accounted for the dropout pattern. The workaround was slow — I spent about six hours debugging the imputation model convergence — but it saved me from publishing the wrong thing. The second thing is measurement error in covariates. When you include a noisy predictor in a regression model you get attenuation bias. The coefficient shrinks toward zero. Beginners often see a nonsignificant relationship and blame the sample size. The real issue is that the variable itself is unreliable. I learned this the hard way when analyzing survey data where the self-reported income variable had a Cronbach alpha well below 0.7. I stopped treating that variable as if it were a precise measure and ran a sensitivity analysis instead. I simulated what the effect would look like under different reliability assumptions. The adjusted estimate was half the size of the unadjusted one. Most journals would have rejected the paper if I had only reported the naive model.
The third thing nobody warns you about is p-hacking in disguise. You do not need to knowingly fish for significance. You just need to make a sequence of analytical decisions that each look reasonable on their own. Choosing between a one-tailed or two-tailed test. Deciding whether to transform a variable. Handling outliers by trimming or winsorizing. These are all defensible choices. But they stack. By the time you have made six or seven of them your effective alpha is nowhere near 0.05. The workaround is pre-registration or at minimum a written analysis plan you commit to before looking at the results. If you cannot pre-register for some reason, write the plan down and timestamp it. It keeps you honest and gives reviewers something concrete to evaluate.
When This Approach Breaks Down
A checklist does not fix bad data. If your sampling frame is fundamentally flawed — say you recruited participants through a single online panel that skews young and educated — no amount of imputation or sensitivity analysis will make your results generalizable to the broader population. The checklist will help you document the limitation. It will not remove it. The checklist also does not help when the research question itself is vague. "Does our intervention work?" is not a good question because it hides the mechanism you are trying to measure. You need to specify the active ingredient, the expected effect size, and the comparator. If you cannot do that, your statistical plan will drift and you will end up with results that are technically correct but uninterpretable. For small samples with complex models the checklist becomes almost useless. Bayesian hierarchical models with weakly informative priors are better suited to that regime than frequentist approaches. If you are working with fewer than fifty observations and more than five predictors you should consider regularization techniques like ridge or lasso regression instead of trying to force a traditional test to work. The checklist will remind you that the problem exists. It will not give you the answer.

How to Use This in Practice
Save the checklist as a single document and keep it open in a separate window while you work. Do not treat it as a form to fill out after the fact. You will skip items if you do that. I learned this the hard way during a grant report where I had already run my analysis and then tried to retrofit the checklist. I caught four serious issues in about ten minutes but I was already deep into a different project when I did it. If I had checked those issues earlier the whole thing would have taken twenty minutes instead of an afternoon of reanalysis. I also find it useful to run the checklist at the beginning of each meeting with collaborators. I go through it line by line and ask whether we have addressed each item. It sounds tedious. It prevents arguments later when someone says the model was biased or the sample was underpowered or the p-value was one-tailed without disclosure. The meeting takes about fifteen minutes and it saves hours of revision down the line. If you want a downloadable version I keep mine as a plain text file that I update whenever I encounter a new edge case. It is not published anywhere formal. It is just my working document. I can share it if anyone wants to see the current version. The file is called stats_checklist_v4.txt and it is roughly two hundred lines long with comments explaining why each item exists. I update it after every project that reveals a gap in my previous thinking.
The main takeaway is that a checklist is only useful if you actually use it. Most people build one and forget about it. The people who benefit are the ones who keep it visible and treat it as a habit rather than a formality. I have been doing this long enough to know that the difference between a clean analysis and a messy one is rarely the complexity of the method. It is usually whether someone paused long enough to check the assumptions before they ran the model.


