Getting Started With Statistics Examples Easy
Most people pick up statistics because they need it for work or research, not because they enjoy grinding through abstract formulas. The problem is that every textbook explains concepts in isolation, which makes it nearly impossible to see how things connect in practice. That's where tools like Statistics Examples Easy come in. It's essentially a curated collection of hands-on examples that walk you through common statistical procedures without requiring you to dig through three chapters of theory first. I've spent years working with data teams, and the most frequent bottleneck I see isn't people being bad at math. It's that they don't know which test applies to their specific situation until after they've already run the wrong one twice. This resource helps you skip that part by showing actual implementations alongside the theory.
What Statistics Examples Easy Actually Covers
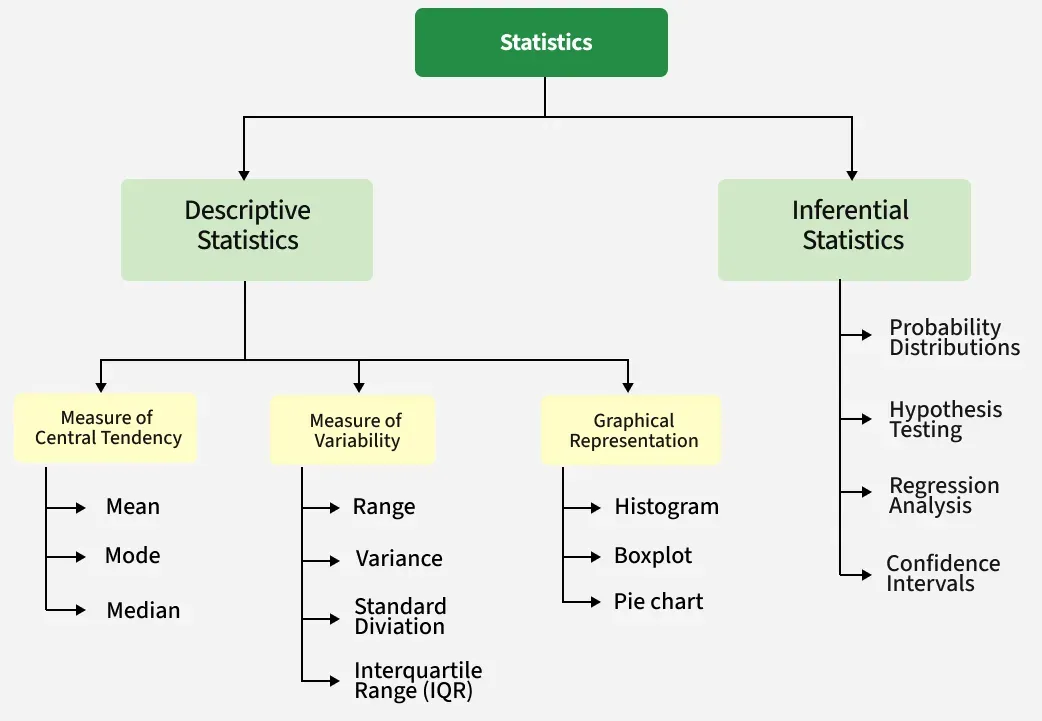
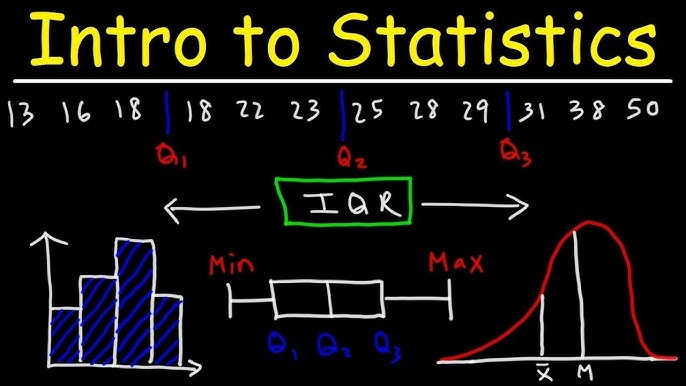
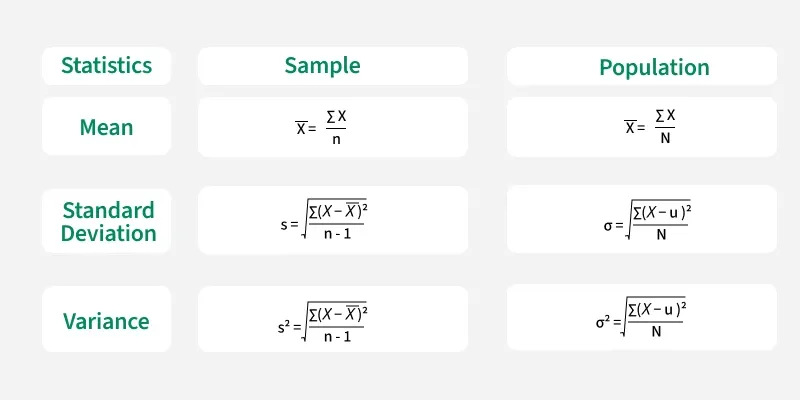
The collection breaks down into several core areas. Descriptive statistics comes first, because you cannot build a model or run a test on garbage data. Mean, median, standard deviation, interquartile range — the usual suspects, but each one paired with real datasets instead of made-up numbers from a textbook. Then there's probability distributions, hypothesis testing, confidence intervals, regression analysis, ANOVA, chi-square tests, and correlation methods. It's not exhaustive, but it hits the things you'll actually use on a weekly basis. One thing most guides gloss over is the decision tree for choosing between tests. You should have a clear flowchart in your head for questions like: normal or non-normal distribution, one group or two, paired or independent, categorical or continuous. When I first started using this myself, I skipped that section because I thought I already knew it. Two weeks later I ran a t-test on ordinal survey data and wasted an entire afternoon trying to figure out why my results looked wrong. The workaround was straightforward once I actually went back and read that flowchart. Since then I keep a printed copy on my desk.
How to Use This Resource Effectively
Open the example that matches your current problem, not the one that looks the closest. There's a difference. People tend to scan titles and pick "t-test example" when they actually need a Mann-Whitney U test, and then they spend another hour debugging output that doesn't make sense. Read the methodology section before you copy any code or formulas. The examples include downloadable datasets, code snippets in both R and Python, and step-by-step explanations of each calculation. If you're working in a different environment like SPSS or Excel, the mathematical steps translate directly. I usually take the R version, adapt the logic to whatever tool my team uses, and then compare the output to verify I didn't introduce a bug during translation. That verification step alone has saved me from shipping incorrect analyses at least four times. Here's a practical example that came up recently. A client needed to compare customer satisfaction scores across four different store locations. The scores were on a Likert scale from one to five, which means ordinal data, not interval. A lot of beginners would immediately reach for a one-way ANOVA. The correct approach here is Kruskal-Wallis followed by post-hoc Dunn's test if the result is significant. The resource covers this exact scenario with code, so instead of spending two hours searching Stack Overflow and piecing together incompatible solutions, I had a working script in about fifteen minutes.
Get the Full Details

Common Mistakes That Trip People Up
P-hacking is the biggest one. Running multiple tests until something hits 0.05 and then presenting only that result. It happens constantly, often unintentionally. The resource doesn't sugarcoat this. Each chapter includes a "what can go wrong" section that points out these traps specifically. For instance, the correlation example explicitly shows how a third confounding variable can create a spurious relationship between two metrics that appear strongly correlated on the surface. Another issue is sample size blindness. People see a statistically significant result and assume it matters practically. A study with ten thousand participants can find a "significant" difference of 0.02 points on a scale. That's statistically real and completely meaningless in any business context. Always check the effect size alongside the p-value. Cohen's d, eta-squared, or odds ratios depending on the test you're running. The examples walk through this, but it's easy to skip that part if you're in a rush.
Limitations You Should Know About
Not every statistical method is covered, and that's intentional. The focus stays on frequentist approaches because that's what most people encounter in standard workplace analysis. Bayesian methods, time series forecasting, and machine learning-based approaches are intentionally absent. If you need those, you'll have to look elsewhere. The datasets used in the examples are synthetic or cleaned public data, which works for learning but doesn't prepare you for messy real-world data. In production, you'll deal with missing values, outliers that shouldn't exist, mismatched columns, and inconsistent labeling. I recommend running through each example with the provided data first to understand the mechanics, then applying the same logic to your own datasets and seeing where things break. That's where the actual learning happens. Another constraint is that the explanations assume basic algebra and a rudimentary understanding of what a variable is. If you've never touched a dataset before, start with the descriptive statistics section and work forward. Jumping straight into regression without understanding correlation will leave you confused more often than not.
If you're looking for something more comprehensive that includes visualization libraries, predictive modeling, or real-time data pipelines, you might be better off with a dedicated data science curriculum instead. This is specifically designed for people who need statistical literacy fast and don't want to wade through academic textbooks to get it.