Why People Keep Digging Up Old Stats Books
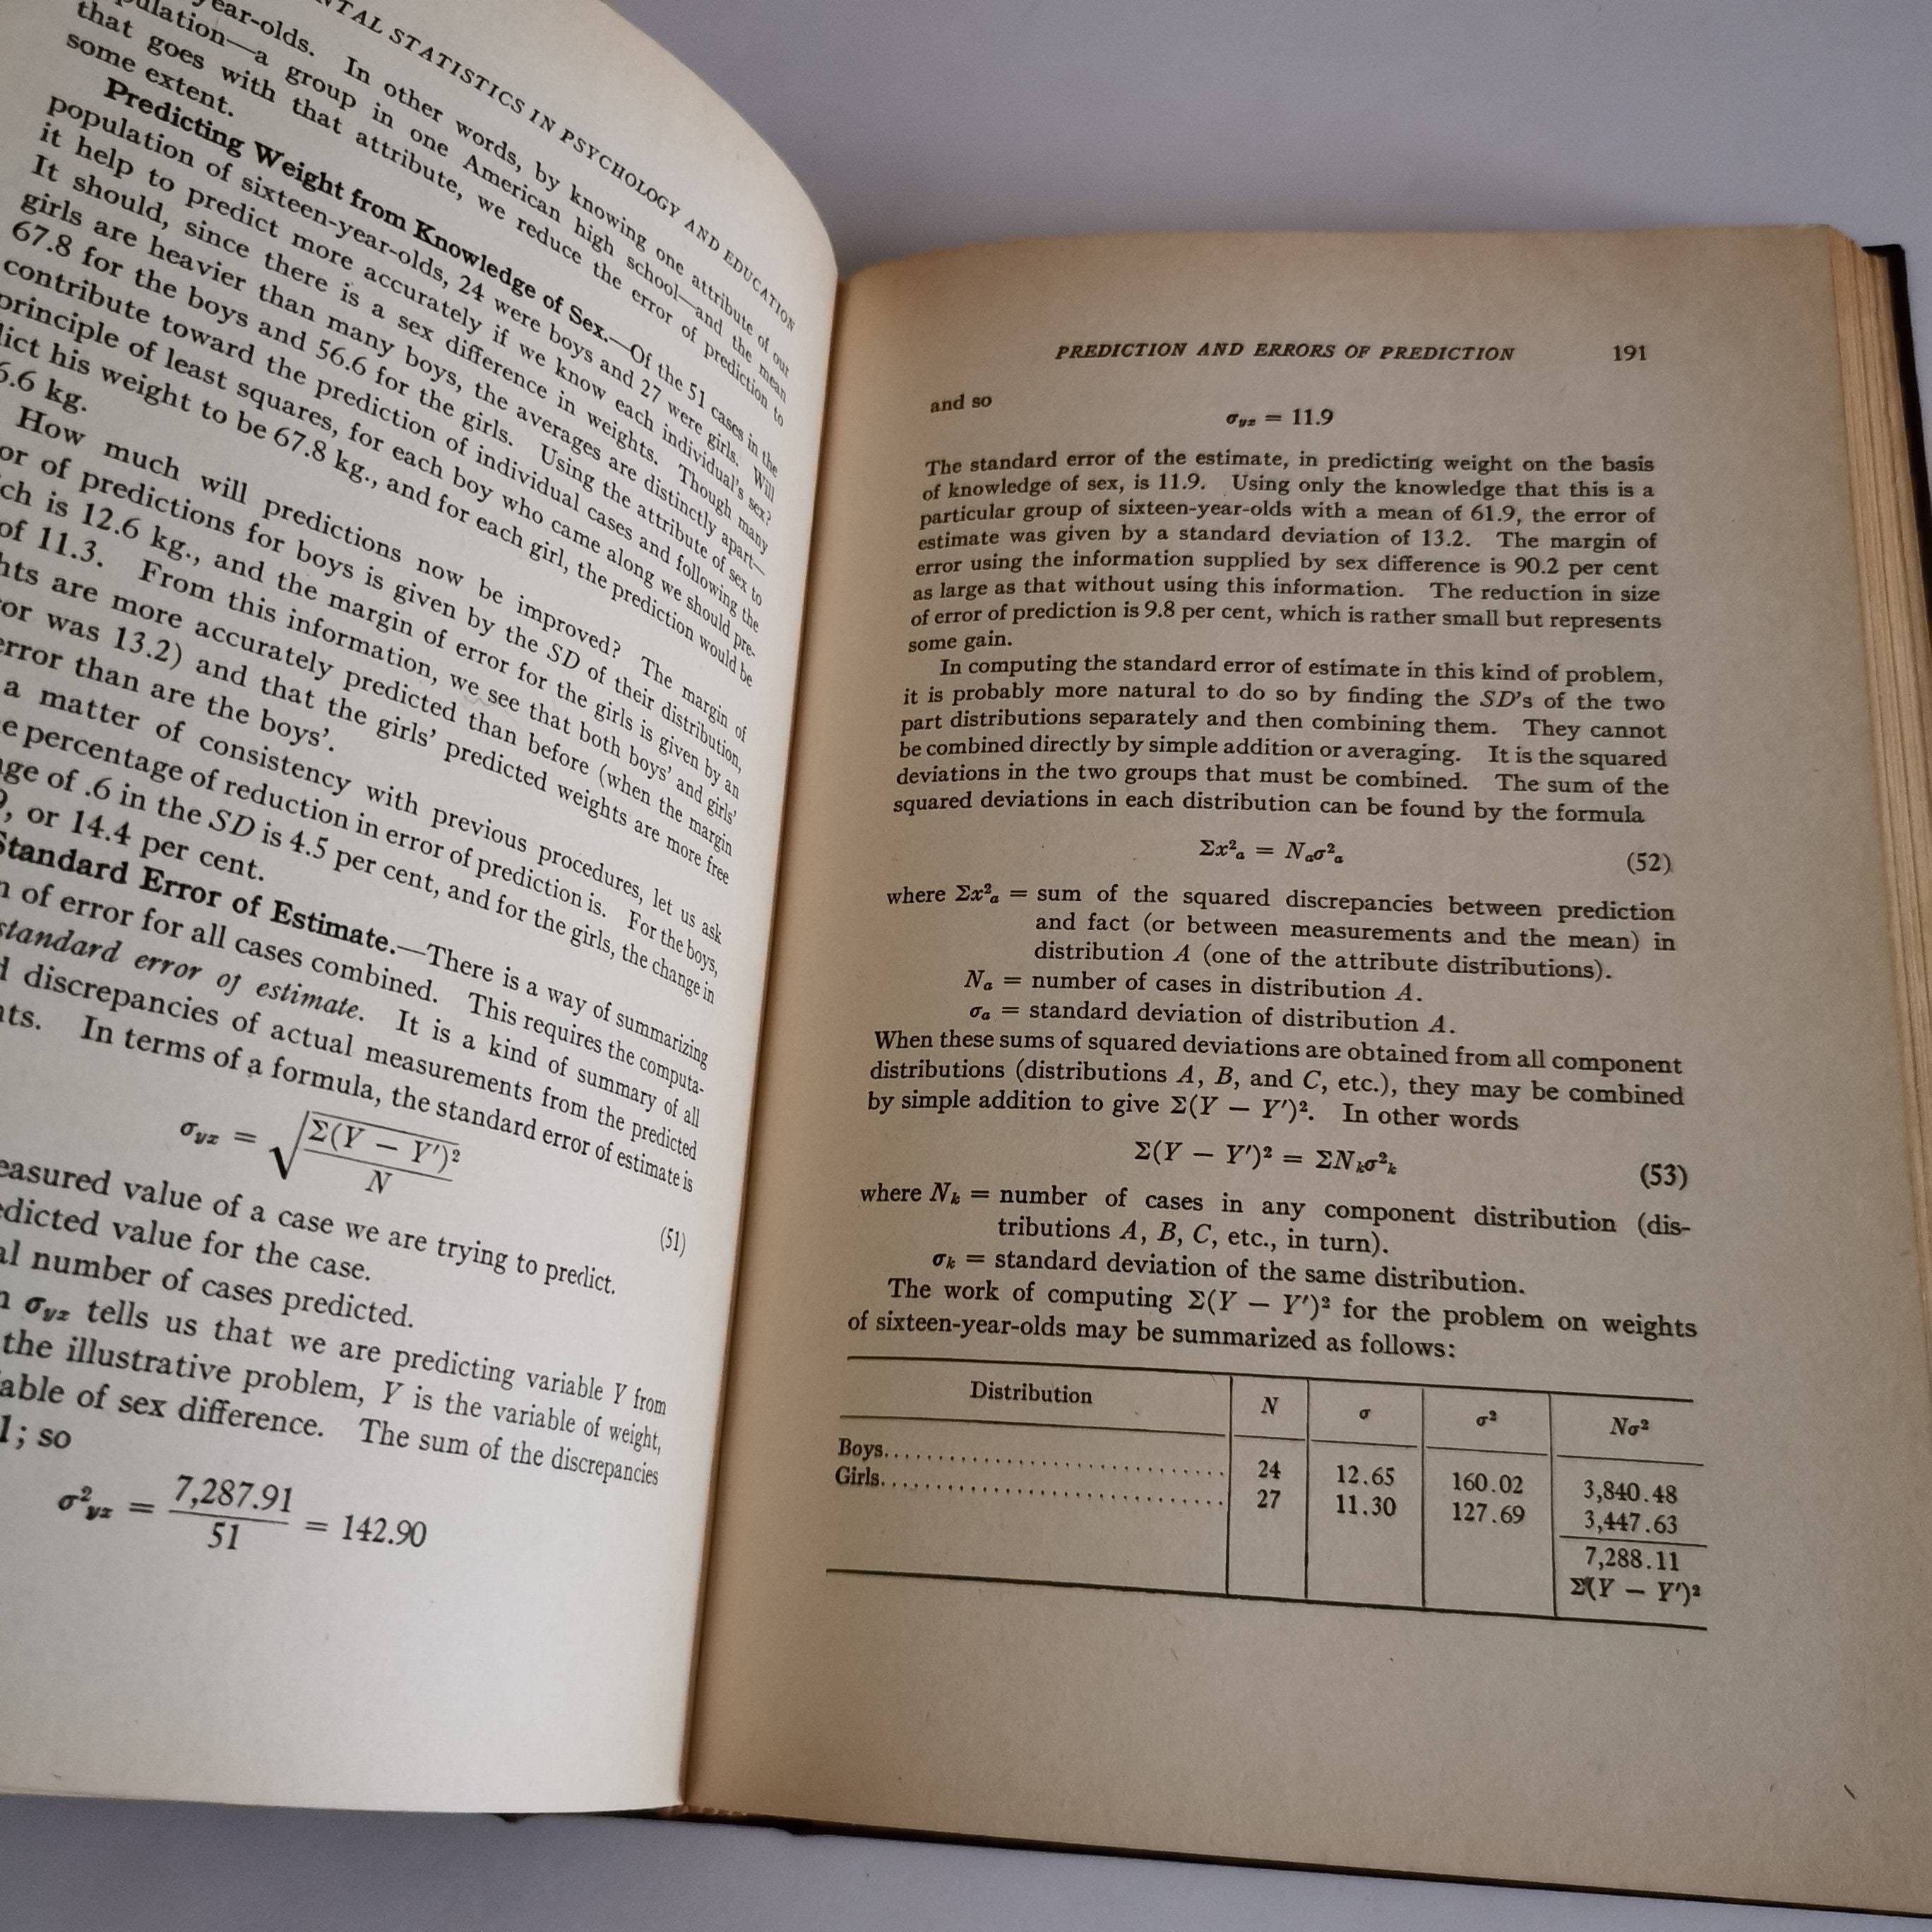
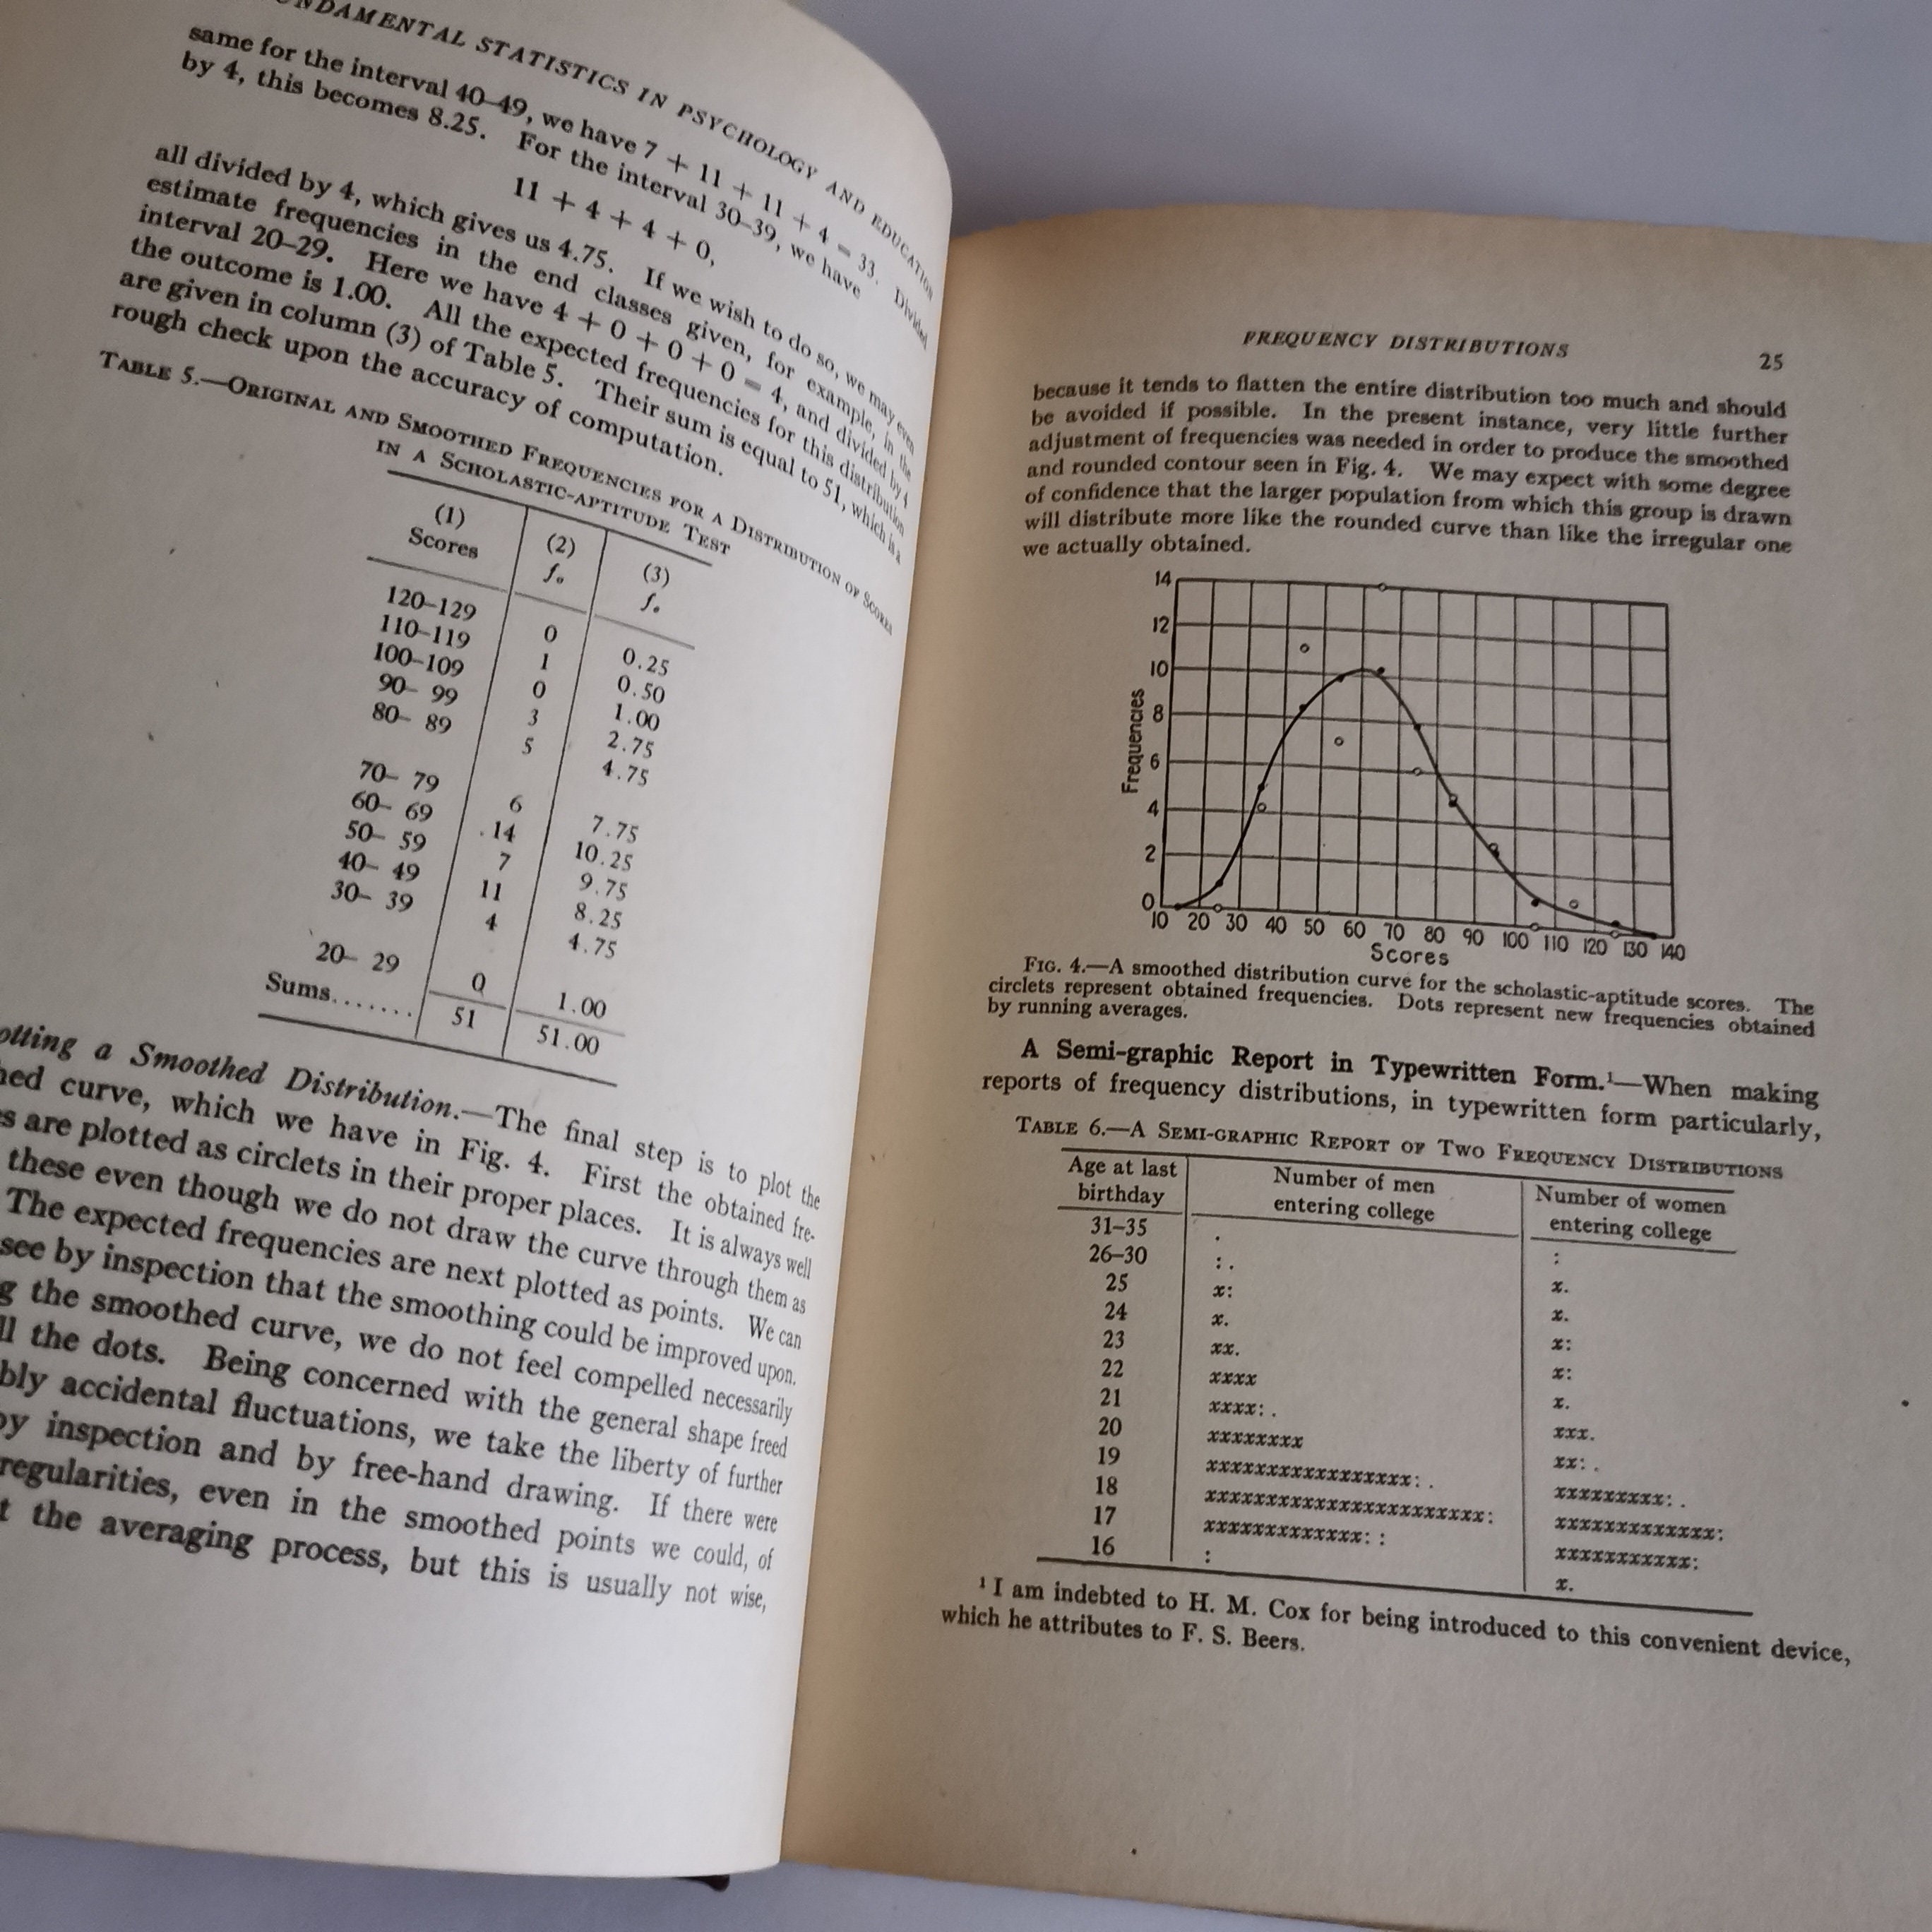
There is a quiet resurgence happening with vintage statistics materials. You see it on Reddit threads, used book websites, and the occasional eBay auction. People are trading in their cluttered 2024 textbooks for battered copies of books published between 1950 and 1980. The reasons are practical more than nostalgic. Older textbooks did not spend 300 pages selling you on the importance of data literacy. They got to the math. They showed you how to calculate a standard deviation by hand. They made you draw frequency polygons on graph paper. The material still works because the math has not changed, and the pedagogical bloat of modern texts often obscures what actually matters.
The Best Statistics For Beginners Vintage Resources Available
Not every old book is worth your time, and some are actively harmful because they teach methods that have been superseded. I have gone through probably two dozen vintage stats books over the years, both for personal reference and when helping people get started. Here is what actually holds up. Fred Szabo's Introductory Statistics is one of the most accessible vintage-style resources you can find. It was originally self-published in the 1990s and has gone through multiple revisions, but the approach is fundamentally vintage: explain the concept, show the calculation, move on. No fluff. You can find PDF versions floating around academic repositories and sometimes on the author's own website. Schaum's Outline of Probability and Statistics by Murray R. Spiegel is the single most useful reference I have ever owned. First published in 1961, it has been in print continuously. The format is pure problem-solving. You get a concise theory section followed by hundreds of worked examples. I used this to teach myself regression analysis before I ever touched software that could do it for me. Knowing how to actually compute a least-squares line by hand changes the way you read every output a computer gives you later.
John W. Tukey's Exploratory Data Analysis is another cornerstone, though it sits further past the beginner range. Still, if you want to understand why modern tools like boxplots exist, you go back to this. The first chapter alone is worth the price of a used copy. Boxplots are not just a pretty visualization, they were designed to catch outliers in a way that mean-and-standard-deviation summaries completely miss, and Tukey explains exactly why that matters. For pure beginner material, Statistics for Psychology by Arlene Finkel is also available in older editions and handles the beginner level with more patience than most technical texts. The 1980s editions are cheap on the used market and cover everything a first-time student actually needs.
Get the Full Details

How to Actually Learn From Vintage Materials
The main problem with vintage statistics resources is that they assume a certain mathematical maturity that most beginners do not have. They skip steps. They say things like "it follows readily that" when the step they skipped actually requires three lines of algebra. You will hit this constantly. My workaround has always been to pair every vintage text with a modern supplementary resource. I keep a copy of Naked Statistics by Charles Wheelan on my desk when I work through older material. It does not teach the math, but it explains the intuition behind why the math exists, and that missing link is usually where vintage texts leave you stranded. You also need to be selective about which topics to learn from old sources. Descriptive statistics, probability basics, hypothesis testing fundamentals, and regression all translate directly from vintage material. But once you get into things like bootstrap methods, Bayesian inference with MCMC sampling, or modern machine-learning-adjacent techniques, the old books are either wrong or simply not covering the territory. Do not waste time looking for vintage coverage of topics that did not exist when the book was written.
I learned this the hard way trying to use a 1978 edition of a statistics textbook to understand logistic regression for a research project. The book covered logistic regression in maybe four pages with a single example and no discussion of model diagnostics or convergence issues. I ended up spending three weeks teaching myself the topic from published papers instead. If you need anything beyond introductory regression, go to a current source.
What These Books Get Wrong That You Should Know About
Vintage statistics textbooks were written for a different world. The software landscape is completely different. Hand calculation was once a required skill because you had no choice. Now it is mostly an exercise in frustration that wastes time you could spend learning to use R or Python properly. The sampling distributions in these books are almost always based on the assumption of normality or large sample sizes. Real data rarely cooperates, and the older texts do not spend nearly enough time on what to do when your data violates their assumptions. I have seen too many beginners follow a vintage textbook's prescribed procedure on data that clearly violates its conditions and then wonder why their results are garbage. Always check your assumptions first, regardless of what decade the book came from. Another thing older books consistently underplay is the difference between correlation and causation. The statistical machinery for detecting correlation is well explained, but the warnings about causal inference are often buried or absent. This is not a flaw in the mathematics, it is a flaw in how the material was framed for students who had no other context for interpreting what they were calculating.
Where to Find These Materials
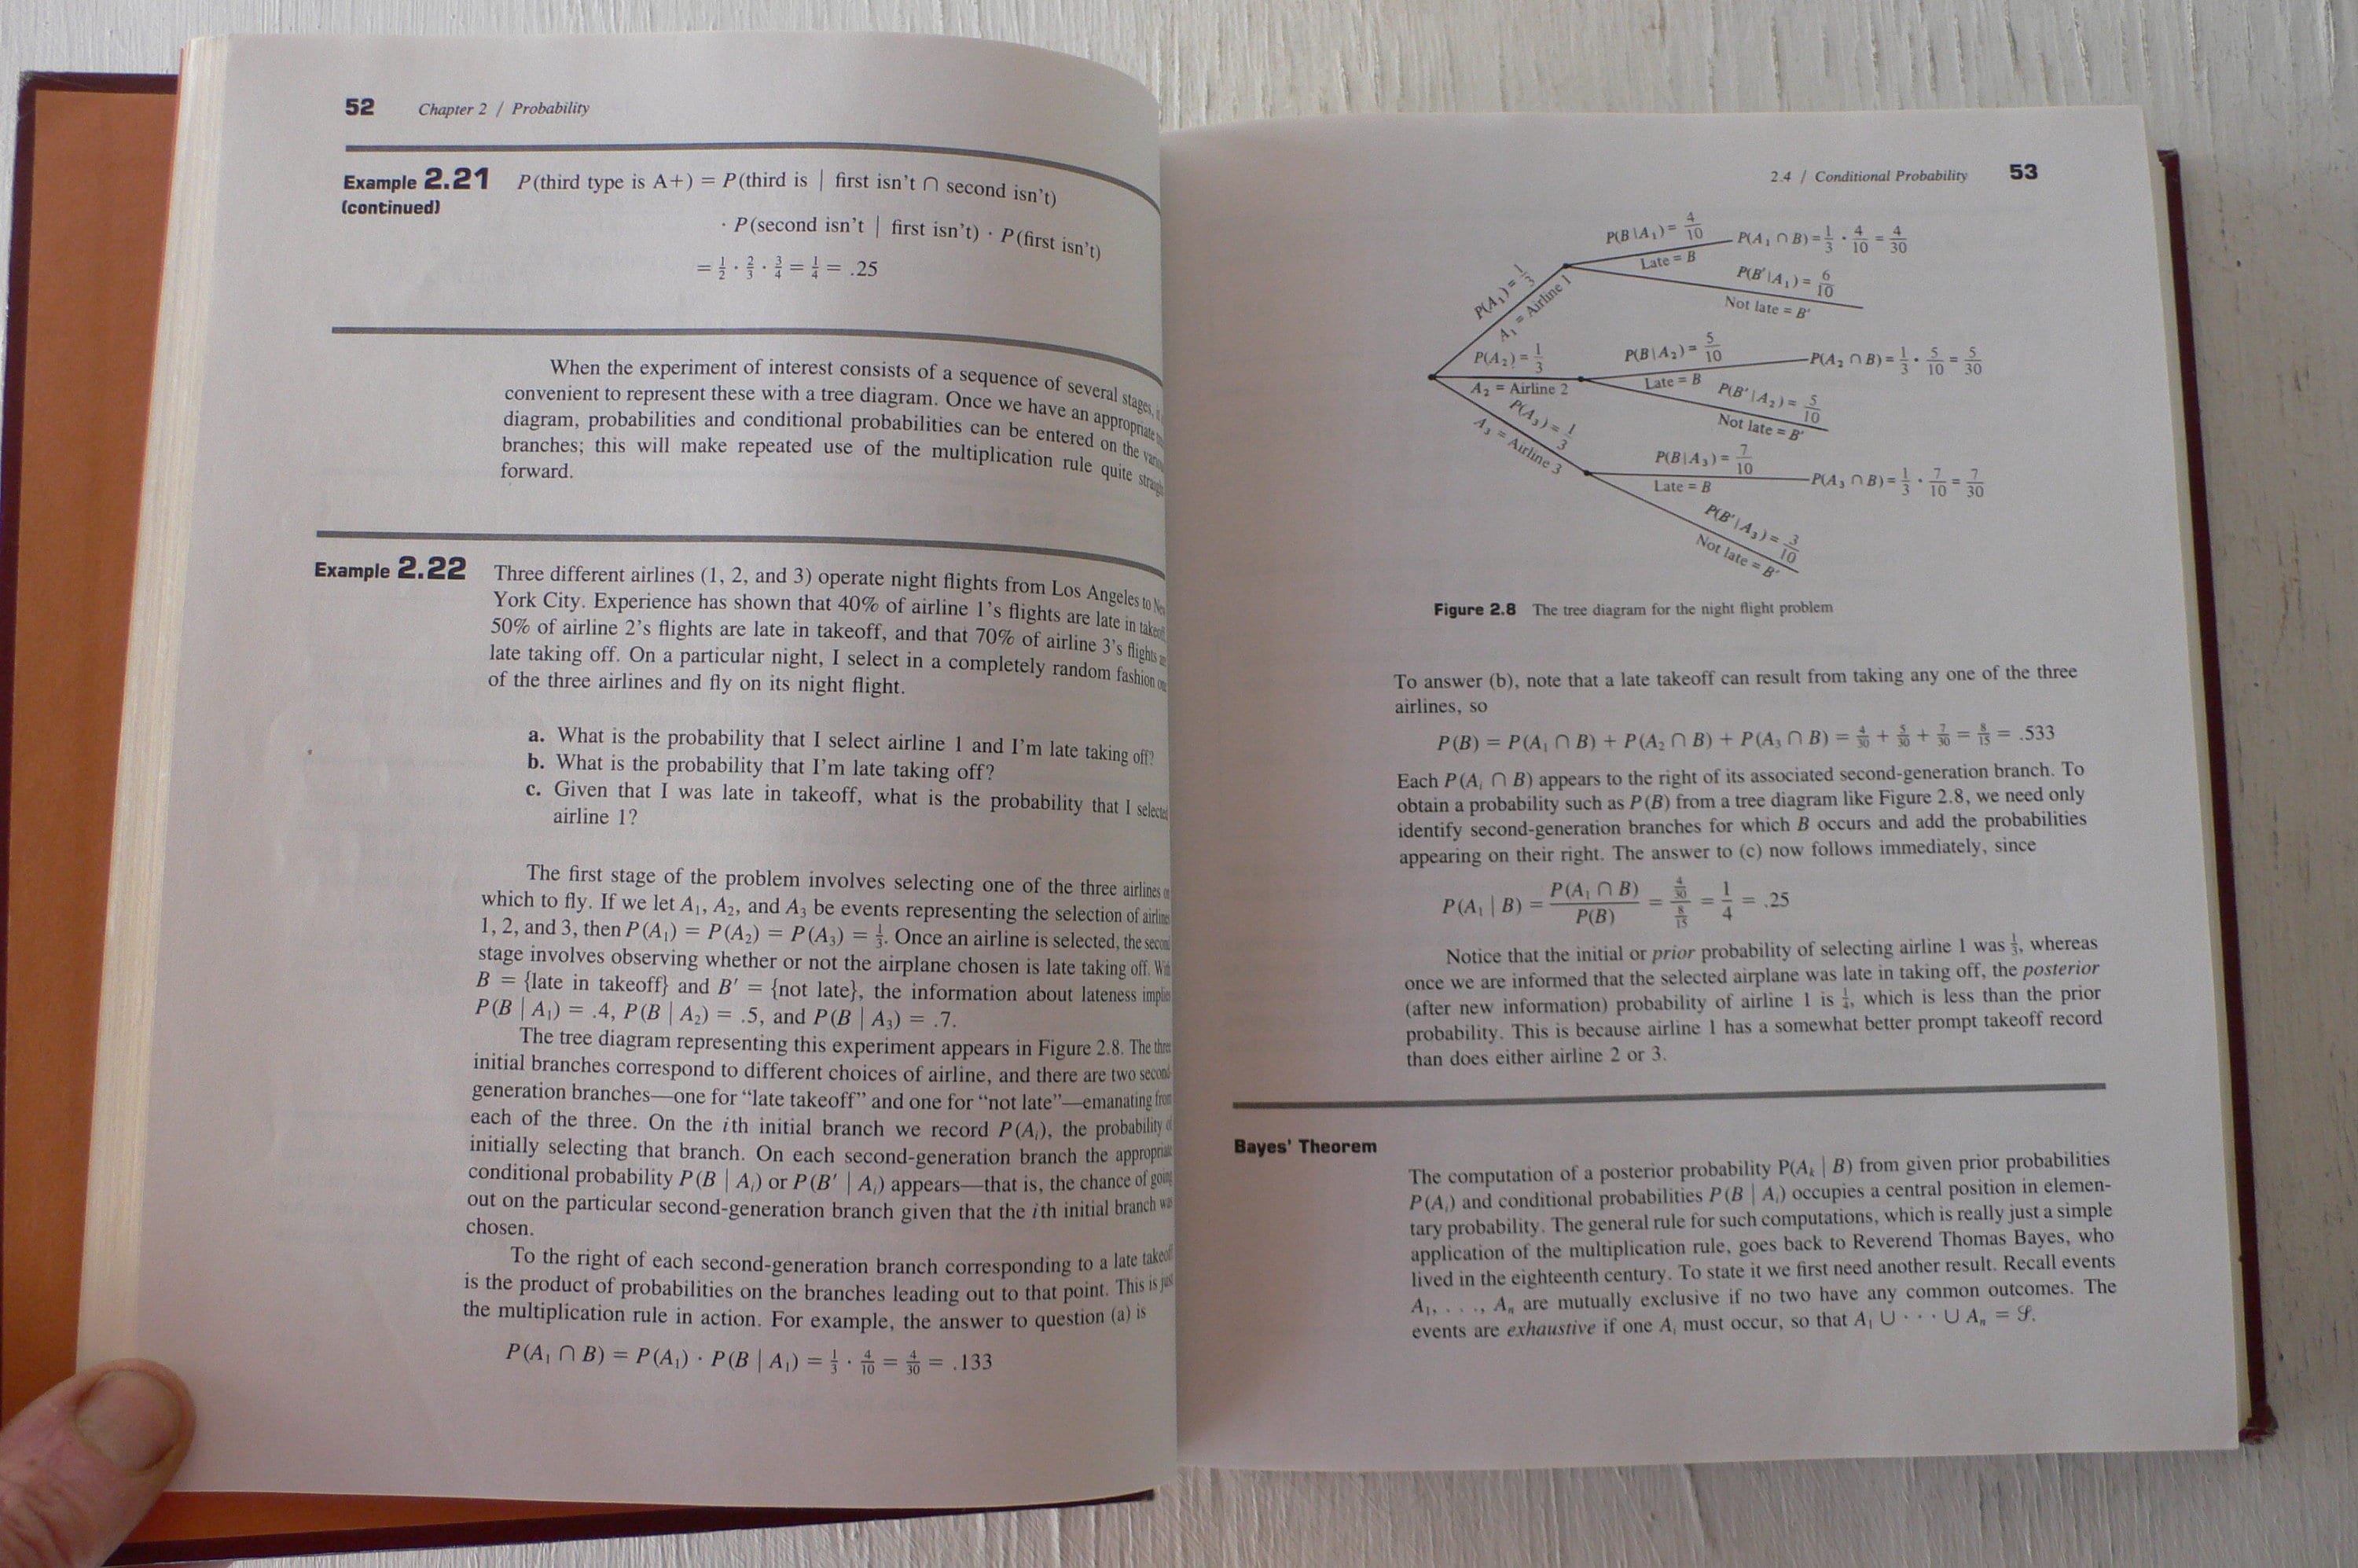
Many vintage statistics textbooks are available through Project Gutenberg and the Internet Archive for free. The Schaum's outlines and several older college texts have been digitized and are searchable. AbeBooks and Amazon Marketplace are reliable for physical copies, and you can usually get a decent used copy of a Schaum's outline for under ten dollars. Z-Library and similar shadow repositories have scanned copies of many academic texts, but I will not link to those directly. The legal route through university library databases and the Internet Archive is sufficient for almost everything you need. If you want something more structured than a random vintage textbook, there are a few modern courses that explicitly teach from a vintage perspective, emphasizing conceptual understanding over software mechanics. They are fewer and farther between, but they exist, and the people who take them usually report higher retention of the material compared to standard Coursera or edX statistics courses.
The short version is that vintage statistics resources are still worth your attention, but they require more scaffolding around them than modern textbooks do. Learn the math by hand from the old books, then learn the software and the modern diagnostic tools from current sources. Mixing the two approaches gives you something most beginners never develop: actual fluency with what the numbers mean rather than just knowing which button to press.