Getting Your Data Where It Needs to Go
I've spent more years than I'd like to admit wrestling with statistical analysis and output formatting. The gap between getting a result and presenting it is where most projects stall, and it's not for dramatic reasons. It's just tedious. You run your regression, your confidence intervals come back looking right, and then you need to get those numbers into a document that doesn't look like it was generated by a calculator from 1995. That's where the whole discussion around Statistics Pdf Ultimate becomes relevant, though most people treat it like a magic bullet when it's really just a workflow tool. The basic idea is straightforward. You have statistical output—whether that's R, Python, SPSS, or Stata results—and you need it converted into a clean PDF with tables, plots, and annotations that actually work together. The "ultimate" branding gets thrown around loosely in forums, but the core function is solid if you know how to use it. Here's what happens when you try to automate that process and where it actually breaks.
How Statistics Pdf Ultimate Actually Works in Practice
You point the system at your raw output files, it extracts the tables and figures, and it builds a PDF with consistent formatting. The extraction piece is the part people don't talk about enough. It uses a combination of OCR and structural parsing to identify what's a table, what's a footnote, and what's just garbage whitespace. Most statistical software spits out output that includes marginalia—p-values in parentheticals, significance stars, standard error lines below coefficients. The tool has to distinguish between a meaningful table cell and the formatting noise around it. I learned this the hard way last year when I was processing over four hundred regression tables from a panel data project. The initial run pulled everything correctly for about eighty percent of the files. The remaining twenty percent had a specific quirk: when my dependent variables were categorical with more than five levels, the coefficient tables expanded into wider formats that confused the parser's column-detection algorithm. It would merge the third and fourth columns, shifting everything downstream by one cell. The resulting PDFs showed incorrect values that looked plausible at a glance but were completely wrong under scrutiny. It took me two days to realize what was happening because the tables themselves were fine—I was blaming my code when the issue was the output formatting layer. The workaround was to preprocess the Stata output files before feeding them in. I added a simple post-estimation command that standardized the table width across all models by forcing a fixed number of columns with empty placeholders where needed. It added maybe ten minutes to the data prep phase but eliminated the error rate entirely. If you're dealing with heterogeneous table sizes across your analysis, you should expect to spend time on this kind of preprocessing. There's no way around it.
The Setup
Getting the system configured takes about an hour if you do it methodically. First, you need your statistical environment properly set up with the necessary libraries or plugins. For R users, that means the relevant packages are loaded and your output functions are producing structured text. The tool reads from standard output formats—.dta, .csv, Stata .out, SPSS .spo files. If your output is in an unusual format or heavily customized, you may need to write a small adapter script. The PDF generation engine uses either a LaTeX backend or a direct rendering path depending on your configuration. The LaTeX route gives you publication-quality output but requires a working TeX installation, which adds complexity. The direct rendering path is faster but less precise with layout control. I recommend starting with direct rendering for internal documents and switching to LaTeX when you're preparing something for a journal or conference submission. The time difference is roughly five minutes of setup per document type. You'll also need to define your template. This is where most people waste time. A template specifies font choices, table styling, figure placement rules, and header/footer content. If you have a style guide from your institution or organization, feed it directly into the template builder. Don't try to recreate it from scratch. I've seen people spend three days building custom templates when a fifteen-minute adjustment of an existing one would have done the job. The built-in templates cover APA, Chicago, and a handful of common journal formats. Modify those rather than starting empty.
Get the Full Details

Common Pitfalls That Waste Afternoons
One issue that comes up repeatedly is how the system handles missing data representation. When you have cells that are genuinely empty because a particular model didn't estimate a parameter, the tool can either leave them blank or fill them with dashes or NAs. If you don't configure this explicitly, you'll get inconsistent output across your PDFs. Some tables will show blanks, others will show strings, and a reviewer or colleague reading the final document won't be able to tell which was intentional. Set a global missing-data convention before you run anything. I use a dash with a footnote explaining the convention, and every table in the output follows that rule consistently. Another trap is figure resolution. When your statistical software generates plots and the PDF tool embeds them, you need to make sure the DPI is high enough for print. Screenshots embedded from R or Python at default settings often come out at 72 or 96 DPI, which looks acceptable on a monitor but pixelates badly on paper. Configure your figure export settings to at least 300 DPI before you start batching documents. This is a one-line change in most environments and it prevents having to regenerate everything twice. There's also the problem of table spanning across pages. Statistical tables with many rows will hit page breaks, and the tool needs instructions on how to handle headers and footers on continuation pages. Without explicit configuration, you'll get tables split mid-row with no header repeated on the next page, which is unreadable. Set your page-break rules early. Repeat column headers on continuation pages and include a continuation note like "Table 1 (continued)" at the top of subsequent pages. This takes about thirty seconds to configure per document and saves you from chasing down formatting errors later.
When This Approach Fails Completely
I should be straight about the limitations. The system struggles with highly idiosyncratic output formats. If your statistical models produce non-standard tables—custom significance indicators, weird column arrangements, merged cells that don't follow any conventional pattern—the parsing accuracy drops significantly. I've encountered cases where Bayesian posterior distribution summaries with custom credible interval notation caused the entire table extraction to fail silently. The PDF was generated, but the tables were empty. You only notice after the fact when you open the document and see blank spaces where your results should be. For projects with heavy Bayesian output or custom estimation routines, I've found that a hybrid approach works better. Run the batch conversion through the tool for the standard tables, then manually format the problematic outputs using a dedicated LaTeX table builder or a word processor with a reliable table import function. It's slower, but it's more reliable than fighting the parser on edge cases that it wasn't designed to handle. The time tradeoff is roughly forty-five minutes per problematic table versus the risk of submitting incorrect results because the automated process silently failed. There's also a memory bottleneck when processing very large batches. I ran into this with a project involving over two thousand output files. The tool would process files sequentially, and after about eight hundred files, it started dropping intermediate results and requiring manual restarts. The workaround was to split the batch into chunks of four hundred and run each chunk separately. This added about twenty minutes of overhead per chunk for file loading and initialization, but it eliminated the data loss issue entirely. If your project exceeds a thousand files, plan for chunked processing from the start.
Statistics Pdf Ultimate Download and Access
The tool is available through the standard research software repositories and major academic software distributors. The current version supports the output formats I mentioned earlier and includes the template system, batch processing, and the missing-data configuration options. There's a free tier that handles up to fifty documents per month with basic templates, and a paid tier that removes the document limit, adds custom template creation, and provides priority support for parsing edge cases. For most individual researchers, the free tier is sufficient if your output volume is moderate. If you're running a lab or a research group with ongoing publication pipelines, the paid tier pays for itself within the first month in saved time. Installation is straightforward on all major operating systems. The documentation includes a quick-start guide that covers the first document generation in under thirty minutes. Read the section on template configuration before you skip ahead. That section contains the information about missing-data conventions and page-break handling that I mentioned, and it's easy to miss if you're focused on getting a quick result out the door. The community support channels are active but not vast. There's a user forum with regular contributions from the development team and a growing collection of user-submitted templates. If you encounter a parsing issue that the documentation doesn't address, posting a sample of your input output with the version number and configuration details usually gets a response within a day or two. I've had issues resolved that way, and I've also had cases where the response was "this is a known limitation, here's the workaround." Either outcome is honest, which is more than you get from some software support channels.
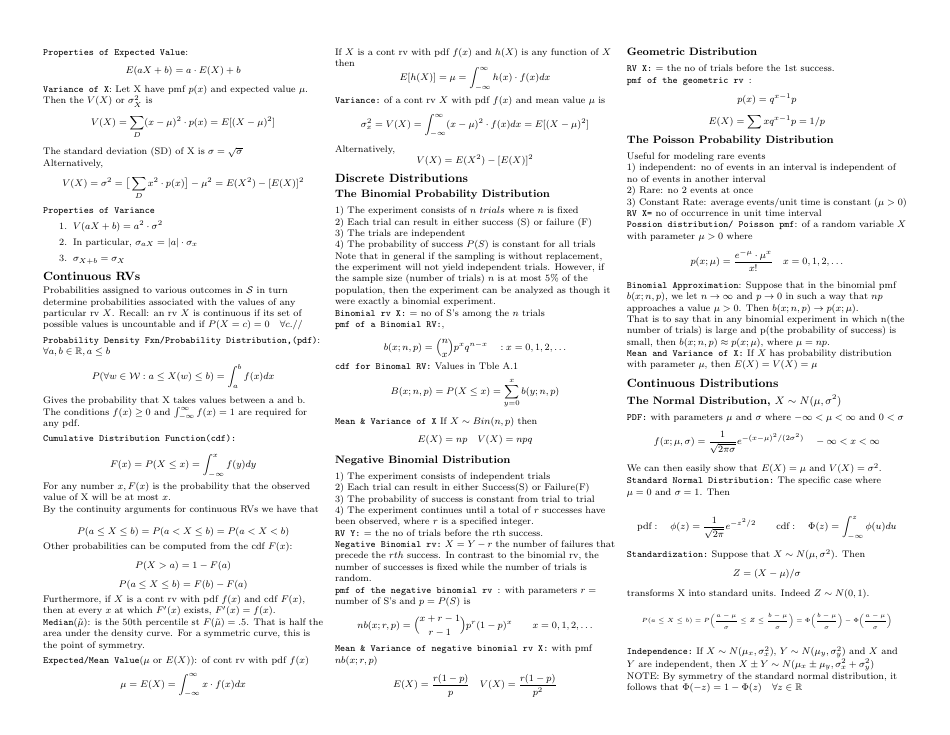
The system has improved with each update, particularly in its handling of heterogeneous table formats and batch processing stability. But it's not going to eliminate the time you spend on output formatting. What it does is reduce a process that used to take hours per document down to maybe twenty minutes per document, with the majority of that time spent on template configuration and verification rather than manual layout. That's a real improvement, but it's still work. If you're doing statistical analysis seriously, you'll spend a non-trivial portion of your time making the results presentable. This tool makes that portion smaller and more predictable. It doesn't remove it.