Why most technical documentation fails before it ships
I've spent years going through API docs, internal runbooks, and business process guides that looked fine on paper but collapsed the moment a real user tried them. The problem isn't usually bad writing. It's a structural mismatch between what the writer knows and what the reader actually needs to do. I once spent three weeks debugging an integration failure that turned out to be caused by a single ambiguous word in a parameter description - the documentation said "optional" but the API silently dropped missing fields instead of throwing an error. That's not a grammar issue. That's a strategy issue. The most effective approach I've found starts with audience inversion. Most writers organize content around their own mental model of how the system works. Users don't share that model. Instead of starting with architecture or feature lists, you map the document to the tasks your audience is actively trying to complete. A developer integrating your API doesn't care about the history of the OAuth flow. They care about getting from point A to point B without calling support at 2 AM. This means every section should answer one question: what does the reader need to do right now? Not what do they need to know. Do, not know. I restructured a 40-page onboarding guide last year using this principle. We cut it to 12 pages and dropped support tickets by about 60%. The content didn't change much. The organization did.
Business writing follows a different but related logic. When you're writing for stakeholders, the hierarchy flips again. Decision makers need the conclusion first, evidence second. Engineers reading your same document need the reverse. This is why dual-path documentation structures work so well. You give leadership a one-page summary with outcomes and risks upfront, and you bury the technical detail in linked sections for anyone who wants it. I've seen teams try to force everything into a single document format and it ends up satisfying nobody.
The practical framework
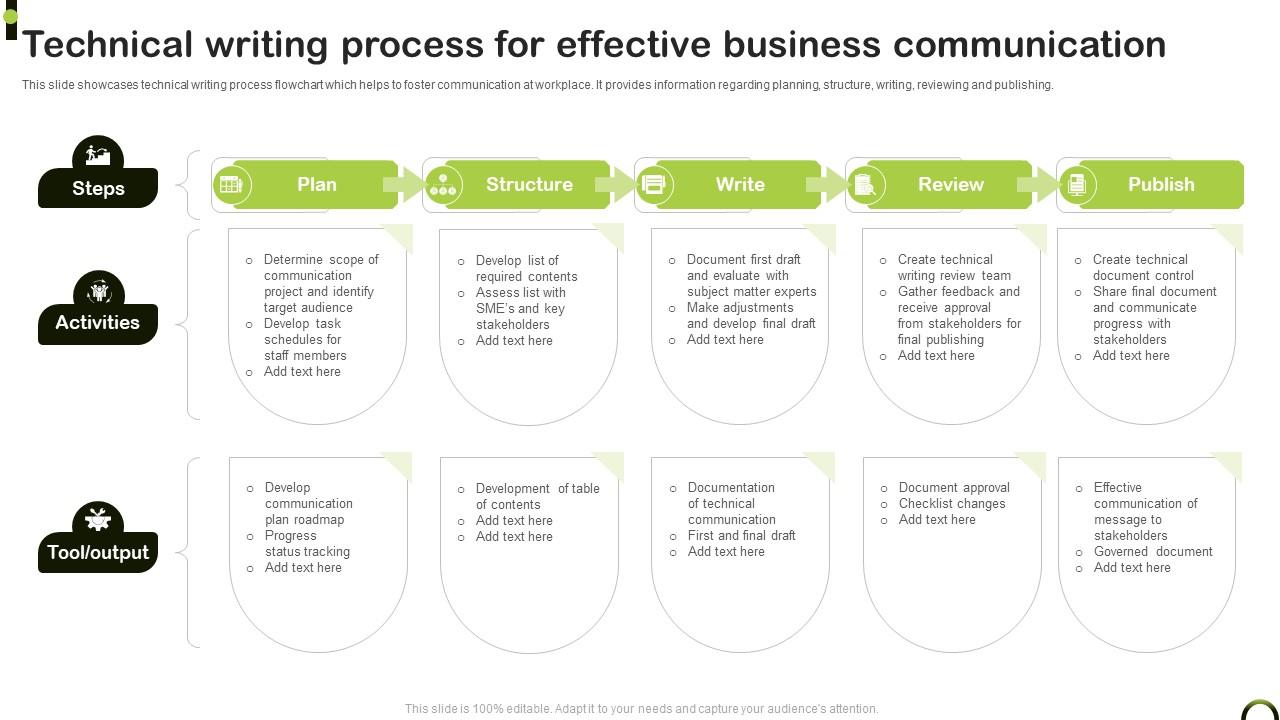
Here's the actual workflow I use when starting any new piece of technical or business documentation. It's not glamorous. It takes longer than you'd expect at first, but it saves time on revisions later. First, I define the unit of action. Every paragraph and section should map to a single atomic task or decision. If I'm writing about deployment, I don't combine environment setup, credential configuration, and verification into one section. Three separate sections, each ending with a clear success criterion. This seems obvious until you've read five hundred docs that don't follow it. Second, I write the warning first. Not at the end as a footnote. At the beginning of any section where someone could easily make a costly mistake. I learned this the hard way when a client accidentally ran a destructive database migration on a production instance because the rollback steps were described after the forward steps, and nobody read past the bold header. Moving the warning to the top cut our incident reports on that procedure nearly in half.
Get the Full Details

Third, I test every example myself. Not by reading it. By executing it. If a code snippet requires a prerequisite step that isn't stated, the example is broken. If a business process description assumes a tool the reader doesn't have, it's useless. I treat documentation like a recipe. If you can't make the dish by following the instructions, the recipe is wrong, not the reader.
Common structural mistakes
Over-organizing is more common than under-organizing. I've seen documentation with seven nested heading levels for content that would work fine as a flat list with two headings. Each extra layer adds cognitive load and makes scanning harder. Keep hierarchy shallow unless the content genuinely demands depth. A three-level maximum works for almost everything. Another issue I see constantly is the assumption of shared context. Writers often skip explaining terms that seem obvious to them but are completely foreign to the reader. This includes acronyms, internal project names, and domain-specific jargon. I keep a running glossary for each product I document, and I flag every term that isn't in it the first time it appears. It adds maybe ten minutes to the writing process but eliminates an entire category of support questions. Version drift is the silent killer of technical documentation. Every software update, API change, or process modification makes existing docs slightly wrong. The worst docs aren't the ones that are clearly bad. They're the ones that look correct but contain one outdated detail that causes five hours of wasted debugging. I track documentation freshness alongside code changes. If a pull request touches a documented feature, that doc gets a review pass. It's a small habit that prevents the biggest class of documentation failures.
Tools and formats that actually help
For pure technical writing, I stick with plain text source files in version control. Markdown, AsciiDoc, or reStructuredText depending on the project. The format matters less than the fact that docs live next to the code they describe. When documentation and code are in separate silos, they diverge. I've managed projects where the latest API documentation was six months old because the team treated docs as a separate deliverable instead of part of the development cycle. For business writing, structured documents in a shared knowledge base with change tracking work better than free-form documents. The key requirement is that someone has explicit ownership of each document. Not "the team." A specific person. Without that, documents get stale because nobody feels responsible for updating them. I instituted a simple rule: if you edit a document, you own it until you hand it off formally. That reduced our stale-doc problem significantly. Diagramming tools matter more than people expect. A well-placed flowchart can replace three paragraphs of text, and it's often more accurate because it forces you to commit to a specific logic path. I use Mermaid for inline diagrams in technical docs and draw.io for standalone process maps. Both integrate cleanly with version control and render directly in most modern documentation platforms.

When this approach breaks down
Not everything benefits from the task-oriented structure I described. Explainer content, strategic overviews, and training materials sometimes need a more narrative approach. For those cases, the audience inversion still applies, but the organization shifts from task sequence to concept building. The difference matters. Putting a conceptual overview inside a task-based document creates friction. People looking for quick answers can't find them. People looking for understanding get interrupted by procedural steps they don't need yet. Another limitation: this style requires upfront planning. If you're writing documentation reactively, under deadline pressure, you'll likely default to describing the system as you understand it rather than organizing it around user tasks. That's fine for quick drafts. It just means the next round of edits will need to reorganize from scratch. Building the task-first structure from the start saves that iteration. Small teams with limited resources might find the rigor I describe overhead-heavy. If you have two people writing docs for an internal tool used by fifteen engineers, the full audience-inversion framework is probably overkill. A simpler checklist works: is it accurate, is it findable, and does it help someone complete the task? Those three criteria catch most problems without requiring elaborate processes.