How To Build A Table Of Contents That Actually Works
A table of contents is just a list of headings with page numbers or links. Most people overcomplicate this. The real issue isn't creating one; it's creating one that stays accurate when the document changes. I've seen developers spend hours on TOCs that break after a single edit pass because they weren't set up with the right automation in mind. Let me walk through how this works in practice, starting with the parts people usually mess up.
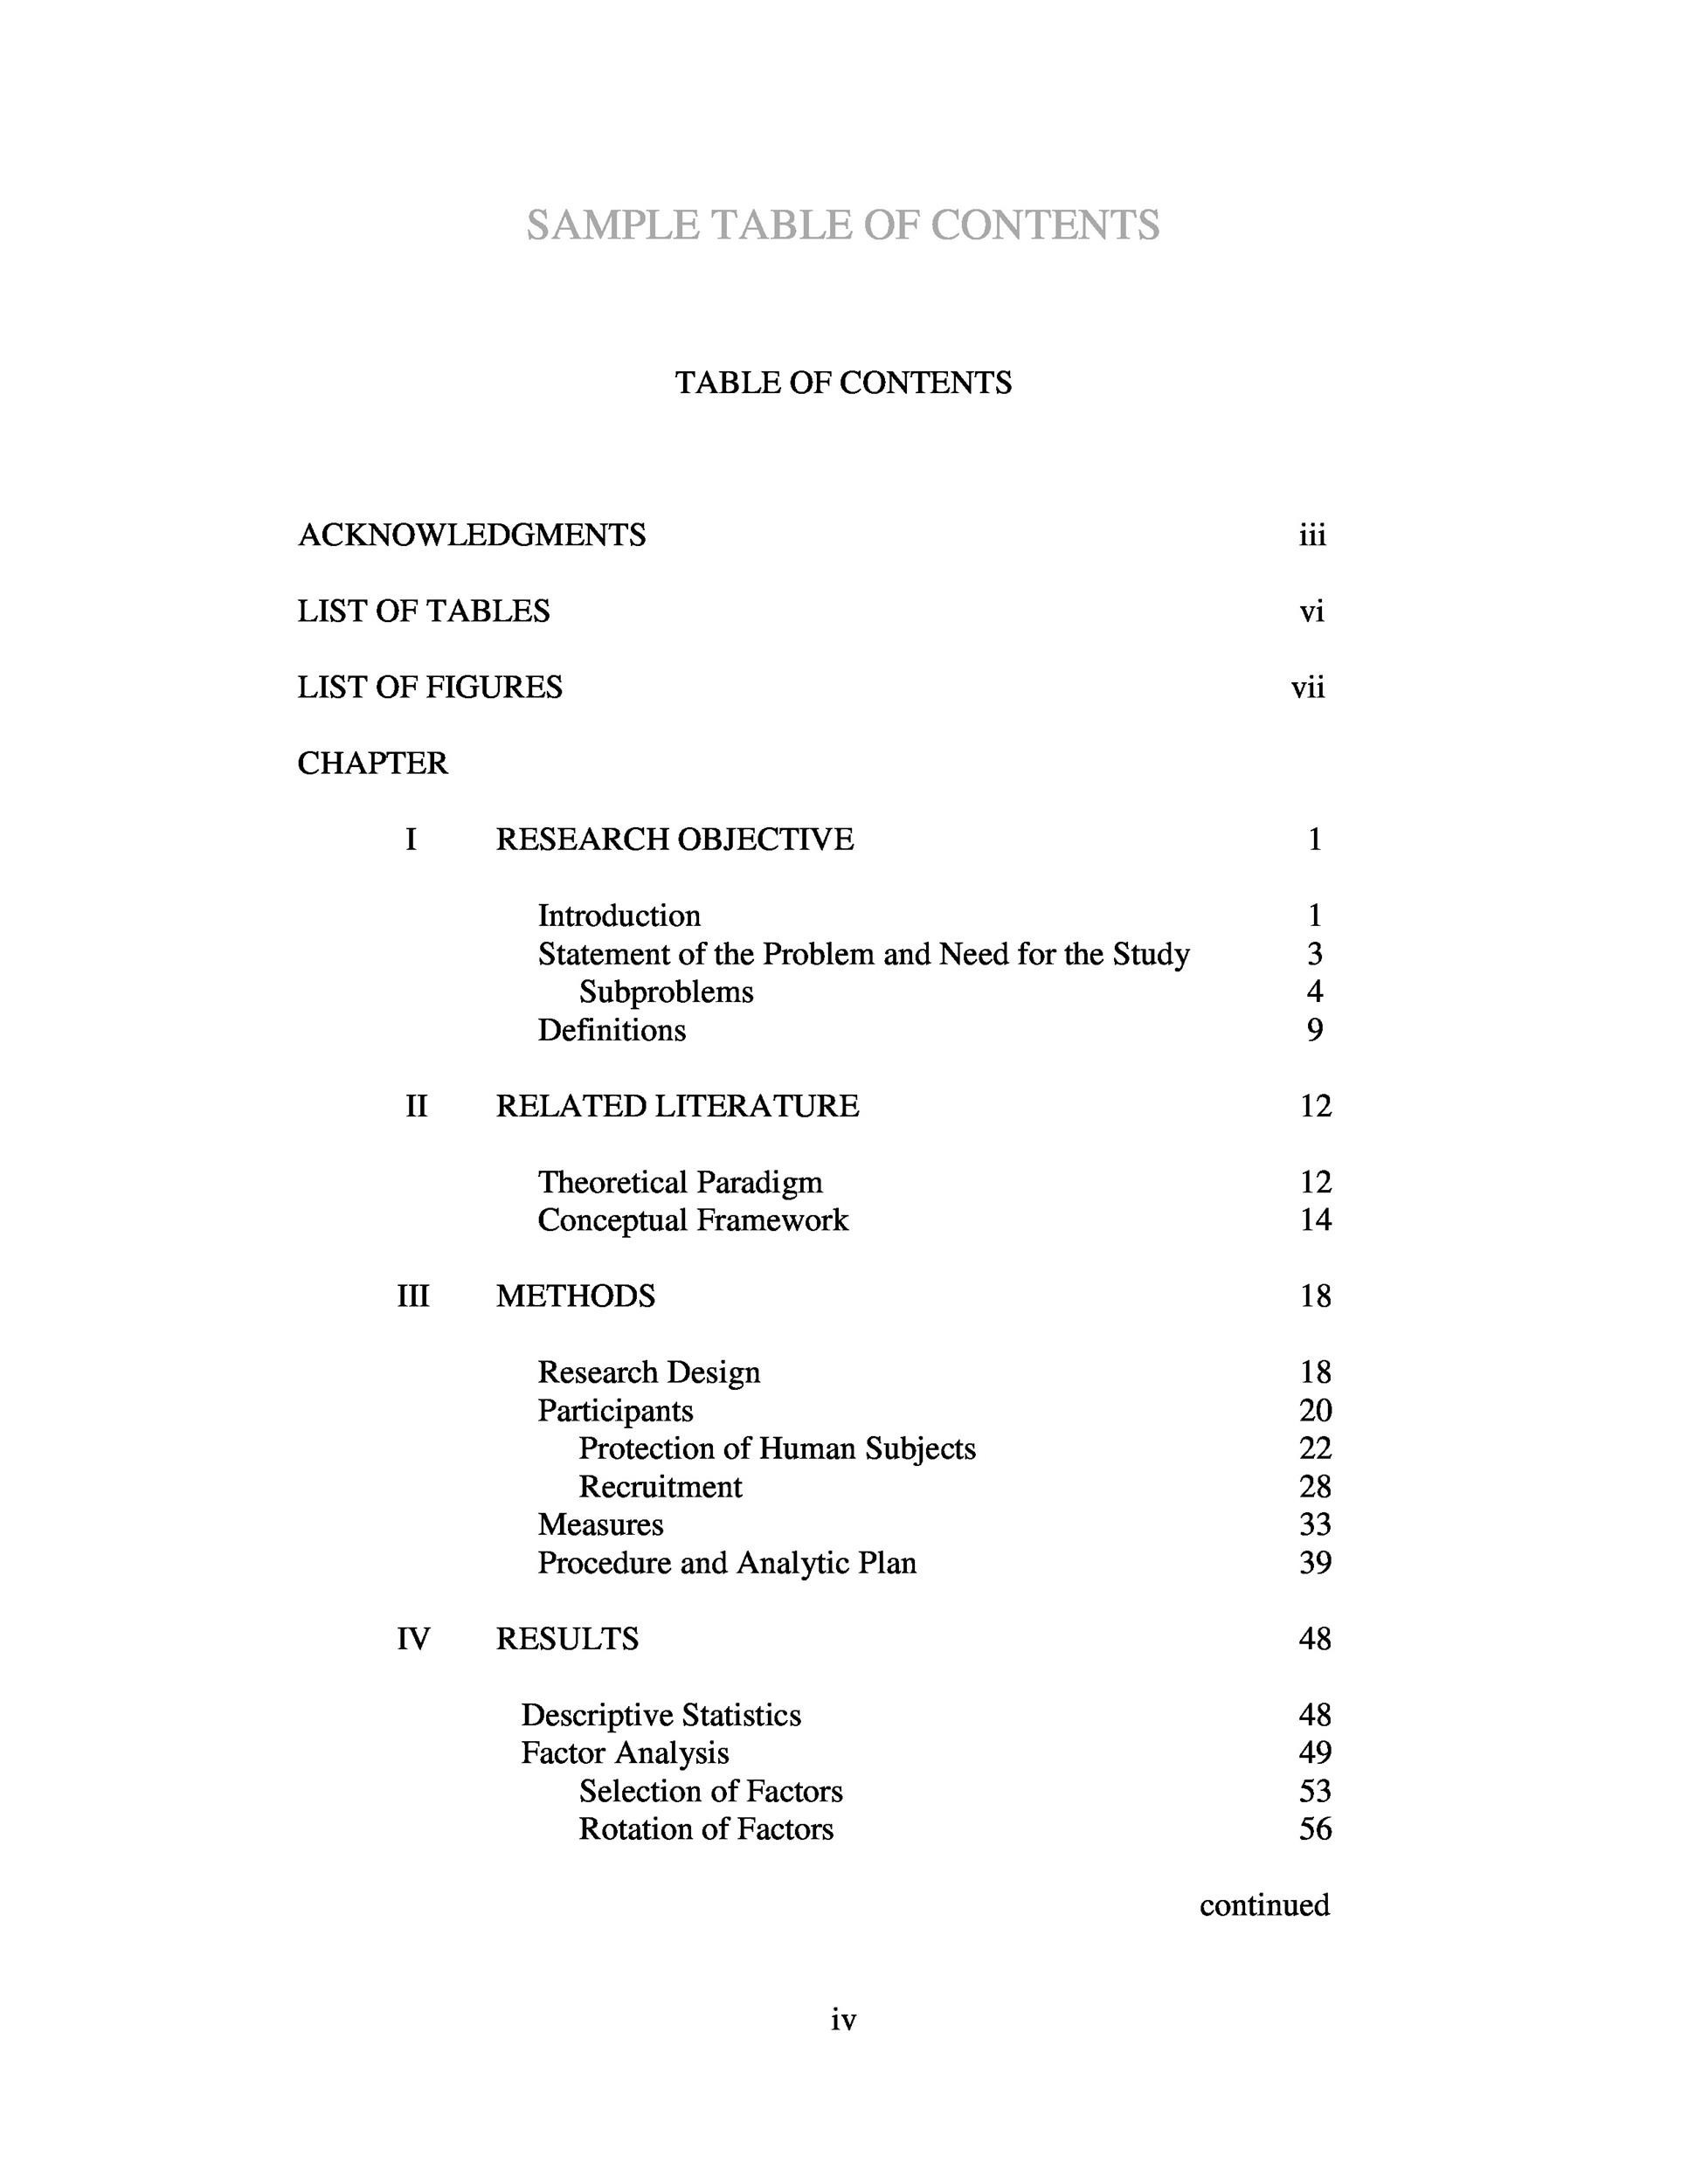
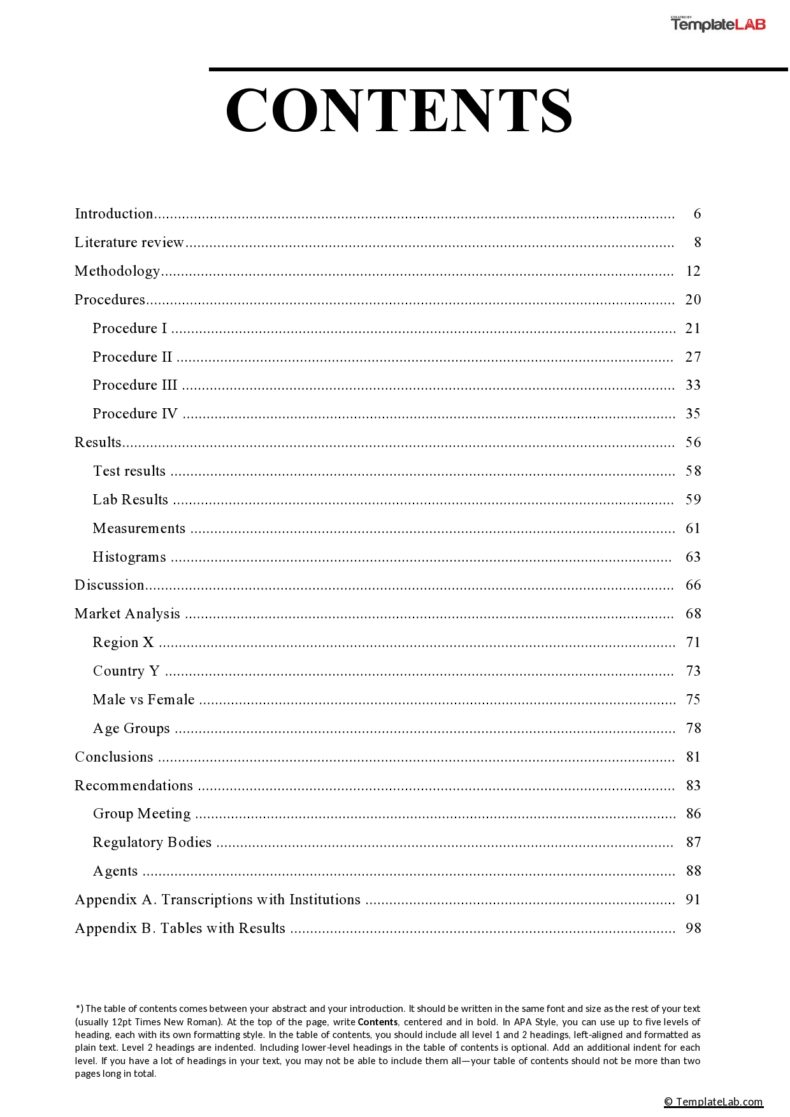
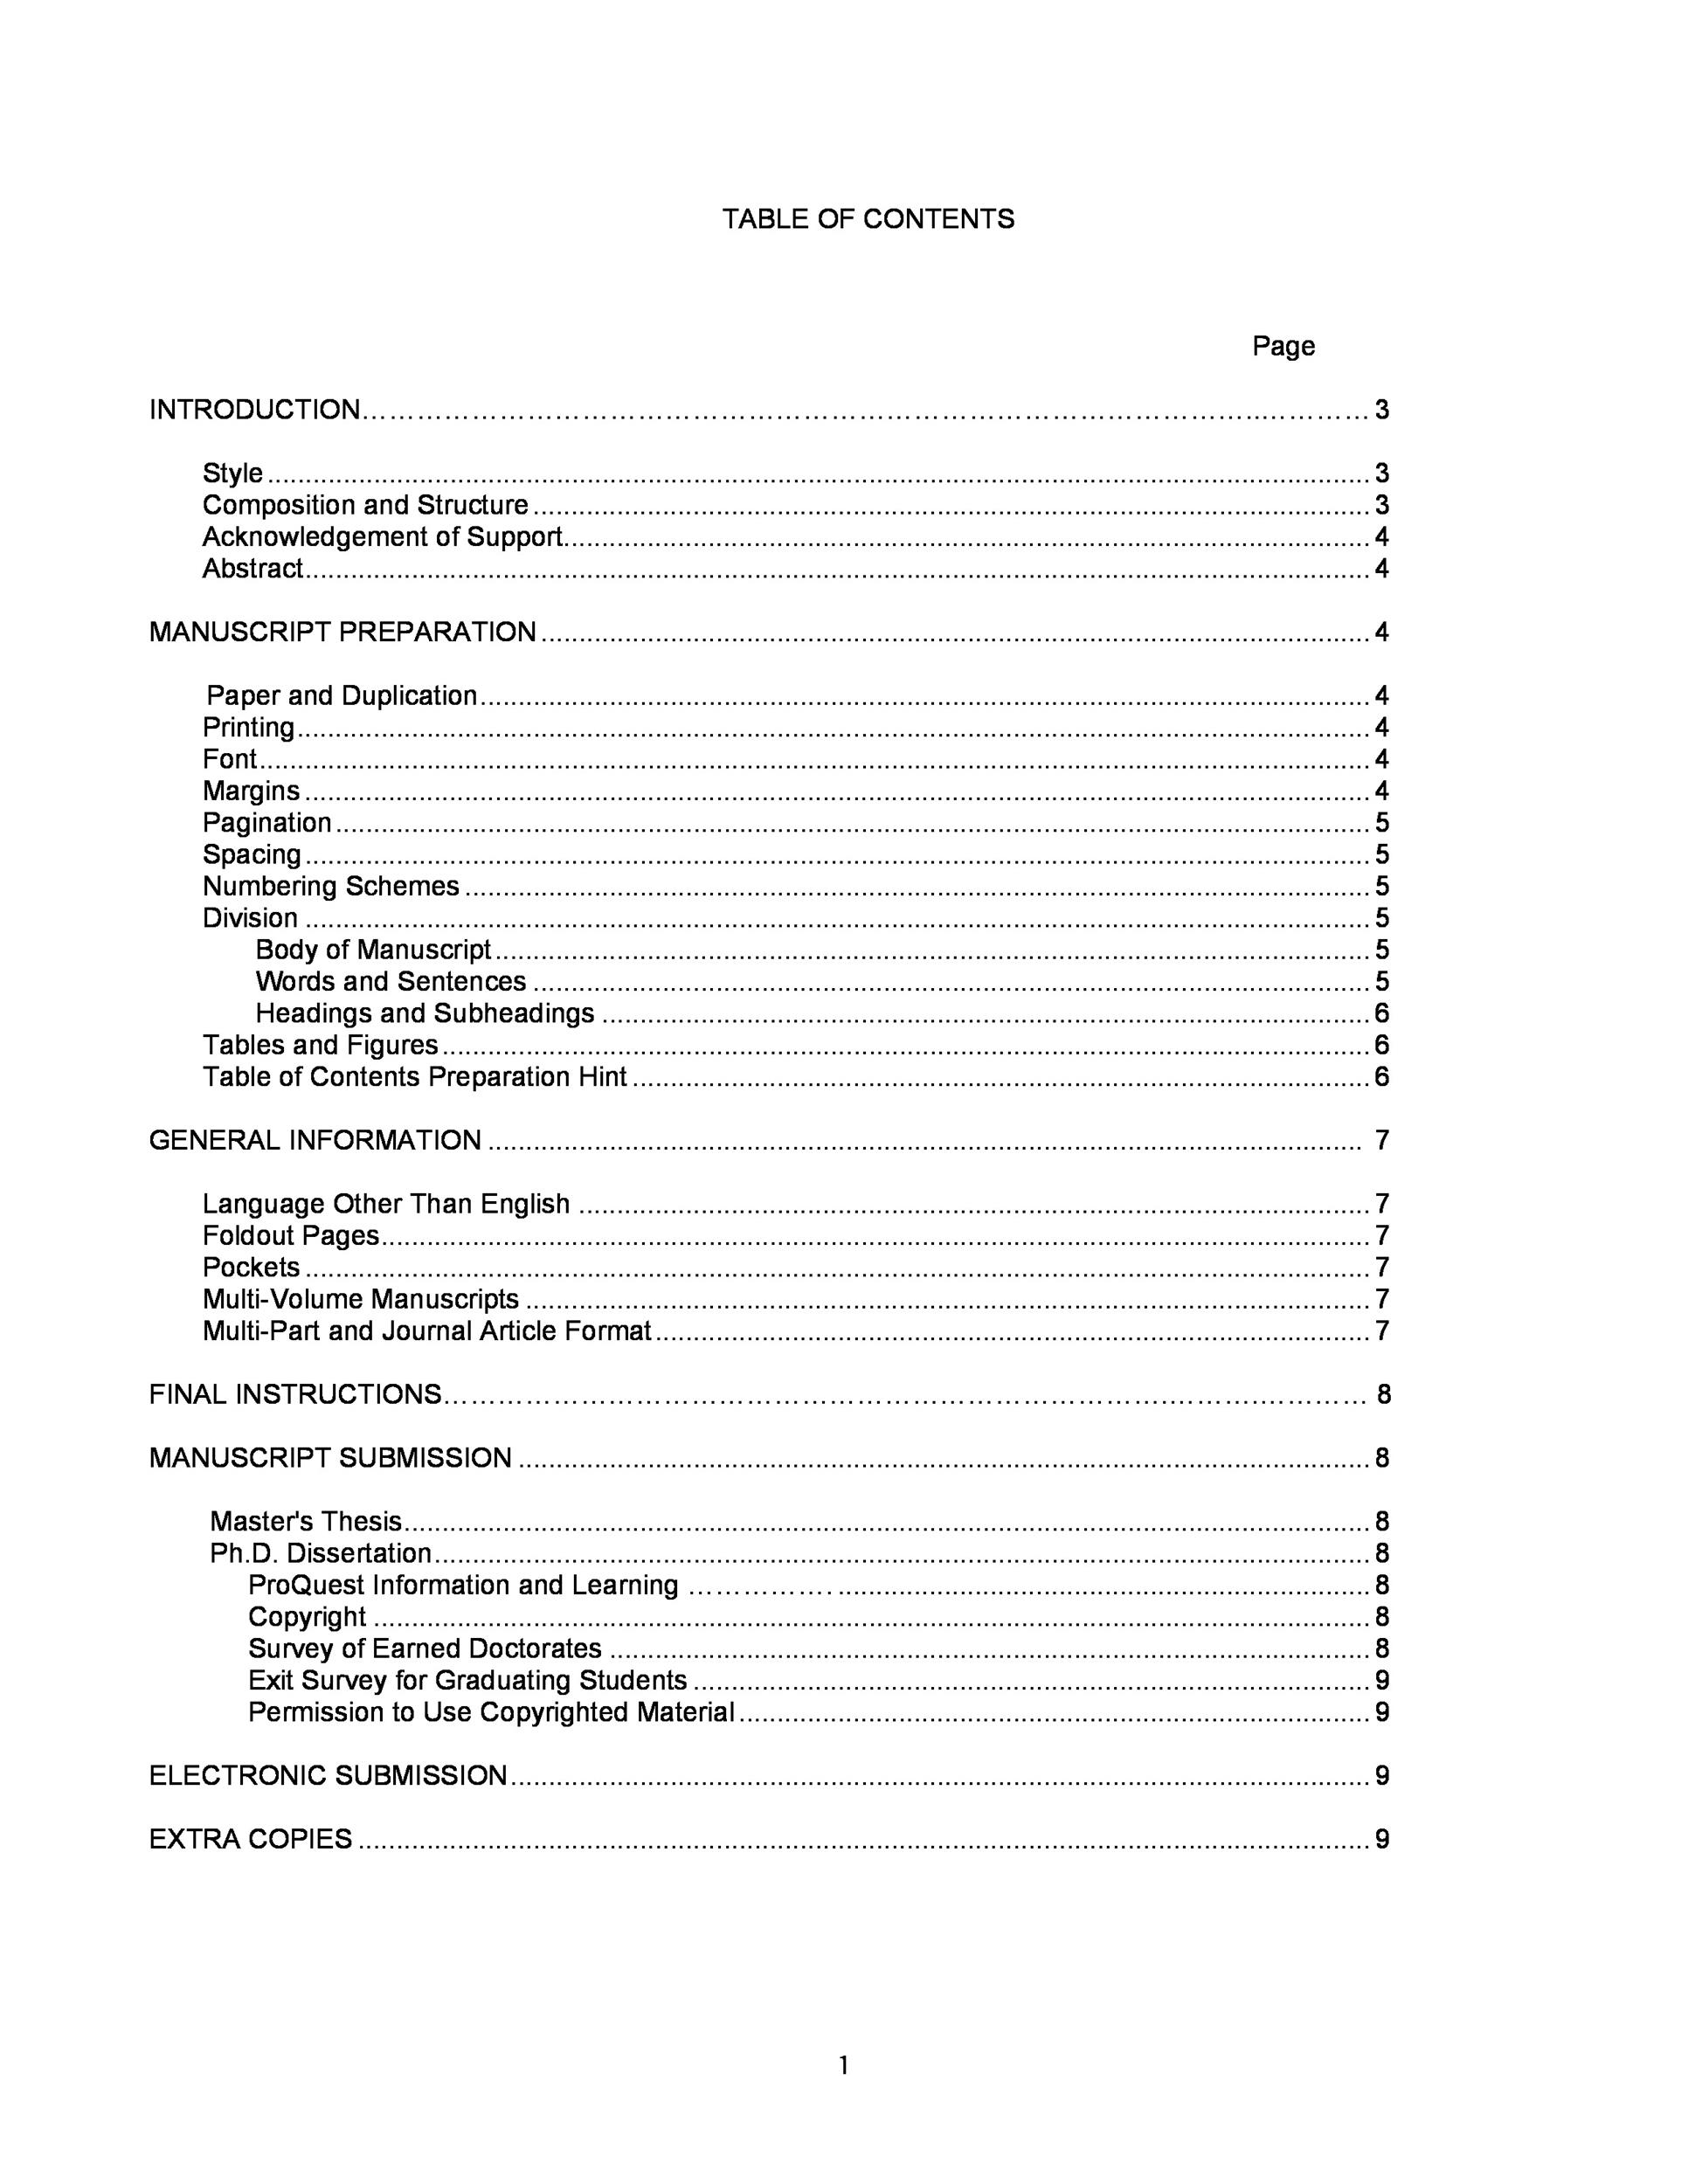
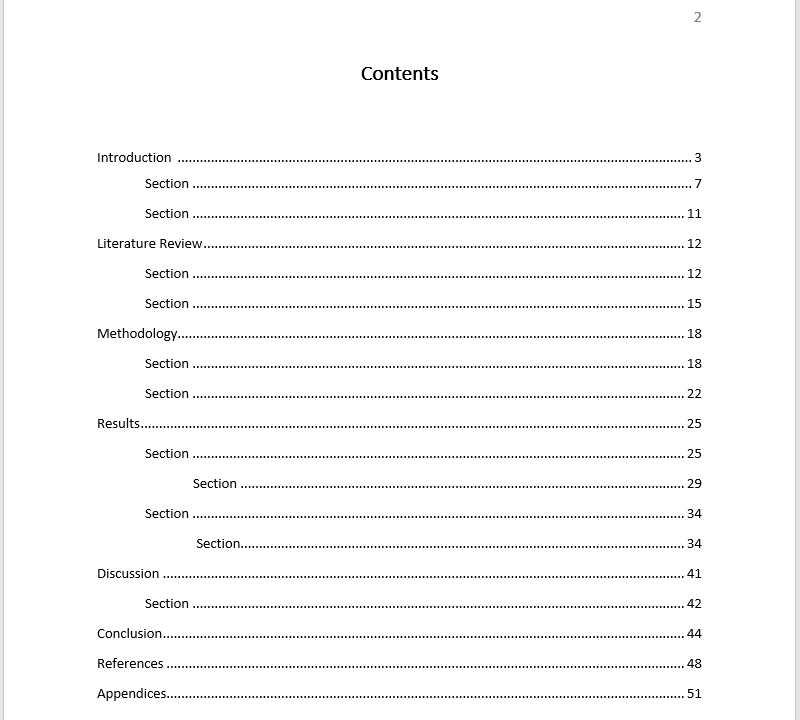
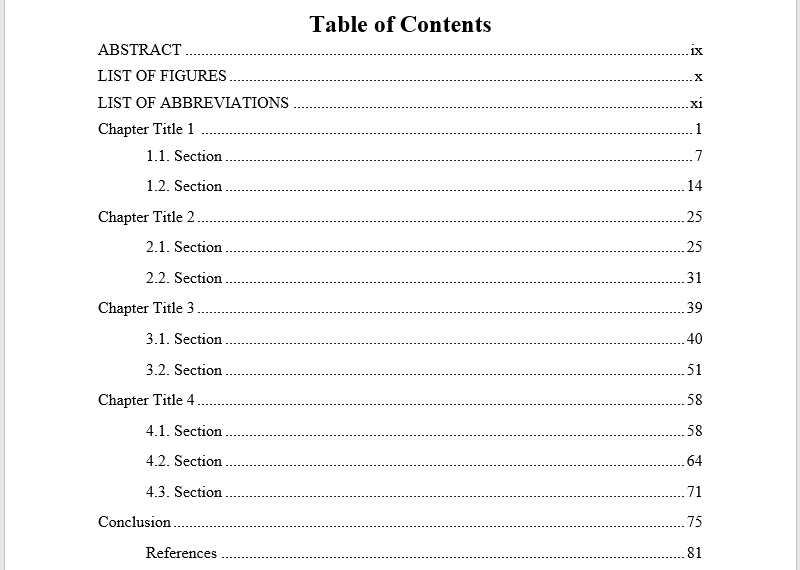
Table Of Content Example From A Real Project
Last year I was working on a 340-page technical manual for a logistics platform. The client wanted interactive clickable navigation, not just a printed list. My initial approach was straightforward: pull all the h2 and h3 tags from the HTML build and generate anchor links. Worked fine on the first draft. Then the content team reorganized three chapters, added new sections mid-document, and the TOC pointed to twelve broken anchors. That took me forty-five minutes to fix manually. After that I switched to using a script that regenerated the TOC from the source markdown before each build. Zero breakage since. The TOC in that project looked like this: 1. Introduction .................................... 3
2. System Architecture ....................... 7
2.1 Frontend Stack ........................... 9
2.2 Backend Services ..................... 14
3. Deployment Procedures ................. 22
3.1 Container Setup ....................... 24
3.2 Database Migration ................. 31
4. Troubleshooting ............................ 45 That looks simple. It is simple. The tricky part is keeping it simple when the document grows.
The Wrong Way People Start
Most folks open a word processor, type out their headings, and then hit insert table of contents. It generates fine. It also becomes stale the moment anyone adds a section, deletes a section, or reorders anything. Page numbers shift. Links rot. This happens because manual TOCs don't track document structure; they track a snapshot of it at one point in time. The same problem shows up in static site generators if you hardcode the navigation. I built a documentation site once where the TOC was written as a static JSON file. Six months later there were seventeen pages in the actual repo that had no corresponding entry. Finding them meant grepping through every .md file and cross-referencing by hand. You can avoid that by generating the TOC from the heading structure itself, but even then there are gotchas.
Get the Full Details
How To Generate A Reliable Table Of Contents
Start by deciding what level of headings you want to include. Most documents should show at least two levels. Some need three. Beyond that you get noise. I usually stick with h1 through h3 and skip anything deeper unless it's a massive reference manual. If you're working in markdown, use a tool like marked, remark, or your framework's built-in parser to extract headings. Feed that into a small script that outputs the navigation structure. Here's a minimal Node example that pulls headings from a markdown file and builds a nested list: const marked = require('marked');
const fs = require('fs');
const md = fs.readFileSync('content.md', 'utf8');
const tokens = marked.lexer(md);
const toc = tokens
.filter(t => t.type === 'heading' && t.depth <= 3)
.map(t => ({ level: t.depth, text: t.text }));
console.log(JSON.stringify(toc, null, 2));
This gives you a clean data structure. From there you render it however you need — HTML, JSON API, PDF backend, whatever. The key is that the TOC derives from the source, not from manual entry. For PDF output, tools like mdbook, Pandoc, or WeasyPrint will auto-generate a table of contents from heading hierarchy. Pandoc's default behavior is actually pretty solid. Just run pandoc input.md -o output.pdf and it builds the TOC automatically. The generated bookmarks in the PDF link correctly as long as your heading levels are consistent.
Common Pitfalls You'll Hit
The biggest issue is heading depth inconsistency. If your document has some h2 tags mixed with h3 tags that should be h2, the TOC structure breaks visually. I see this constantly in collaborative docs where multiple writers use different heading levels for the same conceptual tier. Fix it by running a linting step. markdownlint with a custom rule that checks heading hierarchy catches most of this before it reaches the build. Another pitfall is skip-level headings. Going from h1 directly to h3 without an h2 in between produces a TOC that looks jumbled. Browsers and PDF renderers handle it fine technically, but the visual result confuses readers. I enforce a rule in my projects: no skipping heading levels. A quick regex check during CI catches violations in under two seconds. There's also the problem of long headings truncating badly in narrow navigation panels. A heading like "Configuration Options for the Message Queue Broker in High-Availability Mode" will wreck a sidebar layout. I solve this by keeping a separate title attribute on each TOC entry that shows the full text on hover, while the visible label is shortened to a reasonable length. Something like "MQ Broker HA Configuration" works fine as the displayed text.
When A Table Of Contents Won't Help
TOCs assume a linear structure. If your content is highly non-linear — a decision tree, a lookup table, a set of independent recipes — a traditional TOC adds clutter without utility. In those cases a flat index or a categorized tag system is more useful. I ran into this with a knowledge base of one hundred and twenty troubleshooting articles. Every article was self-contained with no dependency on reading order. A TOC was pointless. I replaced it with a category browser and a search field. Read time dropped by roughly sixty percent compared to the TOC version because users stopped scanning irrelevant sections. There's also the case where dynamic content makes a TOC impossible to keep accurate without heavy automation. If your pages are generated from a database and the section structure changes weekly, maintaining a TOC requires either a build pipeline or client-side JavaScript to scan headings at runtime. Neither is free. Sometimes the right call is just a search interface and moving on.
A Quick Downloadable Template
Here's a basic HTML + JavaScript template you can drop into any project. It scans the page for headings and builds a clickable TOC automatically. Save it as a standalone HTML file and open it to test. <!DOCTYPE html> This is a Table Of Content Example you can modify. It attaches to any heading structure, generates anchor IDs automatically, and keeps everything in sync because it reads the DOM directly. No build step required. The tradeoff is that it only works on the client side, so it won't appear in printed output or server-rendered pages unless you duplicate the logic on the backend.
<html lang="en">
<head>
<meta charset="UTF-8">
<title>Table Of Content Example</title>
<style>
#toc { position: fixed; left: 0; top: 0; width: 240px; padding: 20px; background: #f9f9f9; border-right: 1px solid #ddd; height: 100vh; overflow-y: auto; }
#toc h2 { font-size: 14px; margin-bottom: 12px; }
#toc ul { list-style: none; padding: 0; margin: 0; }
#toc li { margin: 4px 0; }
#toc a { text-decoration: none; color: #333; font-size: 13px; }
#toc a:hover { color: #0066cc; }
.toc-h2 { padding-left: 0; }
.toc-h3 { padding-left: 16px; }
.toc-h4 { padding-left: 32px; }
main { margin-left: 260px; padding: 40px; }
</style>
</head>
<body>
<nav id="toc"><h2>Contents</h2><ul id="toc-list"></ul></nav>
<main>
<h1>Project Documentation</h1>
<h2>Getting Started</h2>
<p>Install the dependencies first.</p>
<h3>Prerequisites</h3>
<p>Node 18 or higher.</p>
<h3>Installation</h3>
<p>Run npm install.</p>
<h2>Architecture</h2>
<p>See the diagram below.</p>
<h3>Frontend</h3>
<p>React-based UI layer.</p>
<h3>Backend</h3>
<p>Express API server.</p>
<h2>Deployment</h2>
<p>Deploy to any container platform.</p>
</main>
<script>
const headings = document.querySelectorAll('main h1, main h2, main h3, main h4');
const list = document.getElementById('toc-list');
headings.forEach(h => {
const id = h.textContent.toLowerCase().replace(/\s+/g, '-');
h.id = id;
const li = document.createElement('li');
const a = document.createElement('a');
a.href = '#' + id;
a.textContent = h.textContent;
a.className = 'toc-h' + h.tagName.toLowerCase().replace('h', '');
li.appendChild(a);
list.appendChild(li);
});
</script>
</body>
</html>
What To Do If You're Working In Print
Print TOCs need actual page numbers. That means you can't generate them until after pagination is complete. Word processors handle this with a field code that updates on print. In LaTeX, the \tableofcontents command works across two compilation passes — first to write the outline to a .toc file, then to read it back. Two runs minimum. If you only compile once, the TOC shows question marks instead of page numbers. This trips people up regularly. In InDesign you set up paragraph styles for each heading level, then use the Tables of Contents panel to generate the layout. It's more manual than automated tools but gives you precise control over indentation, dot leaders, and typography. For a typical 200-page book, setting up the TOC style takes about twenty minutes. Updating it after edits takes thirty seconds. Either way, the principle is the same: automate the generation, never hand-edit the entries. I once worked with a contractor who spent a day manually typing page numbers into a TOC for a client report. The client changed two pages the next morning. He had to redo the entire thing. That's the cost of manual TOCs. It scales poorly.