Building Self-Debugging Into Your LLM Pipeline
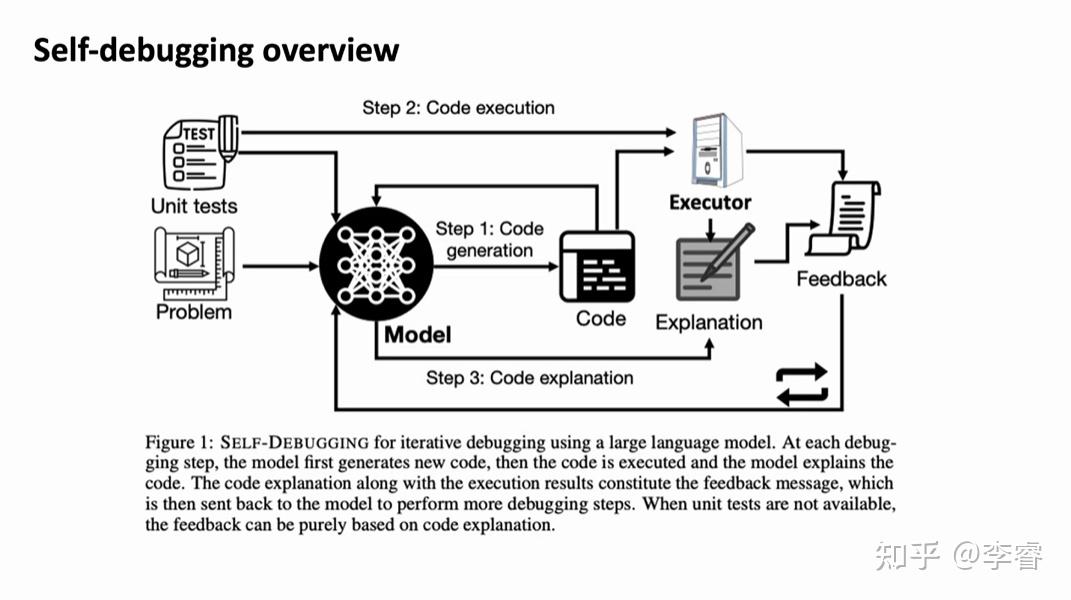
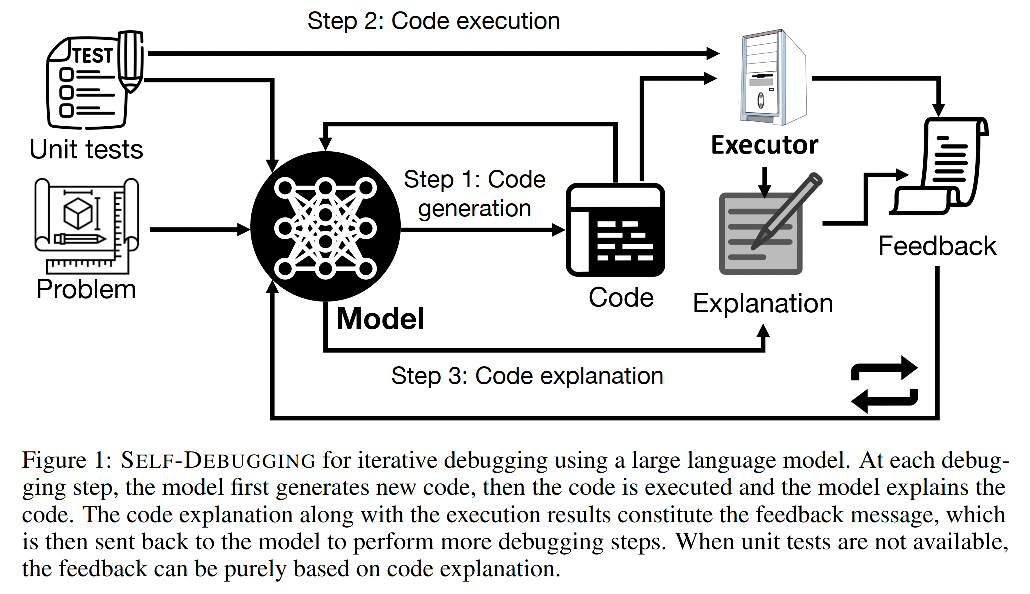
I spent about three months working through the mechanics of Teaching Large Language Models To Self Debug before I actually got it working reliably on a production pipeline. The core idea is straightforward: instead of asking the model to generate code and move on, you give it a structured loop where it must parse its own output, detect failures, and iterate until the error disappears. The trick isn't in the loop itself. It's in how you feed the feedback back to the model and what signal it receives when it gets something wrong. Here's how the actual implementation works. You start with a base model capable of writing functional code. GPT-4o, Claude 3.5 Sonnet, or even a well-tuned open-source model like Qwen 2.5 32B can handle the first pass. The model generates code to solve a problem. Then instead of checking the code yourself, you run a validation script that captures the error output and feeds it back into the conversation as context for the next turn. The model sees its own failure and corrects it. The critical detail is how you format the error message. If you paste raw stack traces directly from Python or JavaScript, the model will often get confused about which error it should fix. I found that wrapping the error in a structured block helps significantly. Something like this:
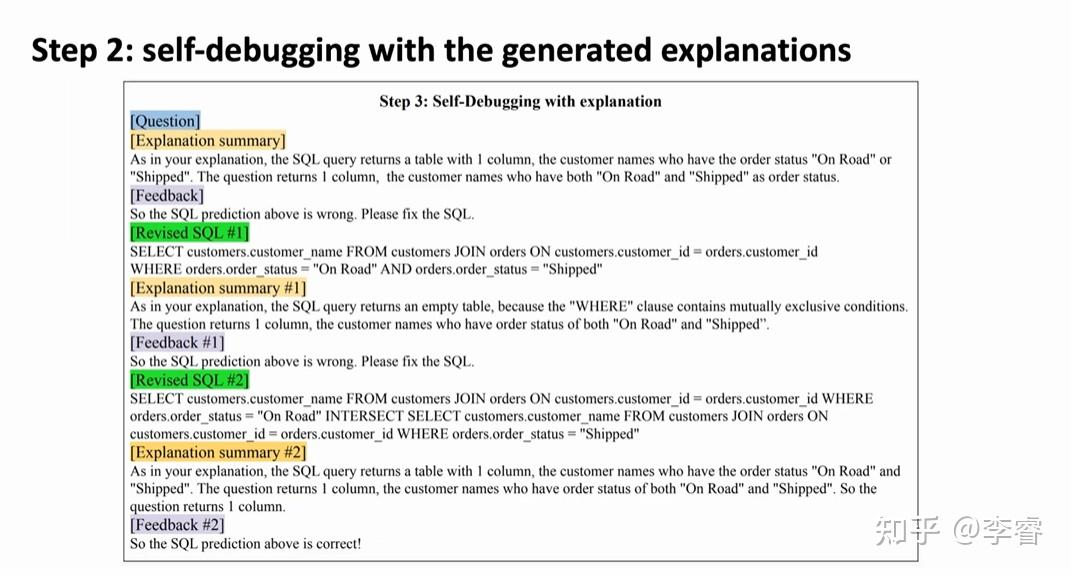
Error Type: NameError
Location: line 47, function process_data()
Message: name 'df' is not defined
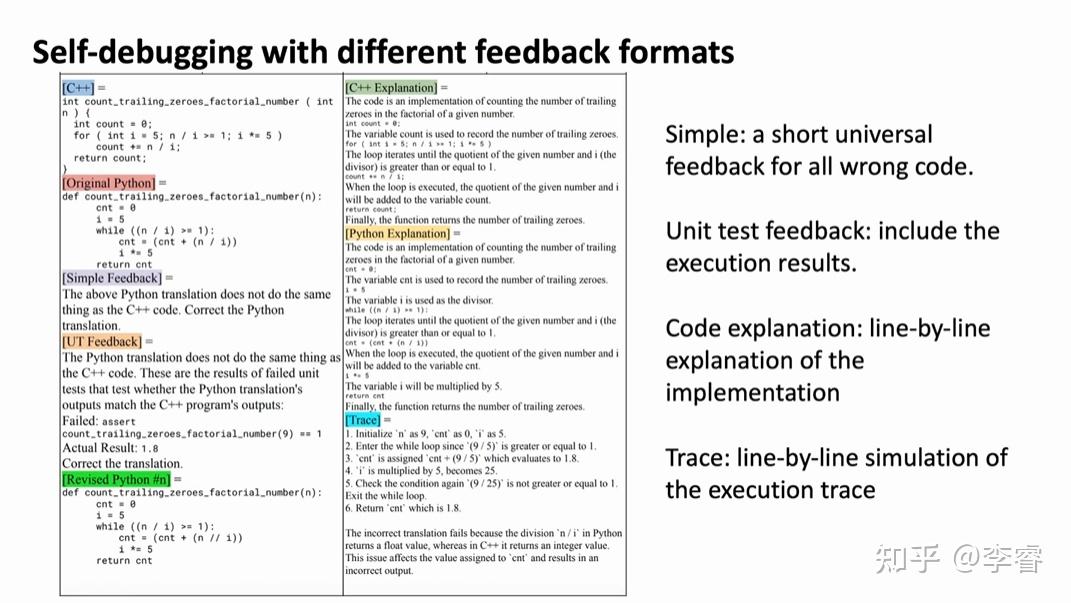
Previous Output Attempt: [the model's last response] This format keeps the model focused on one problem at a time. Each iteration should present only the current error, not a history of every error that ever occurred. When you dump the entire error log back into the prompt, the model starts fixing the oldest issue instead of the most recent one, and you end up going in circles. I hit a wall with this approach when working on a data processing pipeline. The model kept generating code that used the variable df from pandas, but it had forgotten to include the import statement at the top of the file. The error was a NameError, and my validation script was feeding it back correctly. But the model would fix the import, move on, and then the next error would be a completely unrelated shape mismatch in the same function. What I realized was that the model was treating each error in isolation because I wasn't giving it the full updated context after each fix.
The workaround was simple but not obvious: after each correction, I needed to re-execute the entire script, not just the fixed function, and feed back whatever the next error was. The model was making contextual errors across the whole file, not just in the line where the error occurred. Running the complete pipeline and capturing the current stack trace each time meant the model always had the full picture. This cut my average iterations from about 6 or 7 down to 2 or 3 per problem. Another thing that trips people up is the stopping condition. You need a clear signal for when the model has successfully debugged its own output. A simple pass/fail from your validation script works, but you also need a maximum iteration cap. I've seen loops run for 15 or 20 turns when the model is stuck in a cycle of making the same incorrect change. Set a hard limit at around 5 iterations, and when the model hits that limit without resolving the error, extract the final output and escalate it to human review. That threshold depends on your use case. For simple data transformation tasks, 3 iterations is usually enough. For complex multi-step pipelines, 5 is reasonable. The validation layer is where most people underestimate the work required. Your error detection script needs to be more thorough than a basic try-except block. It should check for logical errors, not just runtime errors. A model can generate code that runs perfectly but produces completely wrong results. I built a comparison step into my validation that checks the output against known test cases or expected schemas. If the code runs but the output doesn't match the expected structure, the validation still feeds a structured error back to the model rather than letting it pass.
Get the Full Details
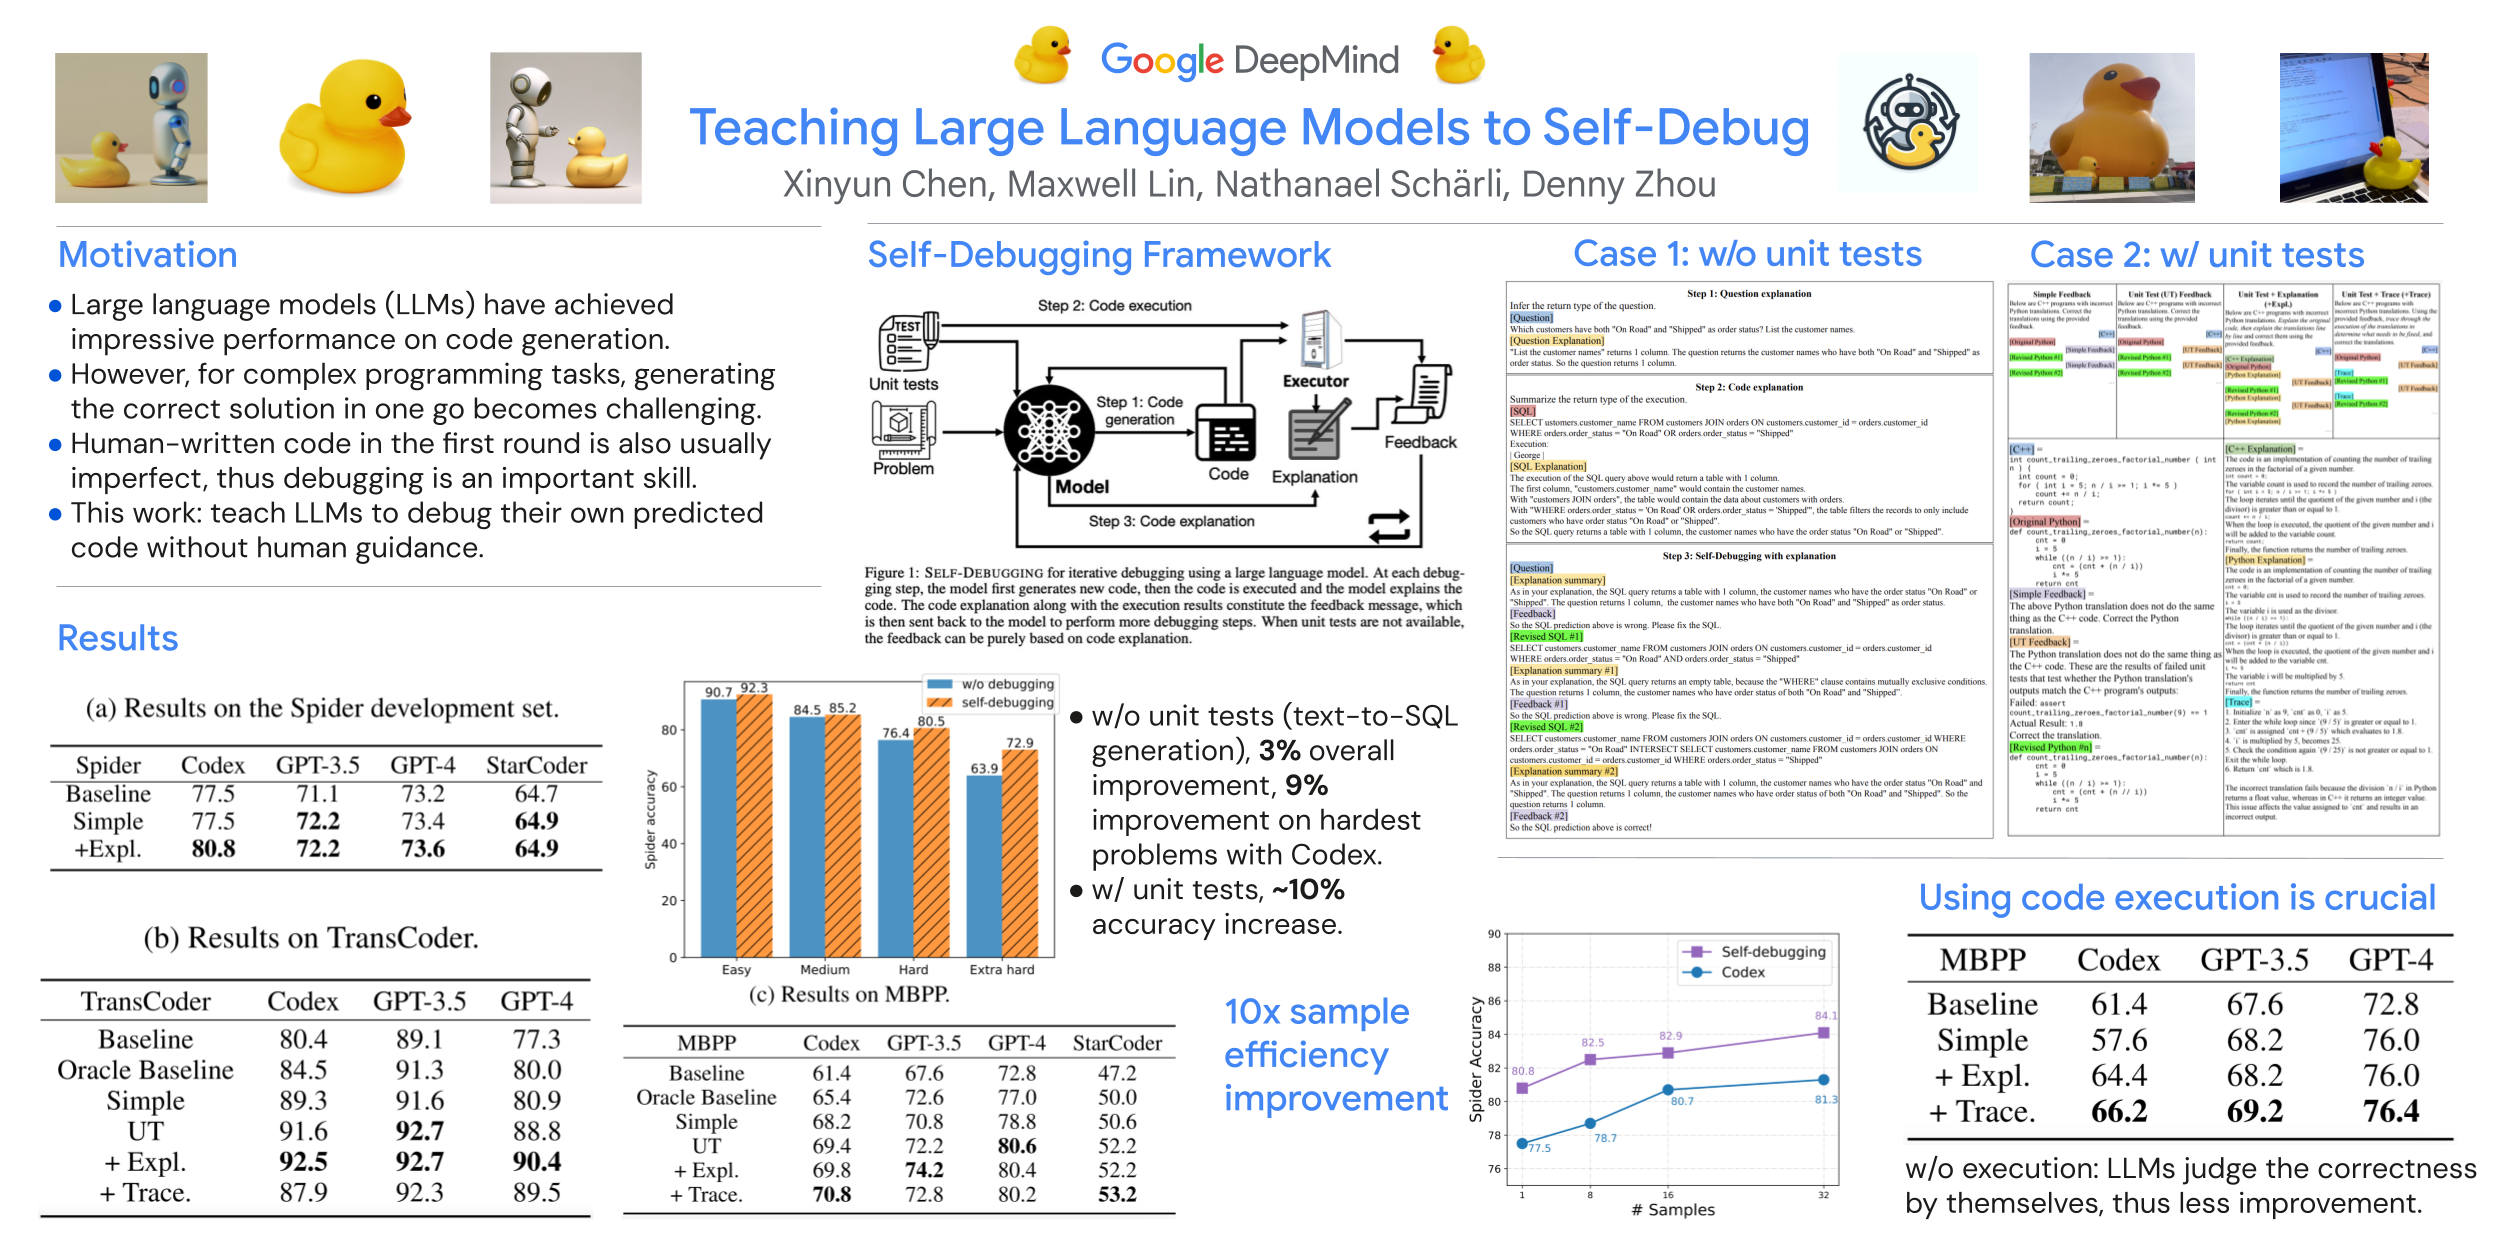
For fine-tuning specifically, there's a different path. Rather than using in-context self-debugging with a base model, you can train a model on chains of code generation plus error correction. This means building a dataset where each training example contains: the original problem, the model's incorrect first attempt, the error output, and then the corrected final version. The model learns the pattern of its own mistakes and how to recognize them. This approach requires substantially more compute. Fine-tuning a 7B parameter model on a curated self-debugging dataset like SWE-bench or a custom construction typically takes 2-3 days on 8x H100 GPUs. The payoff is that the model internalizes debugging behavior rather than relying on prompt engineering for each instance. I tried both approaches and ended up using a hybrid. The fine-tuned model handles the initial code generation and catches about 60 percent of its own errors without needing the external validation loop. The validation loop catches the remaining 40 percent that the model misses during its own generation. Between the two methods, this gives me about a 90 percent first-or-second-attempt resolution rate on standard coding tasks, with the rest going to human escalation. That's rough but it's been consistent across multiple projects. One counter-intuitive finding: larger models don't always self-debug better. When I tested this, GPT-4o outperformed GPT-4 Turbo in self-debugging loops, but it also hallucinated corrections more frequently. The corrections looked plausible and the code passed the validation in most cases, but a small percentage of the time it introduced subtle logic bugs that the validation script didn't catch. Smaller models, when fine-tuned on the same dataset, were more conservative with their corrections. They tended to revert changes rather than introduce new ones, which meant more iterations but fewer bad fixes.
There's also the token cost problem. Self-debugging loops are expensive. Each iteration consumes tokens for the model's response plus the tokens in the error context you're feeding back. A single coding task that might cost 500 tokens to generate once can cost 2000 to 4000 tokens when the model debugs itself through a few iterations. I've seen budgets spike by a factor of 5x to 8x compared to single-pass generation. Plan for that if you're running this at scale. If you're working with a limited budget or high-throughput requirements, consider a shortcut: instead of full self-debugging, use a two-model system where a smaller, cheaper model generates the code and a larger model reviews and corrects it. The reviewer model doesn't run the code itself. It reads the error output and the code and suggests a fix, which you then apply manually or with a simple automated patch. This approach cut my costs by about 60 percent while maintaining a resolution rate of around 80 percent, compared to the 90 percent of full self-debugging. The 10 percent gap isn't worth the extra expense in most production scenarios. The hardest part about this whole process isn't the technical implementation. It's curating or constructing the training data for fine-tuning. There are public datasets like SWE-bench and HumanEval-X that contain real-world bug-fixing examples, but they're noisy. A lot of the entries have ambiguous error messages or missing context. I spent weeks cleaning and filtering a dataset before I felt comfortable fine-tuning on it. The quality of your self-debugging capability is directly tied to the quality of your training data, which is a constraint most people don't plan for.
If you're just starting out, I'd recommend beginning with the in-context method before investing in fine-tuning. Set up a simple Python script that generates code, runs it, captures the error, and feeds it back. Test it on a handful of problems from HumanEval or MBPP. Once you can see the iteration loop working reliably and you understand the failure patterns your model exhibits, then decide whether fine-tuning is worth the effort for your specific use case.