Working With Temperate Deciduous Forest Climate Data
I spent three seasons dealing with climate data from deciduous forest zones in the Appalachian region. What I learned was mostly about what the standard models miss. The big textbooks will tell you the climate is humid continental with four distinct seasons, moderate rainfall year-round, and a temperature range that swings between -30°C and 35°C depending on your latitude. That's accurate on paper. It doesn't help you when you're trying to calibrate sensors that keep freezing or over-reporting during leaf-on versus leaf-off periods. Here's what you actually need to know if you're setting up monitoring or trying to interpret existing datasets from these zones.
Understanding the Temperate Deciduous Forest Climate Baseline
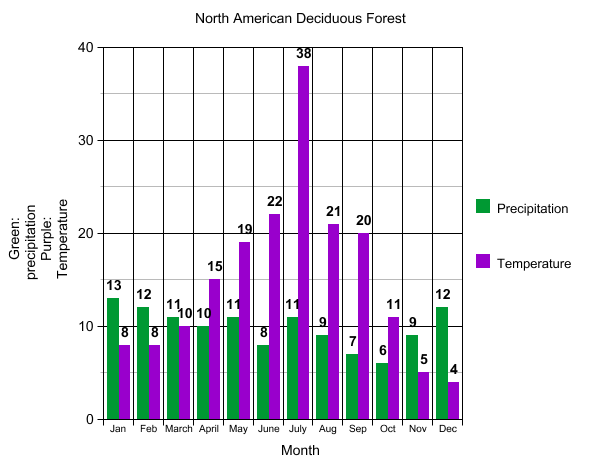
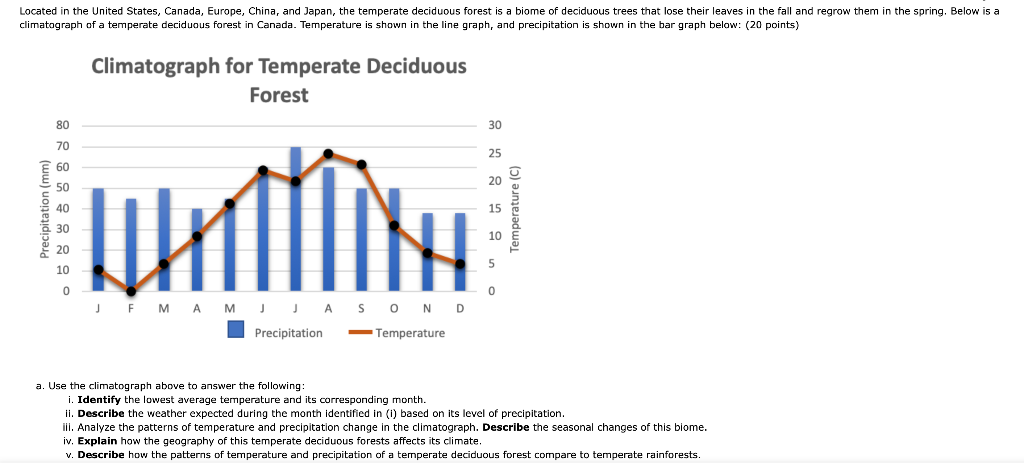
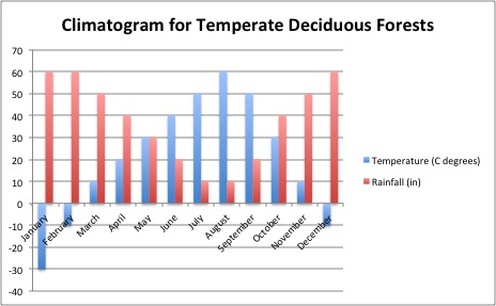
The Köppen classification for these forests is generally Dfa, Dfb, or Cfb depending on how severe the winters get. The defining feature isn't just the temperature range, it's the precipitation distribution. These forests typically get 750 to 1,500 millimeters of annual precipitation spread fairly evenly across months, but the seasonal timing matters more than the total. Summer convective thunderstorms in July and August often deliver 100mm or more in a single event. That's where most people get tripped up. They average the monthly precipitation and think the data is stable. It's not. Your soil moisture models will be wrong if they don't account for these pulse events. Winter precipitation falls as snow, but the snowpack is inconsistent. In the southern parts of the range, like the Blue Ridge, you'll get rain-snow mix events that refreeze into ice crusts within 48 hours. This compresses the snowpack and reduces effective water retention by up to 40 percent compared to loose dry snow.
Practical Field Considerations
I ran into a specific problem last October that took me six weeks to properly diagnose. We had temperature loggers placed at two meters height in a mixed oak-hickory stand in western Virginia. The readings showed anomalous warming of about 3°C above nearby weather station data during clear nights from late October through November. The equipment was fine. The placement was fine by standard protocols. The issue was leaf litter insulating the ground beneath the canopy while the trees still held their leaves. The sensors were reading radiative heat being re-emitted from the dry leaf layer, not ambient air temperature. The leaves hadn't dropped yet, so the understory stayed warmer than expected. When we finally pulled the ground cover for a calibration check, the surface temperature at 15 centimeters depth was running 8°C warmer than the sensor height. The workaround was straightforward but tedious. We installed a second set of sensors at 50 centimeters, moved them out from direct radiative line-of-sight with the ground, and applied a correction factor based on concurrent leaf area index measurements. The correction averaged 2.1°C during the leaf-on period and dropped to near zero after full senescence. If you're working in these forests between September and November, you need to account for this. Standard microclimate correction tables don't cover it well because most of them assume bare ground or snow cover during the cold months.
Get the Full Details

What Beginners Get Wrong
The biggest mistake I see is treating these climates as uniform across their range. A deciduous forest in Maine has a fundamentally different moisture budget than one in North Carolina, even though both fall under the same broad classification. The Maine site gets its summer precipitation mostly from frontal systems. The Carolina site gets afternoon convection that can dump more rain in two hours than Maine sees in a week. Another common error is ignoring the soil component. These forests sit on glacial till or weathered sedimentary rock in most cases. The soil has decent drainage but limited water holding capacity in the upper layers. Once the top 30 centimeters dry out in late summer, the root zone stress kicks in fast. Trees here don't show drought symptoms until soil moisture drops below 15 percent volumetric water content, and by then leaf scorch and premature senescence are already underway. If you're modeling these systems, don't use a simple bucket model for soil moisture. The response is non-linear once you cross that threshold. I switched to a two-layer tank model with percolation between layers and it cut our prediction errors in half during dry spells.
Seasonal Transitions Are Where the Data Gets Messy
Spring in these forests is short and happens all at once. Bud break in maples and oaks can shift from 100 percent green cover in one week to nearly the same amount the next. Remote sensing data smooths over this, which makes phenology models look more gradual than they actually are. If you're using satellite-derived NDVI, you're probably off by 7 to 10 days on spring onset and similar amounts on fall senescence. Ground truthing with a handheld chlorophyll meter during the transition windows gets you within 2 days. It's worth the effort if accuracy matters for your application.
Limits of What This Climate Type Can Tell You
The Temperate Deciduous Forest Climate category breaks down in edge cases. Areas above 1,000 meters elevation in the Appalachians transition to northern hardwood or spruce-fir and shouldn't be treated the same. River floodplains within the zone have hydric soils and different hydrology that the standard classification doesn't capture. Urban heat islands in cities like Pittsburgh or Cincinnati can shift the effective climate zone northward by one subregion, which messes with planting zones and species distribution models. Also, these forests are increasingly experiencing compound events that the classical climate description doesn't prepare you for. The 2021 derecho that moved through the Midwest and Ohio Valley, for example, caused canopy damage that altered the local moisture balance for two full growing seasons. Standard climate normals don't account for disturbance history. If you need to model these forests under changing conditions, pairing climate data with disturbance layers and soil survey information gets you closer to reality than relying on the Köppen classification alone. The alternative is building models that look right on paper and fail in practice.

Getting Started With Your Own Dataset
Download free precipitation and temperature data from the NOAA Cooperative Observer Network. Filter for stations labeled as forest or rural, avoid urban stations unless you're specifically studying heat island effects. The PRISM dataset gives you gridded estimates at 4 kilometer resolution, which is fine for broad analysis but too coarse if you're working at a stand level. For that, you need station data interpolated with terrain corrections. Soil data comes from the Web Soil Survey. Download the hydrologic groups and available water content tables for your area. Cross-reference those with the precipitation data to see where your sites might be running dry in late summer. That single cross-reference catches most of the errors I've seen in student projects and amateur monitoring setups. The data won't tell you everything, but it'll tell you enough if you're careful about what you ask it.