Getting it wrong usually costs more than doing it right
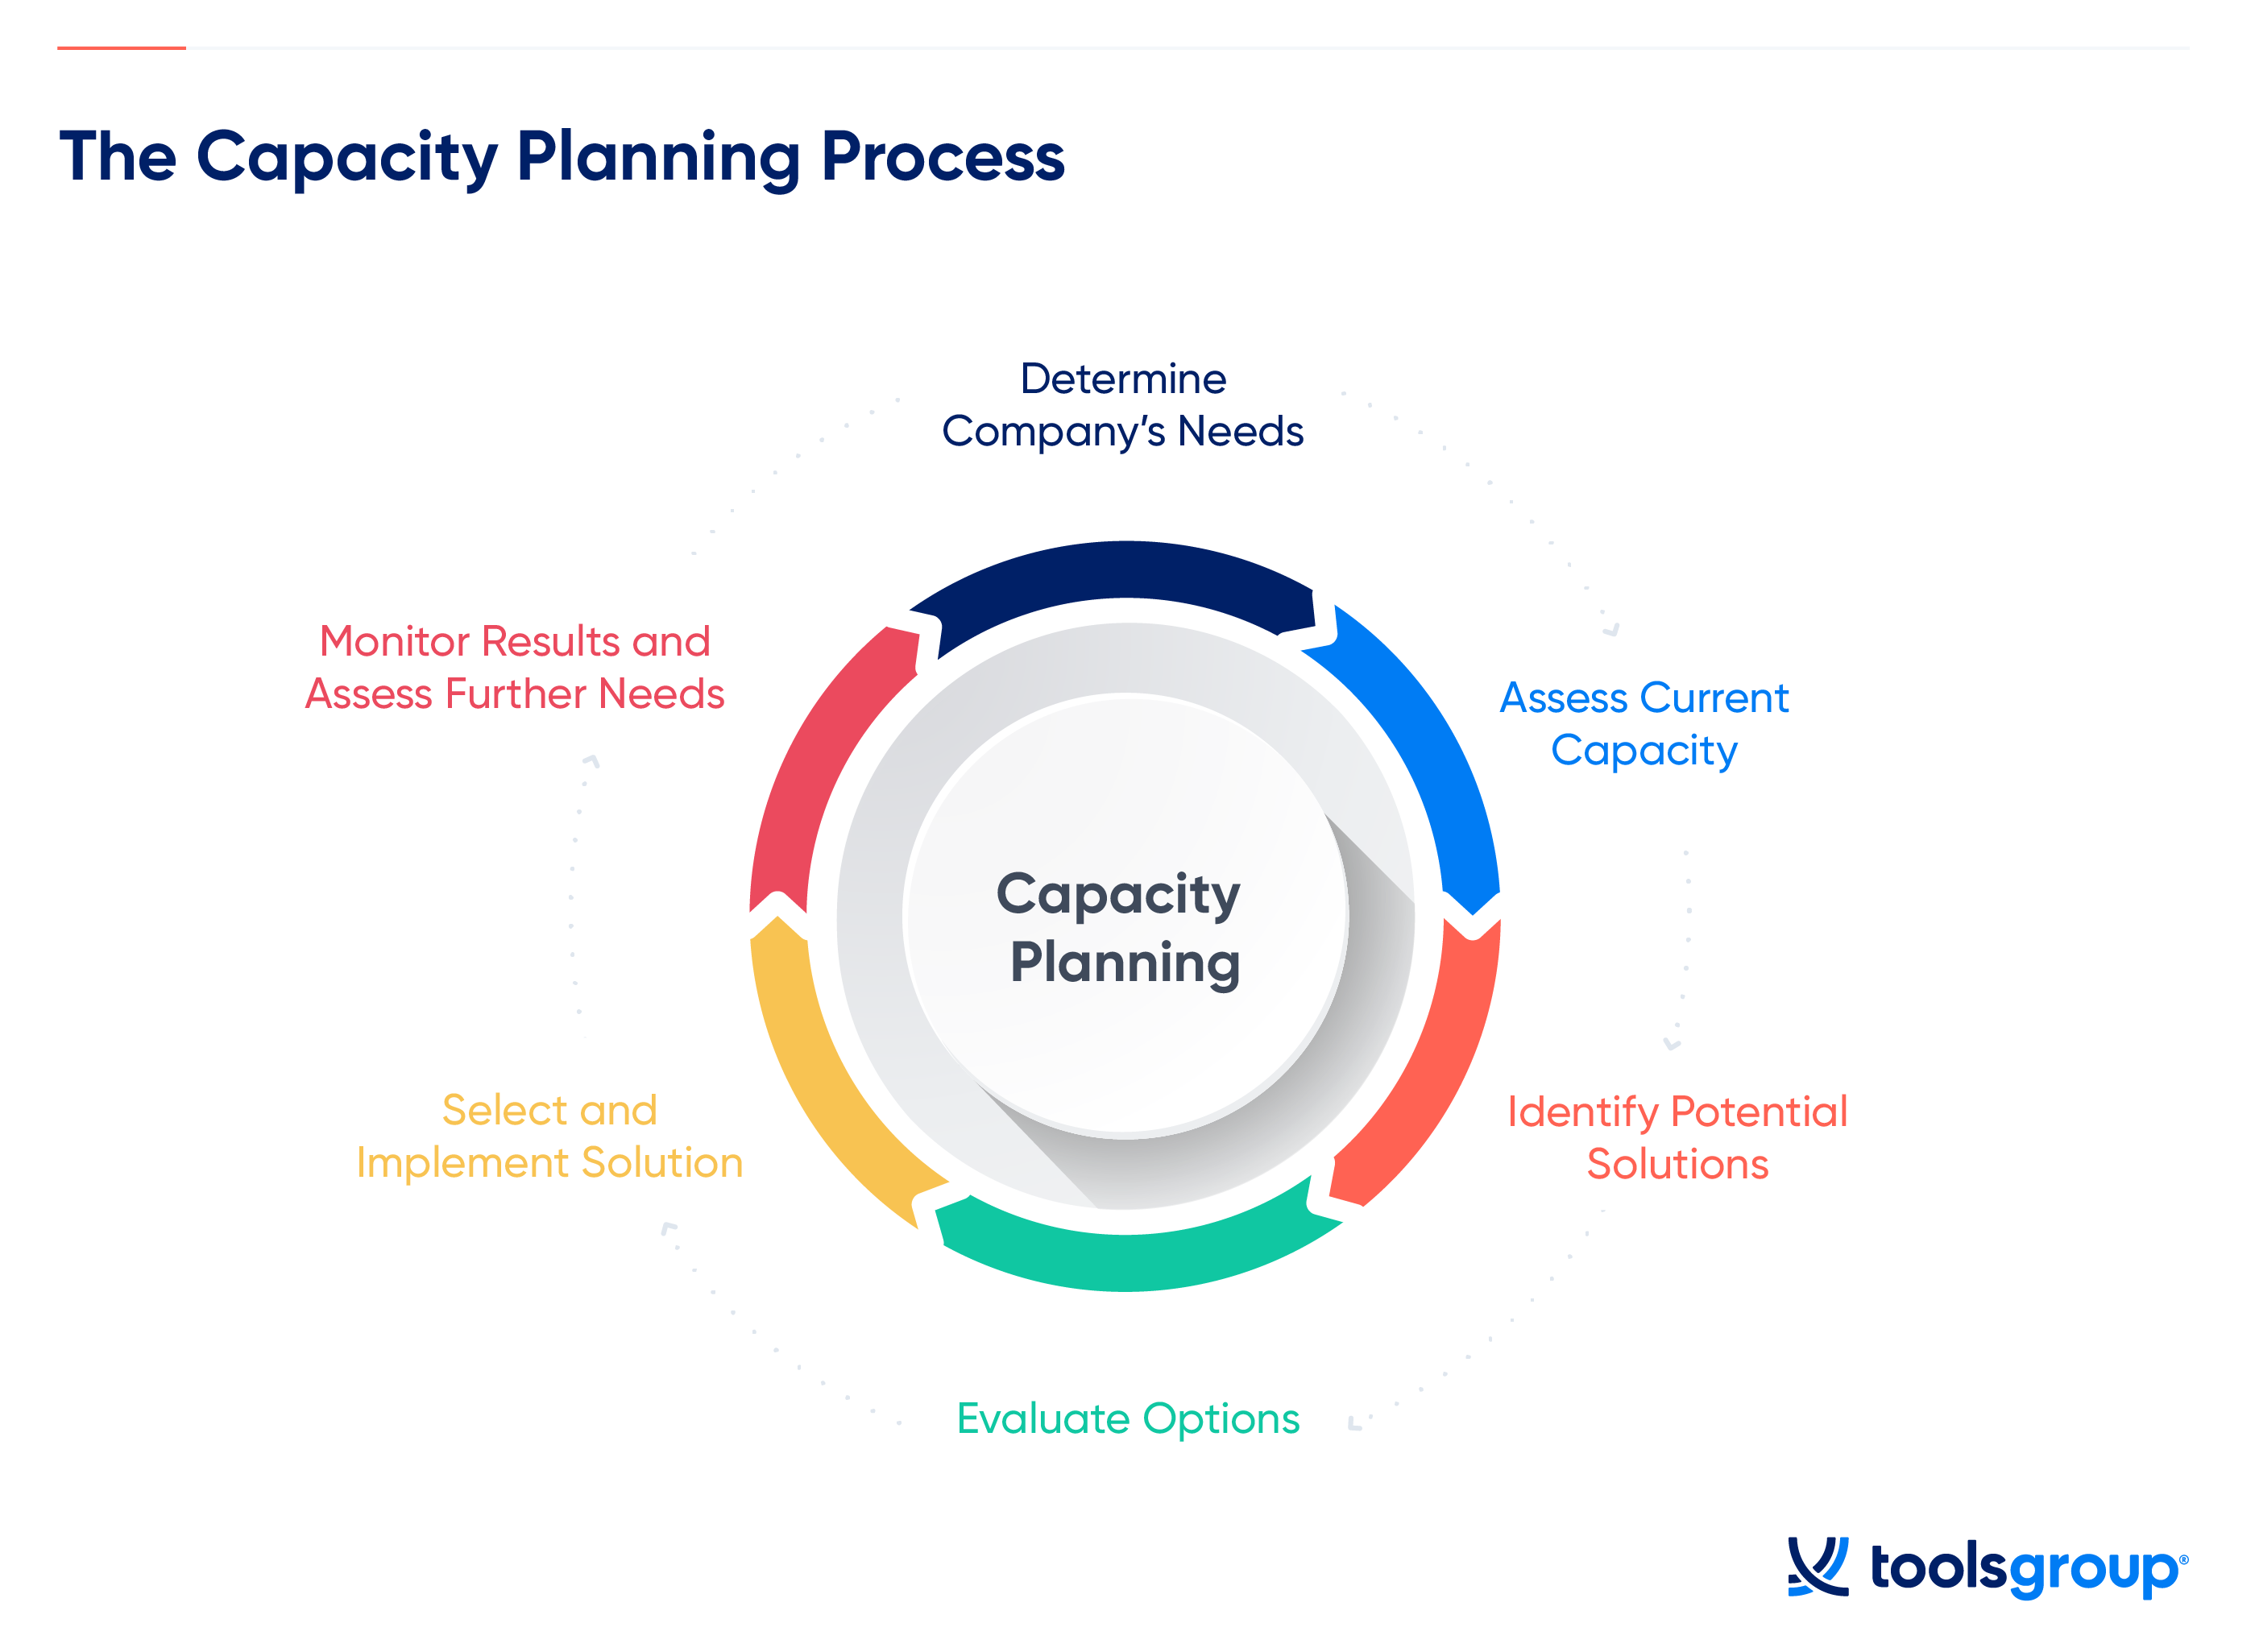
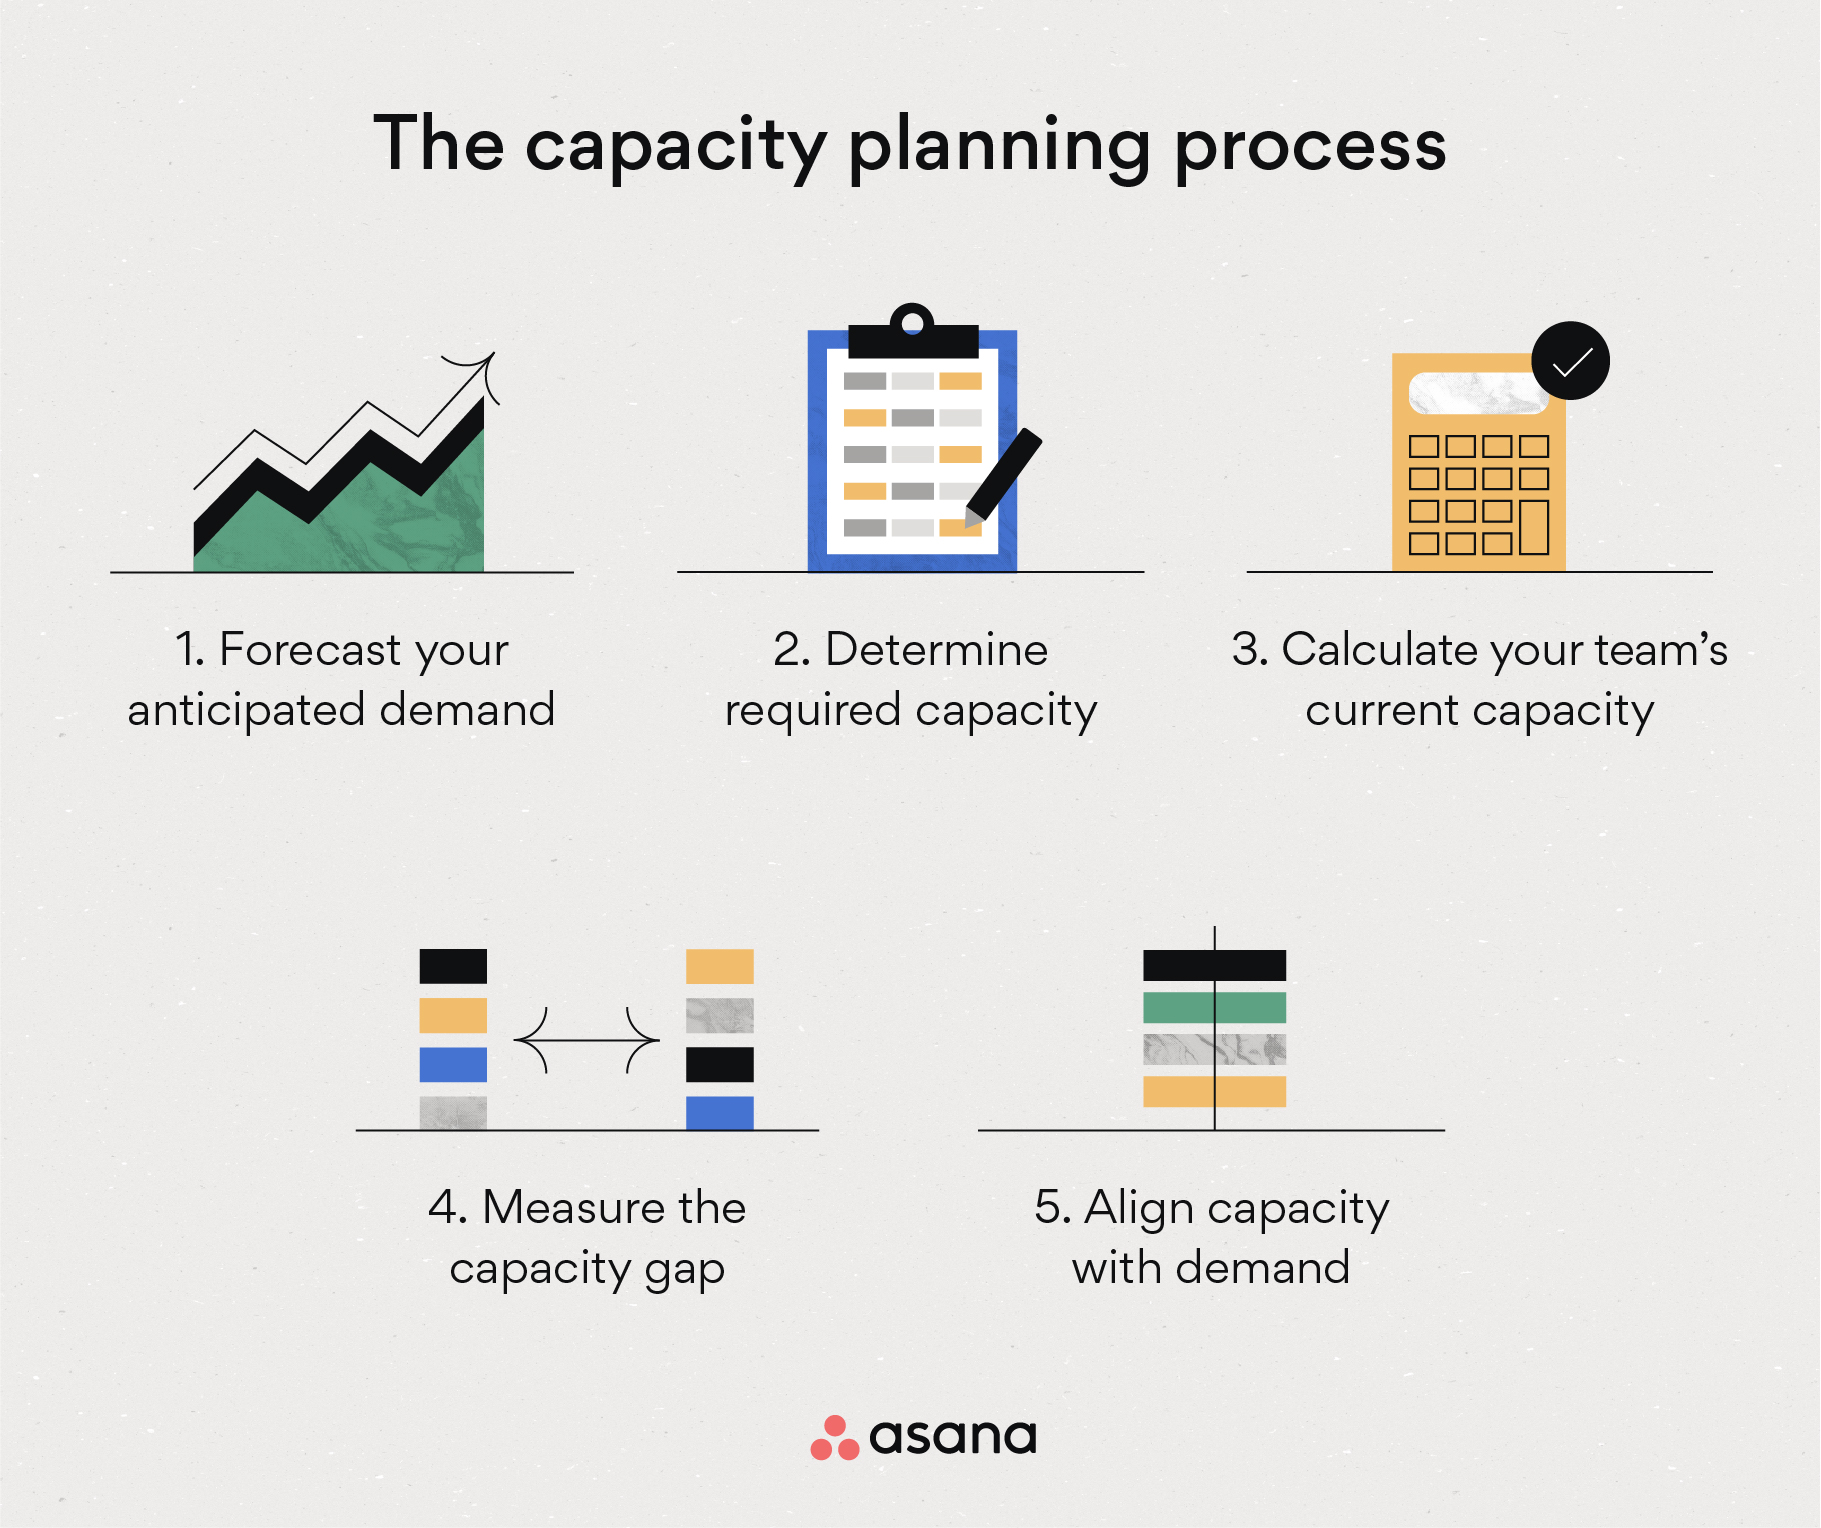
I've seen teams spend weeks building capacity models that fall apart the moment anything unexpected happens. The core idea is straightforward - figure out how much resources you need before you actually need them. In practice, it's messier than that because nobody can predict traffic spikes with perfect accuracy, and nobody wants to pay for infrastructure that sits idle. Here's the practical workflow I use. First, map your current resource baseline over at least a 90-day window. Don't use averages from a busy period or a dead period. Pull actual hourly utilization data for CPU, memory, network I/O, and storage. You need to see the variance between peak hours and trough hours, plus the day-of-week and month-of-year patterns that most dashboards hide because they default to showing daily averages. Next, calculate your peak demand curve. This means identifying not just the highest single-hour spike you've seen, but the sustained multi-hour peaks that actually stress your systems. A 30-second burst hitting 90 percent CPU doesn't cause the same problems as a two-hour sustained run at 85 percent. They feel different on-call too.
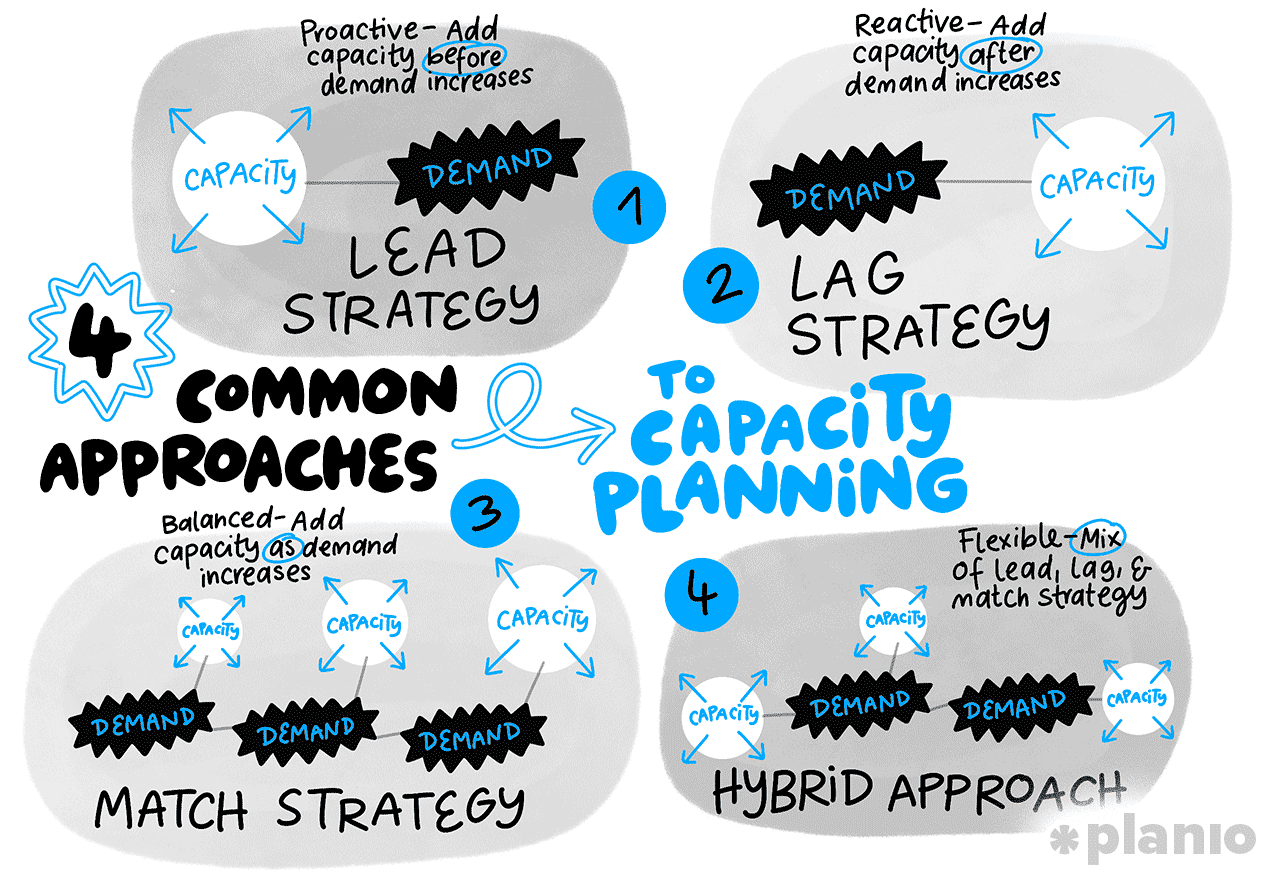
Then factor in your growth trajectory. If you're running at 60 percent of your current capacity today and your business metric shows 20 percent quarter-over-quarter growth, you're looking at a problem in roughly nine months, not twelve. Compound growth eats simple linear forecasts alive. Here's where most people go wrong. They size for the peak and stop there. That gets you to a holiday surge and then you're paying for infrastructure that sits at 10 percent utilization for eleven months. The actual work is finding the gap between what you can afford to run continuously and what you need to handle brief spikes. Your answer usually involves a combination of reserved capacity for baseline load and burstable or auto-scaling resources for peaks. I worked on a system last year where the monitoring tool reported CPU at 45 percent average. We sized to that number and provisioned exactly enough for what the dashboard said we needed. Two weeks after launch, the service started failing intermittently during batch processing windows. The problem wasn't CPU. It was a custom application-layer lock contention that only appeared under specific concurrent request patterns, and it had nothing to do with the metrics the monitoring team was tracking. We ended up running a parallel load test that simulated the actual user transaction mix rather than the synthetic benchmark load, and that revealed the bottleneck. The fix required architectural changes, not more servers, but we had already ordered them by then. That costs real money and delays.
The takeaway from that wasn't that capacity planning is pointless. It's that your definition of capacity matters more than the calculation itself. If you're measuring the wrong thing, the most precise model in the world won't save you. For storage capacity specifically, there's a nuance that people overlook. Most storage systems report usable space, not raw space. A drive marketed as one terabyte gives you roughly 930 gigabytes of actual usable capacity after filesystem overhead. If you're planning five years of log retention at two gigabytes per day, don't just multiply five by three hundred sixty-five by two. Account for compression ratios, index overhead, and the fact that retention policies rarely stay exactly as written once humans start touching them. Network bandwidth is another category where the obvious answer is wrong. Peak throughput and average throughput can differ by an order of magnitude depending on your traffic pattern. Bulk data transfers, database replication, and backup jobs often don't show up in user-facing performance graphs but they consume bandwidth in ways that starve interactive traffic. I had a situation where a nightly ETL job that moved forty terabytes was saturating the primary network link every evening from midnight to four in the morning. No one noticed until latency alerts started firing. The workaround was scheduling it on a secondary link and throttling it to seventy percent of available bandwidth so it couldn't fully congest the pipe even when it ran hot.
Get the Full Details
When it comes to tools, spreadsheet models still work fine for small infrastructures with maybe a few dozen servers. Once you cross into hundreds of instances with mixed workloads across availability zones, spreadsheet models become brittle and error-prone. I've used CloudHealth, AWS Cost Explorer combined with Compute Optimizer, and custom Python scripts that pull CloudWatch metrics and project them forward. The Python approach gives you the most control but requires maintenance. The commercial tools save time but their projections are only as good as the data they ingest, and they tend to smooth over the jagged edges that are usually the most important part. There's no tool that solves this for you entirely because the hard part isn't the arithmetic. It's deciding what counts as a capacity constraint in your particular environment. A database connection pool exhaustion looks identical to user-facing systems as a CPU ceiling. One is solved by increasing connection limits. The other is solved by adding read replicas. If you provision for both without understanding which one is actually limiting you, you've wasted money on both and solved neither problem. Review cadence matters more than people admit. Quarterly reviews are the minimum I'd accept for anything non-trivial. Monthly is better if your growth rate is above fifteen percent year-over-year. Biweekly if you're in a high-velocity environment where deployment frequency is measured in days rather than weeks. The data gets stale fast when you're iterating on infrastructure continuously.
The biggest limitation of this whole practice is that it assumes some correlation between past behavior and future behavior. That assumption breaks when your product hits a growth inflection point, when a competitor launches something that shifts user behavior, or when a new feature changes the traffic profile entirely. Capacity planning doesn't protect you from those events. It protects you from the slower, more boring failures that happen when you're growing steadily and someone assumes everything will keep fitting in the box it's currently in. What it also doesn't handle well is multi-cloud environments where resource types, naming conventions, and billing structures differ enough that aggregating utilization data requires a normalization layer. I've spent more time building data pipelines to feed capacity models than I have building the models themselves, and that's before any of the actual planning work begins. If you're starting from scratch and your infrastructure is small enough that spreadsheets still make sense, start there. Just make sure you're tracking the right metrics from day one, because retrofitting historical data is nearly impossible and you'll spend the rest of your capacity planning career guessing at what happened six months ago. Get the monitoring right first. Then the projections will actually mean something.