What Actually Works When Managing Risk
Risk management is less about fancy frameworks and more about not getting caught flat-footed when something goes wrong. I spent years watching teams build elaborate risk registers that nobody actually read, then pivot to something much simpler and more effective. The Essentials Of Risk Management really comes down to a few practical steps that most people overcomplicate. Start by identifying what could actually go wrong in your specific project or operation. This sounds obvious, but most teams skip straight to solutions without properly cataloging threats. I once worked on a deployment where we missed a third-party API dependency rate limit. The API would throttle after 10,000 requests per hour. We had no monitoring for that threshold. When traffic spiked during a promotional event, everything ground to a halt for six hours. After that, I made it a rule to map every external dependency with its hard limits before considering anything ready for production.
The Essentials Of Risk Management in Practice
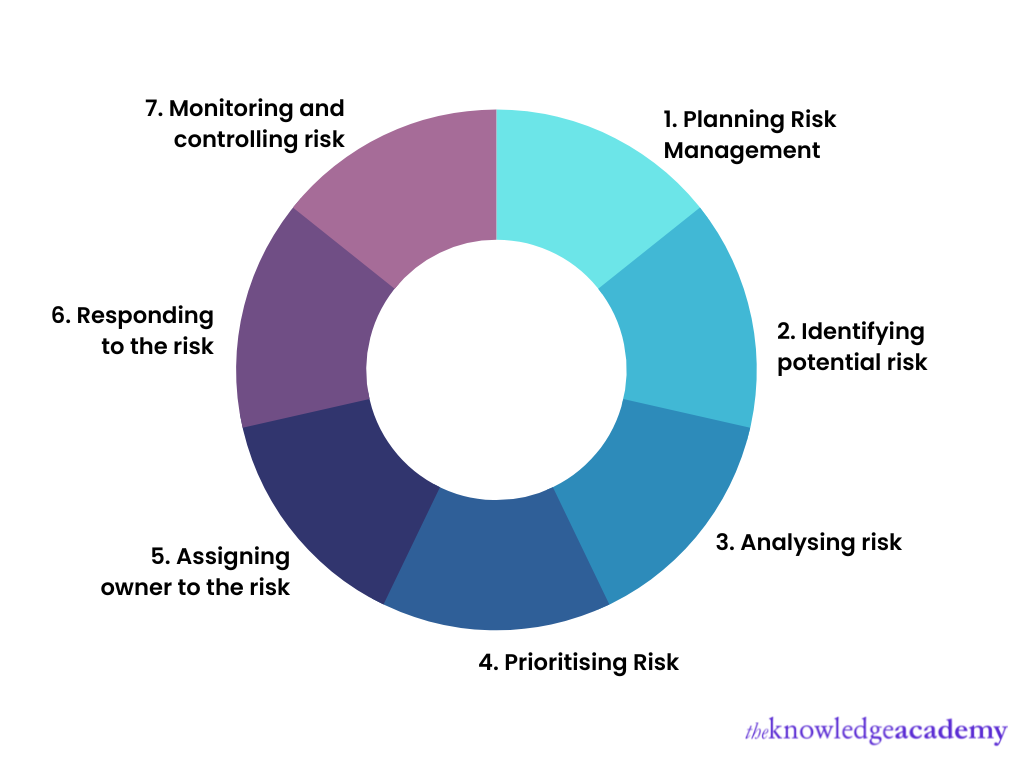
Here is the process I actually use. First, list your risk factors. These are things that could negatively impact your timeline, budget, or quality. Second, assign a probability score from one to five and an impact score from one to five. Multiply them together. That gives you a risk score. Third, prioritize based on that score. Fourth, decide on a response strategy: mitigate, transfer, accept, or avoid. Most people stop at the matrix. They fill out a spreadsheet and file it away. That is where it falls apart. The matrix tells you what to worry about, but it does nothing to change outcomes. What matters is the mitigation plan attached to each high-scoring risk. Who owns it. What triggers escalation. When you revisit it. I keep a living document rather than a static PDF. Tools like Notion or even a shared spreadsheet work fine. The key is that someone opens it weekly and updates status. A risk that sits unreviewed for three months becomes irrelevant because circumstances have already shifted one way or another.
Common Pitfalls That Wreck Risk Management
One counter-intuitive thing I learned the hard way: not all risks need mitigation. Some of the highest-scoring items on your register might be things you genuinely cannot influence. Accepting those risks is a valid and often better choice than wasting resources trying to control the uncontrollable. I used to pressure my teams to create mitigation plans for everything. We ended up spreading ourselves thin across twenty active risk responses and missed the two that actually mattered when they triggered. Another pitfall is confusing risk identification with risk analysis. Writing down "server outage" as a risk is easy. Analyzing it means understanding the failure modes: single point of failure, no automated failover, recovery time estimate of four hours, business impact of lost transactions during that window. The analysis takes real work. Most teams do the first part and skip the second. There is also the problem of recency bias. Recent incidents dominate risk registers while slow-moving, low-probability threats get ignored. I saw this repeatedly. A security breach a year ago kept getting renewed risk scores even though the remediation patches had held for twelve months straight. Meanwhile, a gradual database performance degradation that had been creeping for months went unnoticed because it did not feel urgent. Both were real risks. Only one got attention.
Get the Full Details

Quantitative Methods Worth Knowing
Beyond simple probability-impact matrices, there are more rigorous approaches. Single Loss Expectancy (SLE) calculates the expected cost of a single risk event by multiplying asset value by exposure factor. Annualized Rate of Occurrence (ARO) estimates how often the event happens per year. Multiplying SLE by ARO gives you Annualized Loss Expectancy, which helps you decide whether a control is worth the investment. I used these calculations for infrastructure decisions. If a control costs fifty thousand dollars annually and reduces your expected annual loss from one hundred twenty thousand to forty thousand, that is a straightforward positive return. The math makes conversations with finance and leadership much easier. Numbers speak louder than gut feelings in those meetings. Simulation methods like Monte Carlo analysis take this further by running thousands of scenarios to produce a probability distribution of outcomes. These are powerful but require clean input data. Garbage in, garbage out applies especially here. I found that spending time validating assumptions upfront saved far more time than trying to interpret unclear simulation results later.
When Risk Management Fails Completely
I should be blunt about where this all breaks down. Risk management does not work well for black swan events. These are low-probability, high-impact occurrences that are essentially unpredictable. The 2008 financial crisis, a pandemic shutting down global supply chains, a zero-day vulnerability in foundational software. No risk register prepared anyone for these. Trying to model them precisely is mostly theatrical. For these scenarios, the best approach is building resilience rather than predicting. Redundancy, diversification, and maintaining cash reserves serve you better than any probabilistic model. I learned this after watching a team spend three months modeling supply chain disruption scenarios that looked thorough on paper. When an actual geopolitical event hit, none of their scenarios matched reality. The teams with flexible contracts and alternative suppliers recovered in days. The rest took months. Another scenario where risk management stalls is small teams with tight deadlines. I get it. Filling out risk registers feels like bureaucracy when you are three days from launch. In those situations, I switch to a lightweight version: write down the top three things that could go wrong, assign one owner to each, and agree on a quick escalation path. That usually takes fifteen minutes and covers the vast majority of practical concerns.
A Real Workaround I Developed
One specific edge case I encountered involved a SaaS product where risk ownership rotated every quarter due to team restructuring. Each new owner inherited a risk register written by the previous person. The information was always stale. Risk scores reflected conditions from three months prior. Critical updates were missed because nobody felt responsible for the document. My workaround was to tie risk ownership to functional areas rather than individuals. The infrastructure risk owner was whoever held the on-call rotation for production systems, regardless of their official title. The compliance risk owner was the person reviewing audit findings each quarter. Ownership transferred automatically with the role, not with the person. I also set a hard rule: risk scores above a certain threshold required a written mitigation status update within forty-eight hours of any trigger event. This eliminated the passive ownership problem entirely.

Bottom Line
Risk management is not a checkbox exercise. It is an ongoing practice of staying aware of what could go wrong and preparing reasonable responses. The tools matter less than the discipline of keeping the information current and actionable. Start simple. Update regularly. Focus on what you can actually influence. Accept the things you cannot. Build resilience for the surprises that no amount of planning will catch.