What Actually Happens When You Try To Fix Things
Most people skip the diagnosis and jump straight to the fix. They see smoke, grab a fire extinguisher, and wonder why the building is still on fire five minutes later. I spent years watching engineers, product managers, and operations people do exactly this across a handful of industries. The result is always the same: expensive patches that introduce new failures. The Problem And The Solution is not a proprietary framework. It is simply the disciplined practice of separating the identification phase from the resolution phase and keeping them distinct long enough for both to be useful. That separation sounds trivial until you watch someone spend three weeks deploying a patch for a problem that was actually caused by a configuration mismatch two layers upstream.
The Problem And The Solution
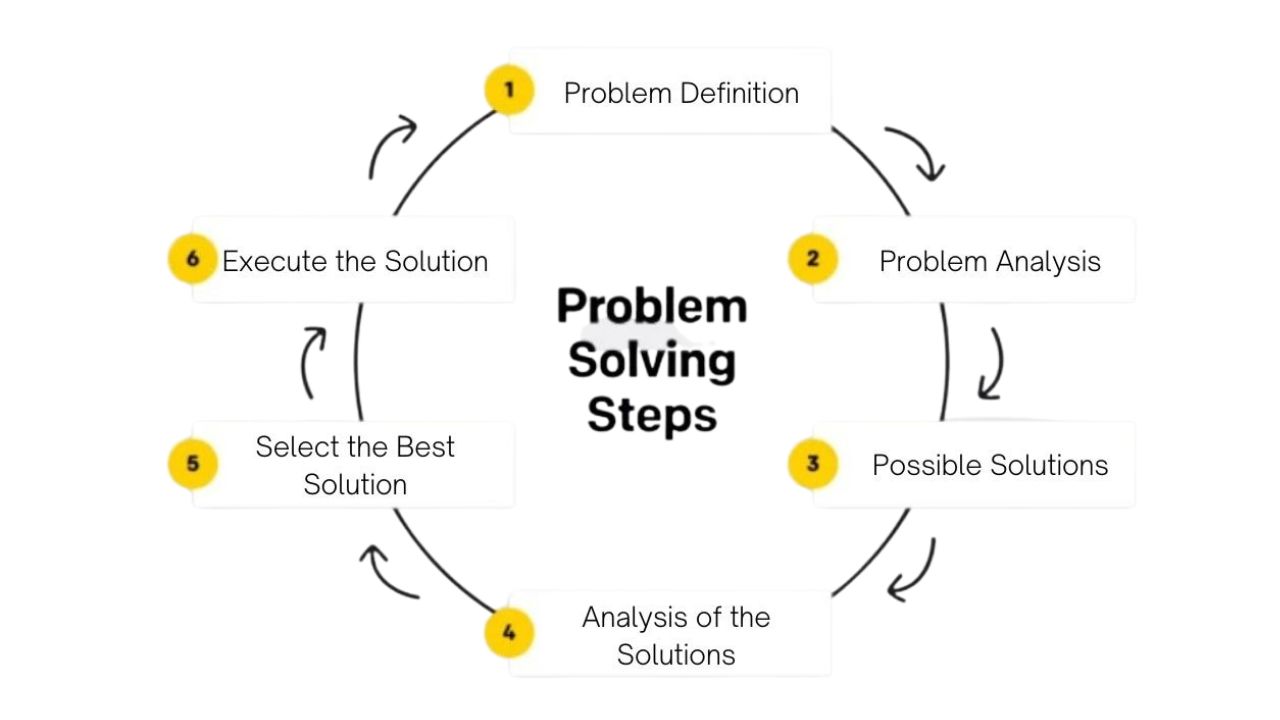
Here is how the method actually works in practice, not the sanitized version you see in management presentations. Step one: write the problem down as a factual statement. Not a hypothesis. Not a blame assignment. A factual statement that includes observable symptoms, the affected system boundary, and the timeframe. "The API returns 503 errors intermittently between 2 AM and 4 AM UTC on the payment service" is a problem statement. "The API is broken" is not. I have seen teams waste entire sprint cycles because they never bothered to draw the boundary around what was actually failing. Step two: resist the urge to propose a fix. This is the part where most people fail. Your brain will immediately suggest solutions because pattern-matching is fast and comfortable. Suppress it. Spend time gathering data until the problem statement can no longer be argued with. Reproduce it. Check logs at the right granularity. Talk to the person who filed the ticket and ask what they were doing five minutes before the symptom appeared. This step usually takes longer than anyone expects. Budget for it.
Step three: define success criteria before you touch anything. Write down what it would look like if the problem were genuinely solved, not just masked. If your fix improves one metric but breaks another one you did not anticipate, you did not solve the problem. I learned this the hard way on a deployment pipeline where we eliminated build failures by pinning a dependency to an older version. The builds stopped failing. Security scanners flagged the pinned version two weeks later. We had swapped one problem for a worse one because we never wrote down what "solved" actually meant. Step four: generate multiple solutions and score them against the criteria. This is where people normally start shopping for their favorite answer. Do not do that yet. List at least three possible approaches, even the ones you initially dismiss. Score each one against your success criteria, implementation cost, reversibility, and risk to adjacent systems. You will often find that the solution you disliked on first inspection scores better once you actually compare them on paper. Step five: implement the highest-scoring option in the smallest viable form. Roll it out in a way that lets you measure whether you actually moved the needle. If you cannot measure the change, you do not yet understand the problem well enough to solve it.
Get the Full Details
There are real limitations to this approach. It does not work well in situations where the problem statement is fundamentally contested because different stakeholders are observing different systems. In those cases, the method stalls at step two and you need a different process entirely, usually involving mediation or escalation rather than technical analysis. It also requires access to data. If your organization stores logs in a system that requires three ticket approvals to query, you are not going to be completing this process in any reasonable timeframe. I worked at a place where the log retention policy was thirty days and the incident we were investigating had occurred forty-two days prior. We could not reproduce the root cause and spent two weeks going in circles. The fix at that point was procedural, not technical: negotiate longer retention before the next incident happens. Beginners also tend to miss the distinction between symptoms and causes. A slow database query is a symptom. The missing index on a frequently filtered column is the cause. Treating the symptom means rewriting the query to be marginally less painful. Treating the cause means adding the index and verifying query plans. Sometimes the symptom-is-the-problem situation is legitimate, like when a third-party service has a documented latency spike and you cannot change their infrastructure. In that case, the correct solution is an architectural workaround, not a root cause fix, and you should treat it as such rather than pretending you solved something you cannot actually control. The method is straightforward enough that explaining it takes less time than most implementation attempts. The reason it fails so often is not complexity. It is impatience. People want to be seen as solving problems, and the diagnosis phase does not look like progress to anyone watching from the outside. That is why the first discipline in this whole process is simply refusing to move faster than the evidence allows.