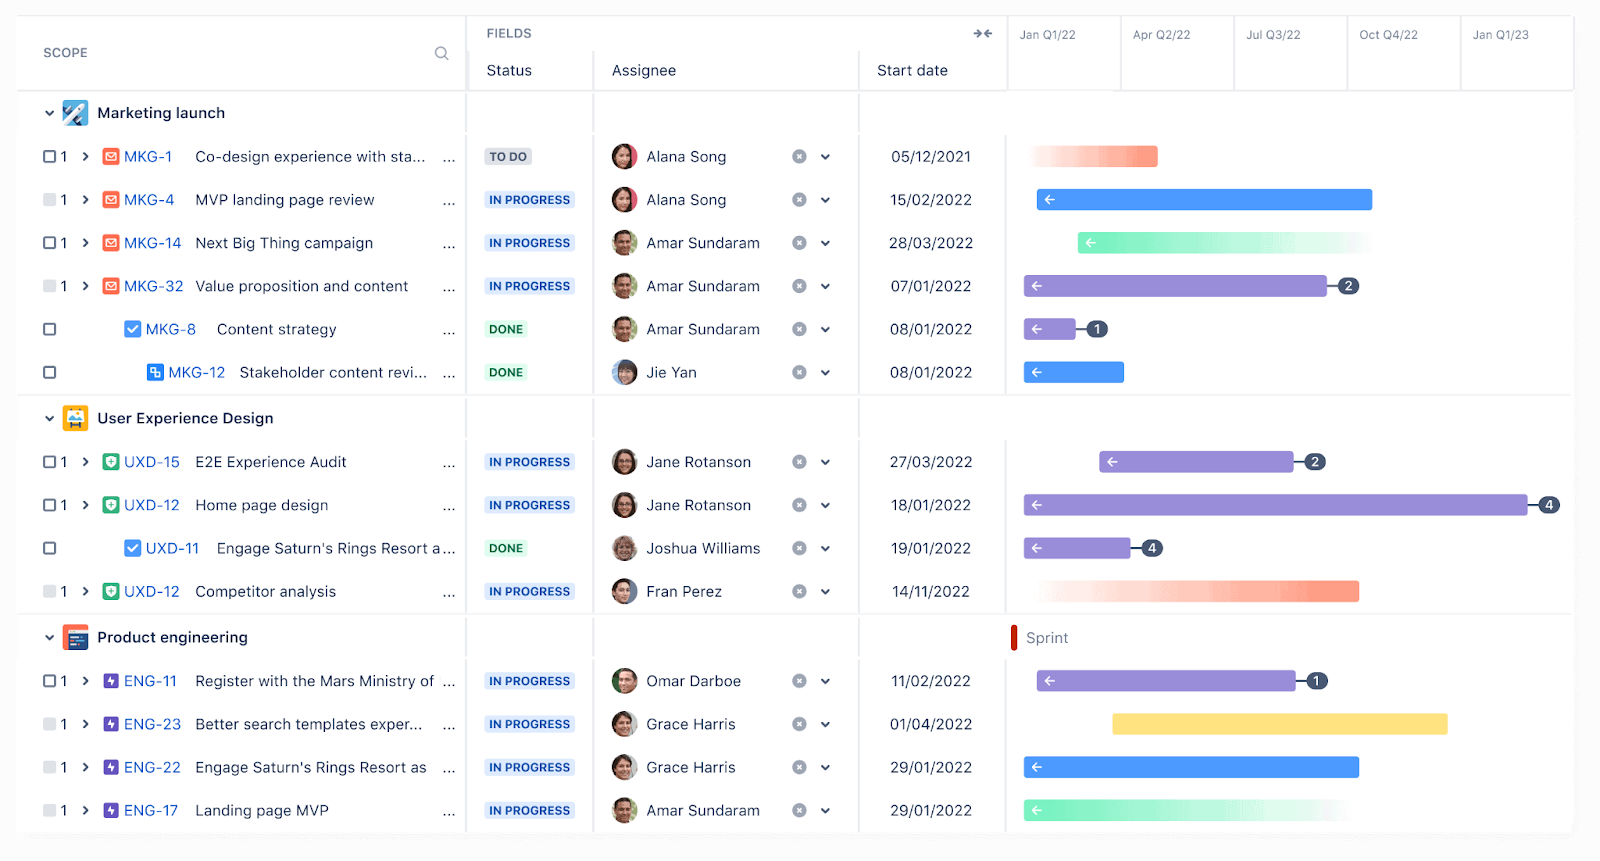
Building a Diy Web Development Tracker That Won't Drive You Crazy
Most people overcomplicate this because they treat it like they're building a project management tool for enterprise software. They're not. You're trying to track bugs, tasks, and deployed commits across a handful of repos. The gap between what you think you need and what you actually need is where the frustration lives. I spent three months debugging a custom tracker that started as a Google Sheet and graduated to a full Airtable base before I realized I was spending more time managing the tracker than shipping code. The problem wasn't the tooling. It was the workflow assumptions baked into the tool.
How the Diy Web Development Tracker Actually Works
At its core, a DIY web development tracker is just a database with a UI on top. You define your entities, your fields, your status transitions, and then you wire them together with scripts or a lightweight frontend. That's it. The complexity comes from every edge case you encounter after the basic setup, not from the setup itself. The typical stack I see work well is something like a SQLite backend with a Flask or FastAPI wrapper, a simple React or even plain HTML/CSS frontend, and maybe a GitHub Actions webhook that pushes events to your tracker when commits land or PRs merge. Python for the backend, since it handles JSON serialization cleanly and you can spin up a local server in under five minutes. SQLite for the database, because you do not need PostgreSQL for tracking twenty tasks at a time and the backup story is trivial. Here is the structure I ended up using after the Airtable disaster:
Tasks live in one table. Bugs live in another. Each has an ID, a title, a status field, a type column, a priority number, a created_at timestamp, and an associated repo string. Commits are ingested via webhook and stored separately, then linked to tasks by matching a prefix pattern in the commit message. When a commit with a message like fix #42 — resolved login timeout lands, the script checks if task 42 exists, changes its status to "resolved," and logs the commit hash as the resolution reference. This is not novel. But it is what actually works on a Tuesday night after a long deployment window.
Get the Full Details

Where People Get Stuck
The first wall most people hit is the status transition logic. You think defining statuses is enough, but statuses without transition rules become a free-for-all. A bug can't go straight from "new" to "deployed." A task can't go from "in progress" to "closed" without passing through "review" if it involves more than one person. These rules matter more than the database schema itself, and they are the thing people skip. I learned this the hard way when a junior developer on my team moved a critical security patch from "testing" directly to "closed" because the UI let them. There was no intermediate check. The tracker did not prevent it. The code never made it to production staging. We caught it two days later during a routine audit, but the tracker should have been the first line of defense and it was not. After that, I added transition validation at the API layer. Every status change now requires a valid previous state, a valid next state, and a reason string. The reason string is optional for internal tasks but mandatory for anything labeled "security" or "critical." The API returns a clear error if someone tries an invalid transition instead of silently accepting it and corrupting your data.
This is the kind of thing that does not feel important until it saves you from reconstructing a timeline that took four hours to trace manually.
Counter-Intuitive Things Beginners Miss
The first thing nobody tells you is that fewer fields beat more fields every single time. Every extra field you add to your tracker is a field nobody fills out consistently, which means it becomes noise, which means you stop trusting the data. I once had a tracker with forty-two custom fields. Twelve of them were populated less than once a month across six months of use. The other thirty had legitimate purpose but only because people treated them as checkboxes and checked them without thinking. The second thing is that commit-based linking sounds elegant until your team starts writing commit messages that don't follow a convention. I have seen people write "fixed stuff" and "updated readme" across repos that were supposed to be auto-tracked. Your tracker becomes useless when the commit messages are garbage because there is no clean mapping between a commit and a task. The workaround is not stricter commit policies. The workaround is making the tracker accept manual task association as a first-class action, not a fallback. Add a simple "link to task" button on each commit entry so someone can tie a messy commit to the right ticket without needing to rewrite history.
The Downside Nobody Talks About
A diy web development tracker will break when you scale beyond a certain point, and that point is much lower than you think. SQLite handles a few thousand rows comfortably. It struggles with concurrent writes. If two developers push changes at the same time and both update the same task, you will get write conflicts. The error messages are not intuitive. SQLite will give you a "database is locked" error and your frontend will just show a generic failure unless you build proper error handling. Another limitation is the absence of a notification system. Most diy trackers I see are purely reactive. Someone has to open the tracker and look at it. That means you miss updates. You miss when a task sits in "review" for three days because nobody checked. You miss when a bug gets marked "in progress" but the developer disappeared from the conversation. I added a simple daily digest email that summarizes open items, tasks stuck for more than two days, and new bugs filed since the last run. It runs as a cron job against the SQLite database and sends to whoever is assigned. Five lines of Python. Changed the whole dynamic. If you need real-time collaboration, live cursors, threaded comments on tasks, or role-based access control, a diy tracker is the wrong tool. Go with something like Linear, Notion, or even GitHub Projects. Those cost money or take time to configure properly, but they handle the edge cases you would otherwise spend weeks building yourself.
Setting Up the Core Tracker
Start with the schema. Here is the minimal version that covers most workflows without being useless: Tasks table: id, title, type (bug/feature/task), status, priority (1-5), created_at, updated_at, assigned_to, repo, linked_commits, reason. Commits table: id, hash, message, repo, authored_at, linked_task_id.
That is it. Everything else is derivative. The repo field matters because web development rarely happens in isolation. If you are tracking work across multiple repositories, your tracker needs to know which repo a task belongs to, or you lose the ability to filter by codebase. For the backend, use FastAPI. It gives you automatic OpenAPI docs for free, which saves you from writing separate documentation. A basic endpoint for creating a task looks like this, and I am being intentionally brief because you already know how FastAPI works: Create task endpoint accepts a Pydantic model with title, type, priority, repo, and optional assigned_to. Inserts into SQLite. Returns the created record with its ID. That is the entire CRUD surface for the start. Add the update endpoint next, and that is where the transition validation lives.
The webhook handler for GitHub is equally straightforward. GitHub POSTs to your endpoint on push events. Parse the payload, extract the commit hash, message, and repo, insert into the commits table, then run a regex search across all commit messages for the pattern #(\d+). If it matches a task ID, update the task and link the commit.
The Real Workflow in Practice
Here is what a normal week looks like with this setup. A developer opens a feature branch, creates a task in the tracker with type "feature," priority "3," and the repo it belongs to. They push code. The commit message references the task ID. The webhook fires, the tracker logs the commit, and the task shows a linked commit entry automatically. When the PR is merged, another webhook event updates the task status to "merged" or "deployed" depending on your branch protection rules. Someone reviews the PR, leaves a comment, and updates the task status to "needs revision." The next developer picks it up, pushes a fix, and the cycle continues. The tracker is barely involved in the actual work. It records it. That is the design goal. A tracker that requires active engagement during the work loop is a tracker that will be abandoned within a month. One detail that matters more than people expect is the priority system. Numbered priorities sound arbitrary until you have fifty tasks and need to know what to pick up next. I use a simple 1-5 scale where 1 is critical/hotfix, 2 is urgent but not blocking, 3 is normal feature work, 4 is nice-to-have, and 5 is backlog. The tracker should default the sort order to priority descending, then created_at ascending, so the most urgent oldest tasks surface first. This is so basic that people forget to implement it, and then they wonder why their board looks random.
When to Stop DIYing
If your team grows past five people, if you need time tracking on tasks, if you need a dashboard that shows cycle time or lead time metrics, or if you need to integrate with a CI/CD pipeline that blocks deployments based on open critical bugs, the diy tracker becomes a liability. You will spend more time maintaining it than it saves you. At that point, move to a proper tool and use the tracker only as a fallback for the specific workflows the commercial tool does not handle well. I kept a minimal diy tracker running even after we moved to Linear for the team. The diy version handled one thing Linear could not do at the time: linking commits across private repositories that were not connected in Linear's integration. That one gap justified maintaining a separate system alongside a paid product. It also meant I had to sync data between the two, which introduced its own problems, but that is a separate conversation.
Common Mistakes to Avoid
Do not build authentication into your diy tracker unless you actually need it. Basic auth or a simple API key is enough for a personal or small-team tracker. Rolling your own session management adds complexity without meaningfully improving security for a tool that stores task titles and commit hashes. The attack surface is small and the consequence of a breach is low compared to what you gain by skipping it. Do not over-engineer the frontend. A table with filters and a modal for creating or editing tasks is sufficient. Do not build drag-and-drop boards. Drag-and-drop sounds good in theory and adds about forty percent more development time with zero productivity gain for most teams. If someone asks for a Kanban view, give them a filtered table grouped by status instead. It takes twenty minutes to build and it works. Do not skip backups. SQLite is a file. Back up that file. Use a cron job or a simple script that copies the database to a dated file on a regular schedule. I lost three weeks of tracker data once because my disk failed and I had not backed up the SQLite file in two months. It was not the end of the world because the commit history existed in GitHub, but it was embarrassing to reconstruct task statuses from memory and commit messages alone.
A Note on Maintenance
Your diy web development tracker will accumulate stale data. Tasks that were never completed but also never closed. Bugs that were marked "resolved" without a linked commit. Commits that no longer correspond to any task. This is normal. Build a monthly cleanup routine that flags tasks older than ninety days without updates, commits with no task link, and tasks with status "in progress" longer than fourteen days. Send the report to yourself. Delete or archive what is clearly dead. Do it manually the first few times until you can tell the difference between legitimate work-in-progress and abandoned tasks. The tracker is a tool, not a system of record for your entire development process. It tracks tasks and commits. That is the boundary. Anything outside that boundary is scope creep, and scope creep is what kills diy projects.