Most people get the first step wrong
They start choosing colors or styling before deciding what the map is actually supposed to do. That mistake compounds through the whole project. A map meant to show road connectivity needs a very different projection than one meant to show population density. Pick the purpose first, then work backward to the tools. The rest is just execution. I once spent three days trying to overlay parcel data onto a base map, only to realize the parcel dataset was in NAD 27 and the base was in WGS 84. They looked close but shifted by about thirty meters in places. QGIS has a reproject-on-the-fly feature, but it doesn't fix the underlying misalignment for printing or publishing. I ended up reprojecting the parcel data permanently using GDAL's cs2cs tool with the correct transformation parameters, then rebuilt the symbology from scratch. Cost me a morning, saved me from a much worse embarrassment later.
The Science Of Making Maps
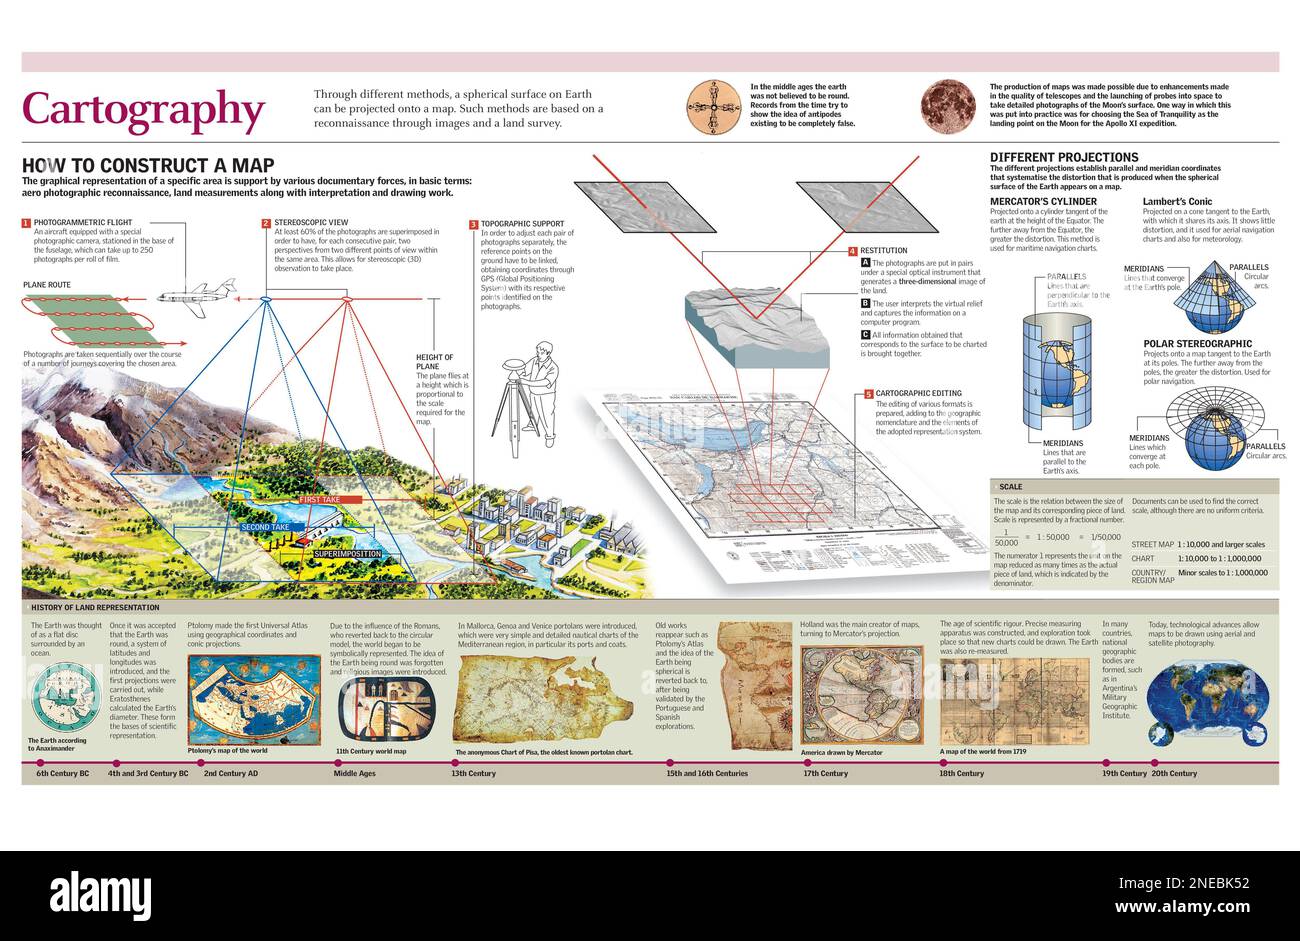
Cartography sits at the intersection of geometry, data science, and visual design. You're taking three-dimensional reality and compressing it into two dimensions while trying not to lie too badly about anything. Every choice you make about projections, generalization, and classification shapes how someone interprets the information. And most of those choices are arbitrary until you force yourself to justify them. Projection selection is where the real math lives. There is no perfect flat representation of a curved surface. You pick which property you're willing to sacrifice: area, shape, distance, or direction. Equal-area projections like Albers or Mollweide preserve relative size but warp shapes. Conformal projections like Mercator preserve angles and local shapes but blow up area at high latitudes. For thematic maps showing choropleth data, equal-area is almost always the right call because your eye compares regions by size. Using a Mercator for a choropleth of US states makes Alaska look dominant when it isn't. That's not a style choice, that's a distortion of the data itself. Data preparation eats more time than anything else. Raw spatial data comes in every format under the sun with inconsistent attribute schemas, missing values, and topology errors. I keep a checklist for any new dataset: verify the coordinate reference system, check for duplicate geometries, validate that polygons actually close, and confirm attribute types match what the analysis requires. Geopandas and the ogrinfo command line tool handle most of this. A polygon with a self-intersection will silently produce wrong area calculations in most GIS software. You won't know it happened until your choropleth has hot spots in places that should be empty.
Classification breaks more maps than any other decision. Jenks natural breaks, quantiles, equal intervals — they produce different maps from the same data. Quantiles force equal numbers of classes regardless of distribution, which means you can end up with five categories that all look nearly identical if your data clusters tightly. Equal intervals can collapse most of your data into one class if the range is wide. Jenks tries to minimize within-class variance but sometimes creates classes that don't make intuitive sense. I use an interactive approach: render the map with each method, overlay the actual data table, and pick the one that actually reflects the distribution. There's no algorithm that does this better than a human looking at both. Simplification matters more than people admit. Generalizing features by reducing vertex count creates cleaner maps and faster rendering. The Douglas-Peucker algorithm is the standard, but it can cut through important detail if your tolerance is too high. I typically run simplification at 0.5 to 2 meters depending on the source scale and the output scale, then visually inspect a few key areas. Automated simplification followed by zero review produces maps that look fine at the overview level but fall apart when someone zooms in on a boundary they know. There are hard limits to what spatial analysis can tell you. The modifiable areal unit problem means that changing the boundaries of your aggregation zones changes the statistical results. Zoning decisions, census tract definitions, even how you draw a watershed boundary can flip a correlation from positive to negative. This isn't a bug, it's a fundamental property of aggregated spatial data. If you're doing any kind of correlation or regression on spatial units, you should run sensitivity tests with at least two different zoning schemes. If the results flip, your conclusions aren't robust and you need to say so.
Get the Full Details
Label placement is another area where automation falls short. Automated label placement in QGIS or ArcGIS uses a cost function, but it still conflicts with features it shouldn't and ignores your judgment about what's readable. I run the auto-placement first to get close, then manually adjust about ten percent of labels in a typical map. The ones that need adjustment are usually the ones near boundaries or in areas of high density where the algorithm makes the worst guesses. Export settings matter. A lot of people export at 96 DPI for web and expect it to work everywhere. It doesn't. For screen use, 150 to 200 DPI is sufficient and keeps file sizes manageable. For print, 300 DPI minimum, and you need to set the color mode to CMYK or convert properly, or the colors come out wrong. Also, embed fonts or convert text to outlines before sending to a printer. Missing fonts produce garbage in the final output and nobody notices until it's too late. Validation is the step most people skip. Before anyone sees your map, test it against known data points. If your choropleth says a certain county has the highest value, pull up the raw numbers and confirm it. Check that your classified breaks actually contain the values they claim. Make sure the legend matches the symbology, not the other way around. A map with an incorrect legend is worse than a bad map because it actively misleads.
The tools have gotten faster but the fundamental problems haven't changed. You're still making choices about what to show, what to hide, and how to represent reality without lying. The software handles the geometry. You handle the judgment. That hasn't changed in forty years and it won't change soon.