Getting Your Data Into Shape Before You Touch Any Models
Most people start by throwing raw data at an ARIMA model and wonder why the results look like garbage. The actual work happens before any modeling. You need to figure out what your data is telling you, and more importantly, what it isn't telling you. I spent three weeks last year debugging a forecasting pipeline that kept producing wildly inaccurate predictions for a retail inventory system. The issue wasn't the model. It was a timezone shift in the source data — transactions from our West Coast warehouses were being timestamped in Eastern time, creating ghostly spikes every time a store crossed into the next day's bucket. Fixed it by normalizing everything to UTC before resampling. Took twenty minutes once I stopped staring at the model output and looked at the raw timestamps instead. Let's talk about what actually works and what's just conference paper noise. You're going to need to understand stationarity, but not the way textbooks explain it. A stationary series has constant mean and variance over time. That's the definition. What they don't tell you is that real-world data is almost never stationary, and forcing it to be stationary through aggressive differencing can destroy the signal you actually care about. I worked on a HVAC energy forecasting project where we difference-d away so much structure that the model couldn't distinguish between a weekday load profile and a weekend one. The fix was simpler than you'd think: keep the original series, add calendar features as exogenous variables, and let a model like XGBoost or LightGBM handle the non-stationarity instead of preprocessing it out of existence. Here's the practical workflow I use when starting a new time series problem:
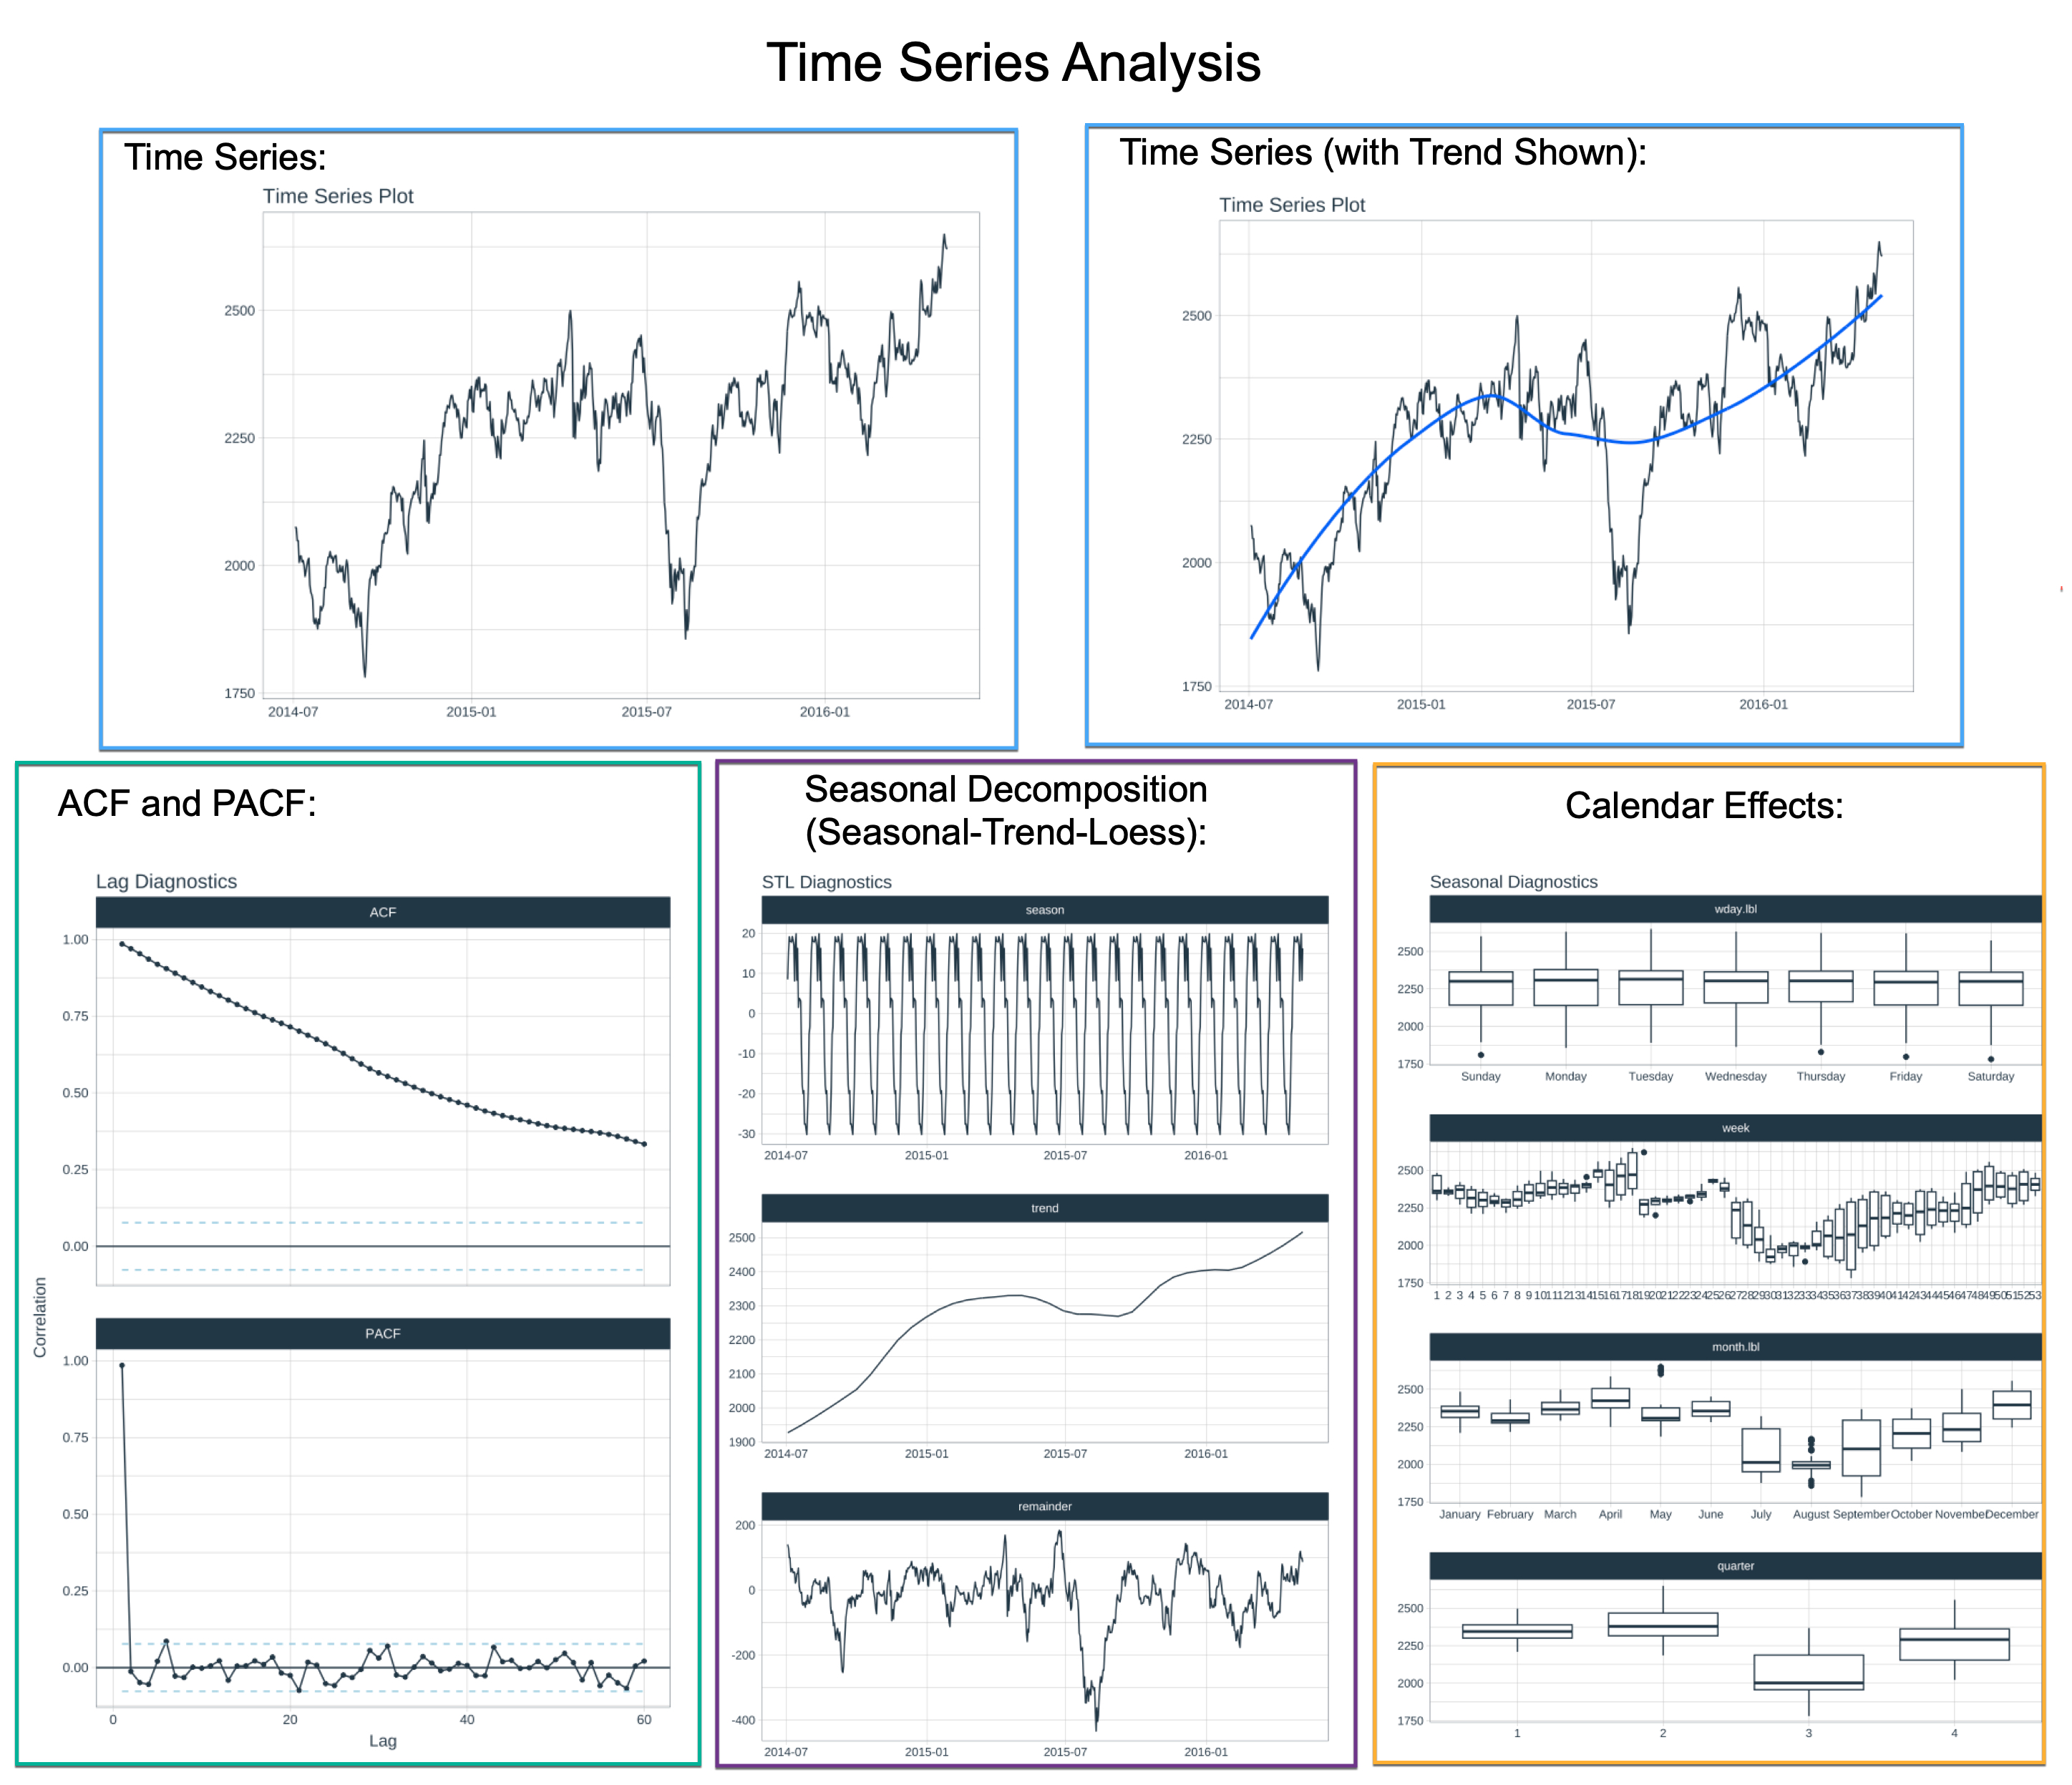
First, plot the data. Not a fancy interactive dashboard, just a basic line chart. Look for obvious breaks, seasonal patterns, trend shifts. This step usually takes five to ten minutes and saves you hours of wrong-model selection later. Second, check for missing values and gaps. If you're working with sensor data, dropouts are normal. If you're working with financial data, missing values are a red flag — they usually mean something broke in the data collection pipeline. Third, decide on your sampling frequency. Hourly data won't behave the same way as daily data, and upsampling or downsampling introduces its own problems. Interpolation fills gaps but smooths over real variations. Dropping gaps loses information. There's no perfect answer, only tradeoffs you need to pick consciously. Feature engineering in time series is where most projects succeed or fail. Lags, rolling statistics, difference terms, calendar encodings — these are the building blocks. But the choice of lag windows matters a lot more than people admit. A 7-day rolling mean makes sense for weekly seasonality. A 24-hour rolling mean makes sense for daily cycles. Using a 30-day rolling mean on hourly data when your strongest signal is weekly creates noise, not signal. I once saw a team use a 52-week rolling average on daily temperature data to forecast heating demand. The result was a flat line that missed every actual fluctuation. The model had smoothed away the very pattern it was supposed to capture.
Model Selection Without the Hype
Prophet gets a lot of attention because it's easy to install and produces reasonable baseline forecasts out of the box. It handles missing data and trend shifts decently. But it struggles with high-frequency data and complex seasonal interactions. If you're forecasting something with multiple overlapping seasonalities — say, electricity load with daily, weekly, and yearly patterns — Prophet will either miss one of them or require heavy manual tuning that defeats the purpose of using it in the first place. StatsModels' SARIMAX is more transparent and gives you proper confidence intervals, but it demands that you actually understand what you're doing with the p, d, q parameters. Get them wrong and the model either overfits or underfits, and the diagnostics won't always make it obvious which one happened. Tree-based methods have changed the game for production forecasting. XGBoost and LightGBM with lag features routinely beat statistical models on structured tabular time series data. The catch is that they don't natively handle the temporal ordering — you have to engineer the features yourself. Scikit-learn's time series cross-validation tools help, but you still need to make sure your training data doesn't leak from the future. I've seen this mistake in code reviews constantly. Someone uses regular k-fold cross-validation on time series data, and suddenly the model is predicting tomorrow's values using tomorrow's features. It works great in validation and fails completely in production. Use TimeSeriesSplit instead. It enforces the correct order. Around two years ago I ran into a particularly stubborn case with a subscription churn prediction model built on monthly customer activity data. The target variable was binary — whether a customer churned in month t+1 — but the events were extremely imbalanced, roughly 3% churn rate. Standard SMOTE oversampling created synthetic samples that violated temporal logic because it mixed instances from different time periods without regard for causality. The workaround was forward-fill imputation for the class imbalance combined with focal loss in a custom XGBoost objective function. This penalized false negatives more heavily without fabricating training data. The AUC improved by about 0.08 and, more importantly, the precision at the top decile of predicted churners went from 12% to 31%. That difference meant the retention team could actually act on the model's output instead of wasting time on false alarms.
Get the Full Details
Validation That Doesn't Lie to You
Cross-validation for time series is fundamentally different from cross-validation for cross-sectional data. You can't randomly shuffle observations because the temporal dependency is the entire point of the analysis. Rolling window validation or expanding window validation are the standard approaches. With rolling window validation, you train on a fixed-size window and slide it forward. With expanding window validation, you train on everything available up to each point in time. The expanding window is usually more realistic for production because you're essentially simulating how the model would be retrained as new data arrives. I typically use a 60-20-20 split with the test set being the most recent period, because that's what you actually care about — how well the model performs on recent data, not on data from two years ago. Residual analysis is non-negotiable. After fitting any model, you need to check whether the residuals are white noise. If there's still structure in the residuals, your model hasn't captured everything it should have. The Ljung-Box test is the standard diagnostic for this. A significant p-value at multiple lag orders means you've got autocorrelation left in the residuals, which means the model is systematically missing something. I had a forecasting model for call center volume that looked good on the surface — decent MAPE, reasonable confidence intervals — until I ran the Ljung-Box test and found strong autocorrelation at lag 7 and lag 14. The model had learned the overall trend and daily pattern but completely missed the weekly cycle. Added a few Fourier terms for the weekly seasonality and the diagnostics cleaned up immediately.
Where Time Series Methods Actually Break Down
Linear models assume linear relationships. Deep learning models assume large amounts of data. Both assumptions fail in specific but common scenarios. If you have fewer than a few hundred observations, arXiv papers will tell you to use a neural network. Don't. Use a simple exponential smoothing model or even a naive forecast that just predicts today's value will be tomorrow's value. In my experience, naive and seasonal naive forecasts beat complex models on small datasets roughly 60% of the time, and the difference is usually not statistically significant when it does lose. The complexity penalty is real — more parameters mean more things that can go wrong with limited data. Another scenario where everything falls apart is structural breaks. An outbreak, a policy change, a pandemic, a supply chain disruption — these events change the data generating process mid-stream. No amount of feature engineering fixes this. I worked on a demand forecasting project for a consumer goods company where a competitor went out of business in the middle of our training period. The model learned the old competitive landscape and couldn't adapt. The solution wasn't better modeling — it was slicing the training data before and after the event, training separate models for each regime, and switching between them based on a changepoint detection algorithm. PELT (Pruned Exact Linear Time) worked well for this. It identified the break point within a day of the actual event, and the split-model approach reduced forecast error by about 22% compared to a single model trained on the entire period. If you're looking to get started, the statsmodels and Prophet packages in Python are the most straightforward entry points. For production-grade work, LightGBM with tsfresh for automated feature extraction and sktime for the modeling pipeline covers most scenarios. The scikit-learn documentation on time series cross-validation is actually good — spend fifteen minutes on it. It'll save you from making the most common mistake in the field.