Planning Statistical Analysis Before You Collect Data
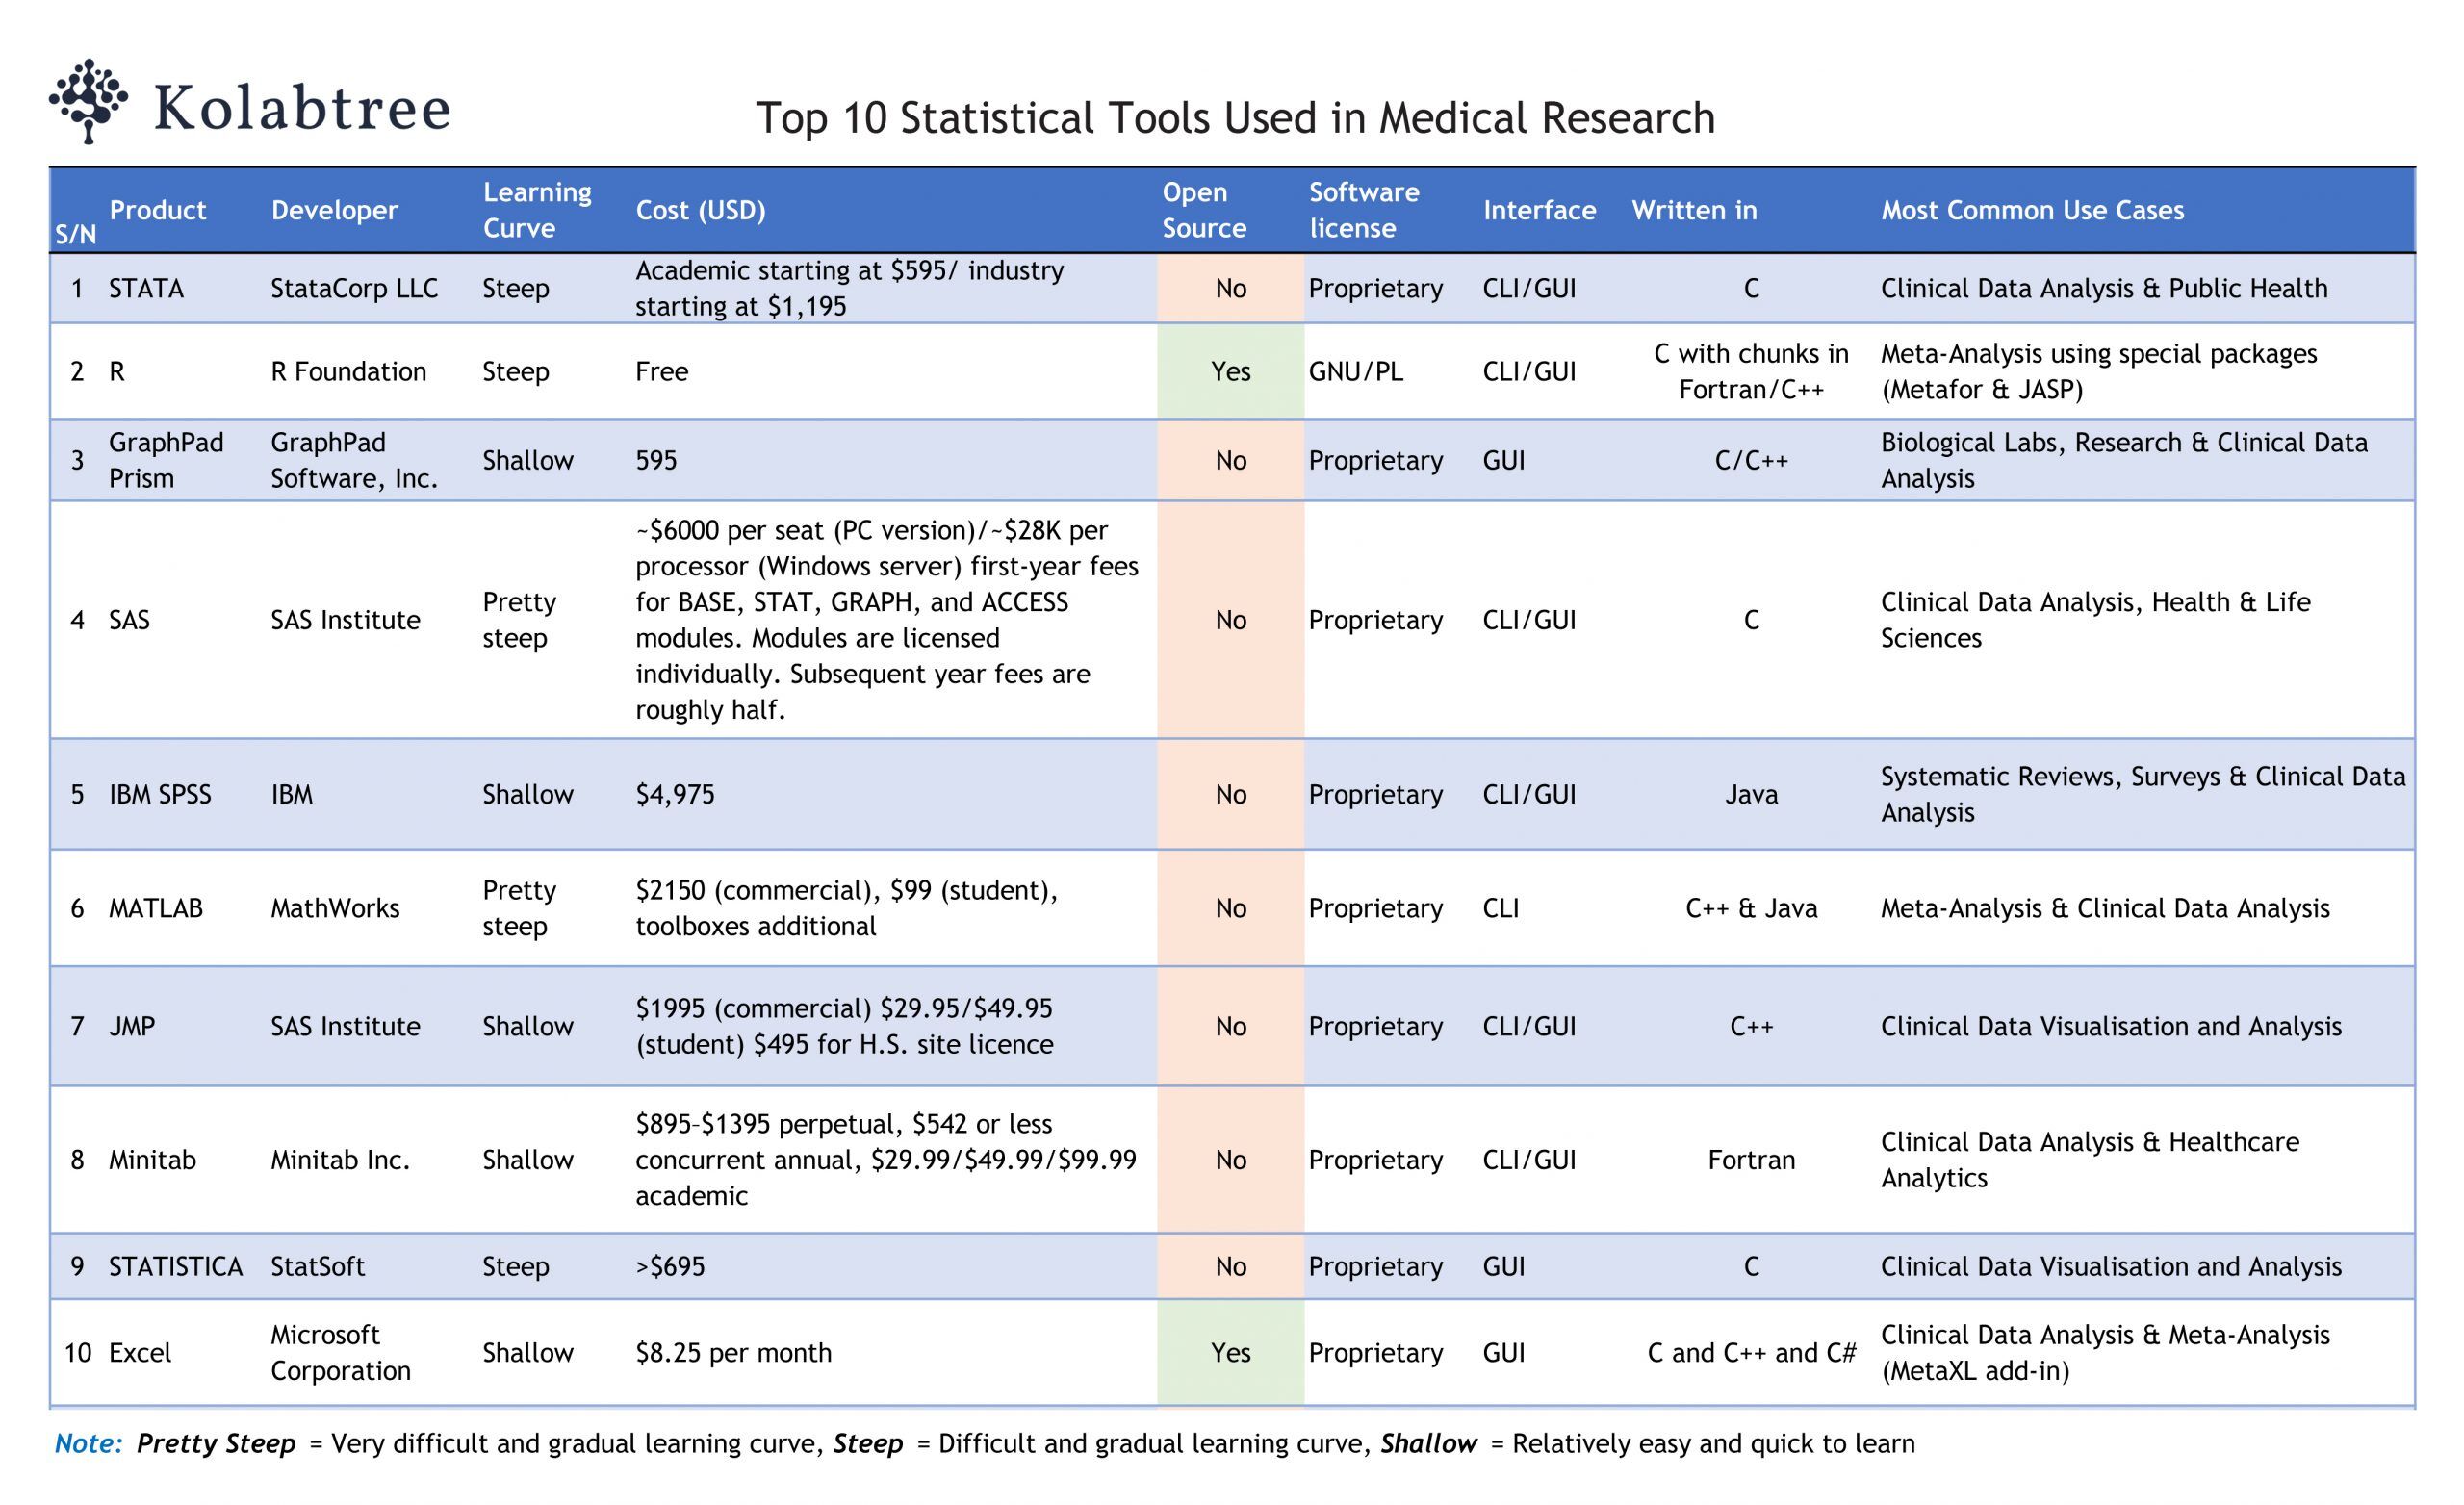
Most people wait until they have data in front of them before figuring out what test to run. That approach usually means a lot of backtracking, missed assumptions checks, or just picking whatever test is easiest rather than whatever is correct. A statistics planner exists to flip that order around. I've built and refined my own Top 10 Statistics Planner spreadsheet years ago because the available tools at the time either required paid software or made you fill out forms that took longer than the analysis itself. The basic concept is simple: you map out your study design upfront, then the planner tells you which test applies, what the assumptions are, how to check those assumptions, and what output to expect.Why a Top 10 Statistics Planner Makes Sense
The real problem isn't picking the wrong test after you see the data. It's collecting data without knowing whether your design can actually answer the question. Power analysis depends on effect size estimates, and if you haven't thought through your statistical test before running subjects, your sample size calculation is just a guess. Here is how I actually use the planner in practice:I start by writing down the research question as a one-sentence statement. Then I identify the variables: what is independent, what is dependent, and whether the design is between-subjects or within-subjects. From there I look at the measurement level of each variable. This determines the test family before anything else. The planner then routes you through a decision tree. Continuous dependent variable, one categorical independent variable with two groups? Independent samples t-test. Same setup but the groups are related? Paired samples t-test. More than two groups? One-way ANOVA. The tree catches most of the standard cases and flags when your situation falls outside the top ten list.
Building Your Own Version
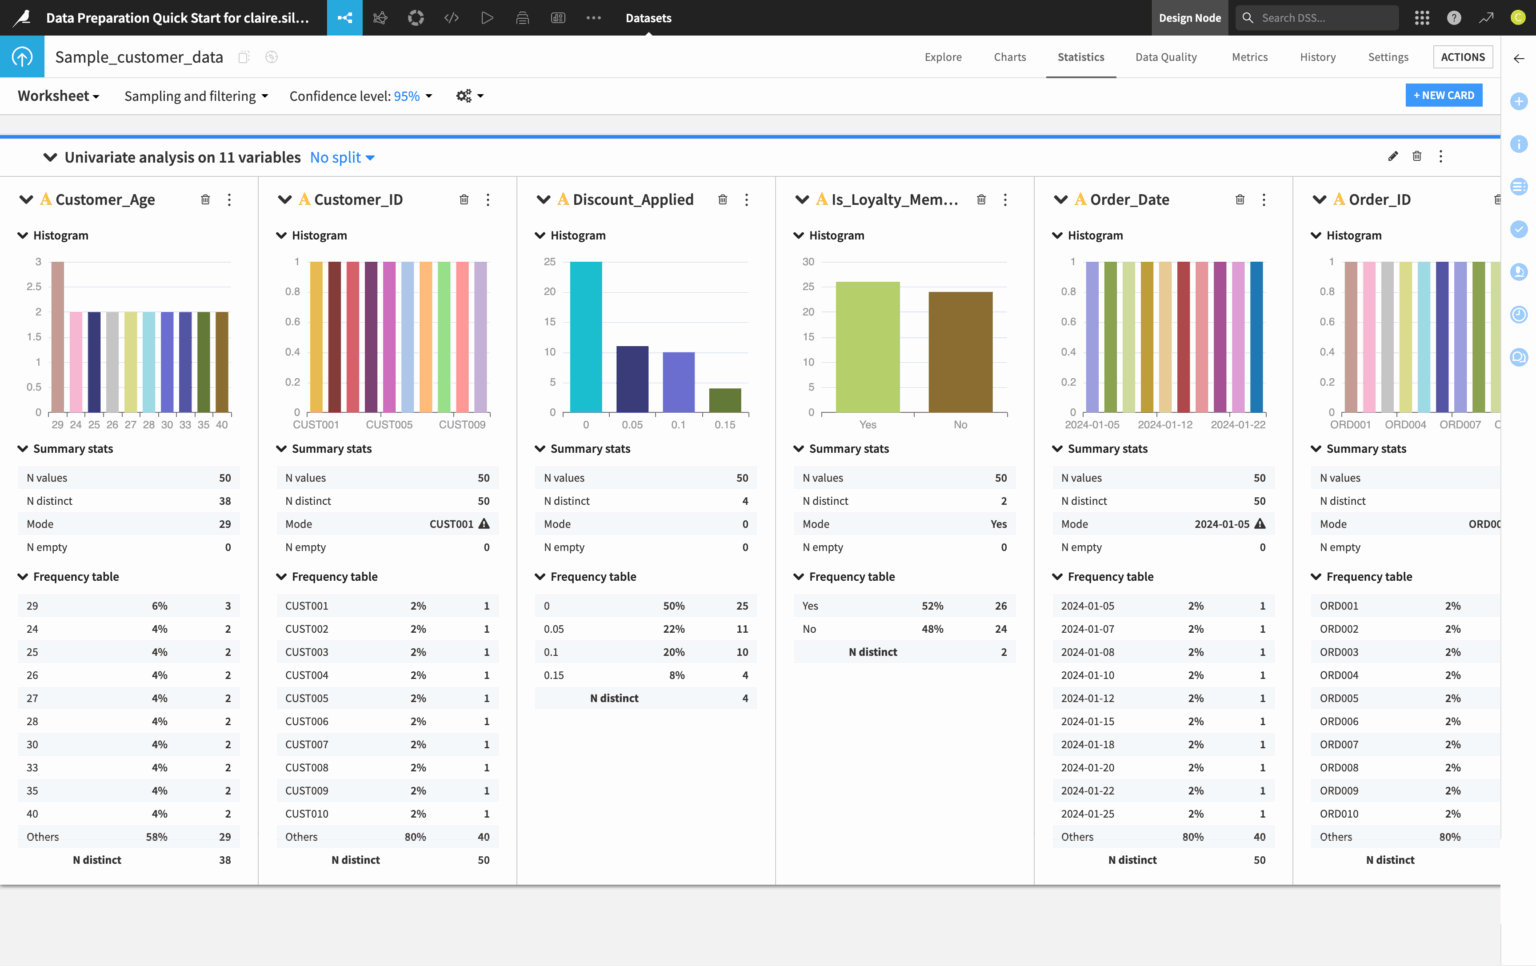
You do not need to buy anything for this. I keep mine as a Google Sheet with five main sections.The first section is a variable declaration table. Every variable gets a row with columns for name, measurement level (nominal, ordinal, interval, ratio), role (independent, dependent, covariate), and expected distribution shape. This sounds tedious but it saves you from realizing after data collection that you treated a Likert scale as interval when it is really ordinal. The second section is the test selection matrix. I list the common tests side by side with their assumption requirements. T-tests require independence, normality of the dependent variable, and homogeneity of variance for the independent version. ANOVA adds the same variance assumption across all groups. Mann-Whitney U and Kruskal-Wallis are the non-parametric alternatives when those assumptions break. The third section is where most people skip ahead and then regret it: the assumption checking protocol. For each test, I list the exact diagnostic steps. Shapiro-Wilk for normality. Levene's test for equal variances. VIF values if you are doing regression. These diagnostics need to happen before you run the main test, not after.