How to actually use top-down and bottom-up approaches in signal processing
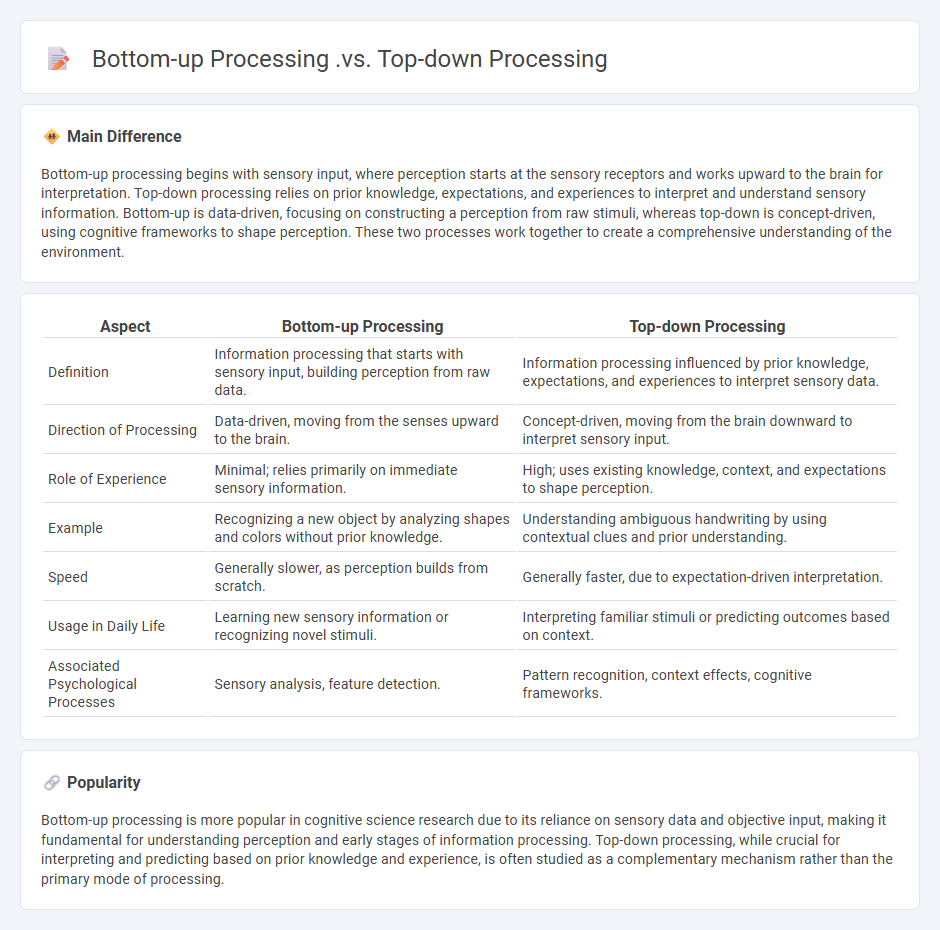
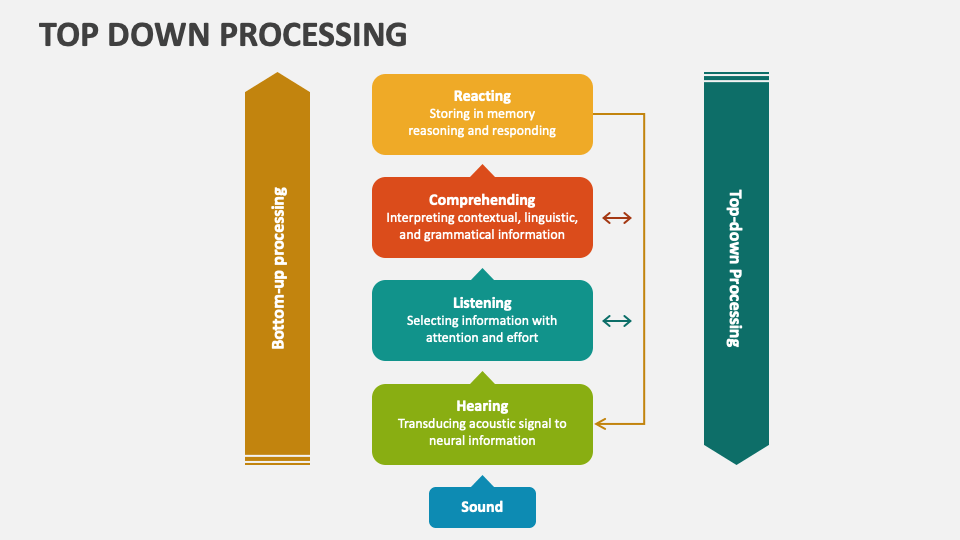
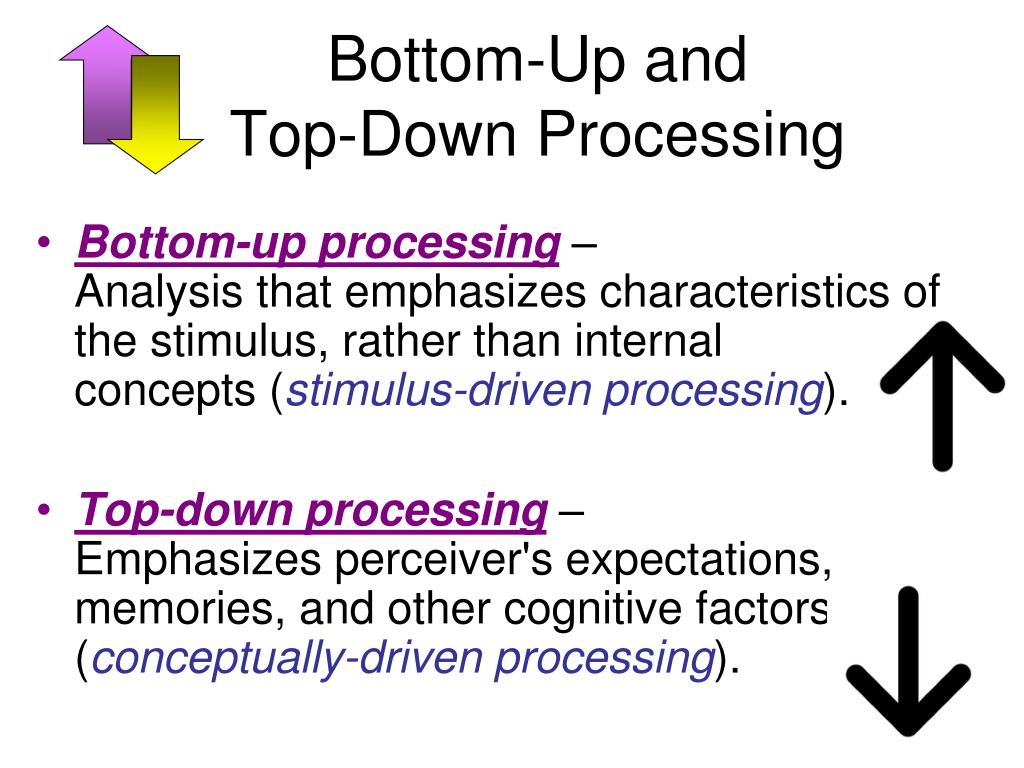
You run into this problem constantly when building recognition systems, whether you are working on audio classification, computer vision, or time-series anomaly detection. The two approaches are not just theory. They dictate the architecture of your pipeline and the quality of your final output. I spent about six months debugging a fault detection system where the model kept flagging normal equipment states as anomalies because the training data was skewed. That experience taught me more about top-down versus bottom-up processing than any textbook did. Bottom-up processing builds representations from raw sensory input upward through hierarchical feature extraction. You feed raw signals into a model and let the layers learn patterns without imposing any prior structure about what those patterns should mean. This is how a standard convolutional network operates. It detects edges, then textures, then shapes, then objects. Each layer abstracts further from the original input. Top-down processing works in reverse. You start with a high-level hypothesis or conceptual model and use that to interpret incoming data. Your prior expectations shape how you perceive and categorize what comes in. In a machine learning context, this looks like a model that incorporates domain knowledge, constraint-based reasoning, or generative frameworks that predict what the input should look like and compare reality against that prediction.
The key difference is directionality of influence. Bottom-up means the data drives interpretation. Top-down means your model drives interpretation. Most real systems blend both, but they rarely blend them well because the interaction is not trivial to design. I encountered a specific edge case that broke my understanding of how these two approaches interact. We were building a bearing fault diagnosis system that used accelerometer data from industrial motors. The bottom-up model, a simple CNN, achieved about 94 percent accuracy on the training distribution. But when we deployed it to a different factory with slightly different motor mounts and ambient vibration levels, accuracy dropped to 71 percent. The model had learned surface-level features from the training environment that did not generalize. It was overfitting to the specific noise floor and mounting resonance of our test setup. The workaround was not adding more data or increasing model capacity. It was restructuring the pipeline to incorporate top-down constraints from the physics of rotating machinery. I built a spectral prior that enforced known harmonic relationships between shaft frequency and its integer multiples. The model could no longer produce classifications based on spurious frequency patterns that violated basic mechanical constraints. Accuracy on the new factory data jumped to 89 percent. The system still underperformed compared to the training distribution, but it was now making errors for plausible reasons rather than arbitrary ones.
This is the counter-intuitive part that most people miss. Adding domain knowledge through top-down constraints does not always improve raw accuracy on benchmark datasets. Sometimes it makes things worse initially because the constraints restrict the hypothesis space too aggressively. But it dramatically improves robustness to distribution shifts, which is what actually matters in production. A model that is 94 percent accurate on familiar data but collapses on new data is worse than a model that is 89 percent accurate everywhere. Another thing beginners get wrong is assuming bottom-up processing scales linearly with data. It does not. Bottom-up models hit diminishing returns quickly once they learn the dominant patterns in your data. Adding another ten thousand samples to a CNN that already has clean, representative data often produces negligible gains. The model has already found the local optimum. This is why hybrid architectures exist in the first place. Top-down processing has its own severe limitations. It requires accurate domain knowledge to encode, and that knowledge is often incomplete or contested. If your top-down constraints are wrong, they systematically mislead the model in consistent ways that are hard to detect. A wrong physics model will make the same mistake across all inputs, producing confident but incorrect predictions. That is worse than random error because it creates false trust in the system. I have seen this happen repeatedly in medical imaging where the prior assumptions encoded in a system were based on population-level statistics that did not apply to individual patients.
Get the Full Details

Here is a practical breakdown of when each approach serves you better. Use bottom-up processing when you have large volumes of labeled data, the domain lacks well-established theoretical models, or you need to discover unexpected patterns that do not fit existing frameworks. Use top-down processing when domain knowledge is strong and well-validated, the operational environment has known constraints or failure modes, or you need the system to handle data distributions different from your training set. Most production systems need both, applied at different stages of the pipeline. The blend itself is the hard part. A common pattern is to use bottom-up extraction for initial feature generation and top-down reasoning for final decision making. Another pattern is to train the bottom-up component on raw data and then constrain its outputs with a top-down validator that checks predictions against known physical or logical rules. The validator does not change the model weights. It filters or corrects outputs after the fact. This post-hoc correction is simpler to implement but less powerful than joint optimization, which is the ideal but much harder to achieve. If you are implementing this yourself, start by mapping out where your domain knowledge enters the pipeline. Identify the assumptions you are making about the data and make them explicit. Write them down as constraints, priors, or validation rules. Then build the bottom-up component separately and measure its performance in isolation. Only combine them once you know how each part performs alone. Combining them blindly usually masks failures in both components.
The bottom line is that top-down and bottom-up processing are not competing philosophies. They are complementary strategies for handling different types of uncertainty. Bottom-up handles uncertainty about what patterns exist in the data. Top-down handles uncertainty about what those patterns mean. Get one wrong and your system will either be ungrounded or rigid. Get both working together and you have something that actually generalizes.