Tracking in ML Isn't Optional, It's Just Infrastructure Now
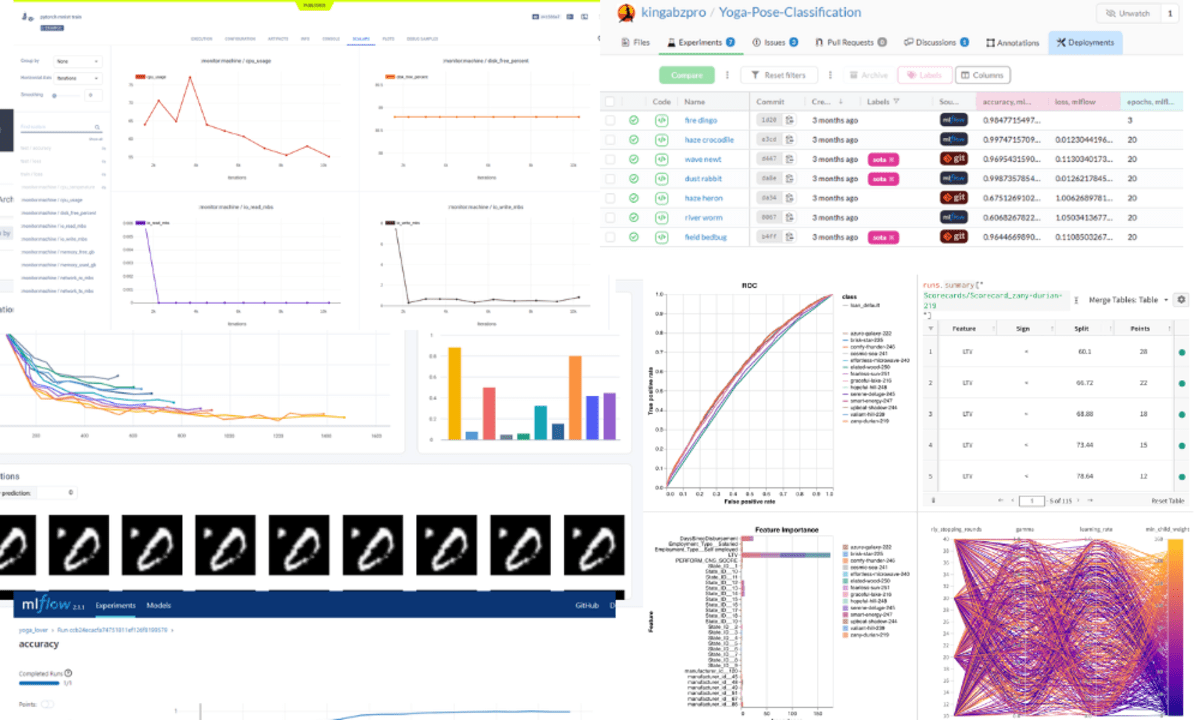
Most people I talk to treat experiment tracking as an afterthought. They train something, look at a printed accuracy number, and call it a day. That works until you have forty runs across three notebooks and can't remember which learning rate produced the best result. Then you hit a wall. A Tracker For Machine Learning Modern workflow stops that from happening. I set one up on a project last year where we were comparing transformer fine-tunes for a classification task. The team had been using CSV exports and mental notes. We spent six hours just trying to reconstruct which hyperparameters we'd used in the fifth run. That shouldn't have been necessary. Modern tracking tools let you log parameters, metrics, artifacts, and code version all in one place. The common stack looks like MLflow or Weights & Biases, though I've also used TensorBoard for quick visual work and Comet for multi-project organization. Pick one, commit to it, and don't treat it like a nice-to-have. It becomes the thing you reach for when you need to make any decision about a model.
Setting Up a Tracker For Machine Learning Modern
The setup itself is straightforward. Install the library, create an experiment, wrap your training loop with tracking calls, and push everything to a backend. That's the skeleton. The actual friction is in the details. I use MLflow as my default because it runs locally without an account, and it exports artifacts cleanly when I need to hand something off. The code looks like this: start a run, log_params, log_metrics, log_artifacts. Each epoch or validation step gets its metric logged. You do it in the loop, not after.
import mlflow

with mlflow.start_run():
    mlflow.log_params({"learning_rate": 3e-5, "batch_size": 32})
    for epoch in range(epochs):
        train_one_epoch()
        val_metrics = validate()
        mlflow.log_metrics(val_metrics, step=epoch)
        mlflow.log_artifact("model.pt")
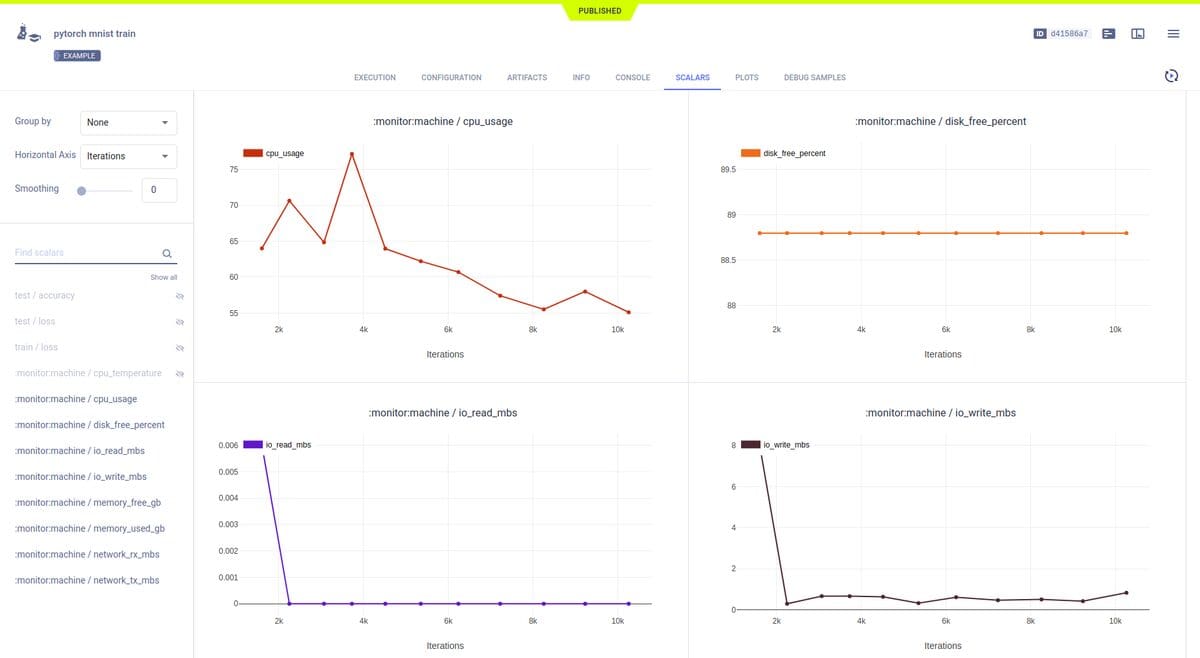
The tricky part most people miss is knowing what to log. You don't need everything, but you do need the things that make a difference later. Log the seed. Log the data split version if you change it. Log the architecture config, not just the final model file. Log validation curves alongside training curves. When you come back six months later, you'll be thankful. There are two use cases that matter more than the rest: comparing experiments and reproducing results. The first one is obvious. You run twenty variants and want to see which parameter combinations move the needle. The second one is less talked about and equally important. Someone asks you how you got a number. You open the tracker and show them the exact run. I've also found tracking useful for detecting drift. When you're monitoring deployed models, the same logging principles apply. Track input distributions, prediction spreads, and error rates over time. A sudden shift in the distribution of a feature is often more informative than a drop in accuracy by itself.
Get the Full Details
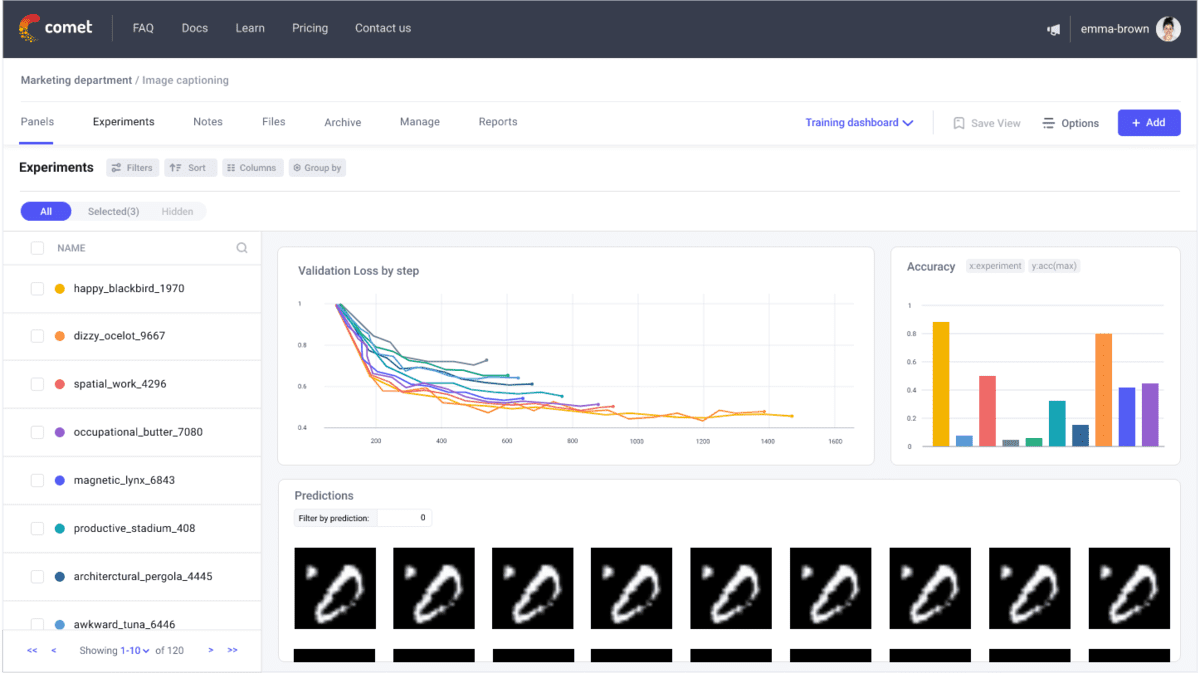
One edge case that annoyed me for a while: tracking nested experiments. When you're doing a sweep and each sweep contains sub-experiments, the flat run list gets messy fast. I solved it by using tags heavily. Tag every run with its sweep group, parameter set, and data version. The UI filtering becomes usable instead of painful.
Pitfalls to Avoid
The biggest mistake I see is logging too little, too late. People wait until the training script is "working" before adding tracking calls. By then they've already run half the experiments and are stuck guessing. Add logging from the first line. Another common issue is treating the tracker like a backup. It isn't. If you only save the final metrics and lose the code or data, the run entry is mostly useless. Keep the artifact path pointing to a permanent location. Don't store models inside temporary directories. Use versioned storage. There's also a tendency to over-track. You don't need to log every intermediate tensor. Log what someone would need to reproduce or evaluate the result. Everything else is noise.
What Tracking Tools Can't Do
These tools don't fix bad experiment design. If your evaluation metric is wrong, tracking won't help. If your data pipeline has a leak between train and test, the logged numbers will just be confidently wrong. Trackers make transparency easier, not correctness guaranteed. They also struggle with heavy compute coordination. If you're running hundreds of experiments across multiple GPUs or cloud instances, the logging overhead becomes real. I've seen batch jobs slow down noticeably when every step tried to write to a remote server. In those cases, batch the metric writes or use a local queue that syncs in bursts. That kept throughput reasonable without losing the data. If your team is small and the project is short-lived, a simple JSON log file might actually be enough. You don't always need the full platform. Just know when the complexity is worth it.
Getting Started
Start with one project. Pick one tracking tool and wire it into your training script. Log params, metrics, and at least one artifact. Use it for two weeks. Then add tags, sweeps, and whatever else your workflow demands. You'll figure out what you actually need faster than you'd expect. The ecosystem around this has matured enough that there's no excuse for not having some form of tracking in place. The alternatives are spending hours reconstructing past work or making decisions based on incomplete memory. I wouldn't go back to the old way even if I wanted to.