Getting Started With Tracker For Machine Learning Weekly
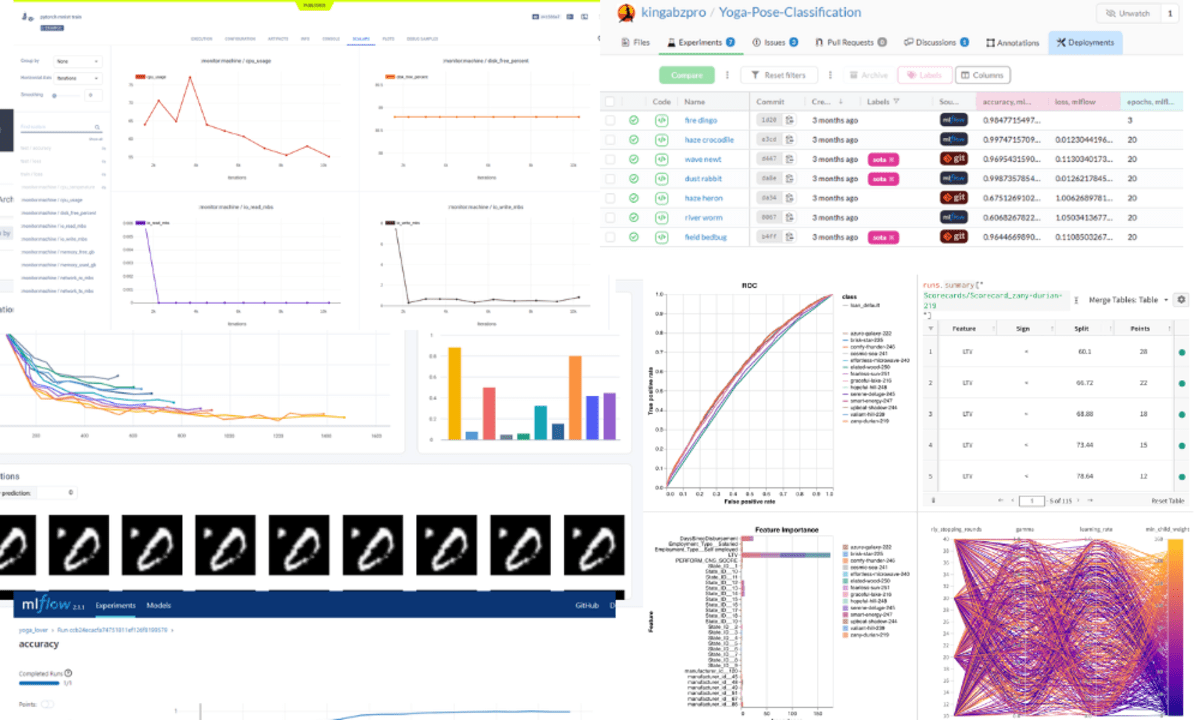
I first ran into Tracker For Machine Learning Weekly about two years ago when I was trying to keep track of model experiments across three different teams. The problem was basic: everyone was logging results in different formats, different places, and nobody could tell you which hyperparameters actually moved the needle. Someone shared the link and I thought it was just another newsletter, but it turned out to include a practical tracking component that was worth looking into. It's primarily a curated weekly publication covering developments in ML experimentation tracking, MLOps tooling, and model management. The "tracker" part refers to the way they aggregate and organize information about tools like Weights & Biases, MLflow, Neptune, and similar platforms rather than being a standalone software product itself. You subscribe, you get a weekly digest with links, tool comparisons, and practical write-ups from people who actually ship models. The value isn't in any single post. It's in the patterns you start noticing across weeks. I learned more about experiment design pitfalls from reading their archives than from any single documentation page.
How to Get Started Using It
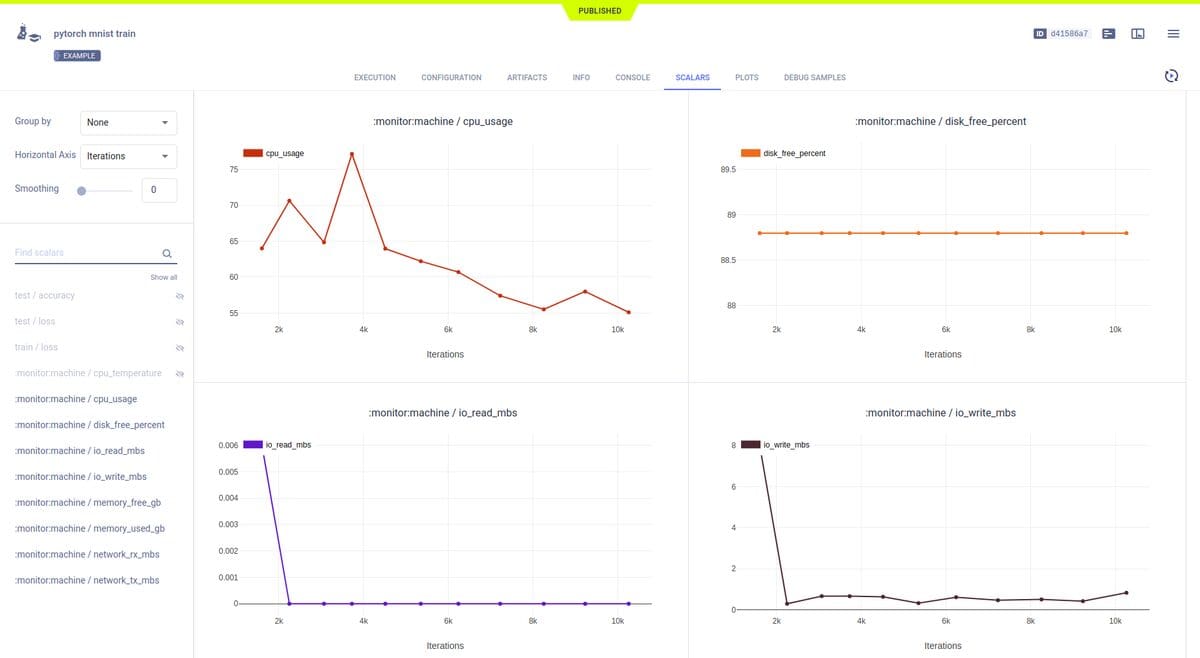
You can find it by searching for Tracker For Machine Learning Weekly directly. The subscription page is straightforward. They have both a free tier and a paid tier. The free tier gives you the weekly email and access to the public archive. The paid tier includes earlier access to tool reviews and deeper comparison charts. My advice on getting value out of it: don't just read passively. When they review a tool like MLflow or ClearML, open that tool and follow along. Run through their quickstart. Most people never do and then wonder why they can't adopt the practices they read about. I set aside twenty minutes every Sunday to actually test whatever tool they highlighted that week. That's where the learning happens.
A Problem I Ran Into
There was a specific issue I hit about six months ago that isn't covered in any guide. I was tracking experiments for a computer vision project and needed to correlate model performance with training infrastructure costs. The weekly covered a few different cost-tracking integrations but none of them worked cleanly with our setup, which used custom Kubernetes pods with spot instances and dynamic pricing. Every time I tried to pipe our cost data into the tracking dashboard, timestamps desynchronized because our cluster nodes were spinning up and down too frequently. The fix was ugly but effective. I wrote a simple script that batched our cost records and aligned them to experiment IDs using a fuzzy timestamp match with a fifteen-minute tolerance window. It added about forty-five minutes to our workflow but saved us from losing a week of cost correlation data. One thing that kept coming up and initially sounded wrong: tracking fewer experiments often produces better models than tracking more. I resisted this because I thought more data points meant more insight. What actually happened is that when you constrain yourself to under fifty tracked experiments, you start designing experiments with real questions instead of throwing everything at the wall. Each experiment gets a clear hypothesis. The signal-to-noise ratio improves dramatically. This took me about three months to accept empirically after our team accidentally deleted two weeks of poorly-structured run data and our best model came from one of the remaining clean runs. Another thing: the best tracking setup is the one your team will actually use consistently. I've seen teams implement elaborate MLflow deployments with custom dashboards and automated metric dashboards that ended up unused because the onboarding friction was too high. A simpler setup that gets adopted beats a complex one that collects dust every time.
Get the Full Details
When It Doesn't Help
This isn't a comprehensive solution for every tracking problem. If you're working with extremely large-scale distributed training across multiple cloud providers with mixed GPU types, the weekly's recommendations tend to skew toward mid-size teams. The tool comparisons assume relatively standard setups. If you're running anything outside the usual PyTorch or TensorFlow pipelines, you'll find fewer relevant posts. There's also a lag between when a tool updates and when it gets reviewed, usually about two to three weeks. You won't be on the bleeding edge of new feature announcements. If you need real-time experiment monitoring at scale, you're better off looking directly at dedicated platforms rather than relying on the weekly digest. This is more of a learning and awareness resource than an operational one. Still, for anyone building models and trying to stay current on how other people are tracking, organizing, and shipping them, it's one of the more practical subscriptions I've found. The archive alone is worth browsing through, even without subscribing. I spend maybe ten minutes a week on it and it consistently surfaces something useful.