What actually moves sites fast right now
The word viral in web development doesn't mean what marketing teams think it means. It isn't about aesthetics that get shared. It is about technical decisions that let a site survive a sudden traffic spike without collapsing. Most developers I talk to still build for normal traffic and then watch their infrastructure fail when a post hits a major feed. I run a few small projects and consult on bigger ones occasionally. The pattern is always the same. Someone builds something beautiful, gets mentioned on a platform like Hacker News or X, and their server dies within twelve minutes. The architecture was never designed for that. Viral web development is really infrastructure work disguised as design work. You plan for the wrong thing. The right thing to plan for is a traffic curve that goes from fifty visitors an hour to fifty thousand in under an hour.
The practical setup
Here is what I actually do before I ship anything that might attract attention. This is not theoretical. I have been through this at least six times across different projects. Step one: static everything that can be static. If a page does not require a database call to render, make it static. Use something like Next.js with static export, Vite build output, or just plain HTML served from a CDN. A static file served from Cloudflare or similar costs almost nothing and handles virtually unlimited requests. A Node server hitting a database does not scale the same way. Step two: edge caching aggressively. Set cache headers that actually mean something. Public, max-age=3600, immutable for assets. For pages, use stale-while-revalidate. The browser and CDN serve the cached version while the origin fetches a fresh copy in the background. This alone kept my project alive during a spike last year. The site rendered from cache while the origin quietly updated behind the scenes. Zero user-facing errors.
Step three: queue everything async. Comments, analytics, form submissions, newsletter signups. None of this needs to happen synchronously when the page loads. I use a simple message queue backed by something like Redis or even AWS SQS. The page renders, the interaction gets queued, and a worker processes it afterward. When traffic spikes, the queue absorbs the burst. Your database does not feel the spike. Step four: pre-warm your origin. This is the part most people skip. Before you know traffic is coming, hit your origin server with requests to populate caches and connections. Cold origins take longer to respond to the first request. A prewarmed origin responds instantly because the warm-up work is already done. Step five: set up alerts that actually matter. Not revenue alerts. Latency percentiles. P99 response time over 500 milliseconds should trigger a page. Memory usage on your origin. Active connection count. Your alerts should wake you up when the system is stressed, not when it is already broken.
Get the Full Details
A real problem I ran into
Last year I shipped a small tool that got picked up on a major subreddit. Traffic went from around two hundred daily users to roughly eighty thousand in about forty minutes. My CDN cached the homepage perfectly. The API layer did not. The problem was a specific edge case with dynamic URL paths. The CDN was configured to cache based on the path, but my API endpoints used query parameters that varied wildly. Every unique query parameter became a cache miss. I had maybe two thousand distinct URLs being requested simultaneously, and each one hit my origin database directly. The connection pool exhausted within six minutes. The database locked up. The entire app became unresponsive. The workaround was not pretty but it worked. I wrote a small middleware layer that normalized the query parameters into a cache-friendly key before they reached the origin. Then I set a shorter max-age on those responses, maybe sixty seconds, and used a CDN that supports cache by response code and status. I also bumped the connection pool size and added a request queuing mechanism that rejected excess requests with a 503 instead of letting them pile up and crash the database. The 503 responses were cached by the CDN too, which meant repeated requests for the same endpoint hit the cache rather than the origin. Traffic held at about forty thousand concurrent users for three hours with zero downtime after the fix went live.
Counter-intuitive things you should know
Adding more server capacity usually makes viral traffic problems worse, not better. A larger server attracts more requests because it responds quickly. When the spike hits, the bigger server just dies faster and takes more users down with it. The better approach is to absorb the spike upstream at the CDN level and let the origin handle what it can gracefully. Degradation is acceptable. Total failure is not. Another thing beginners miss: CDN cache configuration matters more than your application code during a viral event. I have seen sites with complex server-side logic survive because the CDN was caching the entire rendered page. I have also seen trivial applications crash because the CDN was bypassed for every request. Check your cache HIT rate in your CDN dashboard daily. If it is below 95 percent during normal traffic, you will have serious problems during a spike.
Trends Viral Web Development and what to watch
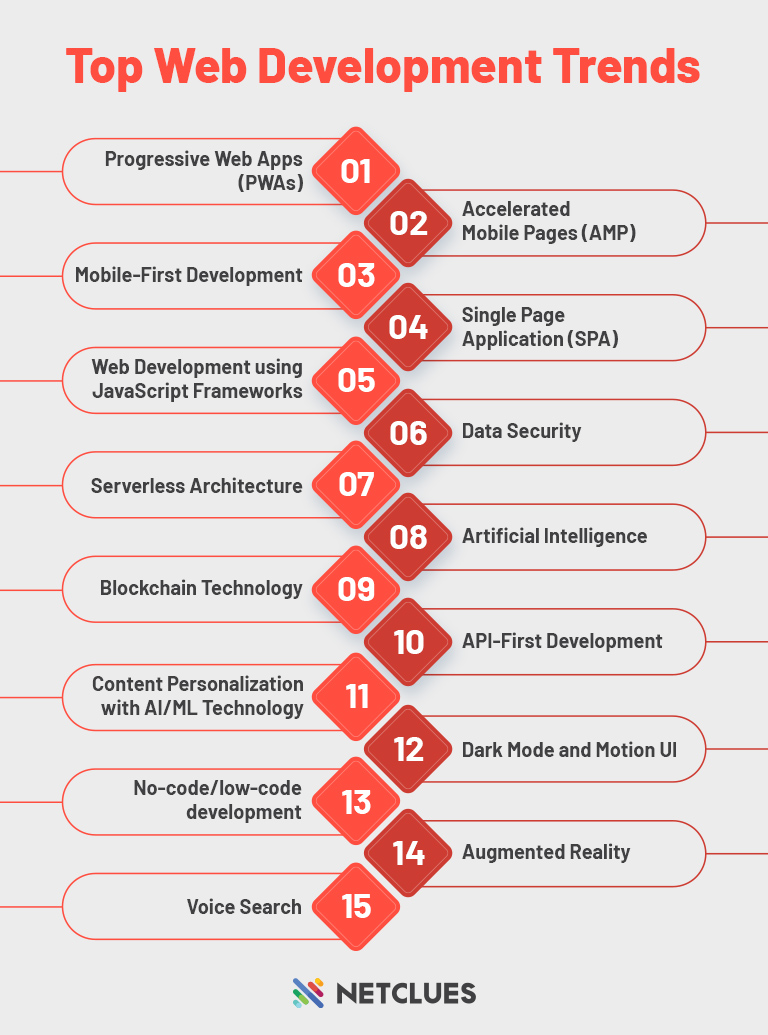
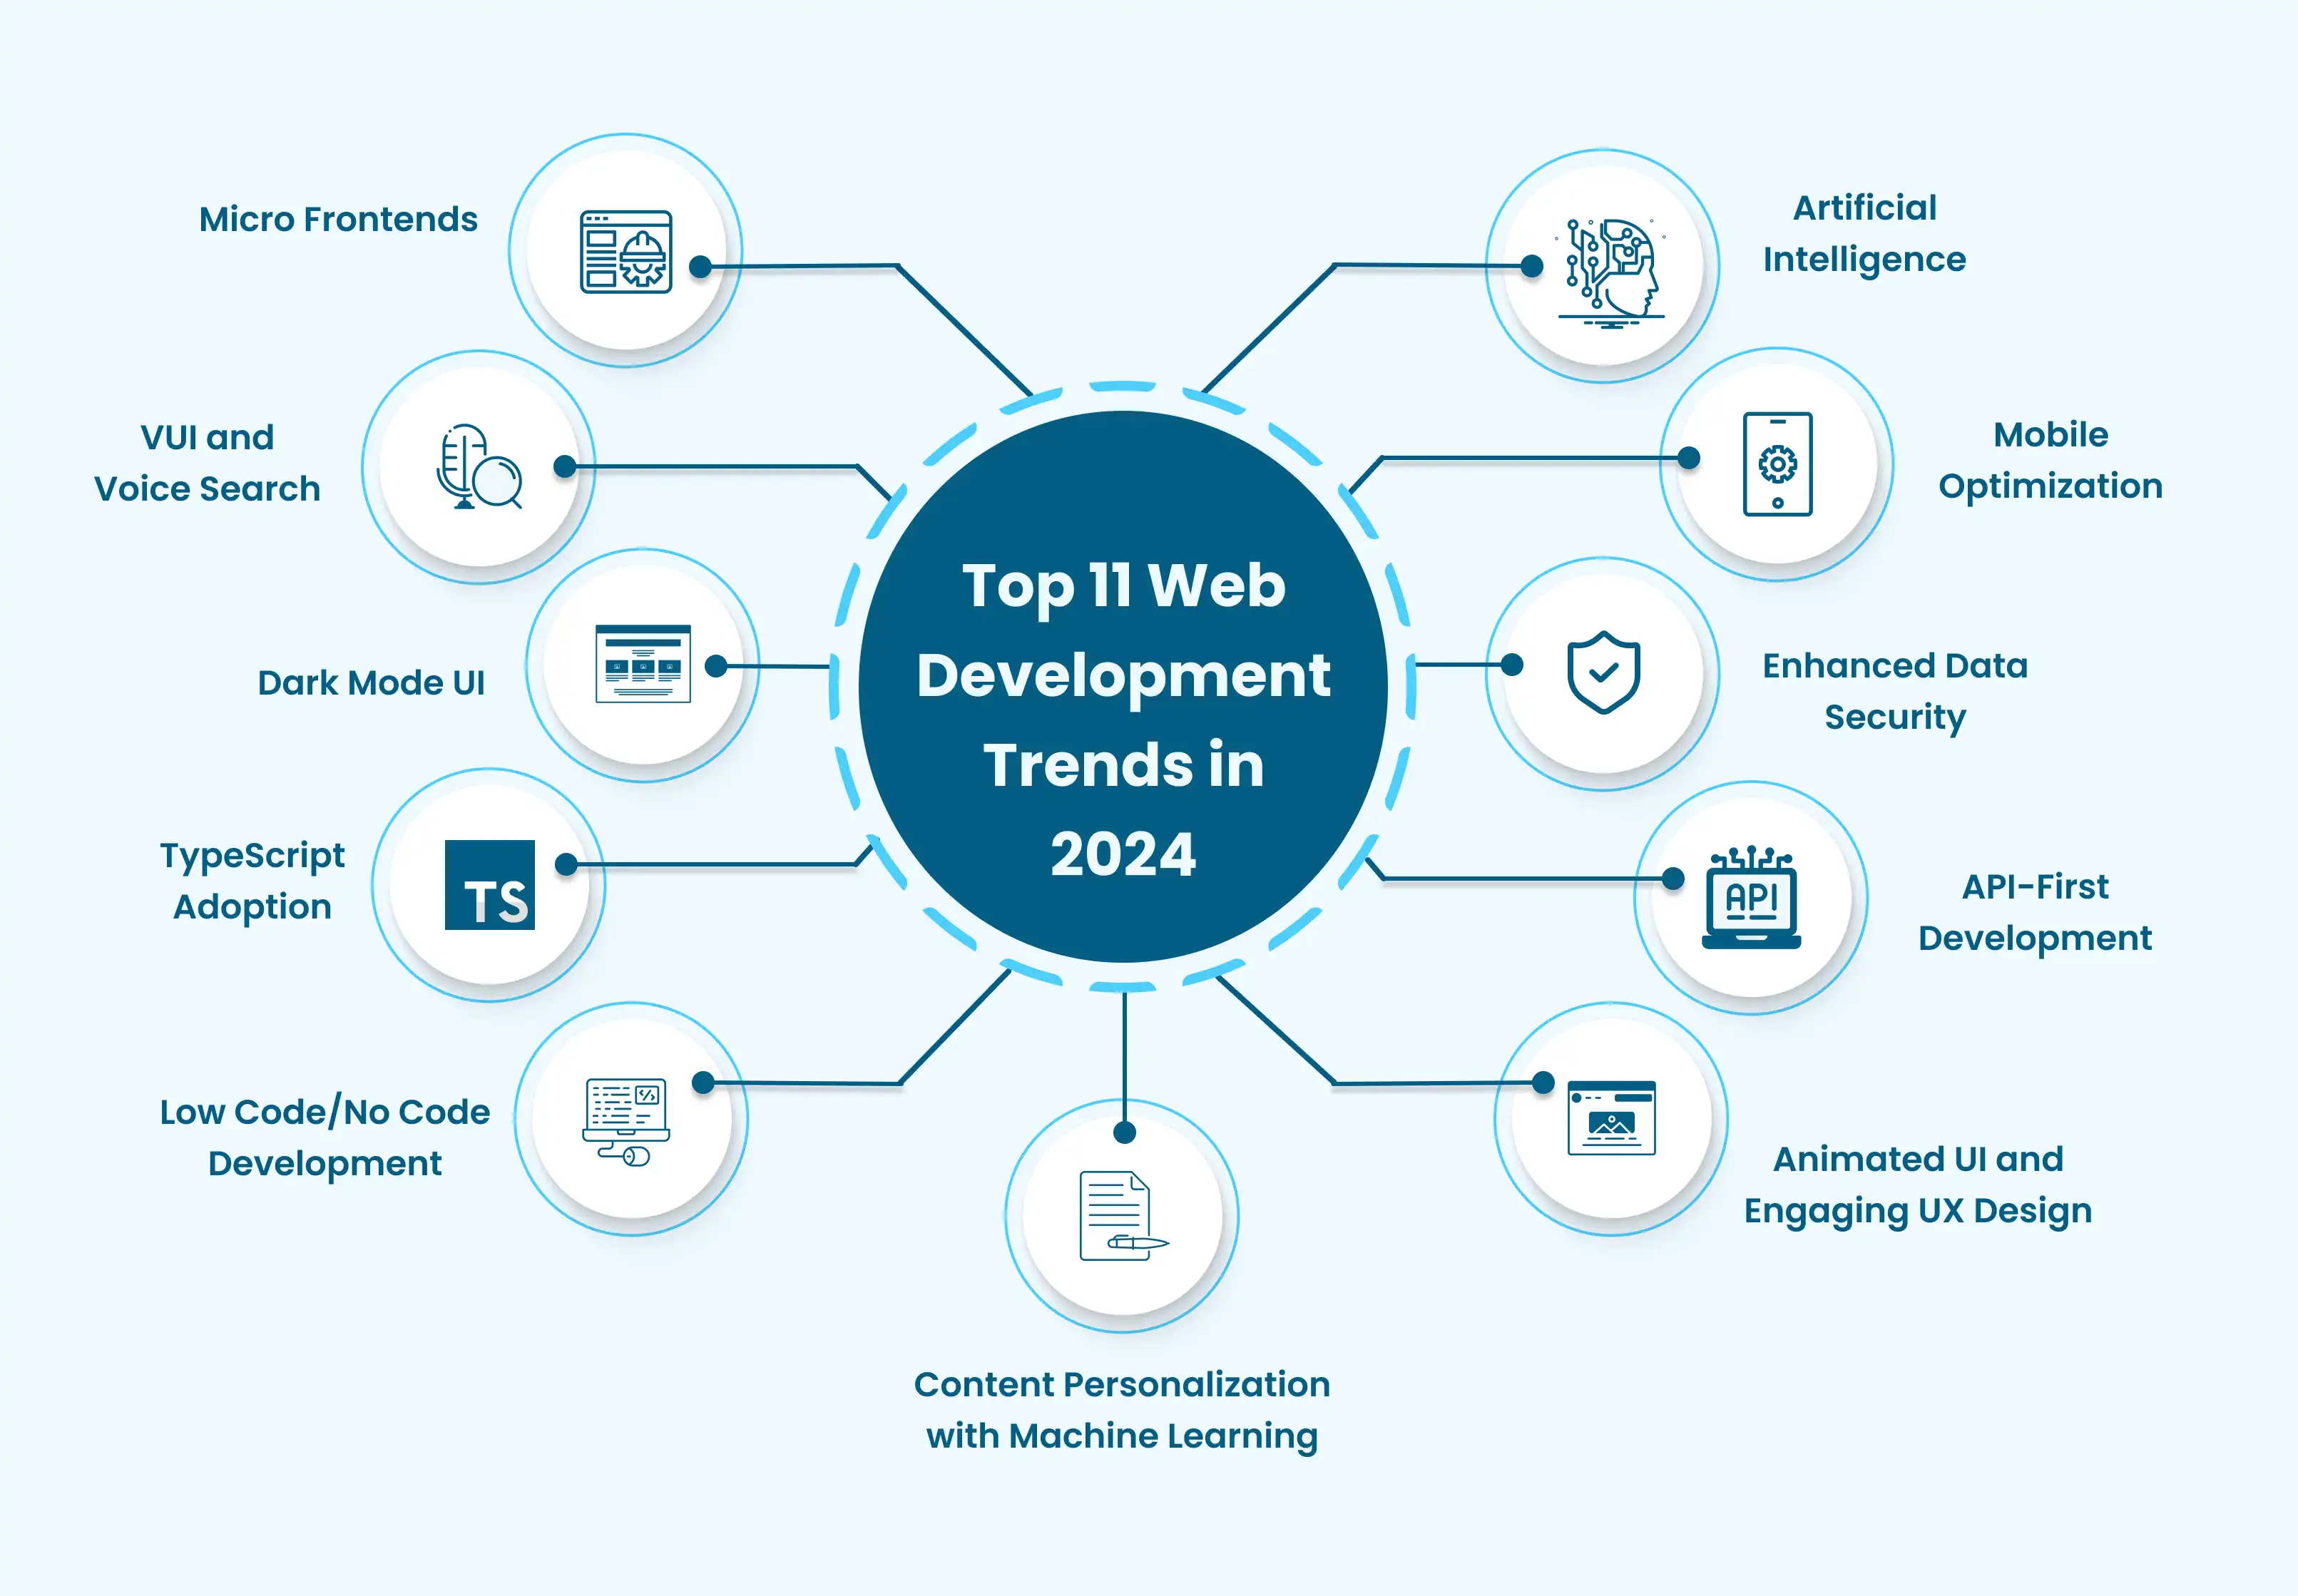
The current direction in Trends Viral Web Development leans hard toward edge computing. Platforms like Cloudflare Workers, Vercel Edge Functions, and similar services let you run logic closer to the user without hitting a central origin. This reduces latency and spreads the load. The tradeoff is that edge environments have memory and execution time limits. You cannot run heavy database queries or long computations there. Use them for routing, caching decisions, and lightweight transforms. Push the heavy lifting back to the origin or a separate worker. Another trend is incremental static regeneration. Instead of rebuilding your entire site when content changes, you regenerate individual pages in the background. This keeps your site fast and available while content updates flow in. The downside is that regenerated pages might serve slightly stale content for a few seconds. Usually acceptable. Sometimes not, depending on what you are building.
When this approach fails
These techniques do not help if your core product itself is the bottleneck. If every request requires a unique database query that takes two seconds to complete, no amount of caching or CDN configuration will save you. You need to optimize the query or redesign the data model. Caching is a bandage, not a solution for bad database design. Static and edge approaches also struggle with personalized content. If your site shows different content to every user based on their account, session, or location, you cannot cache aggressively. In those cases, the best you can do is cache what you can and use a tiered CDN with origin shielding to reduce the load on your infrastructure. It still will not scale infinitely, but it buys you breathing room. I would also warn against relying entirely on managed hosting platforms for viral events. They work fine until they do not. Their autoscaling has limits and sometimes introduces its own delays. Having a fallback plan, even if it is just a static HTML page that says we are experiencing high demand, is better than a white screen of death. I keep a maintenance mode template ready in my repo for exactly this reason. It takes thirty seconds to deploy and saves reputations.
The practical takeaway is straightforward. Build for the spike before it happens. Cache aggressively at the edge. Queue everything that can wait. Monitor the right metrics. And accept that some degradation is normal during extreme traffic. Your goal is to stay available, not to perform perfectly when ten thousand people visit at once.