Most project management failures aren't about tools
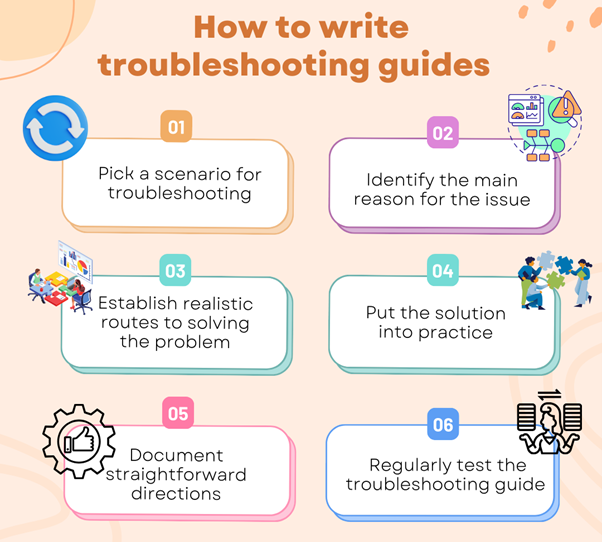
I spent seven years running engineering projects before I figured out that the real problem is almost never your Gantt chart software. It's communication gaps, scope drift, and people being vague about timelines. The troubleshooting approach you need is systematic because throwing more meetings at a broken process doesn't fix it. A Troubleshooting Guide For Project Management Tips And Tricks works best when you treat each symptom independently. You don't fix everything at once. You isolate the breakdown, trace it to its source, and apply one correction. Then you move to the next issue. Multi-variable debugging in project management is how you end up with three new problems for every one you solve.
Identifying the actual symptom
Projects fail for visible reasons that mask invisible root causes. Your project is two weeks late. That's the symptom. The cause could be unclear requirements from stakeholders, a bottleneck in your QA team, underestimated dependencies between subsystems, or people silently avoiding you because they know the status is bad. Start by mapping what you actually know versus what you assume. I learned this the hard way on a migration project where every milestone slipped. We blamed resource constraints for months. The real issue was that three key stakeholders had conflicting definitions of what "done" meant for the deliverable. We re-aligned those definitions in a single two-hour session and the project recovered eight of those nine lost weeks within the following month. No additional headcount. No new tools. Just clarity.
Scope creep detection and containment
Scope creep is the most common project killer and the one people do the least about. It rarely arrives as a dramatic addition to the requirements document. It arrives as casual requests whispered in Slack channels, hallway conversations, and "while we're at it" moments during status meetings. By the time you notice the timeline has drifted, you've absorbed twelve small changes that individually seemed reasonable. The practical workaround is a change log that lives somewhere visible and is treated as a formal gate. Every request, no matter how small, gets logged with an estimated impact on schedule and cost before anyone starts working on it. Most requests die at that step because stakeholders see the tradeoff. When they insist anyway, you have a paper trail that prevents blame-shifting later. This approach isn't perfect. It adds administrative overhead and can frustrate teams who want speed over procedure. For fast-moving startups with under fifty people, a lightweight version works better than a formal system. Record changes in a shared doc with impact notes rather than routing through a change control board. The principle stays the same even if the ceremony is lighter.
Get the Full Details
Communication breakdown patterns
There are three main types of communication failure in project management and each requires a different fix. Information hoarding happens when team members don't share progress because they're waiting for more certainty before reporting. This creates the illusion that everything is on track until it isn't. The fix is structured check-ins with a standard template that forces early visibility of blockers. Even an incomplete status is better than a clean status that turns out to be wrong. Information overload is the opposite problem. Everyone gets updated on everything and nothing gets attention. I recommend segmenting your audience into three tiers: decision-makers get weekly summaries with only what requires action, team leads get bi-weekly updates including dependencies, and individual contributors get daily stand-ups focused on their immediate work. This usually reduces meeting load by forty to sixty percent while improving signal quality.
Assumption drift occurs when team members interpret requirements differently without realizing it. The classic example is a feature described as "fast" where engineering optimized for startup speed and the product team meant sustained throughput under load. This gap doesn't show up until testing. Prevent it by converting every qualitative requirement into a measurable one during planning. "Fast" becomes "under two hundred milliseconds p95 latency." Specificity costs nothing up front and saves weeks of rework.
Resource allocation mistakes
Resource planning most often fails because people estimate based on best-case scenarios rather than realistic ones. A developer who can complete a task in three days in ideal conditions will realistically need five to seven days when accounting for meetings, context switching, code review cycles, and unexpected blockers. The standard adjustment is multiplying optimistic estimates by two or three, not because people are slow, but because optimal conditions almost never exist. I ran into a specific edge case on a product launch where our lead backend engineer was the sole owner of three critical subsystems. She was the fastest person for the job, so we put all the work on her. Three weeks before launch, she called in sick for five days and every timeline collapsed. The workaround I use now is a mandatory knowledge transfer rule: no single person owns more than two critical components without a designated backup who has completed at least one full cycle through that work. It adds upfront training time but prevents single-point-of-failure risk that can derail entire projects.

Tool selection and over-reliance
Project management tools can help or hurt depending on how you use them. Jira, Asana, Monday, ClickUp, Linear, and others all have similar core functions. The tool itself rarely causes project failure. What causes problems is treating the tool as the project management system instead of a reflection of your actual process. If your process is messy, a tool just makes the mess more visible and gives you a false sense of control. I've seen teams spend more time configuring dashboards and automation rules than doing actual project management work. One team I worked with spent three weeks setting up custom fields, workflows, and reporting templates in Jira before they ever tried to run a sprint. The configuration never matched their actual process and they reverted to spreadsheets within a month. The fix is simpler: use the default workflow for two weeks, identify what's actually broken, then customize only those specific gaps. There are also tools that don't scale well. Small teams with simple projects often adopt enterprise-grade tools that introduce unnecessary complexity. A two-person team managing a straightforward website redesign doesn't need enterprise risk management modules. The overhead of maintaining process artifacts that nobody reads defeats the purpose. Match tool complexity to team size and project complexity. Err on the side of less structure.
Risk management that actually works
Most risk registers are exercise in futility. They list generic risks like "key personnel leaving" or "scope changes" without assigning probabilities or mitigation actions. A risk register with no numbers attached is just a list of worries. The useful version assigns a probability percentage and a potential impact score to each identified risk, then specifies a concrete mitigation step for anything above a threshold. For example, instead of writing "developer turnover is a risk," you write "there is a thirty percent probability that our lead API developer leaves within the next quarter based on industry turnover rates and recent budget discussions, which would delay the backend timeline by approximately three weeks. Mitigation: cross-train a secondary developer on the API module within the next two sprints." That's actionable. Generic risk lists are not. Even this approach has limitations. You can't predict black swan events. Supply chain disruptions, regulatory changes, and natural disasters fall outside reasonable forecasting. For those, the mitigation is financial or operational buffers rather than prediction. Maintaining a two-week schedule buffer on critical path items absorbs a significant portion of unpredictable delays without requiring detailed scenario planning for every possibility.
When to escalate versus self-correct
One of the hardest judgment calls in project management is knowing when to escalate a problem to leadership and when to try solving it yourself. Escalating too early signals inability to handle responsibility. Not escalating until it's too late wastes organizational resources and damages credibility. The heuristic I use is straightforward: if the problem is within my sphere of influence and I can resolve it without consuming more than five percent of remaining project resources, I handle it. If it requires authority I don't have or affects more than one department, I escalate immediately with options rather than just problems. Escalating with options means presenting the situation, the recommended course of action, and at least one alternative with tradeoffs clearly stated. Decision-makers don't need to be told something is wrong. They need to know what you're asking them to decide and what each choice costs. This usually gets faster responses because it reduces the cognitive load on whoever needs to make the call.
Retrospectives that produce results
Project retrospectives are widely considered one of the most underutilized improvement mechanisms in project management. Most teams run them as compliance exercises where everyone shares vague feelings and nothing changes. The version that actually moves the needle focuses on exactly three things: what specifically went wrong, why it went wrong, and what concrete change will prevent it from recurring. Each identified issue gets an owner and a deadline for the corrective action. I keep a running improvement log across all projects. When the same issue appears in multiple retrospectives without a sustainable fix, it signals a systemic problem rather than a one-time incident. Systemic issues require process changes, not repeated reminders. A pattern I've seen multiple times is recurring deadline misses caused by the same dependency handoff between teams. Individual reminders to communicate better don't fix this. A revised handoff checklist with explicit acceptance criteria does. Some projects don't need retrospectives if they're short enough that lessons don't have time to compound. A two-week internal tool update where everything goes as planned is fine to skip. But if a project runs longer than six weeks or involves more than three teams, skipping the retrospective is leaving improvement on the table. The time investment is typically two to three hours and can reduce similar effort on the next project by fifteen to twenty-five percent if you act on what you learn.
The core insight most people miss is that project management troubleshooting is diagnostic work, not creative work. You don't need brilliant solutions. You need systematic observation and honest data. The projects that consistently succeed belong to people who ask uncomfortable questions early, document what they find, and adjust course before small problems become structural failures.