Getting Your Incident List Actually Useful Instead of Just Another Spreadsheet
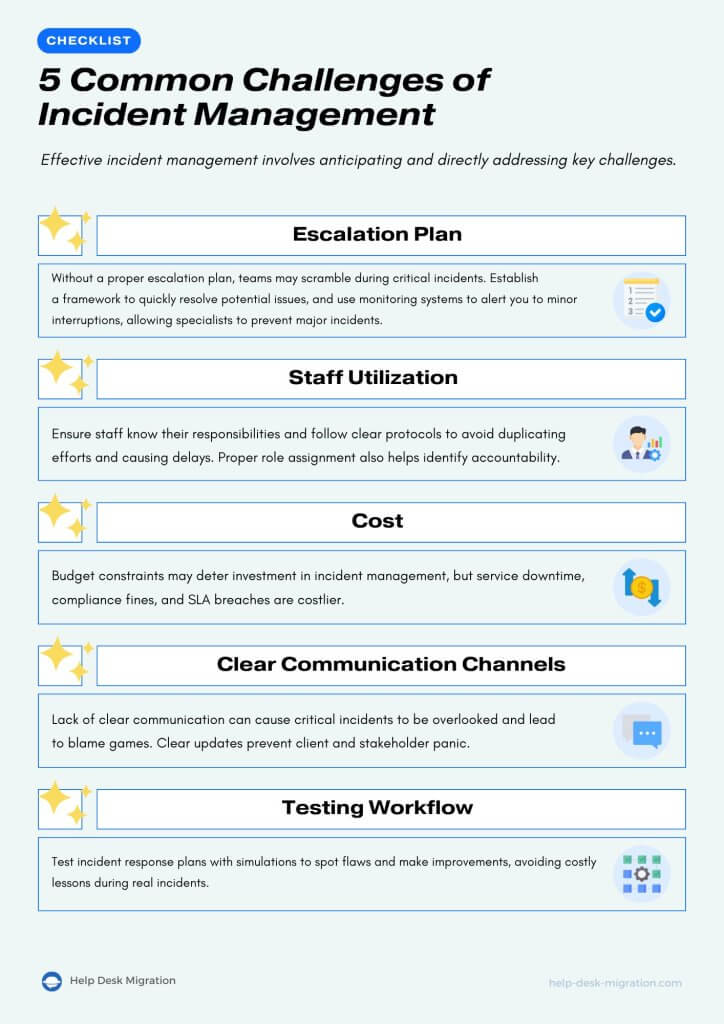
Most people build their Type A List Of Potential Incident Management Issues and then forget about it. I have seen it repeatedly across companies of every size, and it always ends the same way. The list sits in a shared drive or gets attached to a wiki page nobody reads after the first week. Here is how to actually make it work.The core approach is simple. You start by categorizing incidents by their nature rather than by which team owns them. The "Type A" designation is just one bucket in a larger taxonomy. It typically covers external-facing disruptions that directly impact customers or revenue. That means outages, data breaches, payment failures, third-party dependency collapse, and public-facing infrastructure degradation. The rest of the list covers Type B through Type D incidents, which are internal, low-severity, and procedural by comparison. Do not write this in a vacuum. Pull the last twelve months of your incident reports from PagerDuty, ServiceNow, Jira, or whatever tracking tool you actually use. I had to do this at a former employer where we tracked everything in Jira Service Management. The first thing I noticed was that over 60 percent of our "Type A" events were actually caused by misconfigured CI/CD pipelines pushing bad releases, not by the usual suspects like cloud provider outages. That changed the entire shape of the list. Start by listing every distinct failure mode you have experienced. Group them by root cause category. Then assign a severity score based on two axes: customer visibility and revenue impact. A partial API degradation affecting 12 percent of users during a holiday sale scores differently than a full outage that lasts forty minutes on a Tuesday morning when traffic is low. The matrix matters more than the raw description of the incident.
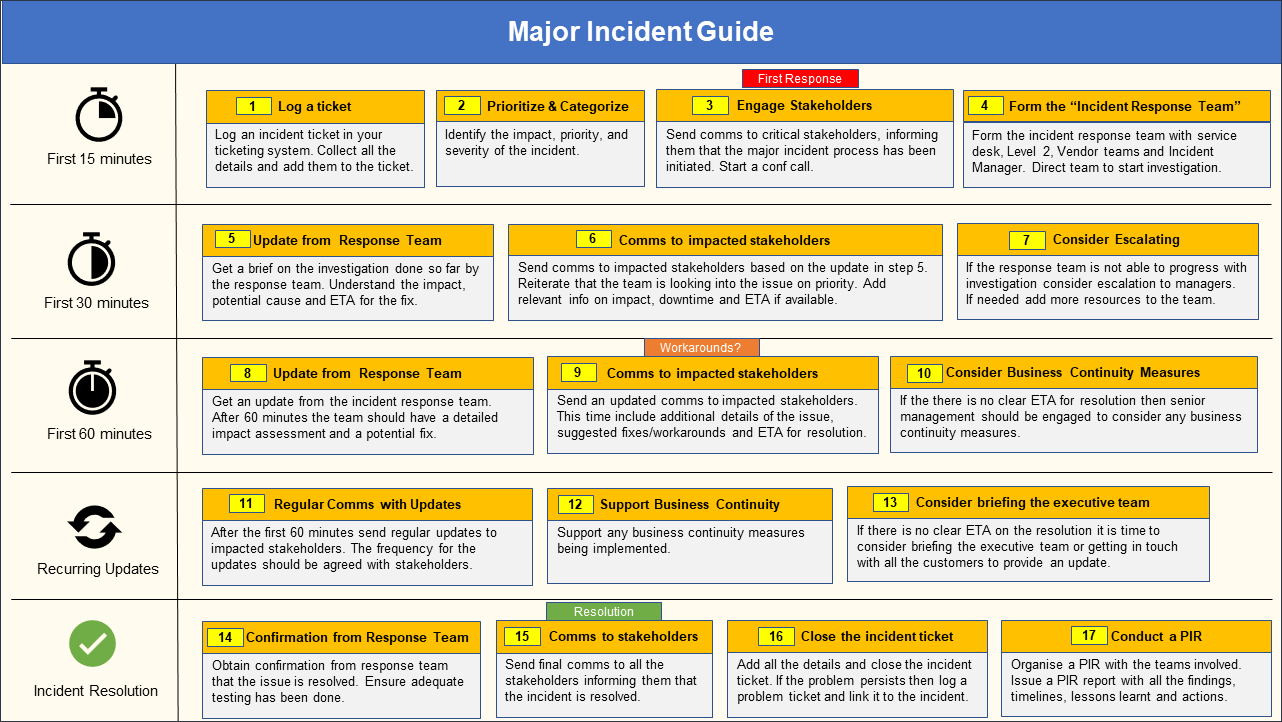
Once you have the grouped list, add response time targets. Type A incidents should trigger page-one-on-call within four minutes and require a war room within twelve. I know that sounds aggressive, but most companies I talk to have closer to thirty-minute page times and nobody seems to notice until it is too late. Set the target. Miss it sometimes. Adjust later. Here is a concrete example from my own work. We had a incident where a third-party identity provider went down for twenty-two minutes. Our type A list had that vendor flagged under "authentication service degradation." But the actual playbook we wrote for it assumed a full outage. The reality was a partial failure where some users could log in and others could not. The existing procedure told engineers to fail over to a backup auth provider, but our backup only handled 40 percent of our normal traffic. So the playbook would have made things worse. I rewrote it to include a grace period where we served cached session tokens and limited new sign-ups instead of attempting a full failover. That changed the outcome from a forty-minute blast radius to something closer to nine minutes. The list itself should live in your incident management platform, not in a separate document. Put it inside your runbook templates so responders see it while they are already in the workflow. If you are using Opsgenie, route each type to its own response policy. If you use ServiceNow, create a classification field tied to your incident table. The friction of having to switch tools to look something up is real, and it costs you time during the first fifteen minutes when every decision matters.
There is one counter-intuitive thing most people get wrong here. You should intentionally leave gaps in the list. Not every possible failure needs a entry. If you try to catalog every hypothetical scenario, the list becomes too long for anyone to reference during an active incident. Aim for coverage of the top twenty failure modes, not coverage of every conceivable combination. The remaining eighty percent gets handled by escalation procedures and judgment calls from senior engineers. Another common mistake is updating the list only after a major incident. The revision cycle should be quarterly at minimum, with minor additions happening immediately after any type A event resolves. I used to spend about three hours per quarter doing a proper review with the on-call rotation. That is nothing compared to the eight-plus hours wasted during an actual incident when someone pulls a stale document and follows outdated steps. The honest downside of maintaining a Type A list is that it requires discipline most organizations lack. You will need leadership to enforce the review cadence. You will need someone to own the list as a formal responsibility, not just an informal task that disappears when priorities shift. The biggest failure point I have seen is when the person who originally built the list leaves the company and nobody inherits the document. It dies quietly and resurfaces as confusion during the next incident.
Get the Full Details

If your organization is small enough that a full documented list feels overkill, start with a simpler version. A single page with the top five type A scenarios, the primary on-call contacts for each, and the escalation paths is better than nothing. You can expand it as your incident volume grows. The alternative is doing nothing and reacting to each event from scratch, which compounds waste every single time.