What actually happens when you try to assess real learning
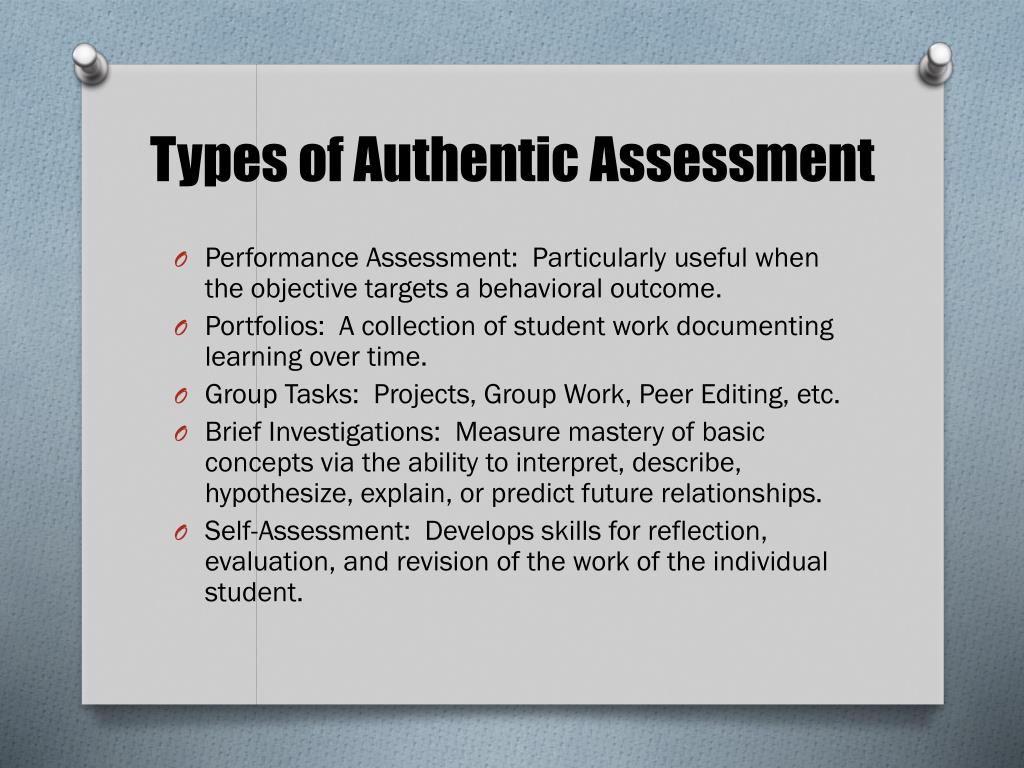
Authentic assessment isn't a methodology you implement on Monday and forget about by Friday. It's a way of measuring whether someone can actually do the thing they were taught, rather than whether they can regurgitate the definition of the thing. I spent years designing these kinds of assessments for vocational programs and higher ed courses, and the thing nobody tells you is that most people who say they want authentic assessment actually want a slightly harder version of a multiple choice test. There's a difference, and it shows up in the data pretty quickly. I'll be direct about this. The main types break down into performance tasks, portfolios, simulations, case studies, projects, and structured observations. That's the textbook answer. The practical answer is more like: pick the type that matches what you're actually trying to measure, because picking the wrong one will waste three weeks and produce results that don't correlate with anything useful. Performance tasks are probably the most common entry point. The student does something in real time under conditions that mirror the actual domain. A nursing student doesn't write an essay on IV insertion. They set up the equipment, verify the patient order, and perform the insertion while being observed against a rubric. The rubric matters more than the task itself. A poorly designed rubric on an otherwise good performance task will give you noise, not signal.
Portfolios collect work over time. This is where people get romantic about the process, but here's the operational reality: a portfolio is only as good as the selection criteria and the reflection prompt. I've seen portfolios where students just dumped every assignment they'd ever done in a folder and called it a day. The reflection component forces them to articulate why certain pieces demonstrate growth. Without that, you're measuring volume, not competency. Simulations recreate environments where the stakes are low but the decisions are real. Flight simulators are the obvious example, but they show up in business schools, emergency response training, and clinical psychology programs too. The challenge with simulations is fidelity cost. A high-fidelity simulation that takes forty-five minutes to set up per student doesn't scale well past twenty-five participants without serious infrastructure investment. Low-fidelity simulations save time but often fail the validity test because students know they're not real and adjust their behavior accordingly. Case studies present a realistic scenario and ask the student to analyze or solve it. Law schools run on these. So do business programs. The trap here is that case studies often measure reading comprehension and analytical writing more than they measure the actual skill the case is supposed to represent. A business case study about negotiation doesn't tell you whether someone can negotiate. It tells you whether they can write a good analysis of a hypothetical negotiation. If you want to assess negotiation ability, pair the case study with an actual role-play component.
Projects are the catch-all category and also the most commonly misapplied. A project assigns a substantive piece of work with a deliverable that has real or pseudo-real consequences. The problem I run into constantly is scope creep. A well-designed project has clear boundaries and success criteria from day one. Students will expand the scope if you let them, and then you end up assessing their project management ability instead of the course content. I solved this by making the scope constraint itself part of the rubric. Anyone who went beyond the defined parameters lost points for failing to follow specifications. That shifted the behavior immediately. Structured observations involve watching someone perform and scoring them against predefined criteria. This is used heavily in skilled trades, healthcare, and teaching credential programs. The reliability problem here is real. Two observers will score the same performance differently about thirty percent of the time without calibration. I ran inter-rater reliability training sessions where three evaluators scored the same recorded performance independently, then compared notes until the variance dropped below five percent. It took four sessions across two weeks. After that, the data held up consistently. I should mention the one edge case that still gives me trouble. I was designing a performance assessment for a technical writing course where students had to produce a set of user documentation for a software product. The rubric covered clarity, accuracy, organization, and audience awareness. During piloting, I noticed that students who had prior experience with the specific software being documented scored significantly higher on the accuracy dimension regardless of their actual writing ability. The assessment was measuring software familiarity, not writing competency. I solved this by introducing a fictional software product with a detailed feature spec sheet that all students received at the same time. This eliminated the prior experience variable and made the accuracy scores actually reflect how well students could translate technical information into user-facing documentation.
Get the Full Details

How to build one without making it useless
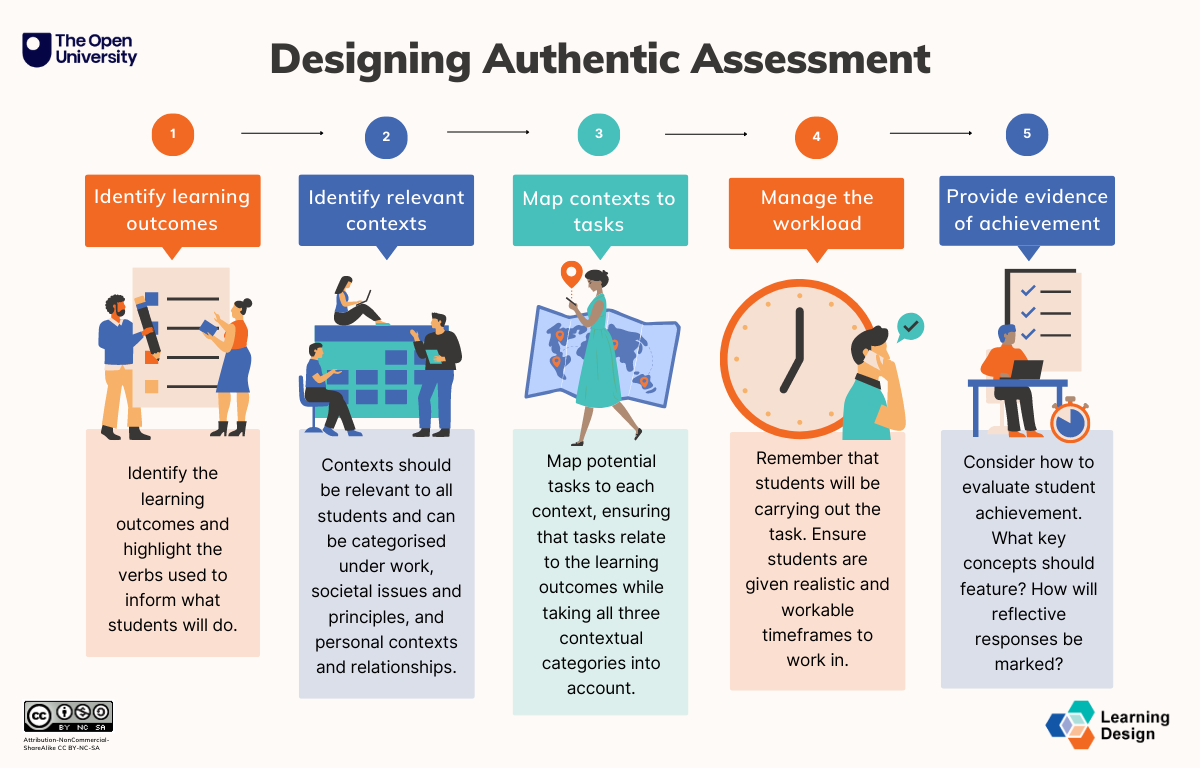
Start with the competency, not the activity. I see this backwards constantly. Someone picks an engaging activity first and then figures out what it's supposed to measure. The measurement ends up vague and the engagement ends up superficial. Reverse that sequence. Write down the specific competency you need to verify, then design the assessment task around demonstrating that exact thing. Rubrics need to be explicit enough that a stranger could use them. "Good writing" is not a rubric criterion. "Uses topic sentences that clearly signal the main claim of each paragraph" is. I've graded assessments using rubrics written by other instructors where the criteria were so ambiguous I had to guess what they meant, and my guesses were wrong about half the time. That's not assessment, that's personality matching. Time your tasks before you deploy them. A task that takes three times longer than estimated isn't authentic, it's an endurance test. I once designed a simulation-based assessment for project management that I thought would take students about ninety minutes. It took most of them three hours because I hadn't accounted for the time needed to parse the scenario materials. Half the class failed to complete it within the session window, and their incomplete work couldn't be fairly scored. I revised the materials for readability and added a pre-session preview period. The second round took an average of eighty-two minutes and the score distribution made actual sense.
Pilot everything. You will miss something in the design phase. A scenario will be ambiguous in a way you didn't anticipate. A rubric criterion will apply to half the students and not the other half. A simulation will fail to load on certain devices. I learned to run every authentic assessment through at least one pilot group that isn't the target population before deploying it widely. The feedback from pilots catches about sixty percent of the problems I'd otherwise discover during actual grading.
When authentic assessment doesn't work
It doesn't scale well for large cohorts without significant resources. If you're assessing two hundred students through performance tasks or structured observations, you need approximately two hundred hours of evaluator time plus calibration sessions, assuming a one-hour-per-student model. That's a real budget question, not a pedagogical one. It introduces more subjective judgment into grading, which increases appeal rates and grade disputes. Students who know their score was partly based on an evaluator's professional judgment will sometimes challenge it by questioning the evaluator's competence. I've seen this happen repeatedly in clinical skills assessments where a student argued that the observer "didn't understand the clinical context." Having clear rubric anchors and recorded sessions for review helps, but it doesn't eliminate the problem entirely. It requires evaluators who actually understand the domain. A biology professor can design a solid authentic assessment for a lab skills course. That same professor designing an authentic assessment for a communication course within their department will likely produce something that looks authentic but measures the wrong things because they lack the framing expertise. Don't assign authentic assessment design to people outside their specialty area and expect reliable results.

Standardized testing regimes often conflict with authentic assessment by design. If your program needs to produce scoreable data for an external body that uses norm-referenced comparisons, authentic assessment data doesn't always translate cleanly into that format. I've worked in programs where the department wanted to use portfolios but the accreditation body required standardized exam scores that measured completely different dimensions of knowledge. The compromise was using authentic assessment for formative purposes and standardized tests for summative reporting, which satisfied everyone involved but left the students with a fragmented experience of their own learning. The main thing to take away is that authentic assessment works when the alignment between competency, task, and rubric is tight. When it breaks down, it's almost always because one of those three elements is loosely defined. Fix the alignment, not the activity.