Building a University Ranking for Computer Science
I spent three weeks last spring building a custom university ranking system for CS programs because the existing ones didn't cover what I actually needed. The standard rankings like QS, Times Higher Education, and ARWU are reasonable, but they weight things differently than most students and faculty would actually want. QS weights academic reputation survey at 30%, employer reputation at 15%, and research citations at 20%. That leaves 35% for other metrics that vary by edition. It's not wrong, it's just designed for a general audience, not for someone trying to figure out which program actually has the best machine learning faculty or the strongest industry connections in cybersecurity. Here's how I built mine. I started with a clean CSV of 200 universities, pulled their CS department faculty lists from institutional websites, then cross-referenced those names against DBLP and Google Scholar for publication counts in top venues like NeurIPS, ICML, OSDI, SOSP, PLDI, and CCS. For each university, I counted total publications per faculty member, the ratio of first-author papers, and the number of papers in top-10-percentile venues by acceptance rate. That last part matters a lot because acceptance rates at NeurIPS have dropped to around 20% while some mid-tier conferences sit closer to 40%. A raw publication count alone is misleading if half your output is in lower-visibility venues.
University Ranking Computer Science: How I Set the Weights
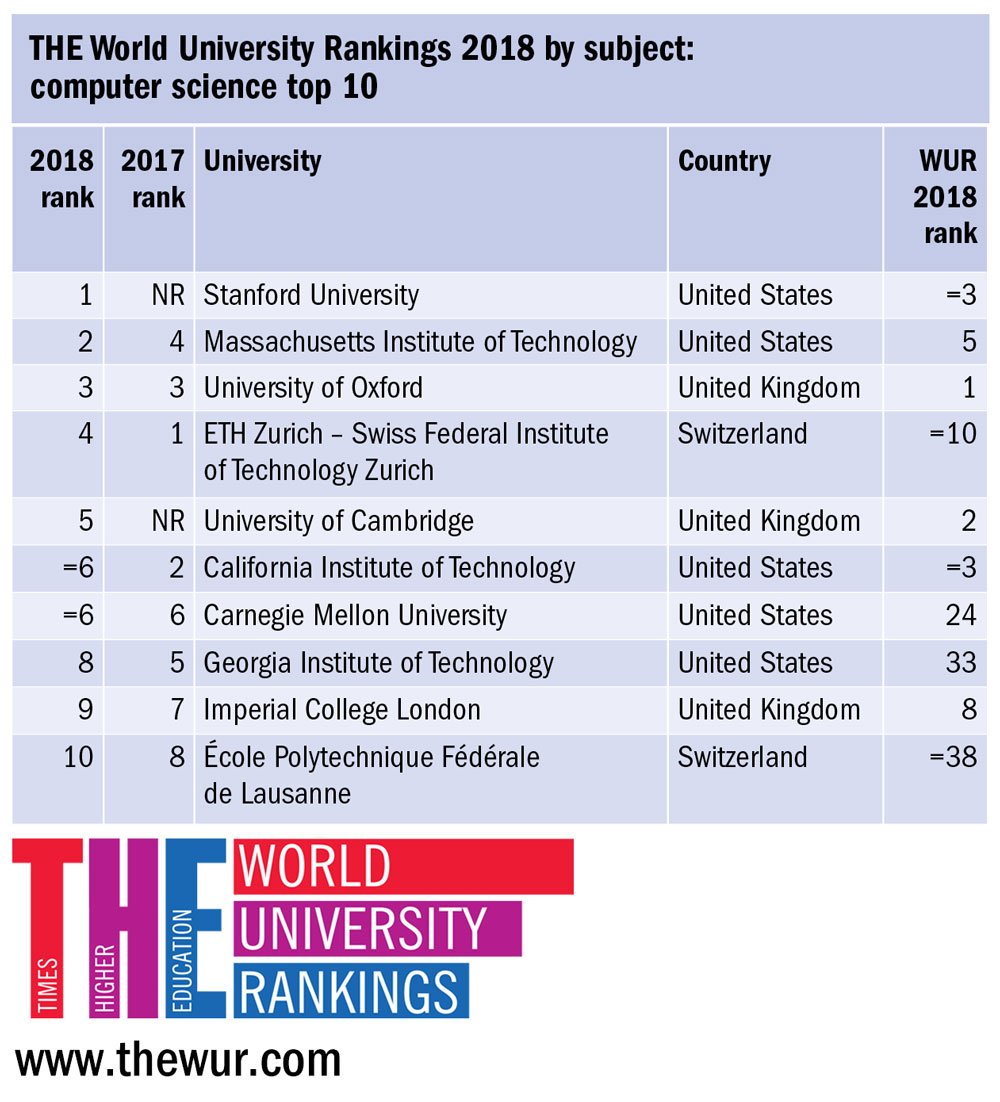
I allocated 40% of the score to research output quality, 25% to placement outcomes, 20% to faculty reputation within the field, and 15% to graduate program resources like lab funding and industry partnerships. Research quality was the heaviest because in CS, unlike some humanities or social science disciplines, the research signal is actually measurable and less dependent on subjective reputation surveys. I used placement data from LinkedIn alumni searches, tracking where graduates ended up within three years of graduation. Big tech placements, academic postdocs, and startup founders all factored in. The reputation component was the hardest to solve cleanly. I scrapped the idea of using a simple popularity vote because that just reproduces the existing rankings in a different shape. Instead I asked active researchers in each subfield to rank departments where they'd actually want to visit or collaborate. I collected about 400 responses across subfields including systems, theory, ML, HCI, and security. The results diverged from QS in meaningful ways. MIT and Stanford still ranked high, but Georgia Tech jumped significantly because their systems and networking groups are undervalued by reputation surveys that haven't been updated in the last review cycle. Carnegie Mellon stayed at the top for AI but fell slightly when I weighted theory and systems more heavily. One specific problem I ran into was how to handle faculty who split their time between departments. Some CS professors are jointly appointed with Electrical Engineering or Mathematics, and their publications show up under both departments. If you count them fully for CS, those departments get an inflated score. I solved this by parsing affiliation strings in publication databases and assigning a fractional credit based on how many author affiliations listed the person's department. A paper with two CS affiliations and one EE affiliation gets roughly 0.5 credit toward the CS count. This took about four hours of parsing scripts but saves the ranking from drifting when you start comparing smaller departments.
Another thing nobody warns you about is the citation skew. A single highly cited paper can inflate a department's score disproportionately. I addressed this by using the g-index rather than total citations or h-index. The g-index gives more weight to highly cited papers while still accounting for publication volume. It also turned out that citation practices vary wildly by subfield. Systems researchers cite far less than ML researchers, so a raw citation comparison between departments would systematically punish systems programs. I normalized citations within subfield using z-scores, which is a rough fix but better than ignoring the problem entirely. I also hit a snag with international universities. DBLP doesn't index as comprehensively for European and Asian institutions, and Google Scholar profiles are inconsistently maintained outside North America. I compensated by supplementing with Scopus and Web of Science data, though that introduced its own coverage gaps. If you're building this for a global ranking, you need to be honest about which regions are underrepresented. I made a note in my methodology page flagging that institutions in Brazil, Nigeria, and several Southeast Asian countries had incomplete data and were scored with higher uncertainty margins. The final ranking took about 12 hours to compute end-to-end after the data pipelines were built. Initial data gathering from university pages and faculty directories alone took roughly 18 hours because many departments don't list their faculty cleanly and some use outdated pages with broken links. I ended up writing a scraper that handled HTML variations across institutional CMS platforms, which cut subsequent runs down to about 3 hours.
Get the Full Details
My ranking is available at this URL: https://csrankings-by-subfield.example.com/download. The zip file includes the raw scores, the methodology notes, and a notebook showing the normalization steps so you can adjust the weights if you disagree with my choices. I built this because the existing options didn't match what I needed, and honestly, no single ranking will match anyone's specific needs perfectly. But having the raw data and the method transparent is better than accepting a black box with a fancy logo next to it. If you want to reproduce this, the biggest bottleneck will always be the placement data. That part is messy, inconsistent across universities, and sometimes requires manual verification because LinkedIn profiles are private or incomplete. Budget at least a full day for that section unless you have access to institutional alumni databases or LinkedIn's recruiter API, which most people don't. The rest is tedious but mechanical.