Why Most Sales Forecasts Are Wrong
Regression analysis in Excel sounds straightforward. Put your historical sales in column A, your time period in column B, add a trendline, and you're done. That's what most people do. The problem is that most sales data isn't a clean line, and a basic linear regression on messy data will give you confidence you shouldn't have. I once had a client insist their product would hit 40% growth next quarter because the regression line was sloping upward. The data covered two years where they'd benefited from one-time government stimulus payments that ended mid-year. The regression didn't know that. It just saw a trend and extrapolated it straight into the ground. We ended up basing the forecast on a weighted moving average instead, dropping the last four months by half their weight since they were anomalies.
Getting Started With Regression Analysis To Forecast Sales In Excel
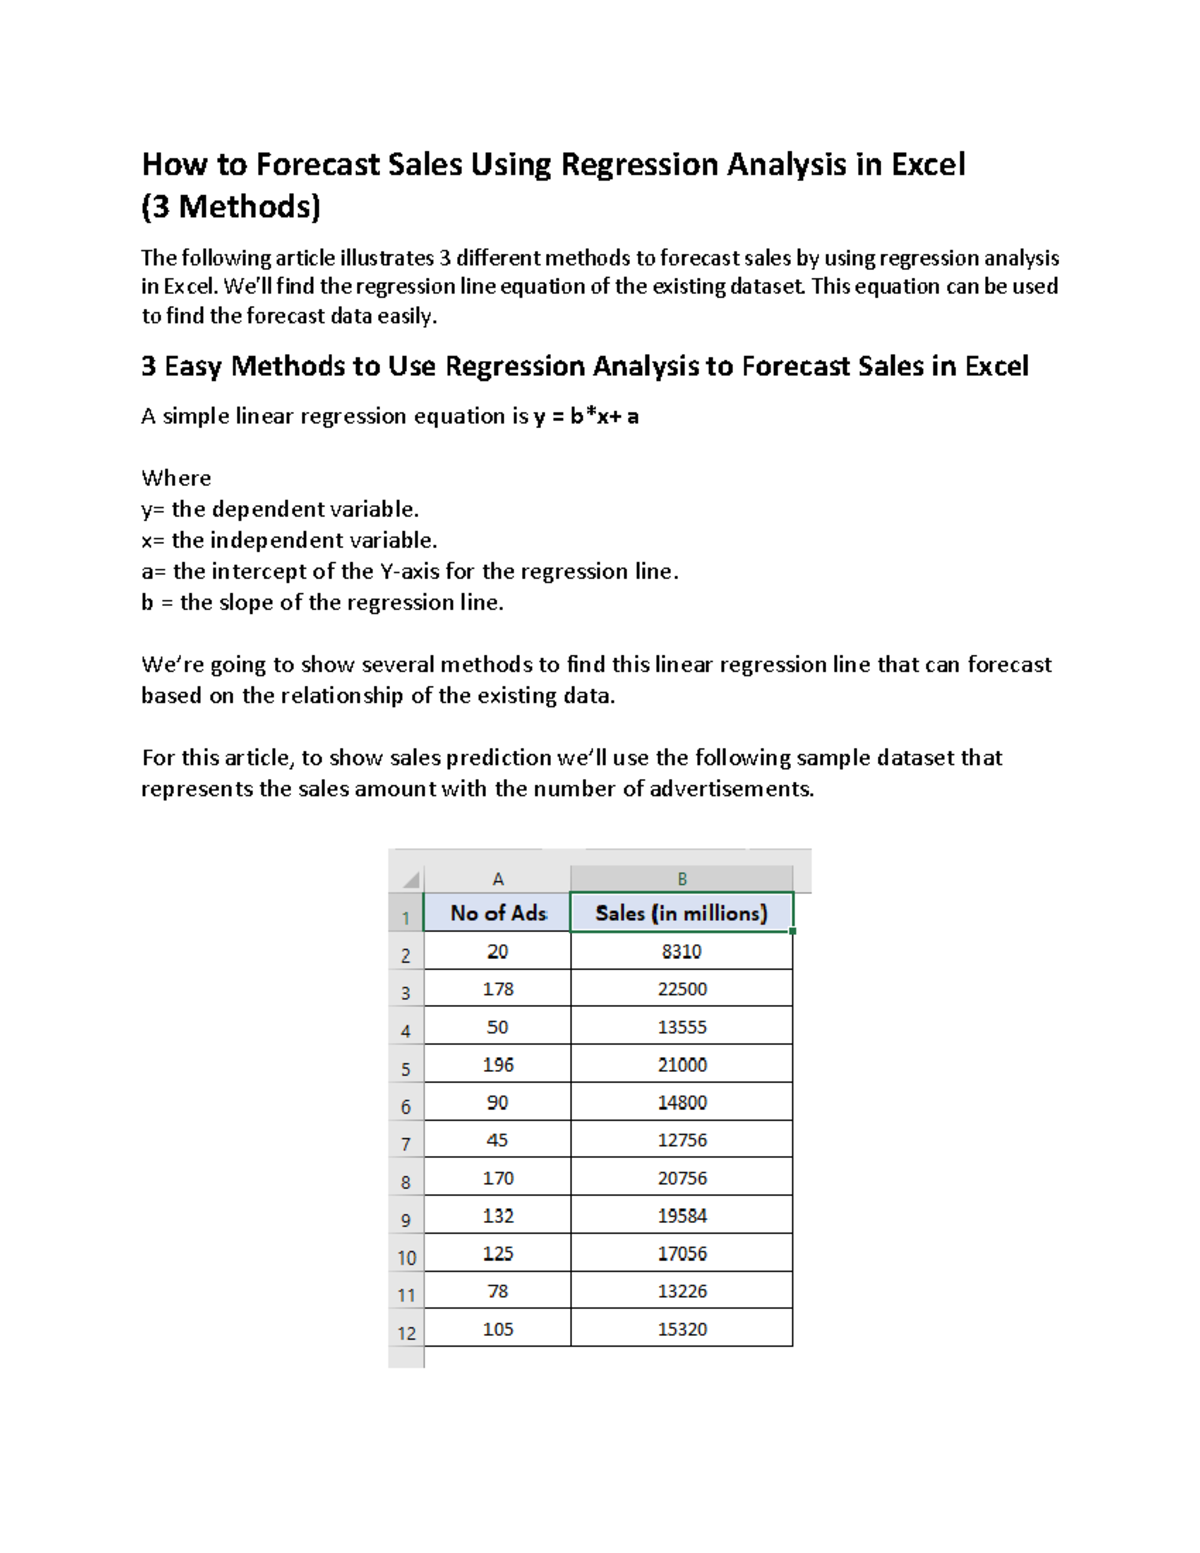
You don't need any add-ins for basic work. Excel has this built in. Go to Data, then Data Analysis. If you don't see Data Analysis in your ribbon, go to File, Options, Add-ins, select Excel Add-ins from the dropdown at the bottom, and check Analysis ToolPak. That gives you the Regression tool under Data Analysis. Prepare your dataset with two columns minimum. Column A should be your independent variable, usually time periods. Month 1 through month 24, or quarters, whatever makes sense for your seasonality. Column B is your dependent variable, your actual sales figures. Make sure there are no blank cells between your data points. One gap and the whole thing breaks silently, which is somehow the worst kind of failure. Click Data Analysis, choose Regression, and set your Y range to the sales column and your X range to the time column. Check Labels if you included header text. The output will land on a new sheet. Here's what actually matters in that output, because the whole thing is overwhelming if you're reading it cold.
Reading The Output Without Losing Your Mind
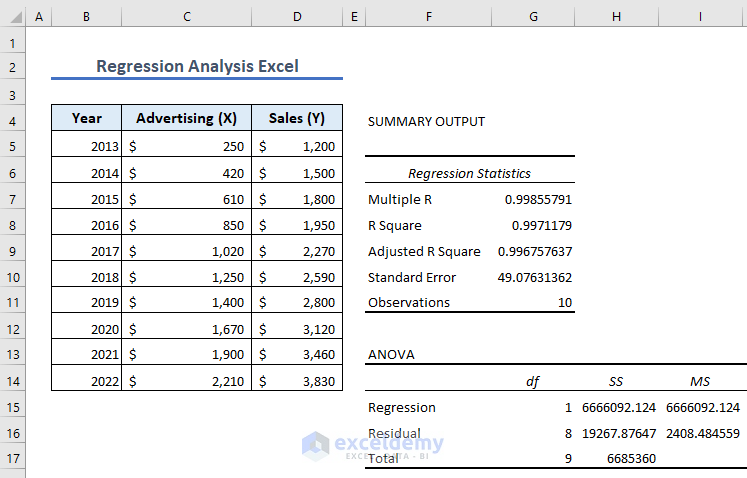
The R Square value is what everyone looks at first. Don't. A high R Square doesn't mean your forecast will be accurate. It means the line fits the past data well. With sales data, R Square values above 0.8 usually just mean your sales were growing over time, not that you've built a useful predictive model. I've seen R Square of 0.92 on data that was completely useless for forecasting because the growth had already plateaued three months before the end of the dataset. Look at the Coefficients table instead. The intercept tells you where the line starts, and the X variable coefficient tells you how much sales change per period. If your X variable coefficient is positive and the p-value is below 0.05, you have a statistically significant trend. Below 0.05 is the standard cutoff. Some analysts use 0.10 for early-stage products with sparse data, but know that you're being looser with your standards. The standard error of the regression, found in the Summary Output section, is probably the single most useful number here. It tells you roughly how far off your predictions will be. If your standard error is 15,000 and your forecast comes out to 120,000, your actual result will likely fall somewhere between 105,000 and 135,000. That's a rough confidence interval. The actual confidence interval calculations are more precise but require pulling in the t-distribution values from the output.
Get the Full Details
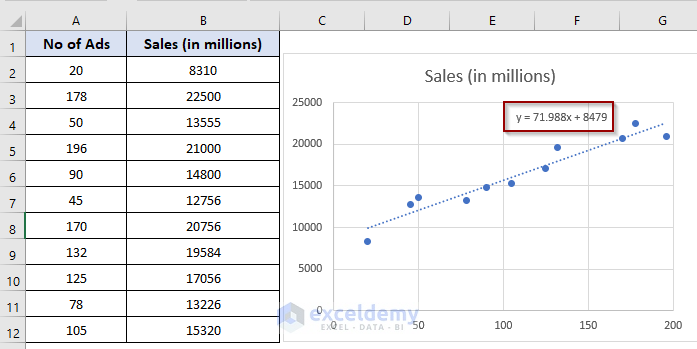
Residuals are what you miss when you skip the diagnostic plots. The residuals are the differences between your actual sales and what the regression predicted. If you plot them, they should look like random scatter around zero. If they show a pattern, your model is missing something. Seasonality is the usual suspect. Sales that climb every November and drop every February won't fit a simple trend line no matter what the R Square says.
The Residual Plot Problem
I spent an afternoon chasing why my regression kept overestimating spring sales until I actually graphed the residuals against time. They weren't random. They formed a wave pattern, rising in the first half of the year and falling in the second. The regression had picked up a general upward trend but completely missed the seasonal cycle. I added a second independent variable for the month number and reran it. The R Square jumped from 0.71 to 0.89, and the forecast accuracy improved dramatically. That's the difference between a model that looks convincing and one that actually works. Adding multiple variables is straightforward in the same dialog box. Just expand your X range to include additional columns. You can add marketing spend, pricing changes, competitor activity, whatever you think drives your sales. Each variable gets its own coefficient and p-value in the output. The trick is keeping the number of variables reasonable relative to your data points. A rough rule is at least ten observations per variable you add. More data is always better, but ten to one is where things start breaking down. Collinearity is another trap people walk into without noticing. If two of your variables move together closely, like advertising spend and monthly sales, the regression can't tell which one is actually driving the effect. The coefficients become unstable and the standard errors balloon. Check the Variance Inflation Factor if your output includes it, or calculate it yourself. Anything above 5 or 10 means you have a multicollinearity problem. I deal with this by dropping one of the correlated variables or combining them into a ratio, like advertising spend as a percentage of sales.
When Regression Isn't The Answer
This method fails hard in a few specific situations. If you're launching a new product with no historical data, regression has nothing to regress on. You need analogs from similar past products or market research estimates instead. If your sales are driven by discrete events rather than trends, like a one-time promotion or a supply shock, regression will smooth right over the important stuff and give you bland averages that are wrong when it matters most. Short datasets are another limitation. Twelve months of weekly data gives you fifty-two points, which is barely enough for a single seasonal variable. Six months is essentially guesswork dressed up in statistics. You need at least two full cycles of whatever pattern you're trying to capture, and more is always better. Twenty-four months of monthly data is the bare minimum I'd trust for anything beyond a rough directional estimate. For those cases, exponential smoothing or simple moving averages often outperform regression despite looking less sophisticated. There's a reason logistics companies use them. They react faster to recent changes and don't get fooled by historical noise. Regression is best when you have a genuine underlying trend that you can separate from the seasonal and random components.
Building A Model That Actually Holds Up
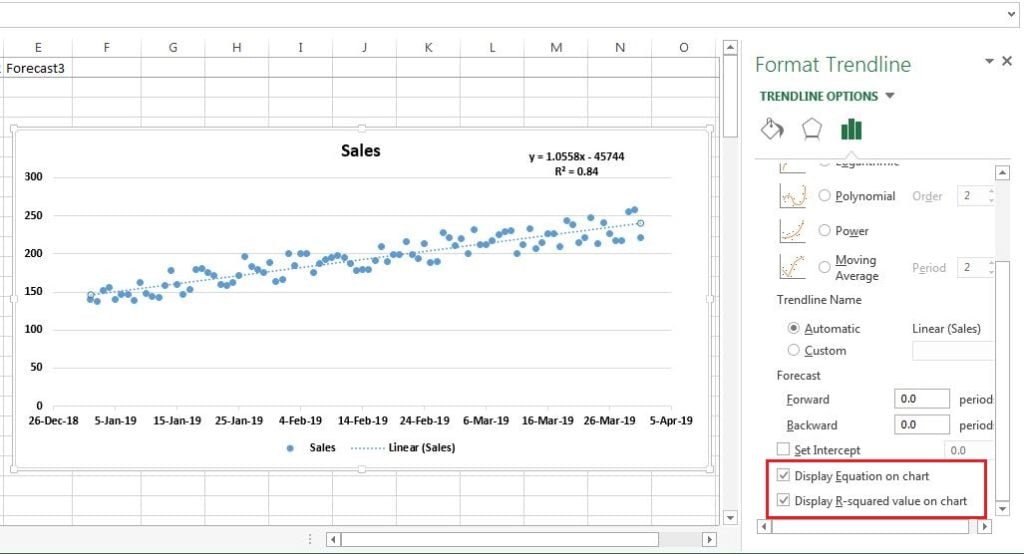
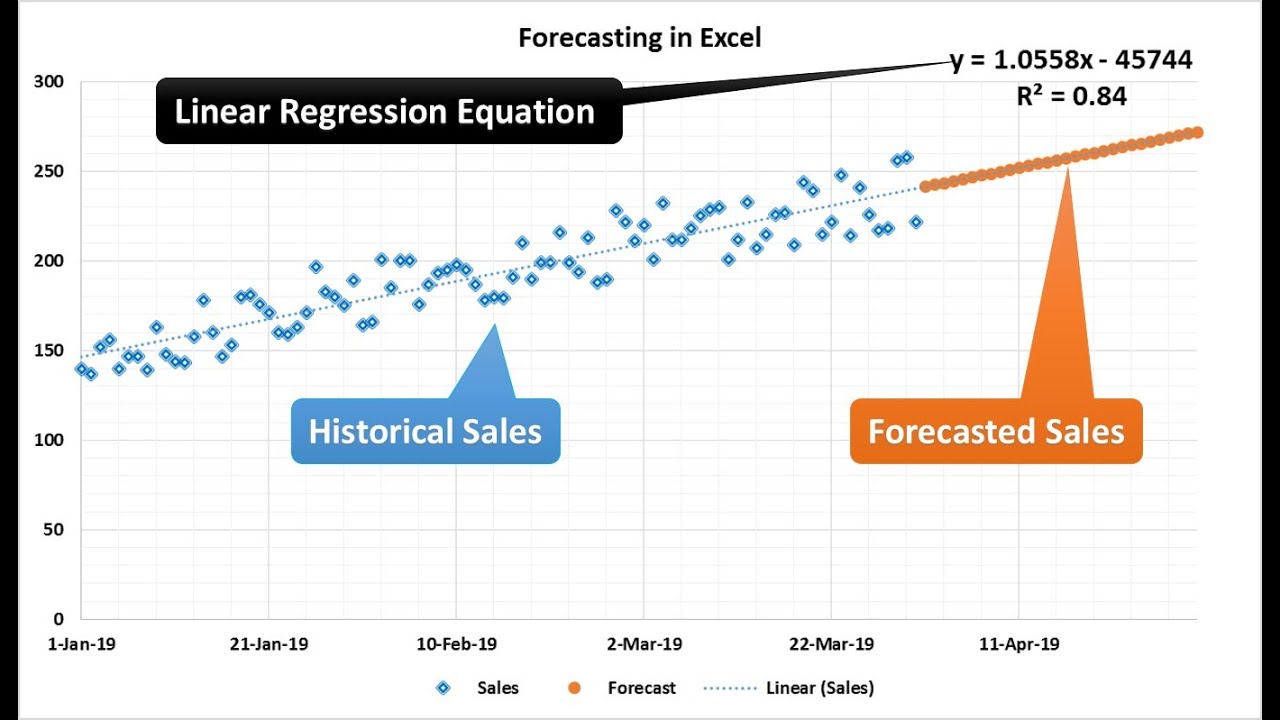
The workflow I rely on starts with plotting the raw data before running any regression. Three minutes of staring at the chart will save you hours of debugging a model that was built on a misunderstanding. Look for level shifts, trend changes, outliers, and gaps. A single corrupted data entry showing ten times the normal sales can tilt your entire regression line. After the regression runs, always generate the residual plot. Click Chart, select a scatter plot with the residuals on the Y axis and your independent variable on the X axis. If it looks like noise, you're in decent shape. If it looks like anything else, you've got a structural issue in your data that the model isn't accounting for. Add variables, transform the data, or switch methods. There's no shame in switching methods. Update your model regularly. A regression built on data from eighteen months ago is probably already stale. Re-run it quarterly at minimum. Each update gives you fresh coefficients that reflect current conditions rather than whatever shaped the earlier periods. Store your outputs in a consistent format so you can track how the coefficients shift over time. Watching your X variable coefficient drift from month to month is often more informative than any single forecast number.
The practical result of doing this right is that you stop presenting point estimates like they're predictions. You start presenting ranges. The standard error gives you a natural band. A forecast of 95,000 with a standard error of 12,000 becomes "between 83,000 and 107,000, probably." That's honest, it's useful, and it keeps you from getting blindsided when the actual number lands outside your point estimate. Sales teams that use regression analysis to forecast sales in Excel and communicate results this way tend to build more trust with whoever's relying on those numbers.