Mapping the flow before you fix it
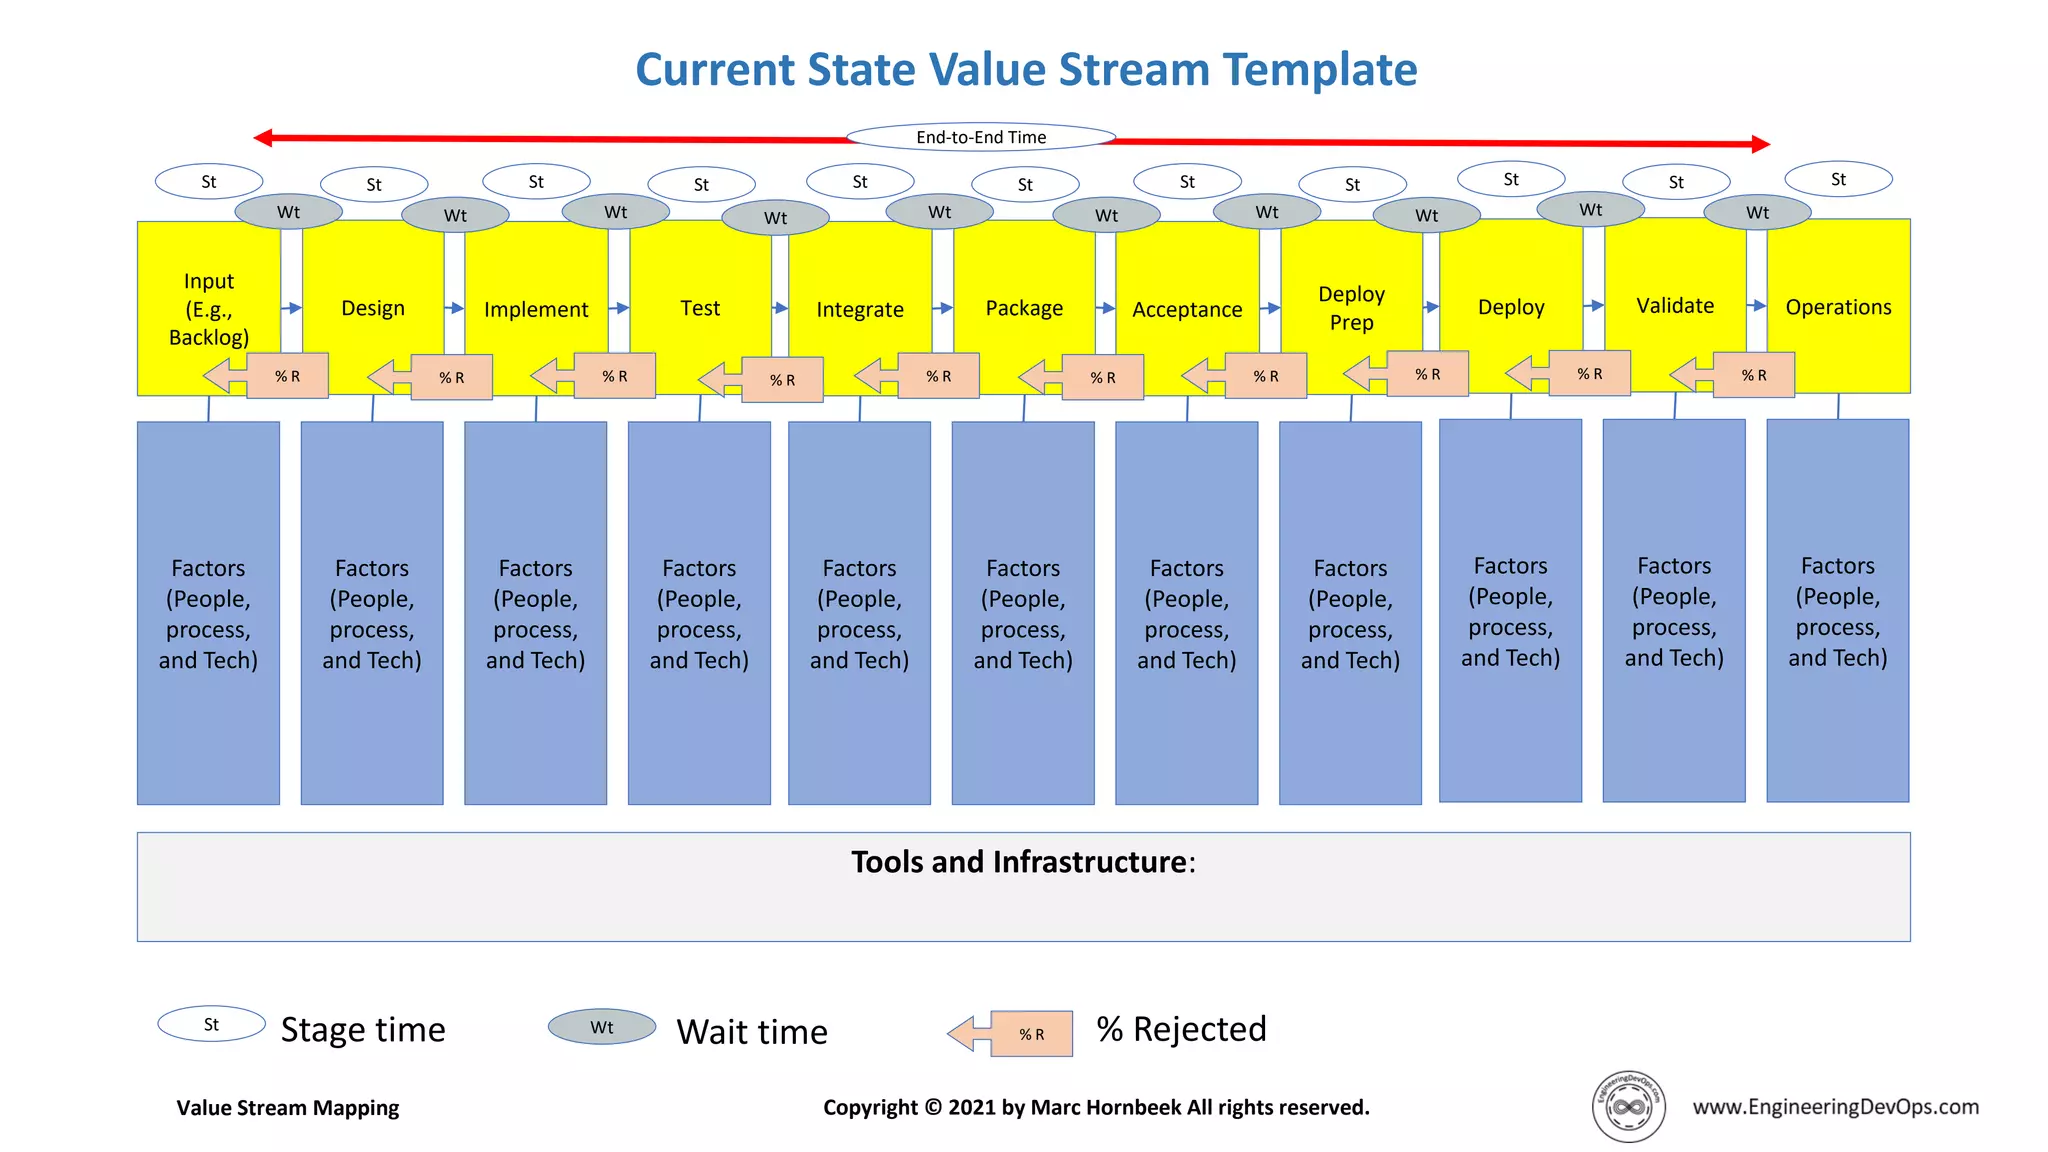
I've done enough Value Stream Mapping DevOps exercises across different orgs to know most of them fail because people treat it like a drawing activity instead of a diagnostic tool. You map the current state, identify the waste, and then you actually do something about it. The most common mistake I see is teams spending three weeks on the map and then never touching it again. It's the same Lean concept from manufacturing, adapted for software delivery. You take a specific product or feature request and trace every step from the moment someone writes it down to the moment it's running in production. Not your ideal pipeline. The real one. You note how long each step actually takes, not how long the documentation says it should take. You separate the value-adding time from the wait time. That wait time is where most of your problems live. In DevOps specifically, the stream usually looks like this: requirement, design, development, code review, build, test, staging, deployment, monitoring. But your actual stream probably has branches, loops, and dead ends that don't appear on any official diagram. That's what you're trying to surface.
The practical method
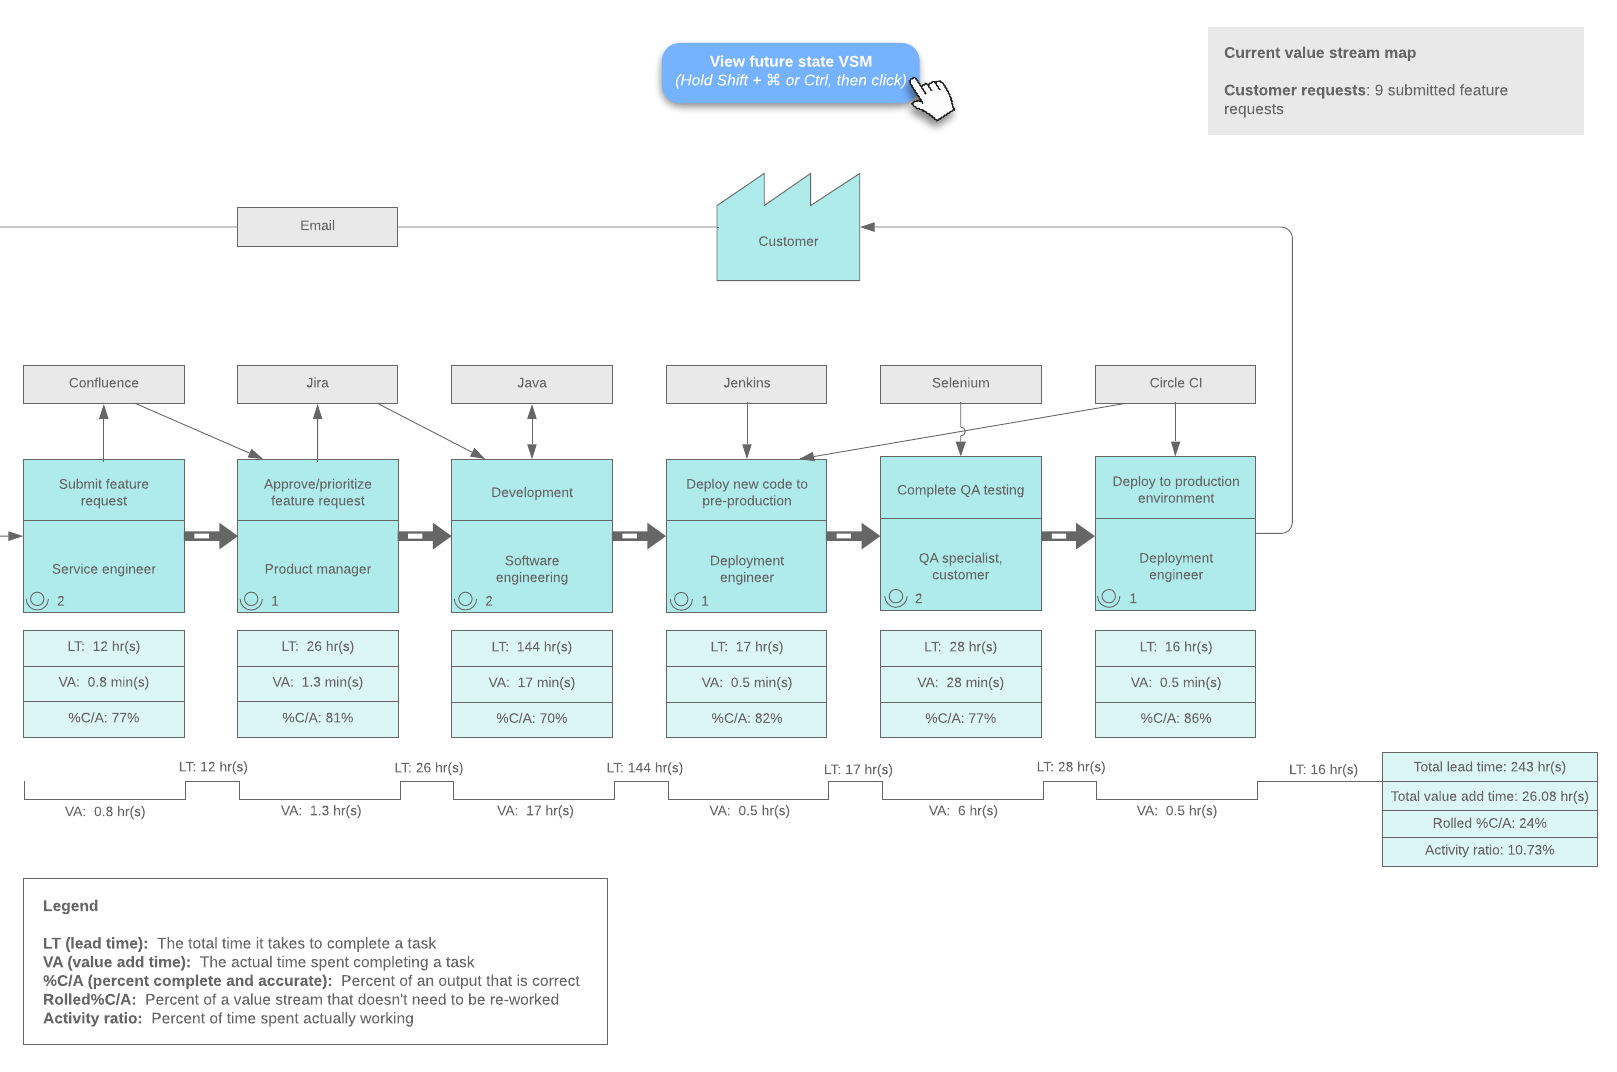
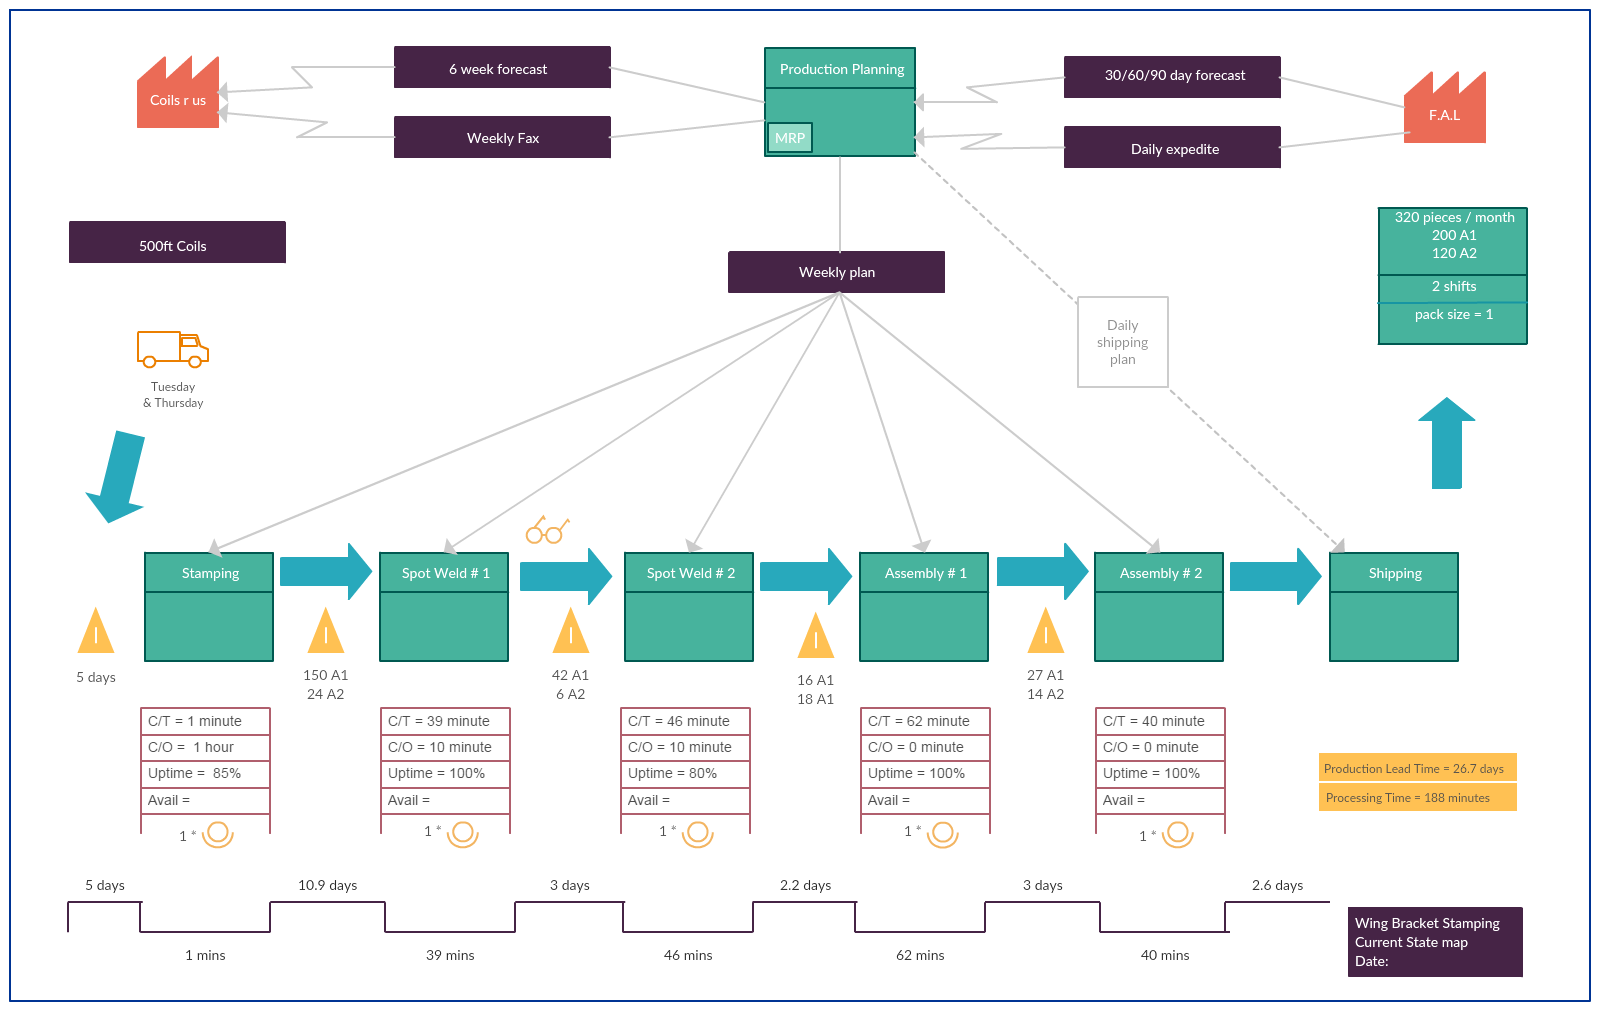
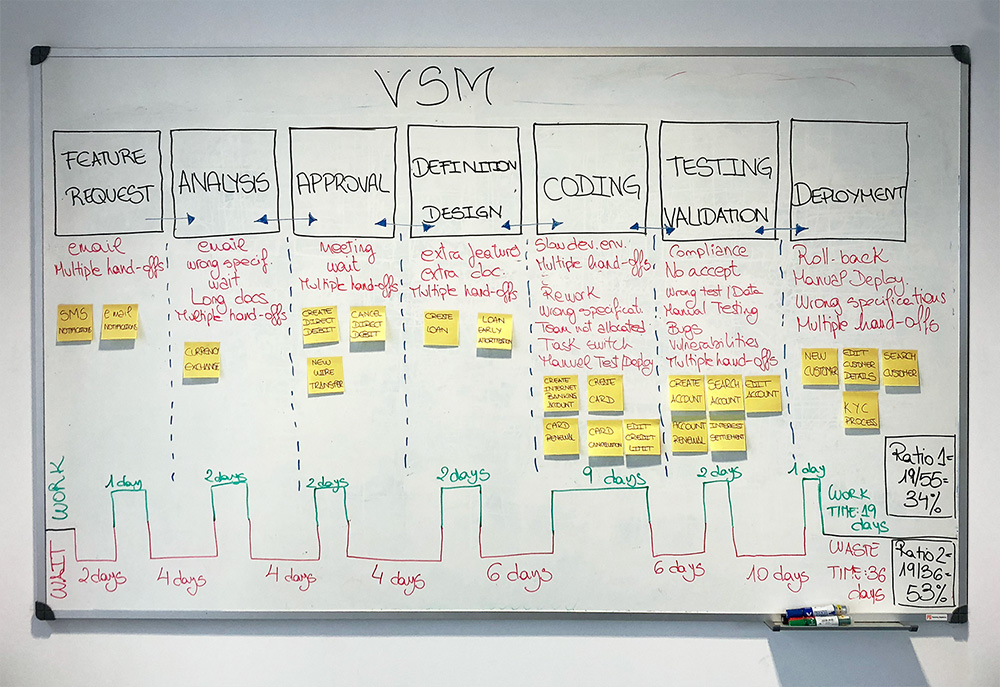
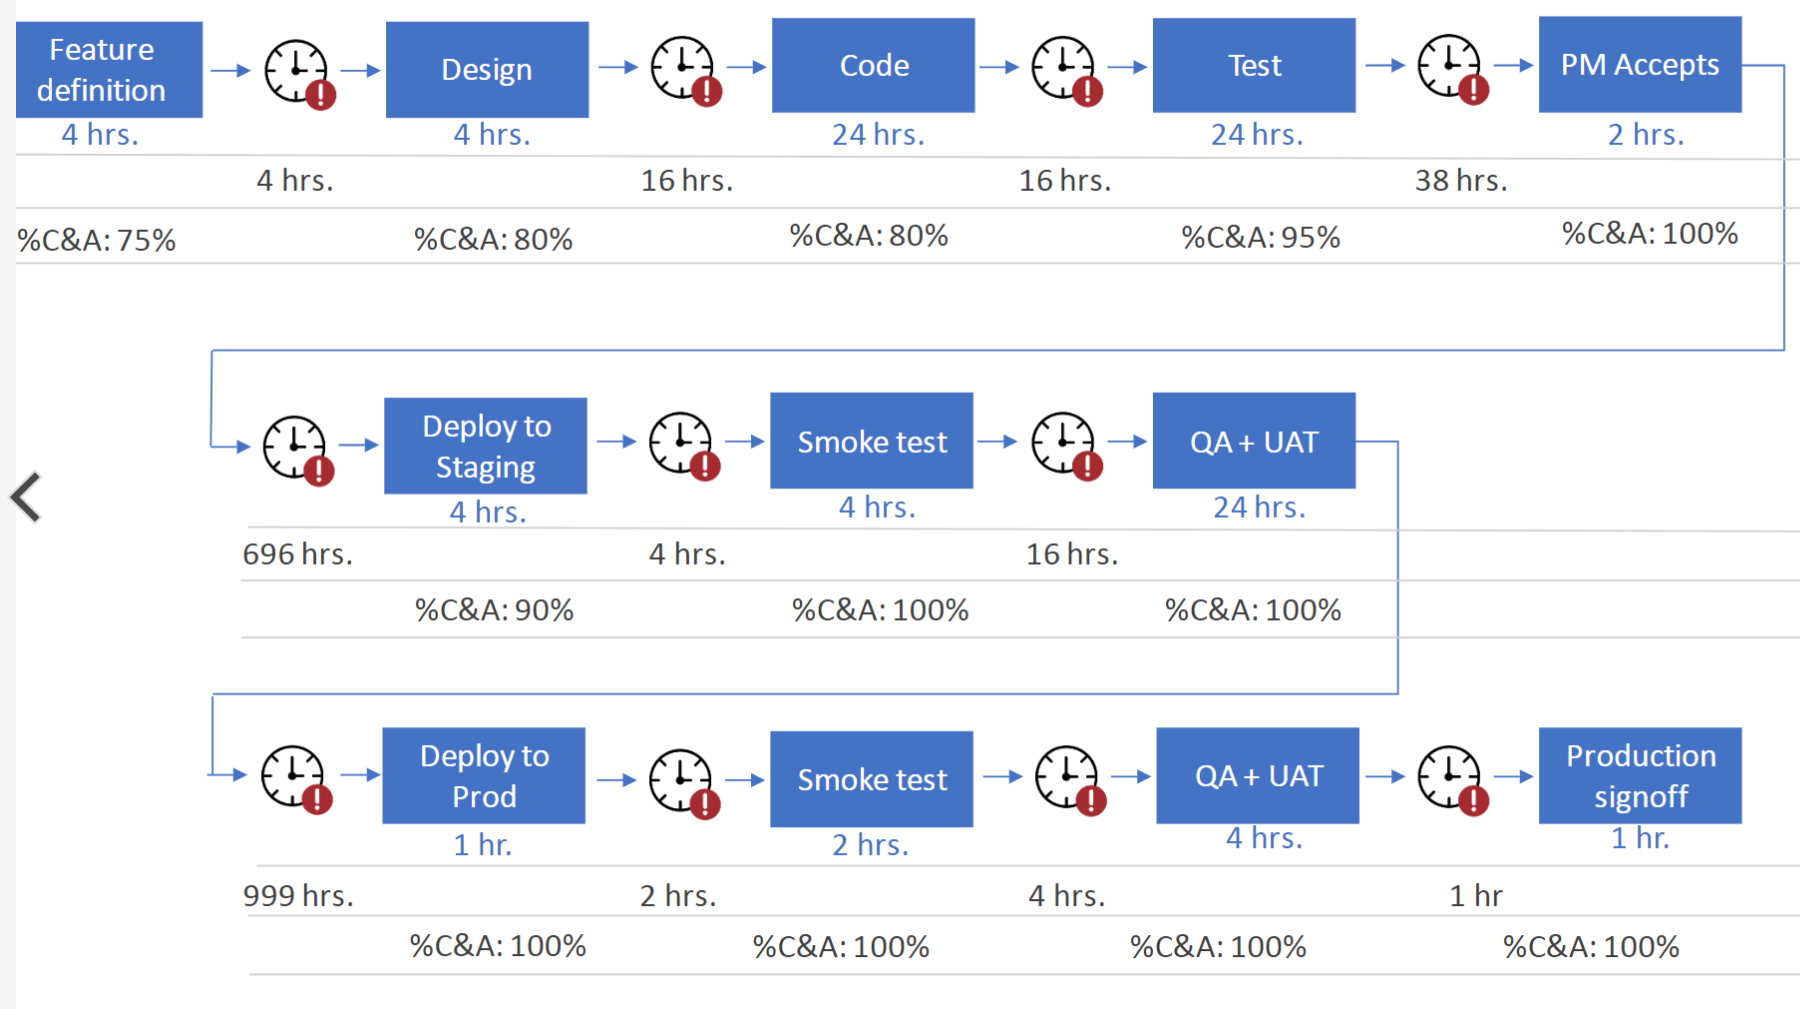
Pick one concrete flow. Not "everything our team does." A single feature type, a specific product line, one team's output. Something bounded. I work with a team that processes merchant onboarding requests for a payments platform. Their flow runs through compliance checks, infrastructure provisioning, environment setup, and application deployment. That's a clean enough stream to map without getting lost. Walk the actual path. Don't rely on meetings or documentation. Go talk to the people who touch each step. Look at the Jira tickets, check the deployment logs, examine the handoff points. Record the real numbers. How long does a ticket sit in "Ready for Review" before someone actually looks at it? How many times does a build fail for the same reason before it passes? Draw the map on a wall or a large digital whiteboard. Use simple symbols. Process boxes for each step. Inventory triangles for anything queuing up. Time arrows showing elapsed time between steps. Keep it ugly. A clean diagram is a sign someone did it from their desk instead of observing the work.
Calculate the process cycle time by adding up only the actual work time. Then calculate the total lead time including all the waiting. The gap between those two numbers is your waste. That gap is what you're solving for. Here's where people get it wrong. The bottleneck is rarely where you think it is. In a recent engagement, the deployment stage looked like the problem. It was taking 47 minutes. But when I looked at the actual flow, the bottleneck was integration testing, which was queueing behind a single shared test environment. The deployment time was just a symptom. If you optimize the wrong step, you waste more time.
Get the Full Details
A specific edge case I ran into
Mapping a platform team that had introduced a approval gate between staging and production. On paper it added 4 hours to the flow. In practice, the approval was almost always rubber-stamped within 20 minutes. The real problem wasn't the approval itself. It was that the staging environment had flaky health checks, so deployments kept failing verification even after going through. The approval gate was masking a deeper reliability issue. I worked around it by skipping the formal mapping of that particular step and instead tracing the actual failure rate from staging to production. The fix ended up being infrastructure, not process. Once you understand the current state, sketch a realistic future state. Not a fantasy pipeline with zero wait time. A version where you've eliminated the actual waste you identified. Remove steps that add no value. Combine steps that belong together. Automate the handoffs that currently require human intervention. Set measurable targets. Reduce lead time from 14 days to 5 days. Cut the deployment failure rate from 23 percent to under 5 percent. Make the numbers concrete so you can tell if you actually improved anything.
What this won't do for you
Value Stream Mapping DevOps assumes your teams have visibility into the full flow. If your dev team doesn't know what happens after deployment, or your ops team doesn't understand why features are being built the way they are, the map will be incomplete and misleading. It also requires genuine access to real data. If people are inflating their metrics or hiding delays, the exercise becomes theater. For organizations with extremely small teams, the overhead of running a proper VSM may outweigh the benefits. A three-person startup moving features daily doesn't need a wall diagram to find bottlenecks. They can just talk to each other. VSM shines in mid-to-large organizations where silos actually exist and visibility breaks down. The biggest failure mode is treating it as a one-time project. Map the current state, present findings to leadership, and move on. That's not how you improve flow. You map, you act, you remap. The cycle repeats. Each round should reveal fewer hidden bottlenecks because you've already surfaced the obvious ones.
Where to start if you want to try this
There are free templates available from the Lean Enterprise Institute and various DevOps communities. You can also use a whiteboard and sticky notes if you have the room and the team in the same building. Remote teams can use Miro or FigJam. The tool doesn't matter. What matters is that someone with authority commits to acting on what the map reveals, not just presenting it. Expect the first map to be frustrating. Your assumptions about how work flows will be wrong. That's the point. You're supposed to be surprised. If the current state map looks nothing like your documented process, you've just learned something useful about where the real problems are.