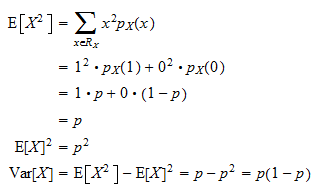Working With Bernoulli Variance in Practice
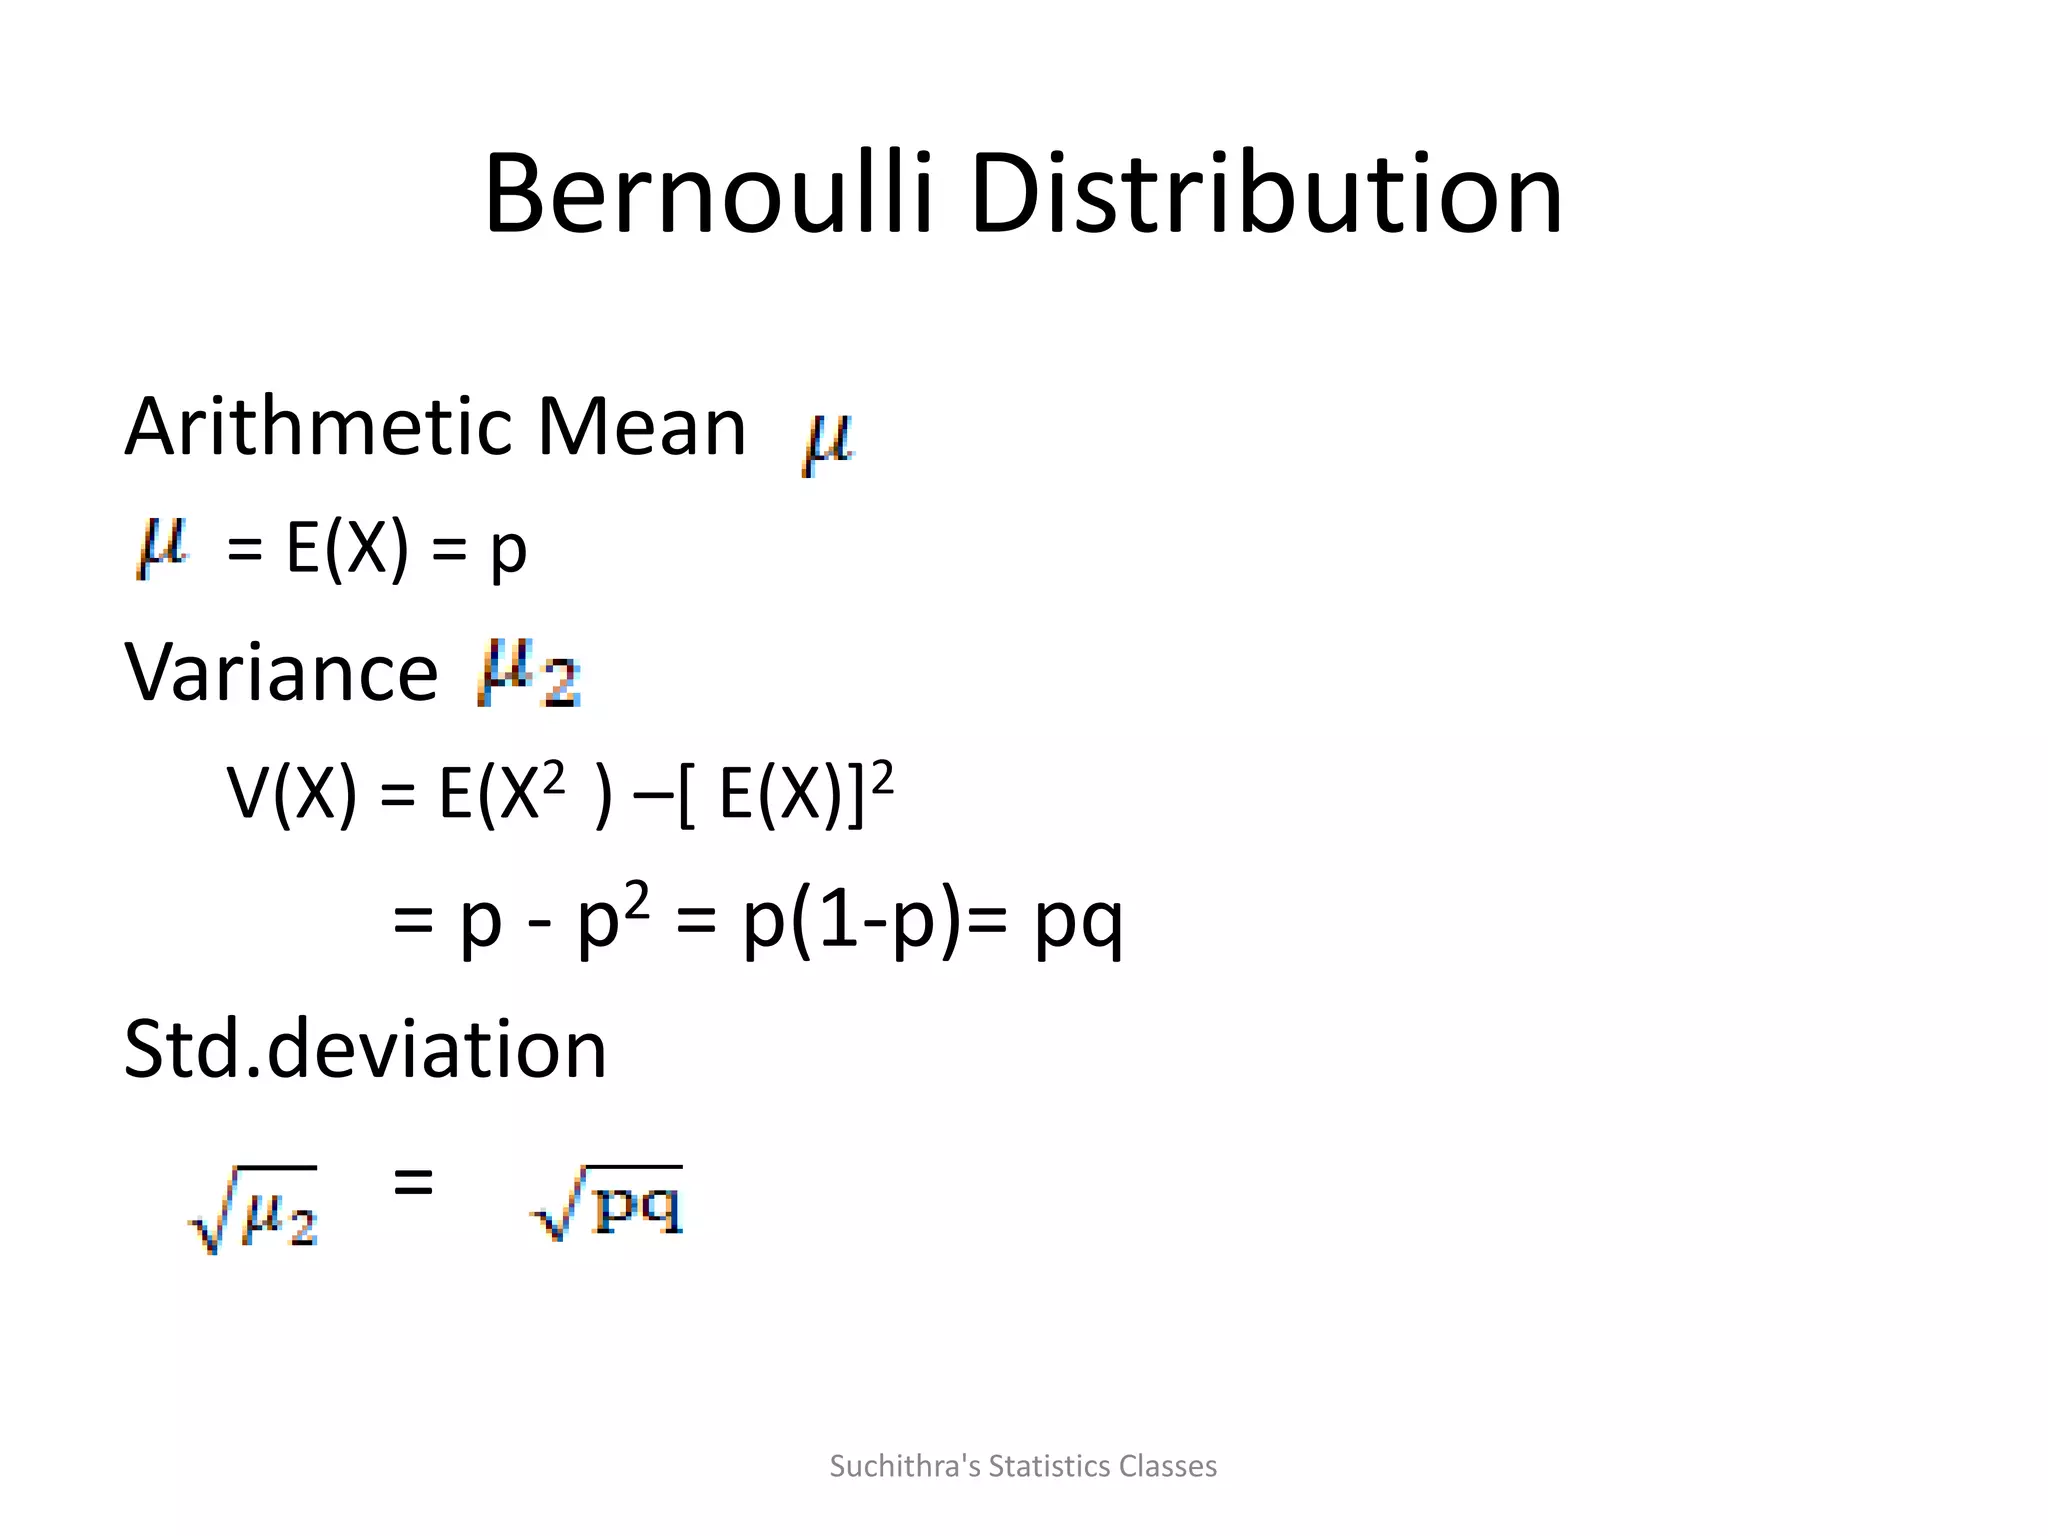
The variance of a Bernoulli distribution comes out to p times (1 minus p), where p is the probability of success. That's the whole formula. But using it correctly in real work requires more than memorizing that line. I've seen people plug in the wrong p value all the time. You have to be crystal clear about what constitutes a "success" in your particular setup. It's arbitrary, and getting it backward flips your understanding of the distribution without changing the numerical answer, which creates confusion when you're reporting results to someone else.
Understanding the Variance Of Bernoulli Distribution
Start with the basic definition. A Bernoulli random variable takes the value 1 with probability p and 0 with probability 1 minus p. The expected value is just p. To get the variance, you subtract the mean from each outcome, square the differences, and weight by their probabilities. That gives you (1 minus p) squared times p plus 0 minus p squared times (1 minus p). Simplify it and you land on p times q, where q is 1 minus p. The algebra is straightforward enough that you should work through it yourself rather than trusting a memorized formula. I usually re-derive it when I'm writing documentation because it anchors the intuition that the variance peaks at p equals 0.5 and drops to zero at both extremes. Here's something most introductory resources skip. The variance of a sum of independent Bernoulli trials isn't just the sum of individual variances in the way people assume. When you're dealing with a binomial distribution, which is literally a sum of n independent Bernoulli trials, the variance becomes n times p times q. The key word is independent. If your trials are correlated, which happens more often than people admit in real data, that formula breaks down completely and you need to account for the covariance terms. I ran into this exact problem working on a click-through rate model where user behavior on one day influenced the next. The naive binomial variance underestimated the true variance by roughly 40 percent because of that serial correlation. I ended up using a quasi-likelihood approach with a robust variance estimator instead, which handled the overdispersion without requiring me to model the full dependency structure.
Another thing that trips people up is interpreting what the variance actually tells you about a single Bernoulli trial. The variance is a population-level measure. For any one trial, you either get 0 or 1. There's no variability within that single observation. The variance describes what happens across many repeated trials, not what you should expect from a single data point. I've watched graduate students argue about whether a single Bernoulli outcome has high or low variance, which is a category error. When p is very close to 0 or very close to 1, the variance becomes tiny. This creates practical problems in A-B testing and similar experiments. If you're testing a feature that converts at 99.5 percent, your variance per observation is nearly zero, which sounds great until you realize that detecting a meaningful relative improvement requires enormous sample sizes because the absolute difference you're trying to detect is also vanishingly small. The signal-to-noise ratio behaves in ways that feel counterintuitive when p is extreme. I worked on a fraud detection project where the positive class was roughly 0.1 percent of observations. Using a standard Bernoulli variance approximation for power calculations gave us sample size estimates that were wildly off because the normal approximation to the binomial fails in that regime. We switched to exact binomial calculations and it changed our required sample size by a factor of three. That's not a edge case that affects a small fraction of users. It affects anyone working with rare events, which is a surprisingly large slice of practical applications.
Get the Full Details

If you need to compute this quickly, the formula is simple enough to put in a spreadsheet or a one-line function. For the more complex cases involving correlated trials or extreme p values, I'd recommend using a proper statistical package rather than trying to derive adjustments by hand. The math gets messy fast once you introduce dependency structures, and the marginal benefit of a closed-form approximation rarely justifies the risk of using an incorrect variance estimate in a decision-making context.