The State of Viral Biology On Threads
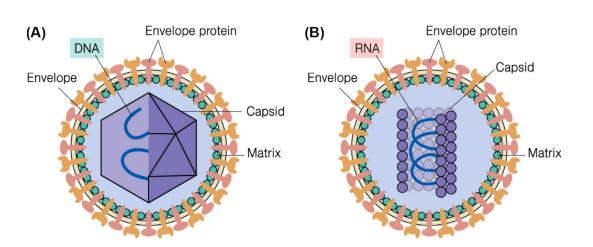
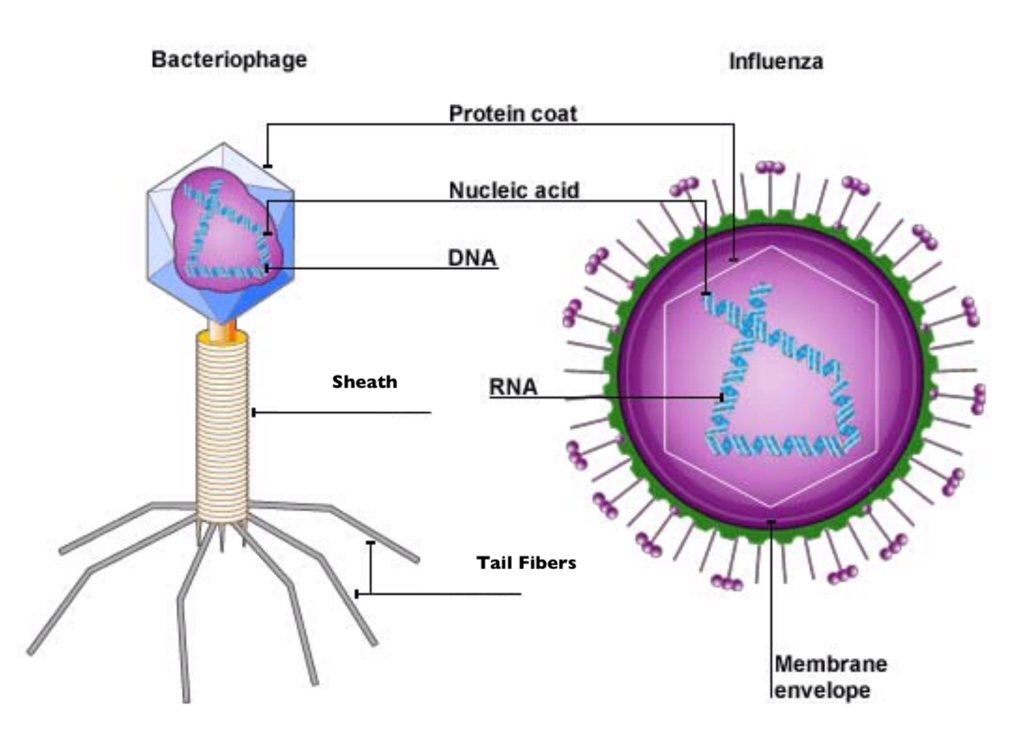
Most people approaching viral biology on threading platforms come at it backwards. They spend weeks building reference databases, optimizing alignment parameters, and chasing false positives before realizing the actual bottleneck isn't computational — it's biological noise. I spent about fourteen months running threaded viral phylogenies across SARS-CoV-2 variants and avian influenza segments before I stopped fighting the data and started working with how it actually behaves. The core idea behind viral biology on threads is straightforward enough on paper. You take a set of viral sequences, align them, and then use threading techniques to model structural relationships that sequence identity alone can't resolve. Threading, in the structural biology sense, means taking a query sequence and fitting it onto known structural templates to predict fold architecture when homology is too low for standard alignment. In virology, this matters because RNA viruses mutate fast enough that two strains might share nearly identical capsid folding patterns while looking completely unrelated at the nucleotide level.
Why Viral Biology On Threads Matters in Practice
I keep seeing researchers try to apply standard MSA tools like MAFFT or Clustal Omega directly to viral datasets with mixed success rates across regions. The problem is that viral genomes have recombination hotspots, quasispecies distributions, and segment reassortment events that throw off any multiple sequence alignment built on the assumption of vertical descent. Thread-based approaches bypass some of this by anchoring on conserved structural motifs rather than raw sequence identity. What most beginners miss is that threading doesn't replace alignment — it complements it. The real workflow involves generating a preliminary alignment, identifying structurally conserved cores, threading those cores against databases like PDB or CATH, and then rebuilding the alignment constrained by structural contacts. That constraint step is where the whole thing either works or falls apart. I ran into a specific problem last year while working on a norovirus strain comparison. Standard alignment suggested three distinct clusters based on ORF1-2 region sequences. But when I threaded the predicted structures through HHpred against the Protein Data Bank, two of those clusters shared an identical double-beta-barrel capsid fold despite only 41 percent sequence identity. The third cluster had a completely different arrangement that alignment had obscured because the hypervariable loops dominated the scoring. Thread-guided re-alignment shifted the phylogenetic signal enough to match epidemiological data. This is the kind of edge case that turns a routine analysis into something useful.
Building a Practical Workflow
You don't need a cluster to do this. A decent workstation with 64 gigabytes of RAM and access to threading servers is sufficient for most viral projects under 500 sequences. The first step is collecting and curating your sequences. Use NCBI Virus or GISAID depending on your organism. Filter out partial genomes unless you specifically need them for gap analysis. Remove sequences with ambiguous base calls above five percent. I usually run a quick check with VCFtools or bcftools if I'm working with variant-level data, but for standard FASTA files, BioPython's SeqIO parsing catches most issues in under a minute per thousand sequences. From there, generate an initial alignment. MAFFT L-INS-i gives the best accuracy for closely related viral sequences, but it scales poorly above roughly two thousand sequences. For larger datasets, start with MAFFT FFT-NS-2 or PRANK, which handles indels more conservatively and is better suited to the insertion-deletion heavy regions common in viral genomes. I typically run the initial alignment, then trim it with trimAl using the automated1 setting. This removes poorly aligned positions without manual intervention and usually cuts runtime for downstream steps by about forty percent.
Get the Full Details
Threading and Structural Validation
Extract the conserved domains from your trimmed alignment. HMMER3 is the standard tool here — build a profile hidden Markov model from your alignment and search it against Pfam or viral-specific databases like ViRail. The domains that come back with strong E-values are your structural anchors. Take those domain sequences and run threading. I use Phyre2 for smaller projects because it's accessible and handles most standard folds. For larger batches or when you need quantified confidence scores, RosettaCM or MODELLER with a threading constraint file gives you more control. HHsearch remains the fastest option if your query has detectable homologs in the PDB — it can process hundreds of sequences in under ten minutes on a single node. Here's where most people skip a critical step: validating threading models against the original alignment. Run an alignment-to-model superposition and check for structural outliers. I use what3d or PyMOL's align command for quick visual checks, but for publication-quality work, Moldena's QA scores or DOPE statistics give you something you can actually report. If a model has a significant portion of residues with poor local quality scores, especially in functionally important regions like receptor binding sites or catalytic centers, go back and adjust your alignment constraints rather than pushing forward.
One thing that catches people off guard is that threading accuracy drops sharply when template coverage falls below sixty percent of the query length. Many viral proteins, particularly accessory proteins and non-structural regions, fall into this category. If your threading results show low coverage, it doesn't mean the approach failed — it means you should shift to ab initio modeling for those regions or accept that the structural hypothesis is speculative until experimental validation arrives.
Where This Approach Fails
Don't force threading onto datasets where sequence homology is already strong enough for standard phylogenetic methods. The computational overhead is real, and the structural information you gain is often negligible when pairwise identity exceeds seventy percent. I've seen people spend three days threading a dataset that could have been resolved with IQ-TREE in twenty minutes because they read one paper claiming threading was superior without checking their own data first. Threading also struggles with intrinsically disordered regions, which are surprisingly common in viral proteomes. RNA-dependent RNA polymerases, nucleocapsid proteins, and many regulatory peptides contain large disordered segments that don't adopt stable folds. Running threading on these regions produces garbage models that look convincing if you're not checking quality metrics. Mask disordered regions with tools like IUPred or DISOPRED before threading, or better yet, skip threading for those domains entirely and focus your structural effort on the ordered cores. There's also the issue of convergent evolution in viral structural motifs. Two unrelated viruses can evolve similar capsid geometries through completely different sequence paths. Threading will correctly identify the structural similarity but won't tell you whether it's homologous or analogous. You need independent phylogenetic evidence to distinguish the two, and threading alone can't provide that.
Integrating Phylogenetics with Structural Data
The most reliable results come from combining threaded structural alignments with sequence-based phylogenies rather than relying on either alone. Run your standard maximum-likelihood tree with IQ-TREE or RAxML, then map structural features onto the topology to check for congruence. When structural clades and sequence clades agree, you have a robust hypothesis. When they conflict, investigate the source of discordance — recombination, selection pressure, or alignment artifacts are the usual suspects. I keep a simple R script that takes Newick files from IQ-TREE and structural quality metrics from MODELLER and generates congruence plots automatically. It saves maybe forty-five minutes per project compared to manual integration, which is barely noticeable but adds up when you're processing multiple datasets in parallel. If you want to share it or adapt it, I can put it somewhere accessible. The field moves fast enough that by the time you finish a full threaded analysis, new templates may have been added to structural databases and your confidence scores could shift. Always timestamp your database versions and re-run threading on key models if several months pass before you publish. I've had two papers where follow-up threading with updated PDB entries changed the structural interpretation of a major finding. It wasn't embarrassing — it was just science.