Comparing income data across demographic groups without making yourself look incompetent
I spend a lot of time helping people who need to compare income distributions between populations. It sounds straightforward until you realize that "average income" means three completely different things depending on who's asking the question, and every single one of them can be manipulated to say whatever you want. Vs Income Sociology is a comparative framework for analyzing income differences between demographic groups, geographic regions, or economic cohorts using sociological methodology. The core idea is simple: you take two or more population segments and examine how their income distributions differ in statistically meaningful ways. But the execution is where most people mess up. The typical toolkit includes median comparison, Gini coefficient analysis, decile ratio calculations, and sometimes Theil index decomposition if you need to break down inequality into within-group and between-group components. You are not just comparing two averages and declaring victory.
I once worked with a researcher who wanted to compare urban versus rural income patterns in a Southeast Asian country. He ran a t-test on mean incomes, found a statistically significant difference, and built his entire paper around it. The problem was that the urban sample had been collected during a harvest season when rural participants were temporarily employed elsewhere, inflating the rural numbers. Meanwhile, the urban income data came from formal employment records that excluded the large informal sector. His "significant" urban advantage evaporated when we adjusted for both seasonal bias and informal economy participation. Took about six weeks to restructure the data properly. We ended up using a fixed-effects model with district-level controls instead, which ate the confounding variables and produced results that were actually defensible.
The methodology breakdown
Here is how you actually approach this without wasting months on data cleaning that goes nowhere. Step one: define your populations precisely. Vague categories like "low income" or "working class" will destroy your analysis. Pick either income percentiles, occupation-based classifications, or government-defined brackets. If you are using household-level data, decide early whether you are adjusting for household size using equivalence scales. The OECD modified equivalence scale and the OECD square-root scale give different results, and picking one after you see which favors your hypothesis is academic dishonesty. Step two: source the data correctly. National household surveys are the standard. Look for LSMS (Living Standards Measurement Study) data from the World Bank for developing economies, or your country's census microdata for developed ones. Be aware that survey data often underreports top incomes because high earners systematically underreport or opt out. If your comparison involves the top 1%, you should supplement survey data with tax records or Forbes-type wealth data. I have seen people compare national survey data against World Inequality Database figures without accounting for the methodological gap between consumption-based surveys and income-tax records. The divergence at the top end can be 40 to 60 percent.
Get the Full Details
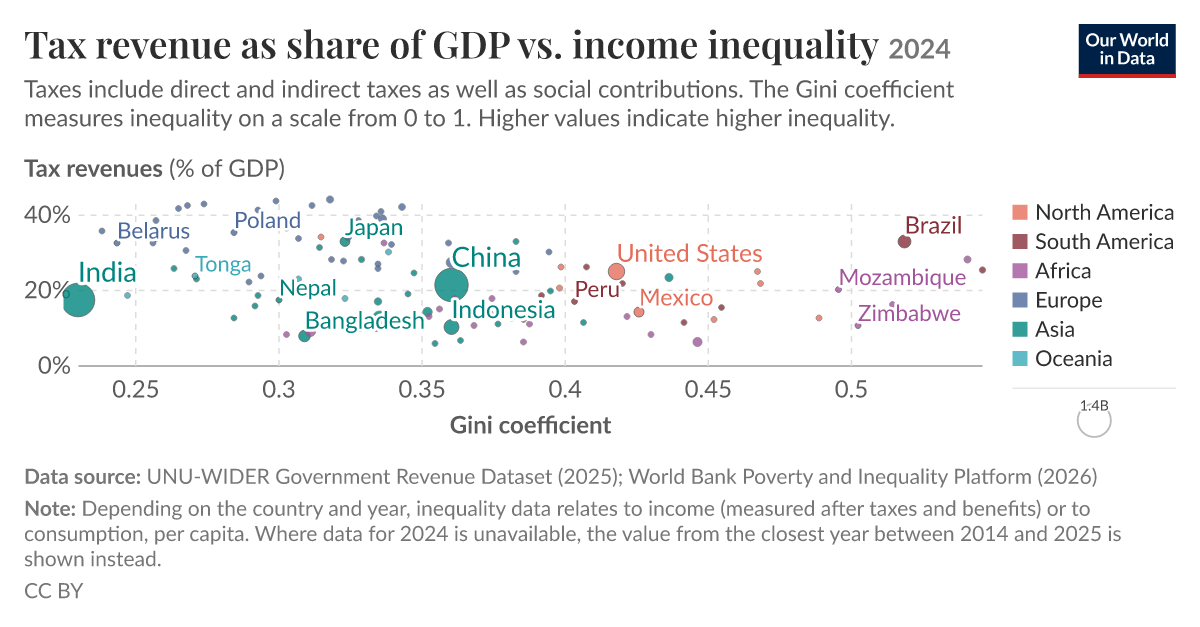
Step three: choose your comparison metric and stick with it. The median-to-mean ratio tells you about distribution skew. The P90/P10 ratio shows top-to-bottom dispersion. The Gini coefficient compresses everything into a single number between zero and one but loses information about where inequality sits in the distribution. A country can have the same Gini as another while its top 1% holds dramatically different shares. If your audience includes policymakers, give them the decile shares alongside the Gini. If they only look at the Gini, they will misread the picture entirely. Step four: run the comparison with proper confidence intervals. Income data is rarely normally distributed. Use bootstrap resampling to generate confidence intervals around your statistics rather than assuming parametric tests will behave. A difference that looks big on paper can fall well within the confidence interval when you account for sampling weights and cluster design effects. Most published comparisons skip this step, which is why half the income comparison papers you read should be treated as suggestive rather than conclusive.
Common pitfalls that will undermine your work
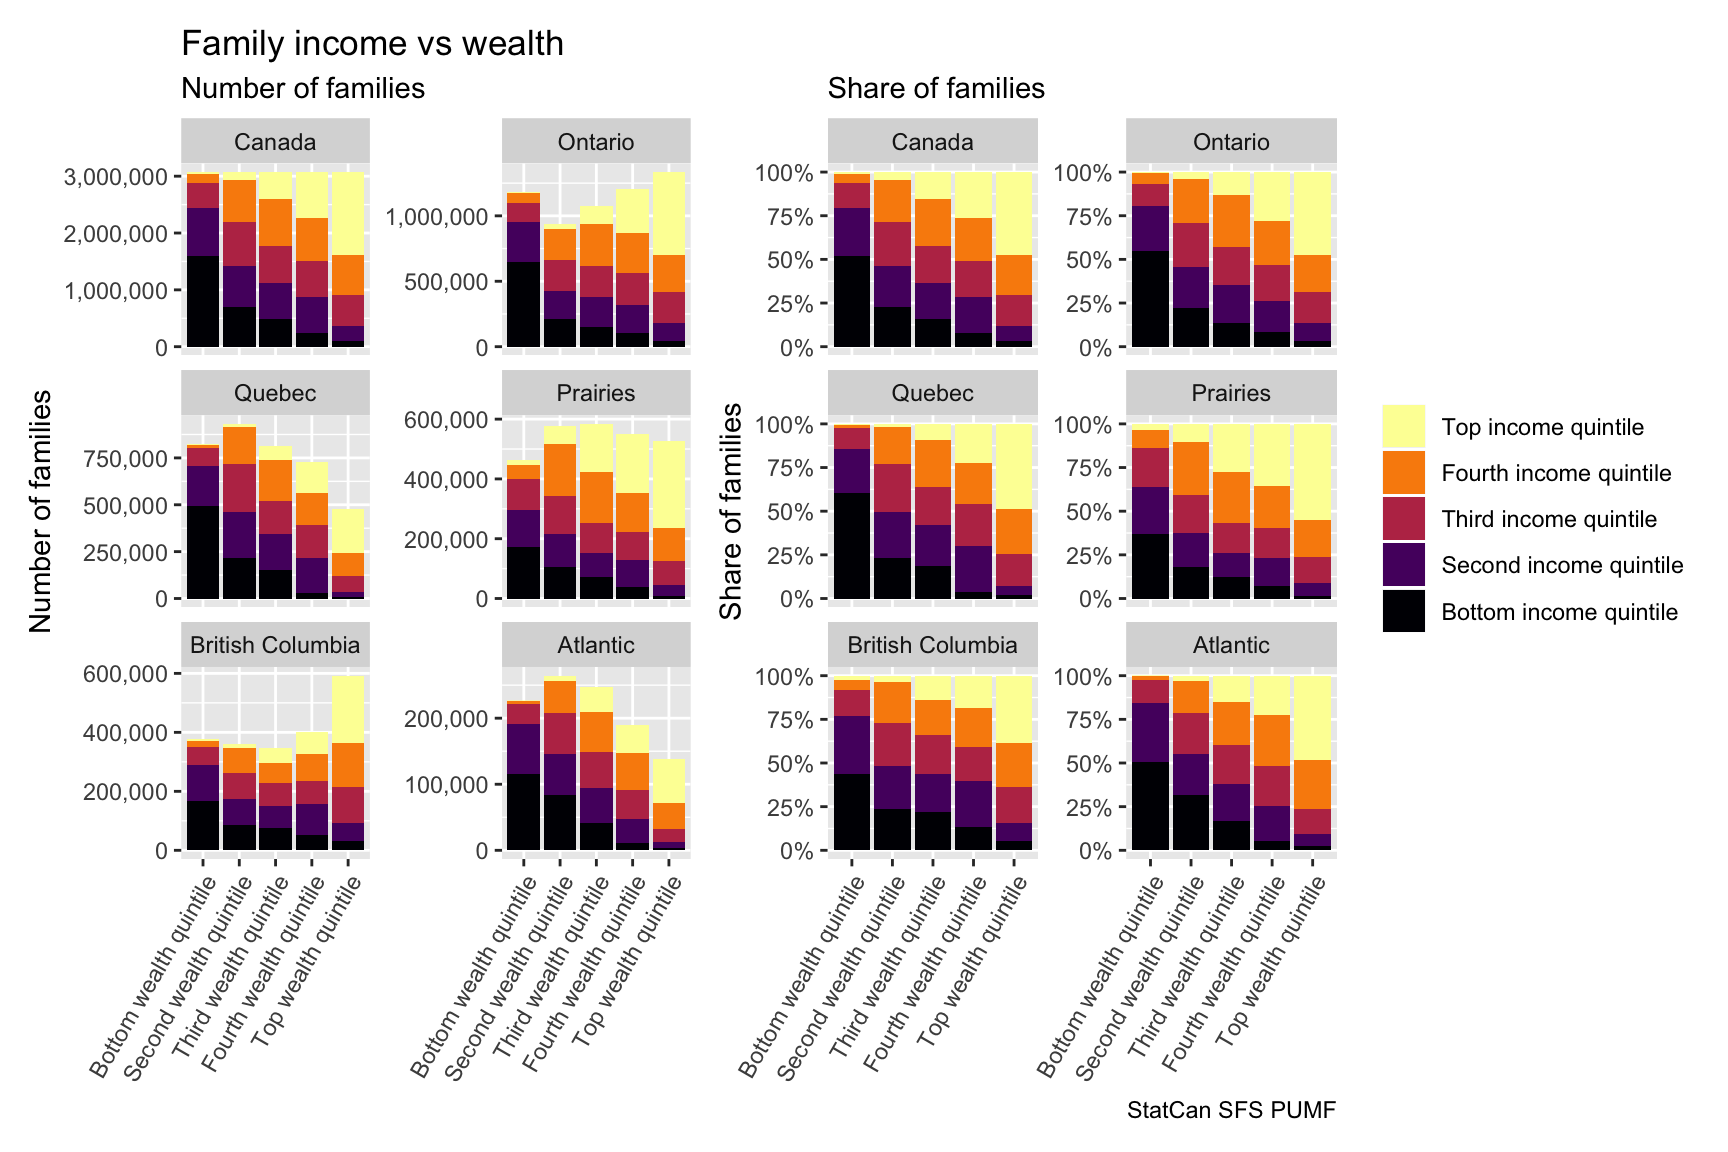
The first and most common error is comparing nominal income across regions or time periods without adjusting for purchasing power. A $30,000 income in rural Vietnam is not comparable to a $30,000 income in San Francisco. Use PPP-adjusted figures or local price indices. I have seen entire comparative studies invalidated because the author compared nominal figures across countries with wildly different price levels. The second error is ignoring household composition. A single earner supporting four dependents has a very different standard of living than a dual-income household with no children, even if their total household income is identical. Always use per-capita or equivalence-scale-adjusted measures unless you have a specific reason not to. Even then, state your reasoning explicitly. The third error is selection bias from non-response. Low-income individuals are less likely to participate in surveys, and high-income individuals are also less likely to participate. Both ends of the distribution go missing, which compresses measured inequality and makes groups look more similar than they actually are. Check your survey documentation for response rates by income bracket. If the top quintile response rate is below 40 percent, your Gini coefficient is almost certainly understated.
When this approach fails completely
Vs Income Sociology methodology does not work well in economies where the informal sector exceeds 40 percent of GDP. You cannot reliably compare income distributions if a substantial portion of economic activity is unrecorded. Migration economies are another weak spot. Temporary migrant labor flows distort cross-sectional snapshots badly. I encountered this when comparing income between two neighboring regions where one had become a destination for seasonal agricultural migrants. The destination region appeared wealthier in the survey data, but the effect was almost entirely driven by temporary workers whose remittances were counted in the destination rather than origin household incomes. Switching to a within-household panel analysis over multiple years resolved the distortion, but it required data that most researchers do not have access to. If you are working in a context with massive informal economies or high migration turnover, consider supplementing Vs Income Sociology with alternative measures like asset ownership, consumption expenditure patterns, or multidimensional poverty indices. Income data alone will mislead you in those settings.
The practical takeaway
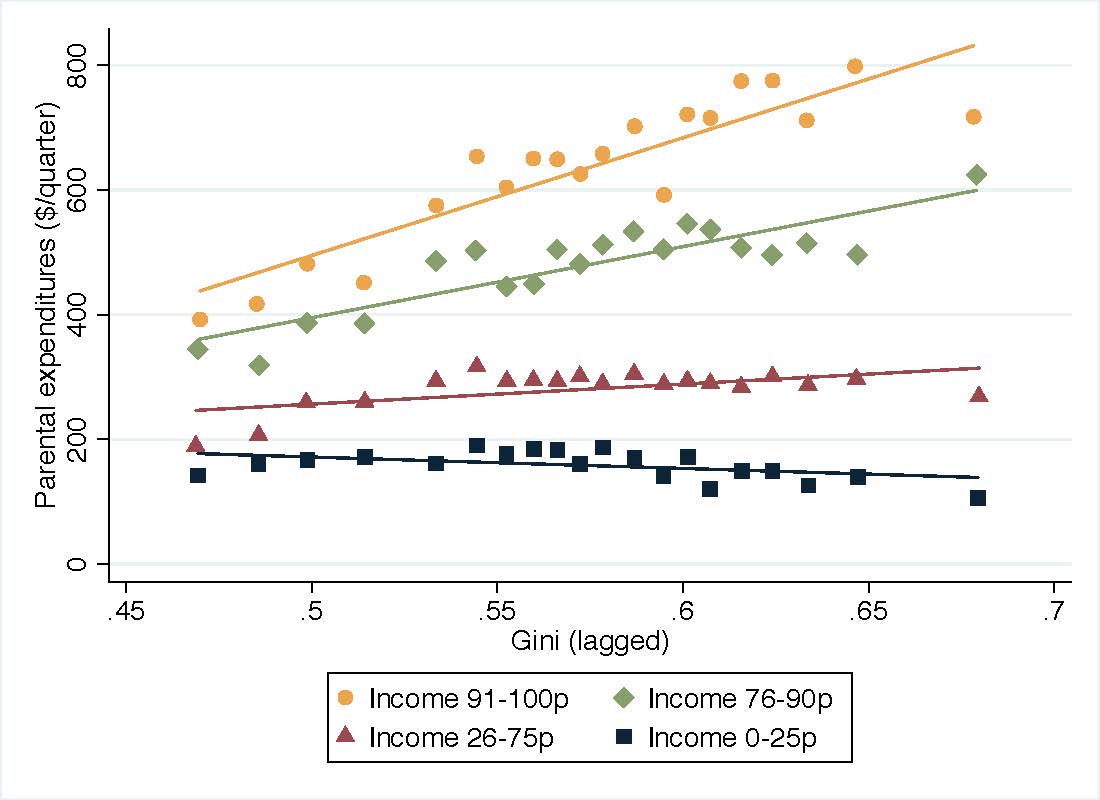
Most people doing income comparison never get past the surface-level statistics. They run a few regressions, report a Gini coefficient, and call it analysis. The difference between a competent comparison and a superficial one usually comes down to three things: adjusting for purchasing power and household composition, accounting for data collection bias at both ends of the income distribution, and presenting enough of the distributional picture that readers can judge the comparison themselves rather than relying on a single summary statistic. Run the bootstrap. Show the confidence intervals. Report the decile shares. Admit what your data cannot tell you. That is the difference between a comparison that holds up under scrutiny and one that gets torn apart in peer review.