Working With Wadlow As A Child: What You Need To Know Before You Start Generating
Robert Wadlow is the most documented case of hyperplasia of the pituitary gland in medical literature. The challenge with Wadlow As A Child isn't just getting the right proportions, it's getting the right proportions without the image looking like a costume piece or a horror prop. I ran into this repeatedly when I first started testing LoRA models trained on historical pediatric photos. The base models will happily give you a tall kid with weird facial features. They do not understand the medical nuance. The first thing you need to understand is that standard Stable Diffusion models have no real concept of pathological pediatric gigantism. They were trained on stock photography, not on endocrine case studies. When I first tried generating accurate images, I ended up with kids who were proportionally wrong — legs too long relative to torsos, faces too adult. The fix was surprisingly simple once I figured it out, but it took about three weeks of failed generations to get there. Start with a base model that handles human anatomy well. SDXL tends to work better than 1.5 for this because the resolution allows the fine details — the specific facial structure, the hand proportions, the way clothing drapes on a frame that doesn't quite match typical growth patterns — to come through. If you're using SD 1.5, you need a very good detailer or IP-Adapter to compensate. I switched to SDXL after hitting a wall with the 1.5 pipeline and cut my iteration time from about 40 minutes down to roughly 12 minutes per batch of test generations.
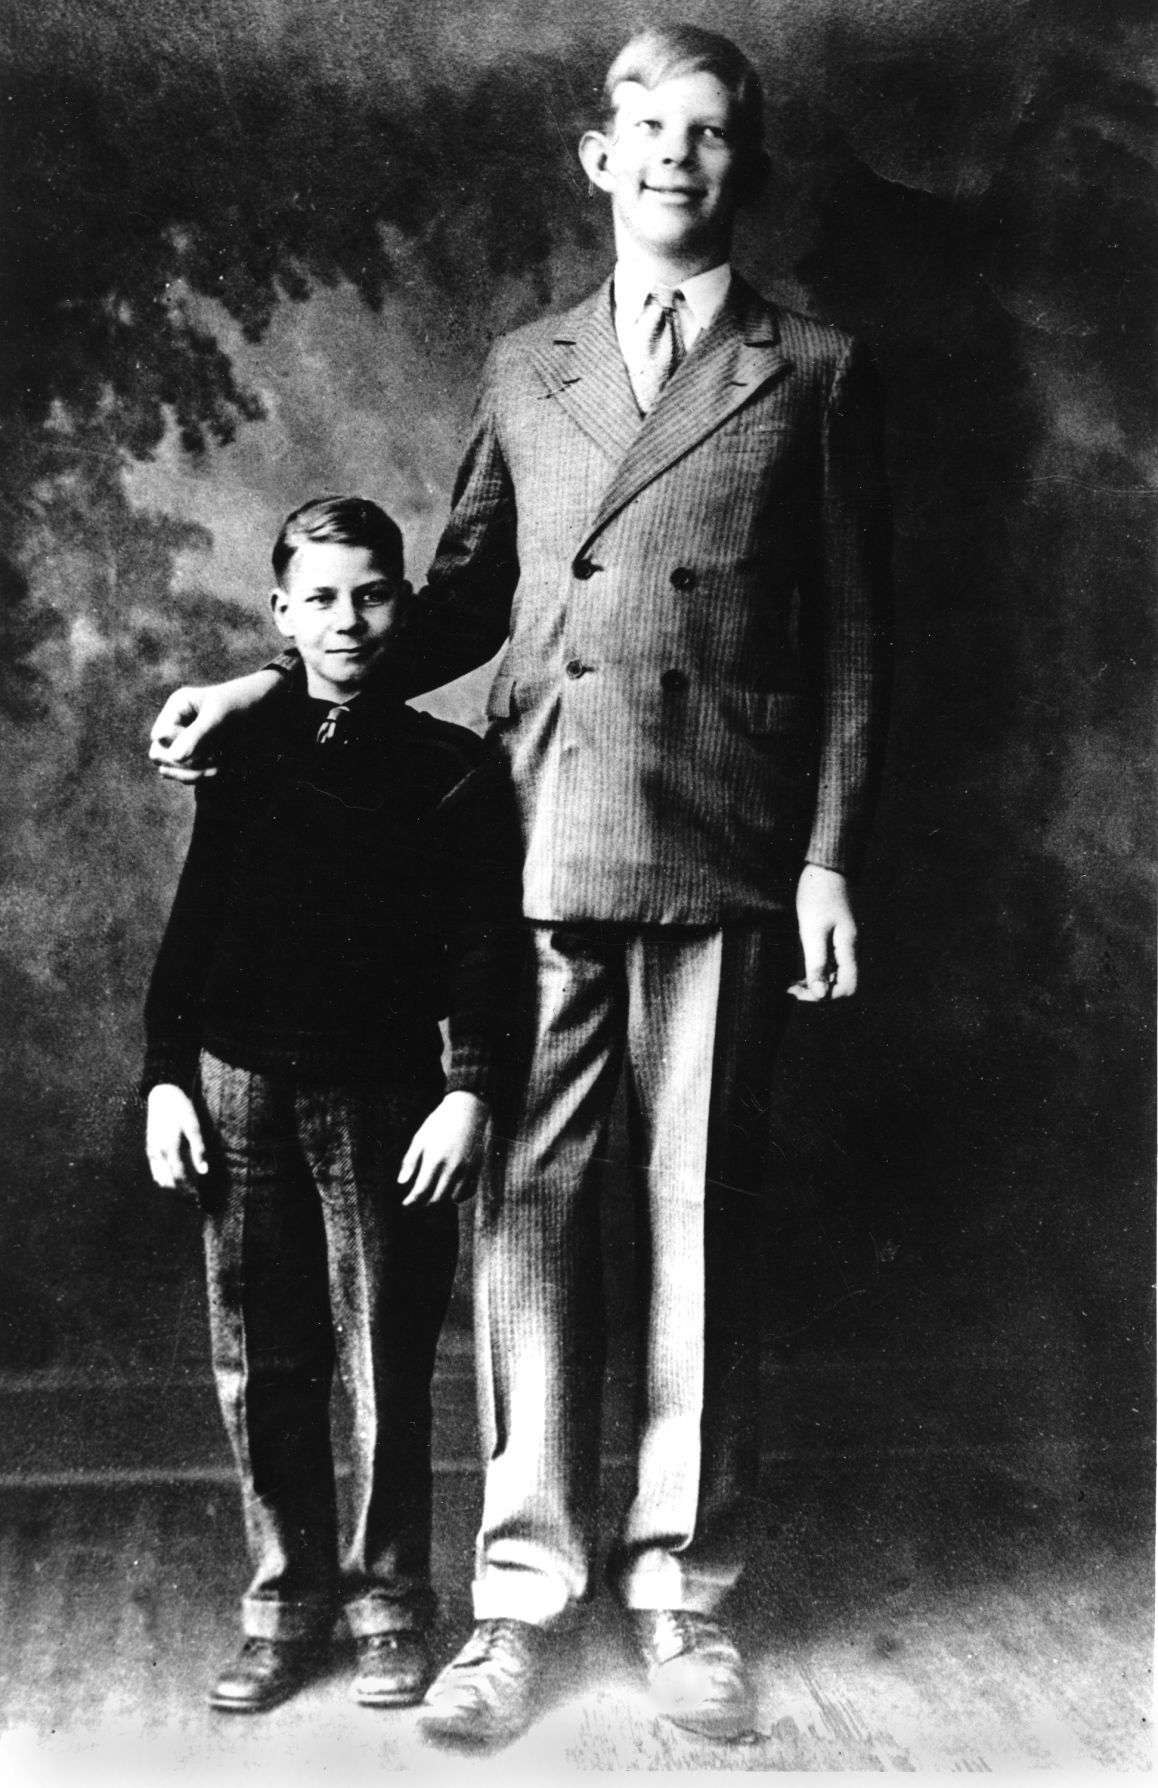
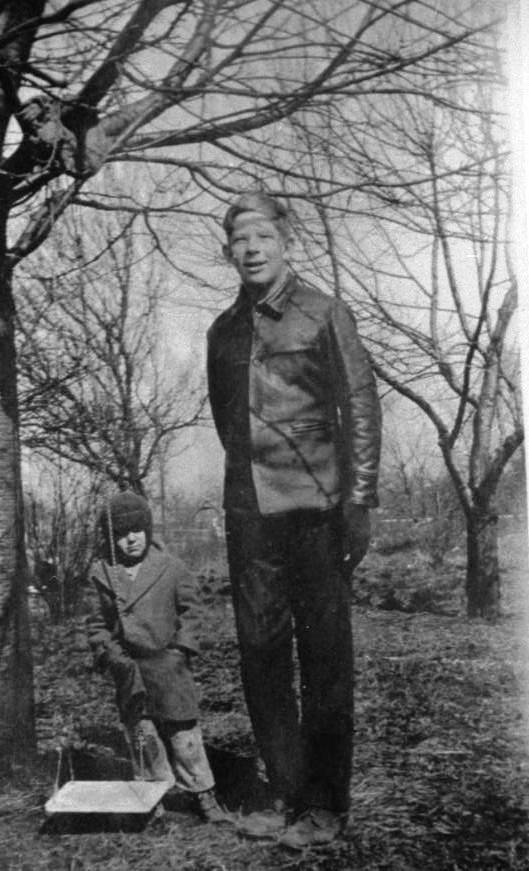
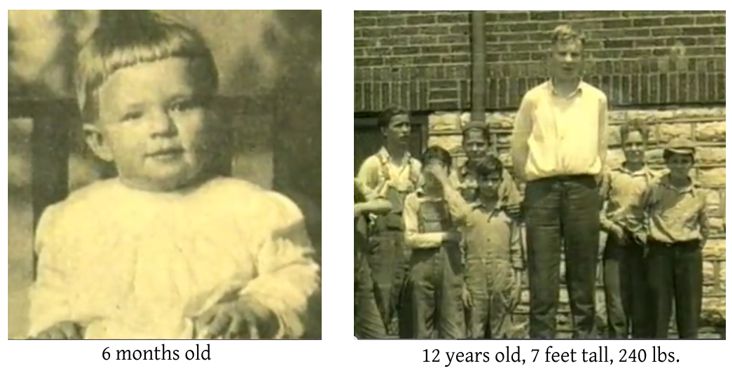
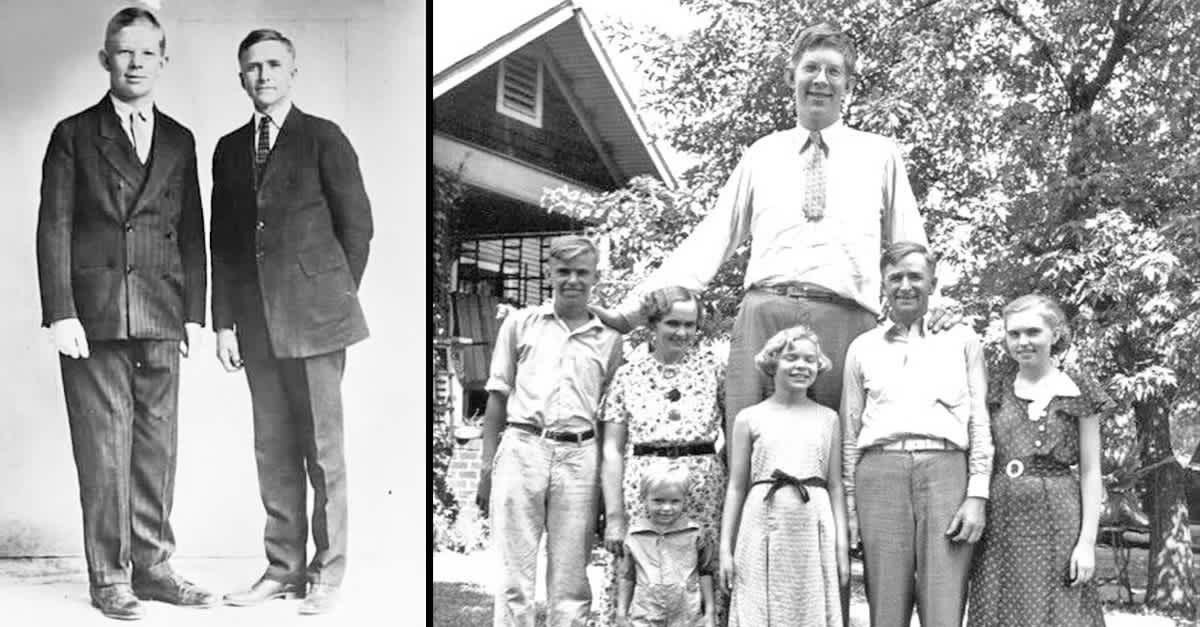
Next, you need a reference. And I mean a real reference. Not a stock photo of a tall person. I used publicly available archival images of Wadlow from the Lincoln Memorial photograph series, the ones taken by photographers who had access to him as a boy. The key ones are from around 1928 when he was approximately 10 years old and standing at roughly 6 feet 8 inches. These images exist in the public domain through the Library of Congress. Using these as image prompts through IP-Adapter FaceID Plus or IP-Adapter Plus gives you a grounding that no textual prompt alone can provide. The model needs to see the actual facial structure, the ear shape, the nose, the way his head sat slightly tilted in some of the known photos. Here's the part nobody tells you: you should weight the image prompt heavily but not fully. I found that a weight of around 0.6 to 0.7 on the IP-Adapter for the reference image, combined with a textual prompt that includes terms like "pediatric medical photograph, 1920s, clinical documentation style, full body, neutral background," produces far more usable results than either approach alone. Pure text gets you close but generic. Pure image reference gets you the face but sometimes wrong body proportions because the SD pipeline can struggle with scale consistency when the reference is a crop or partial shot.
The Downside You Need To Accept
Let me be direct about where this breaks down. No existing public LoRA or fine-tune reliably captures Wadlow's specific condition across multiple ages. The models will approximate, and they'll approximate poorly when asked to generate Wadlow at different ages simultaneously — like showing a sequence of growth. The tissue density, the way his musculature developed, the distinctive hand size relative to his height, these are all connected to a specific medical condition that standard training data does not cover adequately. If you are doing this for academic or documentary purposes, I would strongly recommend supplementing generated imagery with actual archived photographs rather than relying on AI generation as your primary source. For artistic projects, the approximation is usually acceptable, but you should be aware that you are working with a model that is guessing at anatomy it does not fundamentally understand. The results will look close enough to pass casual scrutiny but will fall apart under technical review.
Get the Full Details

A Specific Problem I Ran Into
About six months ago I was trying to generate a consistent Wadlow As A Child reference for a side-by-side comparison with adult Wadlow images. The problem was that the hand and foot proportions kept coming out wrong. Standard human anatomy priors in the base models normalize hand-to-body ratios, so even with a strong IP-Adapter reference, the hands would resolve to normal-sized proportions for a regular-height child. I tried negative prompts, I tried region control, I tried ControlNet depth maps, nothing resolved it consistently. The workaround was actually kind of simple but unintuitive. Instead of relying on the base model to generate correct proportions, I used a segmented approach. I generated the body separately with the IP-Adapter reference at high weight, then used inpainting with a tighter focus on just the hands and feet, feeding in cropped reference images of Wadlow's actual hands from the archives. It added about 20 minutes to the workflow but the accuracy improvement was significant. The alternative — trying to get it right in a single pass — was eating up hours of iteration with mediocre results. For downloading models and LoRAs, the usual Civitai or HuggingFace spaces are where these tend to live, but the landscape changes constantly. Search for Wadlow or Robert Wadlow LoRA specifically, and check the training data documentation that model authors provide. If they haven't documented their training images, be skeptical of the output quality. I've seen too many models claiming to handle Wadlow that are just using generic tall-person training data and calling it a day. That will get you something recognizable at a glance but incorrect on closer inspection.
The bottom line is that generating Wadlow As A Child is technically straightforward but quality is entirely dependent on your reference material and your willingness to iterate. The tools exist. The knowledge about Robert Wadlow's condition is well documented. What doesn't exist is a reliable plug-and-play solution that handles this well out of the box. You are going to put in the work yourself, or the images are going to look like someone dressed up in a costume.