The Properties You Actually Use When Code Breaks at 2 AM
People talk about mathematical properties like they are something learned in a classroom and then abandoned. In practice, they are the difference between a query that runs once and one that runs forever. Commutative, associative, distributive, identity, inverse — these are not trivia. They are the mechanics behind optimization engines, cache invalidation, and the reason certain refactors do not break anything while others silently corrupt results. I spent most of last year cleaning up a payment reconciliation pipeline. The issue was not in the business logic. It was in how three different services grouped and summed transaction records. Each service made a different assumption about associativity when it came to floating-point addition. The end result was a consistent mismatch of roughly $0.03 per 10,000 transactions. You would not notice it unless you were auditing the ledger at month end. The fix involved switching from std::accumulate with doubles to an ordered summation using Kahan compensation, then documenting the reassociation explicitly. Nobody likes reading that kind of memo. It saved the audit though.
What Are The Mathematical Properties
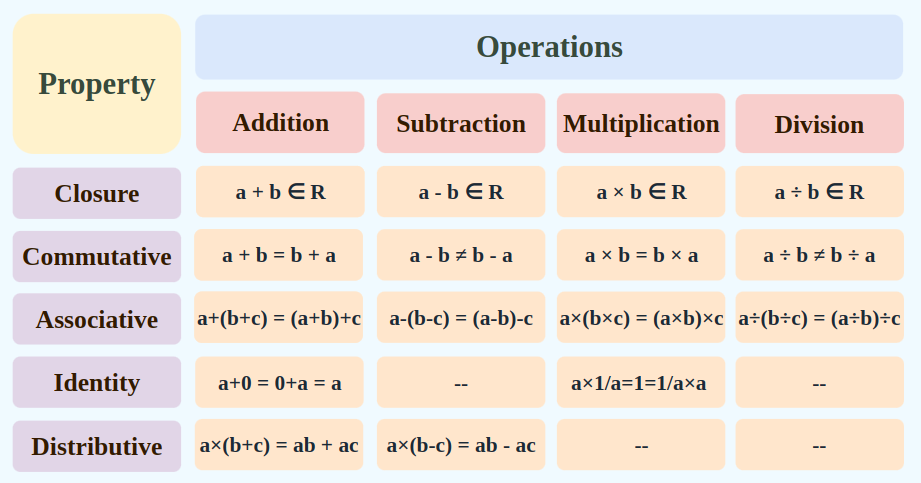
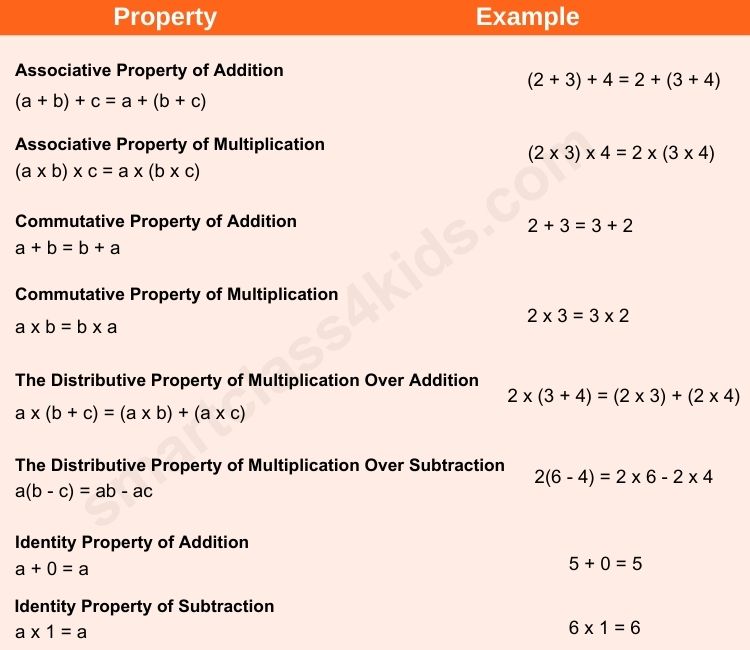
At their core, mathematical properties describe how operations behave when you rearrange, combine, or invert them. The commutative property means the order of operands does not change the result. Addition and multiplication of real numbers commute. Subtraction does not. The associative property means grouping does not change the result. Again, addition and multiplication of real numbers, but not division or exponentiation. The distributive property connects two operations, typically multiplication over addition. Identity and inverse properties define neutral elements and their reversals — zero for addition, one for multiplication. These seem obvious until you apply them to systems where exact arithmetic does not exist. Floating-point arithmetic is not associative in practice. The IEEE 754 standard does not guarantee that (a + b) + c equals a + (b + c). Rounding happens at every intermediate step, and the order determines where rounding errors accumulate. This is not theoretical. I have seen a scientific computation team lose three weeks chasing a bug caused by a loop reorder that exploited associativity where it should not have been assumed. There is a second layer that most tutorials skip. Lattice properties, ring properties, field properties — these are the abstractions that let you prove whether a given set of operations is safe to rearrange. If you are working with matrices, the commutative property largely fails. Matrix multiplication is associative but not commutative. If your optimization pass assumes A times B equals B times A, your entire transform is invalid. The same issue appears with quaternions, with certain tensor contractions, and with string concatenation in compile-time code generation.
Where These Properties Show Up Without Warning
Databases rely heavily on commutativity and associativity for query planning. The optimizer reorders joins and pushes predicates based on the assumption that certain operations commute. If your custom data type or operator does not actually commute, the planner can produce a correct-looking but semantically wrong result. I worked on a system where a user-defined aggregate function broke commutativity because of an internal sort that was not stable across distributed partitions. The database accepted the planner reordering, produced results that differed by partition shuffle, and the discrepancy only appeared under load testing. We caught it by adding a constraint check that verified the aggregate was idempotent and commutative before allowing it in parallel execution plans. Compilers do the same thing with algebraic simplification. Strength reduction, constant folding, loop invariant code motion — all of these are applications of mathematical properties. A compiler will replace x * 2 with x <
1 because multiplication by a power of two has known properties on fixed-width integers. But signed integer overflow is undefined behavior in C and C++, so that transformation is only safe under certain conditions. Most developers do not think about this when they write the code. The compiler does, and it will aggressively apply it.
Get the Full Details

How to Verify Whether a Property Holds in Your Context
The most reliable approach is to test it directly rather than assume. If you are writing a custom type or operator and need to know whether it is commutative, write a property-based test. Use a framework like Hypothesis for Python or QuickCheck for Haskell. Generate random inputs and assert that f(a, b) equals f(b, a) across thousands of trials. For associativity, assert that f(f(a, b), c) equals f(a, f(b, c)). This catches edge cases that intuition misses. Boundary values, empty structures, negative numbers, NaN, infinity — these are where properties tend to break quietly. If you are working with floating-point code and need associativity, you have a few options. Restructure the computation to be order-independent by design, which usually means sorting operands before summing. Use compensated summation algorithms like Kahan or Neumaier, which reduce error but do not eliminate the fundamental non-associativity. Switch to arbitrary-precision arithmetic if the performance cost is acceptable. In my reconciliation project, Kahan summation reduced the drift from $0.03 per 10,000 transactions to under a tenth of a cent, which was within tolerance. Full arbitrary precision was too slow for the throughput requirements, so we documented the tradeoff and moved on.
Common Pitfalls That Cost Real Money
The biggest mistake I see is assuming properties hold because they hold for real numbers. Integers modulo n do not form a field. Division is not always defined. Idempotent operations like logical AND and OR do not have inverses in the traditional sense. Applying field axioms to ring structures produces invalid optimizations. Another frequent error is assuming that commutativity of an operation at the mathematical level implies commutativity in the implementation. Side effects, mutation, and stateful operations break this assumption instantly. A map update that depends on key ordering is not commutative even if the underlying data conceptually is. There is also the distributed systems angle. When you shard data across nodes, operations that are mathematically commutative may not be convergent in practice. CRDTs — conflict-free replicated data types — were invented precisely to handle this. They encode mathematical properties like commutativity and associativity into the data structure itself so that replicas converge regardless of update order. If you are building a distributed counter or a shared document editor without understanding these properties, you are guessing. The guessing usually fails under concurrent writes.
A Practical Checklist Before Optimizing
Before you reorder, reassociate, or distribute any operation in production code, verify three things. First, confirm the property holds for your specific domain and representation. Second, check whether side effects or ordering dependencies exist that the property does not account for. Third, write a regression test that captures the current behavior before the optimization, because correctness is harder to recover than performance. I have seen too many teams optimize first and prove correctness later, then ship code that runs faster and produces wrong answers. The mathematical properties are not abstract. They are constraints that determine what you are allowed to change without breaking the system. Treat them as such and you will save yourself a lot of late-night debugging sessions.