Starting with the Math, Not the Philosophy
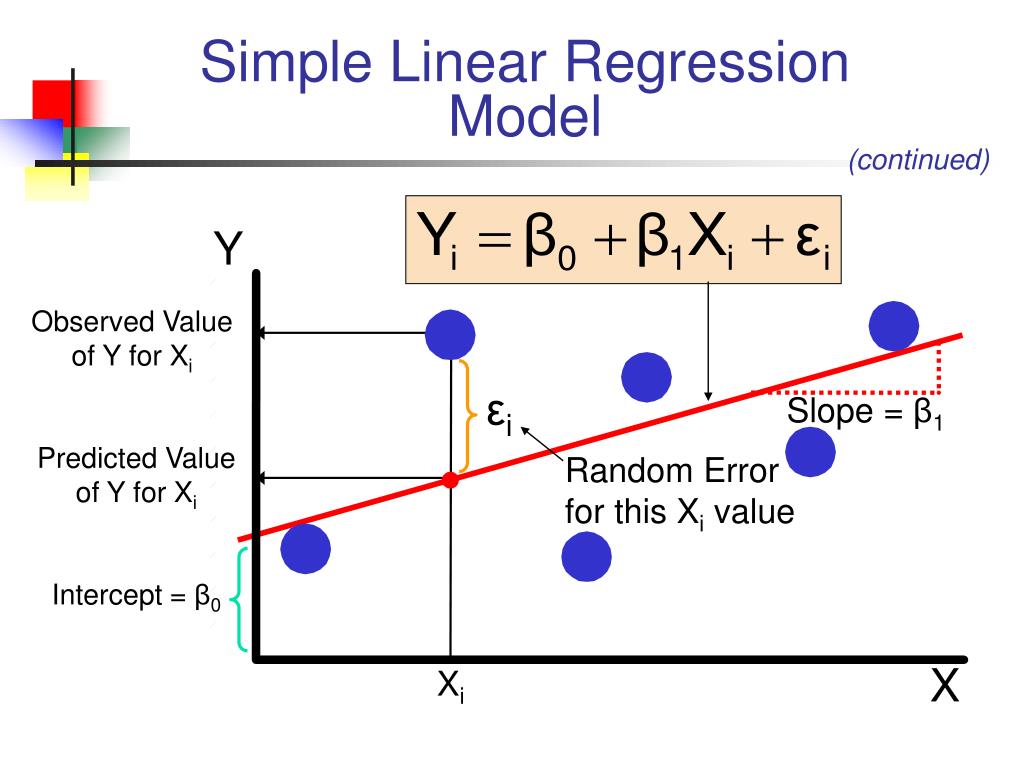
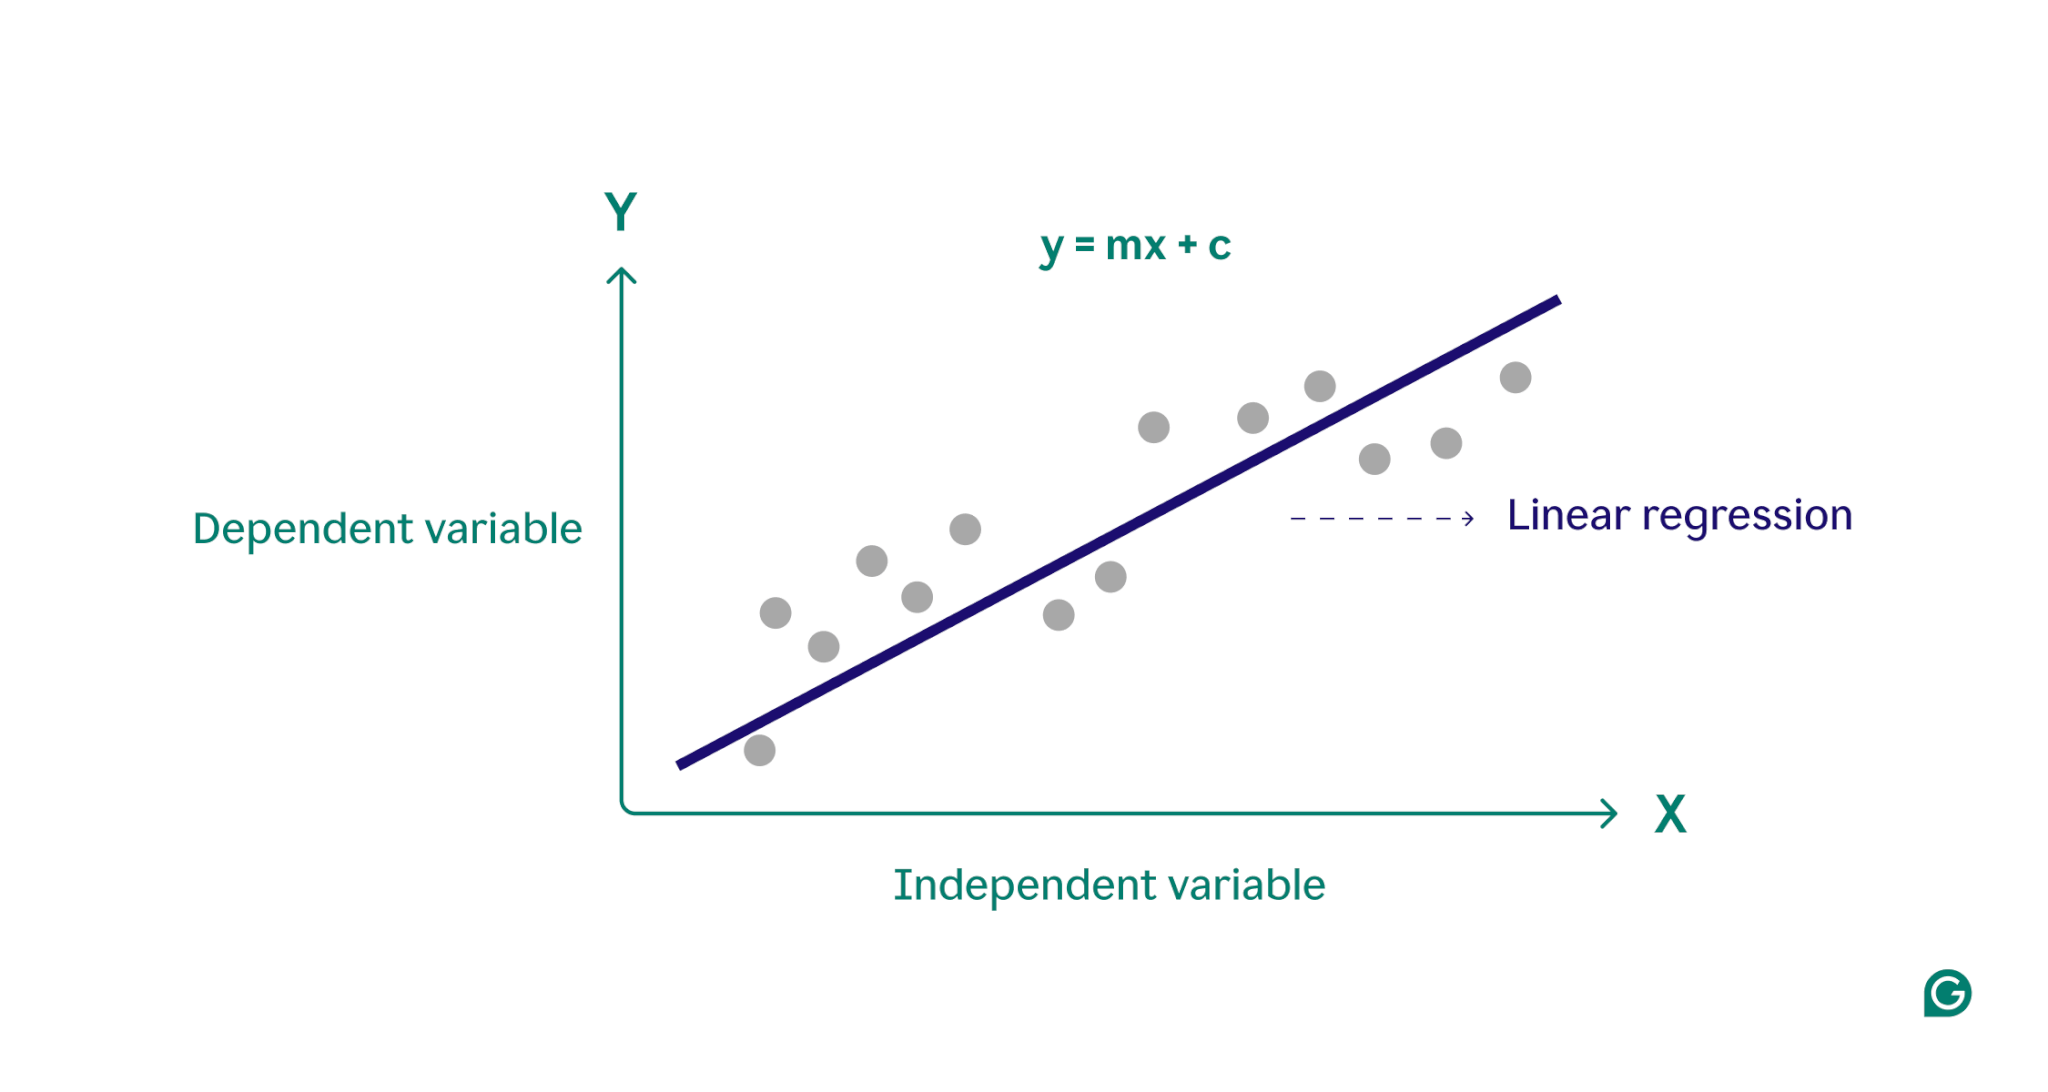
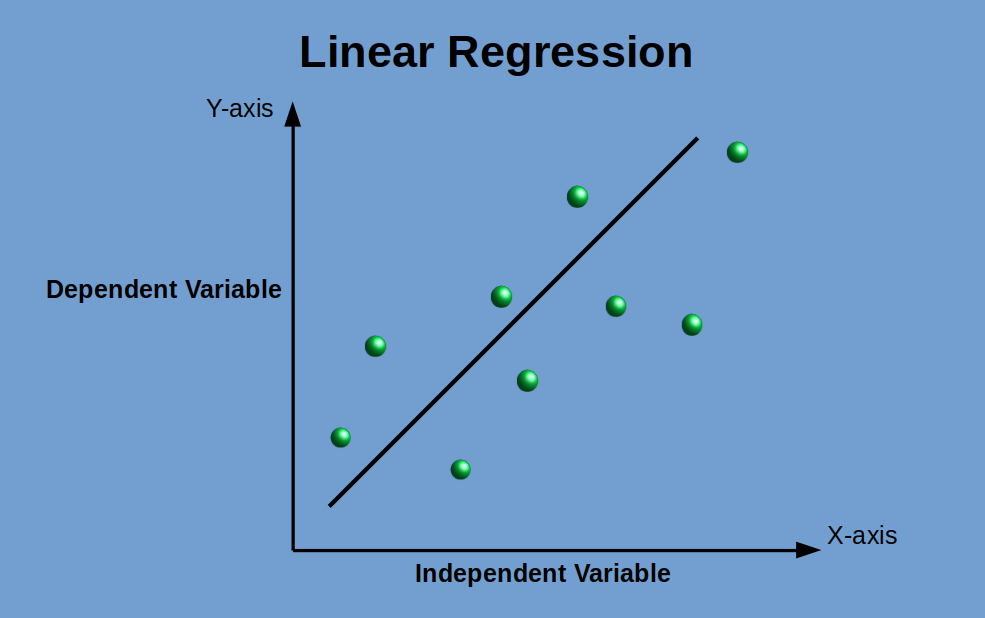
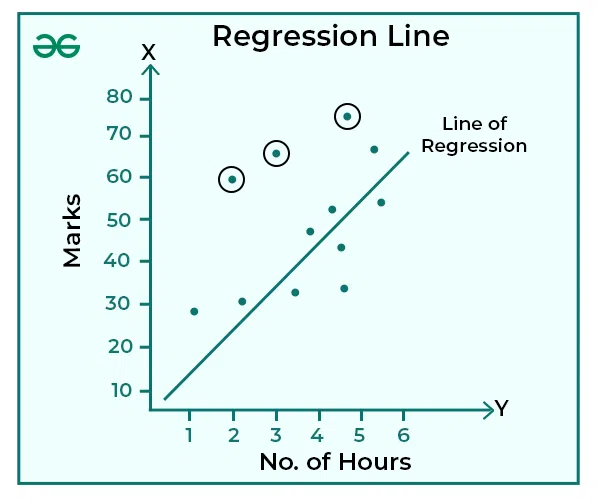
A regression line is the straight line that minimizes the sum of squared vertical distances between itself and every data point in a scatter plot. That's the definition, and it's also the practical starting point because most people who get confused don't need philosophy — they need to know what the line actually does before they try to interpret it. The equation is y = mx + b, or in statistics we usually write ŷ = + x. is the slope, is the intercept. The least squares method calculates those two numbers by finding the combination where the squared residuals add up to the smallest possible total. There's no magic to it. It's just algebra with a purpose.
What Is A Regression Line
When I first started working with regression in a production environment, I was handed a dataset of ad spend versus conversion rates and told to "find the trend." I plotted the points, ran the least squares fit, and produced a line. Everything looked fine on the surface. The R² value was decent. The p-value on the slope was significant. But when I actually used that line to forecast next quarter's performance, the numbers were wildly off. The problem was heteroscedasticity — the variance of the residuals wasn't constant across the range of x values. At low ad spend levels, conversions were tight. At high spend levels, they exploded in volatility. The regression line was still the best linear unbiased estimator under the standard assumptions, but those assumptions were violated, and nobody had checked. The workaround was straightforward once I identified the issue. I transformed the dependent variable using a log transformation, which stabilized the variance. Then I refitted the model on the logged data and back-transformed the predictions. The forecast accuracy improved noticeably. This kind of thing happens constantly in real work, and the standard textbook examples never prepare you for it. The core idea behind a regression line is prediction and explanation. It gives you a way to estimate what y will be for a given x, and it tells you how much y changes per unit change in x. But the usefulness depends entirely on whether the relationship is approximately linear and whether the residuals behave themselves. If you skip the diagnostic checks, you're just drawing a line and calling it science.
One thing beginners consistently miss is that R² is not a measure of model quality. It's a measure of how much of the variance in y is explained by the model relative to a baseline that just predicts the mean of y every time. An R² of 0.30 isn't necessarily bad — in social science or behavioral data, that's often considered useful. An R² of 0.85 isn't automatically good either. You can have a terrible model with a high R² if the data has strong autocorrelation or if you've overfitted to noise. I've seen models with R² above 0.90 that failed spectacularly on holdout data because the training set had temporal structure that the model learned instead of the actual relationship. Another thing that trips people up is confusing correlation with causation in the context of regression. The regression line describes association, not mechanism. If your independent variable is something like ice cream sales and your dependent variable is drowning incidents, the line will be steep and the relationship will be statistically significant. That doesn't mean ice cream causes drowning. It means both are driven by a third variable — temperature. Including temperature in a multiple regression would absorb that confounding effect and the coefficient on ice cream sales would drop toward zero. This is basic, but it's worth stating plainly because I still see it in reports from well-funded organizations. The computation itself is trivial on modern hardware. Ordinary least squares has a closed-form solution: = (X'X)¹X'y. For a simple univariate regression with n observations, this means inverting an n×n matrix in the derivation, but in practice you never actually compute that inverse directly. Numerical routines use QR decomposition or singular value decomposition, which are stable and fast. For a dataset with a few thousand rows, the calculation takes milliseconds. For a dataset with a few million rows and dozens of predictors, it might take a few seconds on a decent machine. The bottleneck is rarely the math — it's the data cleaning and the diagnostic checking.
Get the Full Details
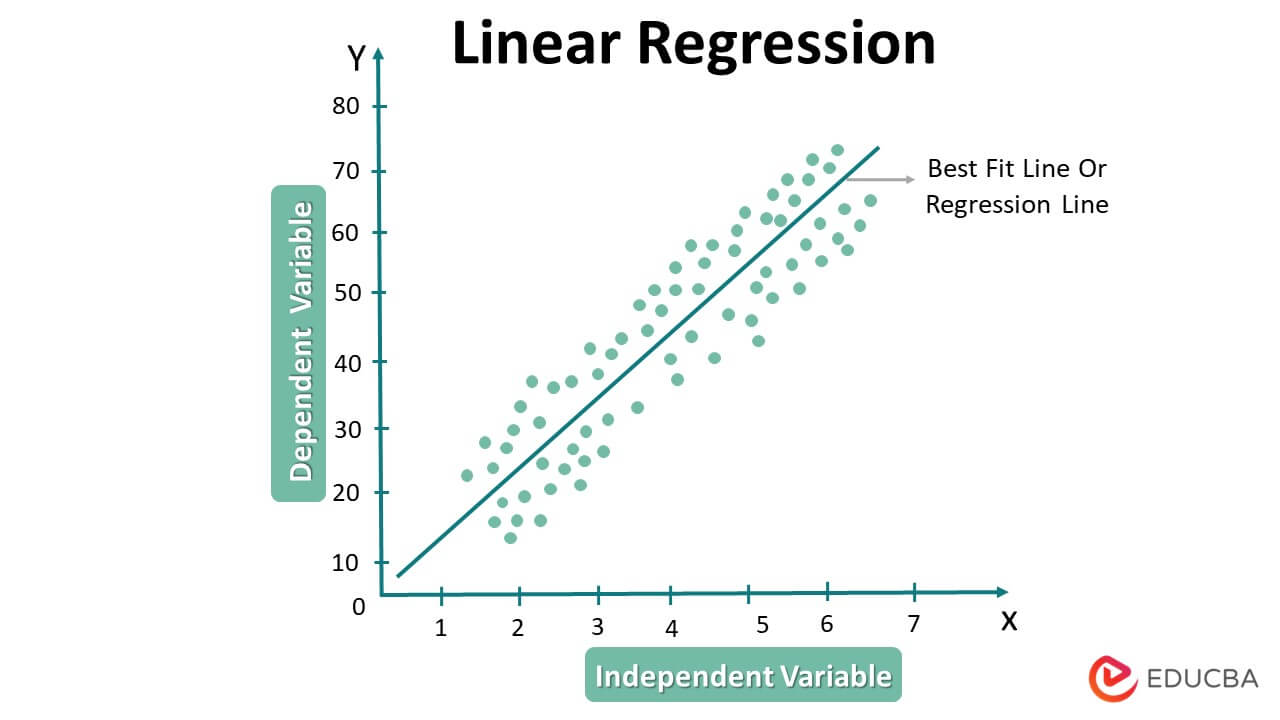
There are scenarios where a regression line simply doesn't work, and you need to stop and reconsider the approach. If the relationship is strongly nonlinear — U-shaped, exponential, saturating — a straight line will mislead you. You can add polynomial terms, but that introduces new problems like multicollinearity between x and x². The variance inflation factor can blow up, making your coefficient estimates unstable and your confidence intervals absurdly wide. A better approach in many cases is to use a generalized additive model or a spline-based fit, which lets the data dictate the shape without forcing a polynomial structure. Another failure mode is outliers and high-leverage points. A single observation with an extreme x value can pull the regression line toward it disproportionately. The leverage statistic h measures this for each point. In a simple regression, the leverage for observation i is h = 1/n + (x - x)² / (x - x)². Points with leverage greater than 2p/n, where p is the number of parameters, warrant investigation. I once had a single data point with x far outside the normal range that accounted for most of the apparent slope in the model. When I removed it, the slope dropped by about 60 percent and became statistically insignificant. Whether to keep or remove such a point is a judgment call, not a formula. Document your reasoning and move on. For practical implementation, you can use any standard statistical package. In Python, statsmodels and scikit-learn both handle OLS regression. In R, lm() is the default and it produces diagnostic output by default. In Excel, the LINEST function or the Data Analysis Toolpak will do it, though the diagnostic capabilities are minimal. The choice of tool matters less than the habit of always checking residual plots — residuals versus fitted values, Q-Q plots of residuals, and leverage plots. These three checks will catch most of the common problems in under two minutes.
If you're building a regression model for a business report and you only have time for one diagnostic, check the residual versus fitted plot. Patterns in that plot — a funnel shape, a curve, a cluster of points far from the rest — tell you more about model validity than any summary statistic. A random scatter around zero means the model is doing what it should. Anything else means you need to rethink the specification before you present the results. The regression line remains one of the most widely used tools in quantitative analysis because it's simple, interpretable, and computationally cheap. It's not a solution to every problem, and it's certainly not a substitute for domain understanding. But when the assumptions hold and the diagnostics look clean, it gives you a clear, actionable summary of the relationship between variables. That's all it's supposed to do, and when it works, it works well.