Scatter Plots Are Just Points On A Grid
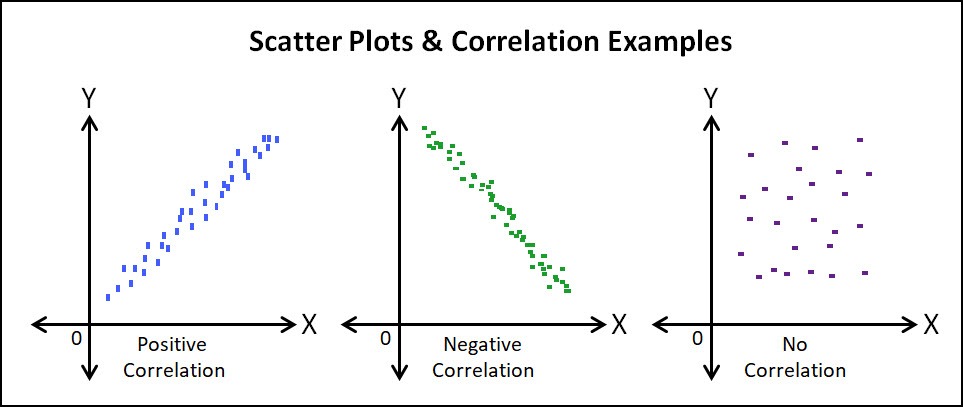
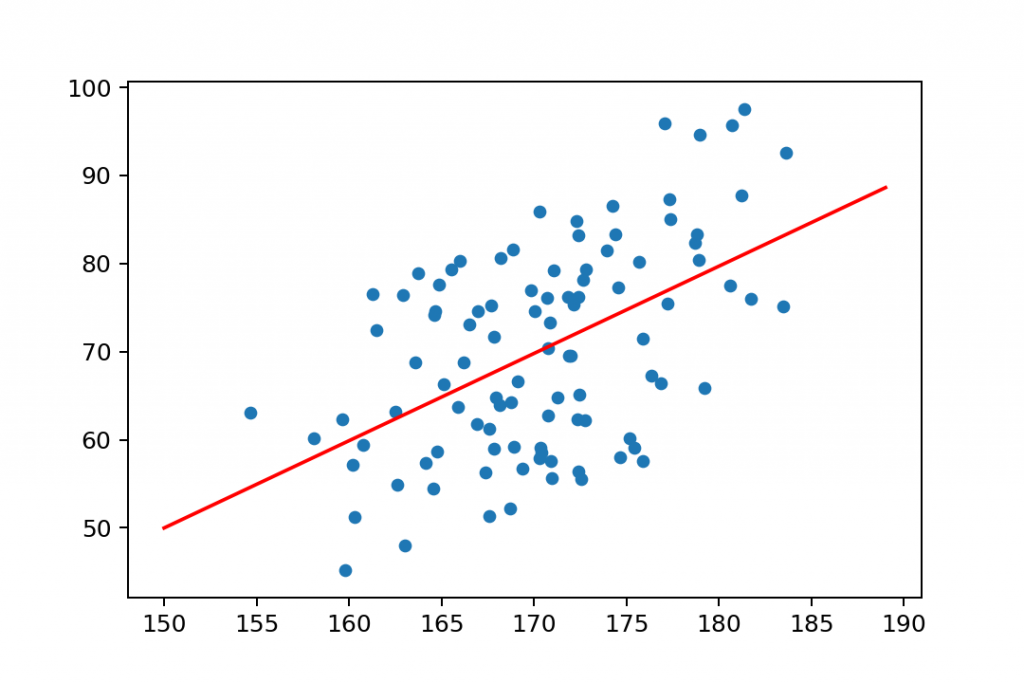
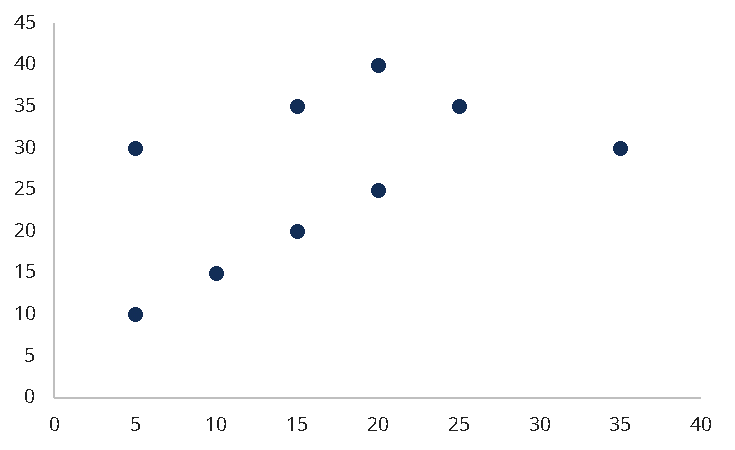
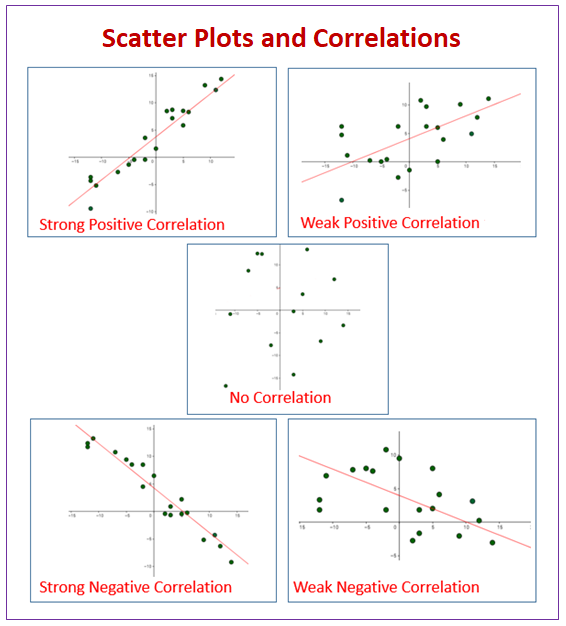
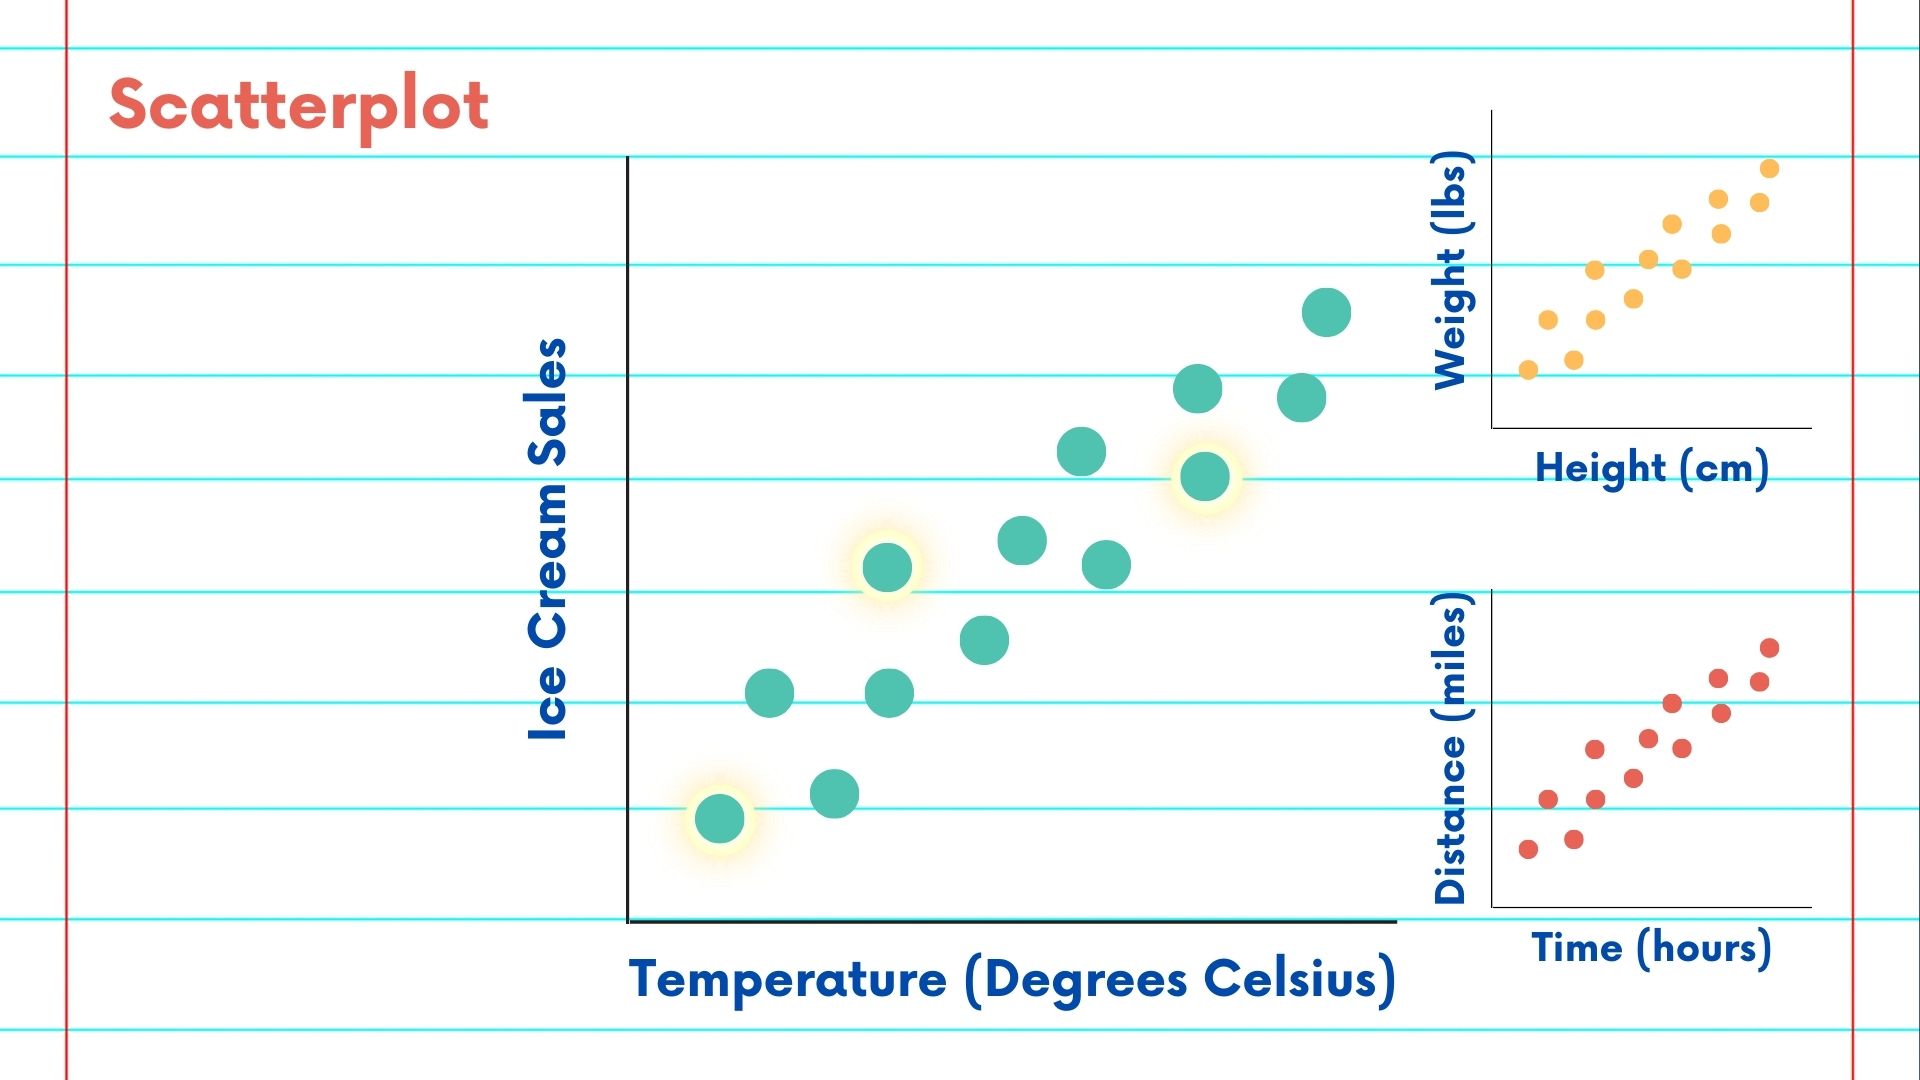
A scatter plot takes two numerical variables and plots each data point at the intersection of its X value and Y value. That is literally all it is. You have pairs of numbers, you drop dots on a coordinate system, and you look for patterns. Correlation, clustering, outliers, trends — the plot reveals whatever structure lives in your data. Nothing more. The reason people get confused isn't the concept. It is the implementation choices that make or break whether the plot actually tells you anything useful.
What Is A Scatter Plot Used For In Practice
Most professionals use scatter plots for three things: checking correlation before running regression, spotting outliers that will wreck a model, and visualizing how two continuous variables relate across subgroups. The last one is where most people fumble. When you add a categorical variable, you are now layering a third dimension onto a 2D chart, and if you do it carelessly the result is unreadable. I had a situation last year where I was plotting employee salary against years of experience across five departments, and the overplotting was so severe that the correlation between the two variables became invisible. Thousands of points stacked on top of each other in the same pixel space created a solid blob with no discernible shape. The workaround was a combination of alpha blending at about 0.3 opacity, jittering the points by a few pixels in both directions to reduce overlap, and then switching to a hexbin overlay for the densest clusters. That single change let me see a weak positive correlation that was completely hidden before. It took me maybe twenty minutes to implement after debugging the first pass.
The Mechanics Behind A Basic Scatter Plot
Building one is straightforward. You assign your independent variable to the horizontal axis and your dependent variable to the vertical axis. Each observation becomes a single marker at the coordinate defined by those two values. The axis scales should be linear by default unless your data spans several orders of magnitude, in which case a log scale on one or both axes is often more honest about the relationships you are trying to show. What most beginners miss is that the choice of marker matters more than they realize. Default circular markers work fine for small datasets with clear separation. But once you cross a few thousand points, circles blend into each other and the human eye starts losing spatial resolution. Square markers, plus signs, or even small filled circles at reduced opacity all render differently depending on the tool you are using. In Python with Matplotlib, for example, the default behavior without setting alpha or size parameters will produce a chart that looks informative at first glance but collapses into an indecipherable mass once the dataset grows beyond a few thousand rows. Another thing that catches people off guard: the scale of your axes can create an illusion of correlation that does not exist. If you fix one axis to a narrow range and let the other axis autoscale to include outliers, the points will appear tightly clustered along a diagonal even when there is no real relationship. I saw this happen repeatedly when someone was presenting regression diagnostics and the residual plot looked deceptively clean because the outlier values on the Y axis were stretching the scale so much that the actual spread of the bulk of the data compressed into a thin line. Setting both axes to the same scale and checking the aspect ratio fixes this almost immediately.
Get the Full Details

Common Mistakes That Ruin A Scatter Plot
Categorical variables treated as continuous is the most common error. If your X or Y axis contains discrete categories encoded as numbers — department codes, product IDs, survey Likert scales — the plot will connect the dots with an implied continuity that does not exist. The fix is simple: convert those to strings or use a nominal color palette instead of a sequential one. Matplotlib will handle the labeling correctly if you pass the data as categorical types rather than integers. Choropleth confusion is another area where people lose credibility fast. A scatter plot cannot show geographic data meaningfully. If your data has a location component and you force it into a scatter format, you are hiding information, not revealing it. Use a map-based visualization instead, or at minimum add a facet grid by region if you need to keep it in the same figure. Overfitting the visual is the third frequent mistake. Adding trend lines, confidence bands, marginal histograms, and subgroup legends all in one chart makes the result look sophisticated but renders it nearly impossible to extract any single insight from. A good scatter plot communicates one relationship clearly. Everything else is secondary. I usually recommend starting with the raw points, adding a trend line only if the relationship is genuinely ambiguous, and putting everything else in a separate panel or a different chart entirely.
How To Build One In Python With Pandas And Matplotlib
Here is the practical path. Load your data into a DataFrame, ensure both columns are numeric, and call the scatter function. That is the core of it. For a quick setup, import matplotlib.pyplot and pandas, read your CSV file, and run a basic plot command with the column names mapped to X and Y. Add a label and a title if you need to share the chart with someone who will not look at the axis annotations. The whole process takes about three to five lines of code and runs in under a second for datasets up to a million rows on a typical machine. When you need more control, set the figure size explicitly, choose a marker style that suits your data density, adjust the edge color to avoid the default thick outlines that clutter the view, and consider using seaborn on top of matplotlib if you want built-in regression fitting with confidence intervals. Seaborn's regplot and lmplot functions handle the trend line and confidence band automatically, which saves you from writing the OLS calculation yourself.
For export purposes, save your figure with a resolution of at least 150 DPI if it is going into a document and 300 DPI if it is for print. PNG is fine for screen sharing. SVG is better if you need to zoom without losing clarity, since it is a vector format and scales cleanly to any size.
When A Scatter Plot Is The Wrong Tool
Scatter plots require two continuous variables. If either variable is purely nominal with more than about six categories, the chart becomes a vertical stack of points that provides no additional insight over a bar chart. If both variables are ordinal with many repeated values, you will hit the overplotting problem again very quickly. In those cases, a heatmap or a barchart with error bars gives you more information per unit of visual space. Sparse datasets with fewer than fifty points can also be misleading in a scatter plot because the human brain tends to infer structure from randomness. A table or a small multiple line chart might communicate the same data more honestly when the sample is that small. Time series data plotted as a scatter ignores the temporal ordering entirely. A line chart or an area chart preserves the sequence and usually tells a clearer story. Scatter plots are for relationships, not sequences.