Numbers Over Impressions
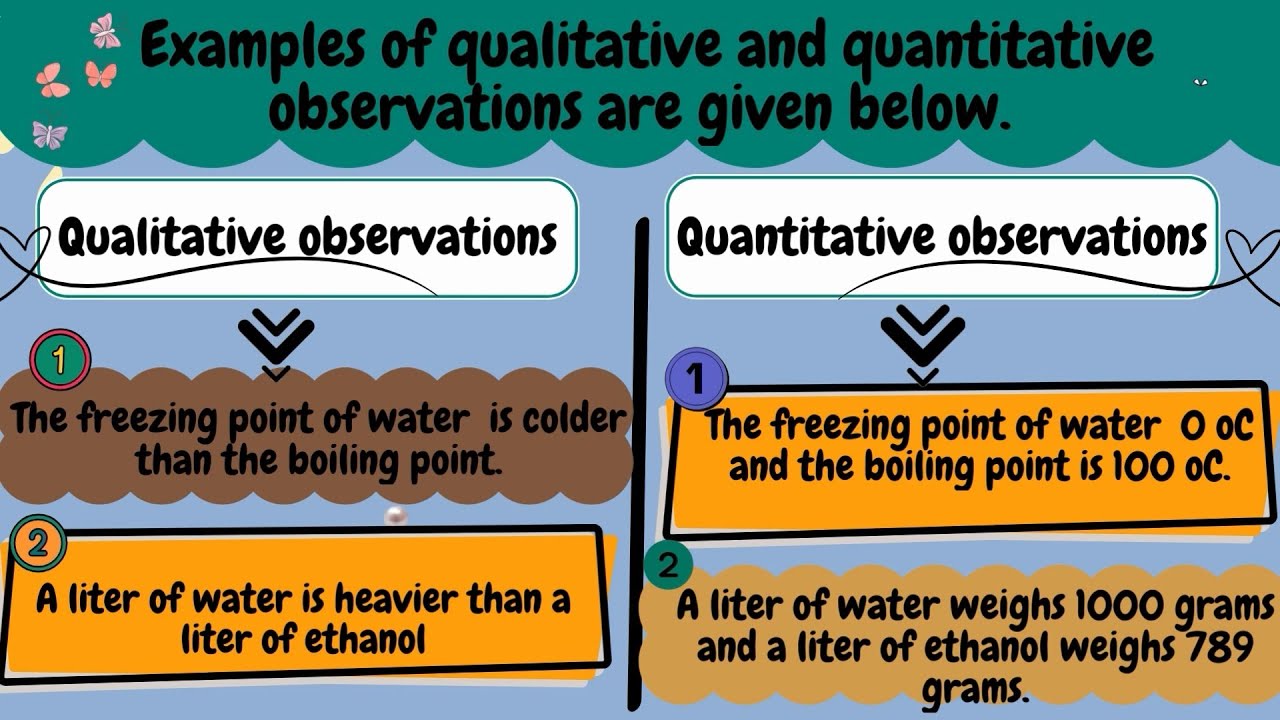
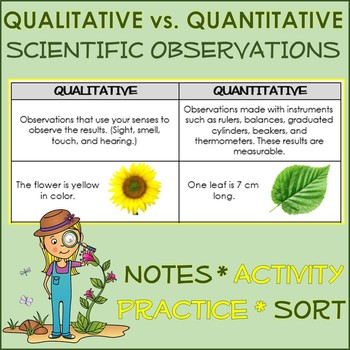
Most people walk into a lab and start eyeballing things. They look at a culture plate and say it looks really cloudy, or they time a reaction and note it was roughly two minutes. That is qualitative observation, and it is fine for a first pass. The problem is that roughly two minutes does not hold up to scrutiny when someone else tries to replicate it. What Is Quantitative Observation In Science is the process of replacing vague descriptors with measurable values that another person can verify independently. It sounds basic, but the jump from "it turned blue" to "the absorbance at 600 nanometers was 0.47 after 180 seconds" is where a lot of early-career researchers get stuck. They treat numbers like decoration instead of data. The workflow is straightforward once you stop treating it as something mystical. You pick a variable, choose a tool that can resolve it, calibrate that tool against a known standard, take the measurement, record it with the correct significant figures, and repeat enough times that random noise settles down.
What Is Quantitative Observation In Science And Why It Breaks Without Calibration
I spent a semester watching undergrads try to measure the growth rate of yeast using a kitchen scale. Their numbers looked clean on paper, but the growth curves were all over the place. The issue was not their technique. It was that the scale had a 0.5 gram drift tolerance and the yeast pellets were consistently hitting the lower end of the readable range. Every batch read slightly differently depending on ambient temperature and how the dish sat on the platform. Once I swapped them for a calibrated analytical balance with 0.0001 gram resolution and told them to tare the dish before every reading, the variance dropped from about 12 percent down to under 2 percent within three trials. That is the actual difference quantitative observation makes when you treat it like a discipline instead of a checkbox. Here is the part nobody tells you clearly: quantitative observation is not the same as precise observation. Precision is about repeatability. Accuracy is about being right. You can measure something precisely and be systematically wrong if your instrument is uncalibrated or your method introduces bias. I have seen this constantly with pH meters that had drifted by half a unit because the calibration buffers were expired. The numbers looked consistent across five replicates. They were all consistently wrong. Running a fresh calibration before each session takes about four minutes and saves you from spending three weeks trying to explain anomalous results in a revision. The tools are whatever resolves your variable at the scale you need. That means volumetric pipettes instead of graduated cylinders when you are doing dilutions, spectrophotometers instead of visual color comparison, thermocouples instead of liquid-in-glass thermometers when you need sub-degree precision, and digital calipers instead of tape measures for anything smaller than a centimeter where geometry matters. The choice is usually dictated by the tolerance your hypothesis requires. If your expected effect size is 5 percent, a tool with 10 percent resolution is useless no matter how precisely you use it. Match the instrument to the minimum detectable difference before you collect a single data point.
Recording matters as much as measuring. I once reviewed a dataset where someone logged mass as 2.3 grams across dozens of trials, but the balance displayed two decimal places and they were rounding everything down. The pattern masked a real trend in the fourth decimal. Writing down exactly what the instrument showed, not what you think it should show, prevents retroactive smoothing that turns real signals into noise. If the device reads 2.347 grams, you write 2.347 grams. Your brain will lie to you later if you pre-filter the numbers as you record them. Significant figures are not a pedantic exercise. They communicate uncertainty. Reporting a length as 12.00 millimeters tells the reader your instrument resolves to hundredths of a millimeter and your measurement carries that level of confidence. Reporting it as 12 millimeters implies a much coarser resolution. Mixing levels of precision across a dataset without adjusting for it creates false confidence in derived calculations. If you divide a value measured to three significant figures by one measured to two, the result cannot legitimately carry more than two. Students routinely forget this and report five-figure answers from two-figure inputs, which makes the data look more reliable than it actually is. Replication is where most people cut corners. Three trials is the absolute floor for anything you intend to publish or build upon. Five to ten is the practical range for standard lab work before diminishing returns kick in. I usually aim for seven unless the measurement process is destructive or expensive, in which case I prioritize three robust replicates with proper controls and a clear explanation of why more was not feasible. Power analysis can tell you the exact number you need if you have estimates for variance and effect size, but you do not always have those upfront. In practice, seven trials catches most common sources of random error without wasting materials.
Get the Full Details

Control variables are not optional. A quantitative measurement is only meaningful if you know what else was held constant. Temperature, humidity, operator, time of day, batch of reagents, equipment serial number. I keep a metadata sheet for every experiment that logs these alongside the raw readings. Two years later, when a reviewer asks why one trial spiked, I can check whether the air conditioning cycled on during that run or whether a new lot of buffer was opened. Without that record, the spike becomes a mystery you pretend did not happen. Quantitative observation also fails in specific scenarios and you should know when to switch methods. If your variable changes too rapidly to capture with your instrument, like a reaction completing in under two seconds, a standard stopwatch and manual reading will introduce human latency errors around 0.2 to 0.3 seconds per trial. That is a 10 to 15 percent error margin at best. In those cases, you either use a fast sensor with data logging at 100 hertz or higher, or you slow the reaction down by lowering temperature or concentration so your existing tools can resolve it. Forcing a slow instrument to measure a fast event just produces noisy garbage you will waste time trying to analyze later. Another hard limit is when the phenomenon itself is stochastic at the scale you are observing. Single-molecule fluorescence, particle decay events, certain biological assays with low copy numbers. Repeated measurements will not converge to a stable mean in the way you expect because the underlying process is not deterministic at that scale. Here you shift from traditional quantitative observation toward statistical modeling of distributions, and you need enough events to fit the model rather than just averaging repeated readings. Treating Poisson-like data with simple arithmetic means will mislead you every time.
The biggest practical pitfall is ignoring the resolution and accuracy specs of your instrument and assuming the displayed number is trustworthy. A digital thermometer claiming 0.1 degree resolution might have an accuracy of ±1 degree. That means the display changes in neat little increments while the true value could be wandering almost a full degree away from what you see. Check the manufacturer's accuracy specification, not just the resolution, and design your experimental tolerance around the accuracy. This usually takes about ten minutes of reading the manual and saves weeks of confused results. Calibration curves are another area where shortcuts create problems. If you are using a spectrophotometer, running a blank and then measuring unknowns assumes linearity across your range. It is often linear between 0.1 and 0.8 absorbance units, but outside that range the relationship bends. I always run at least five standard points spanning the expected range of my samples and check the R-squared value and residual plot. If the residuals show a pattern instead of random scatter, the linear model is wrong for that range and I either dilute my samples into the linear zone or fit a higher-order curve. Skipping this step is how you get publication-quality-looking data that is structurally flawed. Documentation should allow someone else to reconstruct your measurements from scratch. Raw data files, calibration certificates, instrument software versions, environmental conditions during measurement, and the calculation sheet or script used to process the data. I store everything in a folder named by date and project, with a README that lists the chain of custody from sample collection to final number. It sounds excessive until you need to reproduce a result six months later and realize you cannot remember whether you used deionized water or distilled water for the standards.
The workflow I use takes about 15 minutes per measurement cycle once set up: power on instrument, let it warm up for the recommended time, run calibration check, zero the blank, measure replicates, log metadata, clean up. A full session with seven replicates across three conditions usually runs 45 to 60 minutes depending on instrument recovery time between samples. If it is taking you two hours for the same amount of data, something in your setup is inefficient and you should audit where the delay is coming from. Error propagation deserves more attention than it gets. When you calculate a derived quantity from multiple measurements, the uncertainty in each input carries through to the output. Adding a volume measured to ±0.05 milliliters to a mass measured to ±0.0001 grams will produce a result where the volume uncertainty dominates. I calculate propagated uncertainty for every derived value because it tells you which measurement actually limits your confidence. Often you find that improving your least precise measurement gives you the most return. This usually redirects effort away from obsessing over the most precise instrument and toward fixing the weak link in the chain. Blind measurement helps reduce observer bias, especially when you expect a particular result. If you know which sample is the treatment and which is the control, your brain will unconsciously nudge readings in the expected direction. I label samples with codes instead of names during measurement and only decode them after the data is locked in. This takes one extra step and eliminates a class of error that is nearly impossible to detect after the fact.
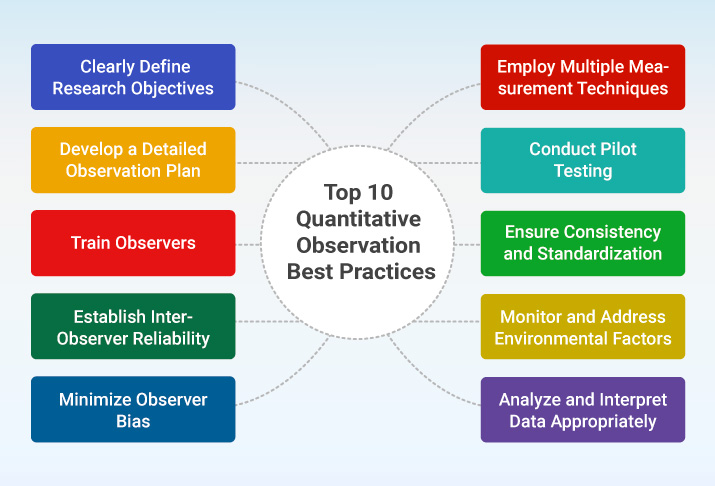
Finally, quantitative observation is a means, not an endpoint. Collecting precise numbers does not equal understanding. The numbers become useful only when you ask the right question, apply the right statistical test, and interpret the result within the actual limitations of your measurement system. A p-value below 0.05 from poorly collected quantitative data is still garbage. A clear trend with large error bars tells you more than a neat number from an uncalibrated instrument. Treat the observation as the foundation, not the building.