How Social Surveys Actually Work in Practice
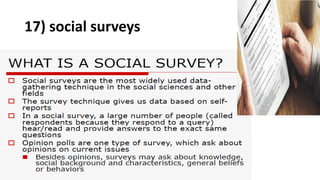
A social survey in sociology is a systematic method for collecting information from a group of people about their attitudes, behaviors, demographics, and lived experiences. That's the textbook version. The real thing is messier and far more method-dependent than most beginners realize. The core of any social survey comes down to three moving parts: sampling, measurement, and analysis. Get any one of those wrong and the rest doesn't matter. I've sat through thesis defenses where students had beautiful datasets and fundamentally invalid conclusions because they never thought through their sampling frame. The survey tool itself is almost secondary.
What Is Social Survey In Sociology
At its foundation, a social survey is a structured research instrument—usually a questionnaire—administered to a sample drawn from a larger population. The goal is to generalize findings back to that population with measurable confidence. In practice, you're trading depth for breadth. You might ask 500 people 30 standardized questions instead of having one conversation with a single person for three hours. Both approaches generate knowledge, but they generate different kinds and different levels of it. The most common mistake I see is treating surveys as if they automatically produce objective data. They don't. Every question design choice, every skip pattern, everyLikert scale endpoint carries assumptions built into the instrument. The survey reflects the researcher's framework as much as the respondent's reality.
Sampling: Where Most Surveys Break Down
Sampling is the single most important decision in survey design, and it's also the most frequently botched. A questionnaire written by a committee means nothing if your respondents aren't the people you actually need to hear from. Probability sampling—simple random, stratified, cluster, multistage—is what gives you the right to generalize beyond your sample. But it requires a proper sampling frame, which means an actual list of every unit in your population. If you're studying informal migrant workers in a city, there is no list. You don't have a frame. Everything you collect is non-probability data, and you need to know that going in, not after you've already collected it. I ran a neighborhood satisfaction survey a few years back targeting low-income renters in a midwestern city. My sampling frame came from city tax records. The data looked clean at first glance. Then I realized the frame excluded everyone living in informal housing arrangements, group homes, and doubled-up situations. About 18% of my target population was invisible in that list. Those were also the people most likely to be dissatisfied with their neighborhood. My results systematically underestimated dissatisfaction. I ended up reporting the limitation prominently in the discussion section, but it still felt dirty. There's no perfect workaround for a bad frame except acknowledging it upfront and not overstating your precision.
Get the Full Details
Question Design: The Things That Go Wrong
Question wording bias is one of those things that sounds obvious until you see it wreck your data in real time. A single word shift can flip response distributions by double-digit percentages. Consider two questions about the same policy: "Should the government restrict public speech that could be offensive?" versus "Should the government protect public speech even when it's controversial?" The second phrasing pulls significantly more support even among people who would reject the first. Double-barreled questions are the most common amateur error. "How satisfied are you with the quality and responsiveness of local government?" Some people are happy with quality but unhappy with responsiveness. There's no way to answer that honestly, so they either pick the middle option or guess at what you "really" mean. Both responses are noise. Acquiescence bias is harder to catch. It's the tendency for respondents to agree with statements regardless of content. This is why mixed-keyed Likert scales—where some items are positively worded and others negatively—exist. Without them, a chunk of your data is just people clicking through fast, not actually reading.
Open-ended questions are valuable but expensive. Coding qualitative responses from hundreds of survey takers takes substantial time and introduces coder reliability as a new source of error. I usually reserve open-ended items for the end of longer surveys and limit them to two or three per instrument. If you need deep qualitative data, do a separate focus group study. Don't pretend a survey box at the bottom of a 40-question instrument replaces that.
Administration Modes and Their Hidden Costs
The mode of administration shapes who responds and how honestly they respond. Face-to-face surveys achieve higher response rates but introduce interviewer effects. The researcher's appearance, tone, and reactions subtly steer answers. Web surveys reduce that pressure but dramatically lower participation unless you invest in recruitment incentives and follow-ups. Phone surveys sit somewhere in between and are increasingly difficult to execute well because of caller ID avoidance and do-not-call registries. Mode effects aren't just about response rates. They affect the substantive answers too. People report more socially desirable behaviors in face-to-face interviews and more honest admissions in anonymous web surveys. If your research question involves sensitive topics—substance use, sexual behavior, discriminatory attitudes—the administration mode is a methodological variable you can't ignore. I designed a web-based survey for a study on workplace discrimination and got terrible completion rates at first. The average time on page was under two minutes and drop-off hit 60% before the end. Switching to a mixed-mode approach—offering both web and telephone options—doubled completion. The telephone respondents took longer and gave more nuanced answers on the open-ended sections, but they also introduced a different kind of bias since the interviewer was always present. You pick your compromise and live with it.
Weighting and Nonresponse Adjustment
Even with a perfect design, your final dataset will have gaps. People drop out of panels, refuse to answer specific questions, and skip demographic sections. Nonresponse bias is the silent killer of survey validity. It's not enough to say "15% didn't answer." You need to compare the people who did and didn't respond on any available demographics and adjust accordingly. Post-stratification weighting is standard practice. You align your sample distributions to known population totals from census data on age, gender, race, education, and region. This corrects for known imbalances but doesn't fix bias in the unanswered questions themselves. If nonrespondents differ from respondents on the actual variables you're studying, no amount of weighting fully recovers that. It gets you closer to the truth but not there. Being honest about this gap matters more than pretending your weighted estimates are population-representative. Another thing beginners overlook is the cost of weighting. Weighted analyses require larger effective sample sizes and more complex variance estimation. A weighted n of 800 often behaves like an unweighted n of 500 statistically. If you're working with a small sample to begin with, heavy weighting can destabilize your results more than it helps.
When Surveys Fail Completely
There are situations where a social survey is simply the wrong tool. If you need to understand how someone constructs meaning around a rare experience, a survey won't get you there. If the population is small, hidden, or actively avoids institutions, probability sampling may be impossible and your findings will be limited to descriptive patterns at best. If you're studying power dynamics or institutional behavior, surveys often capture surface-level attitudes while missing the structural realities that actually drive outcomes. Mixed-methods designs solve some of these problems. A survey followed by targeted interviews gives you generalizable patterns and the contextual depth to interpret them. It costs more time and money, but it prevents the common error of treating survey statistics as complete explanations rather than directional signals.
Bottom Line
A well-run social survey produces defensible, generalizable data about populations. A poorly run one produces noise dressed up as evidence. The difference isn't sophistication—it's rigor around sampling frames, question validation, mode effects, and honest reporting of limitations. The tools and software have gotten easier. The methodological discipline hasn't.